Skip to content
Anton Dergunov

Projects

Evaluation and post-training

3 projects

LLM agent evaluation test bed

active

A support agent for a fictional neobank, built to iterate on how LLM agents are evaluated. The model only talks; plain Python makes every decision that touches money or account state, so prompt injection has no action to reach. An LLM plays the customer, and every simulated conversation is scored by deterministic checks and an LLM-as-judge.

  • llm evaluation
  • llm as judge
  • agent evaluation
  • ai agents
  • guardrails
  • rag
  • prompt injection
  • python
Agent memory systems, traced and measured

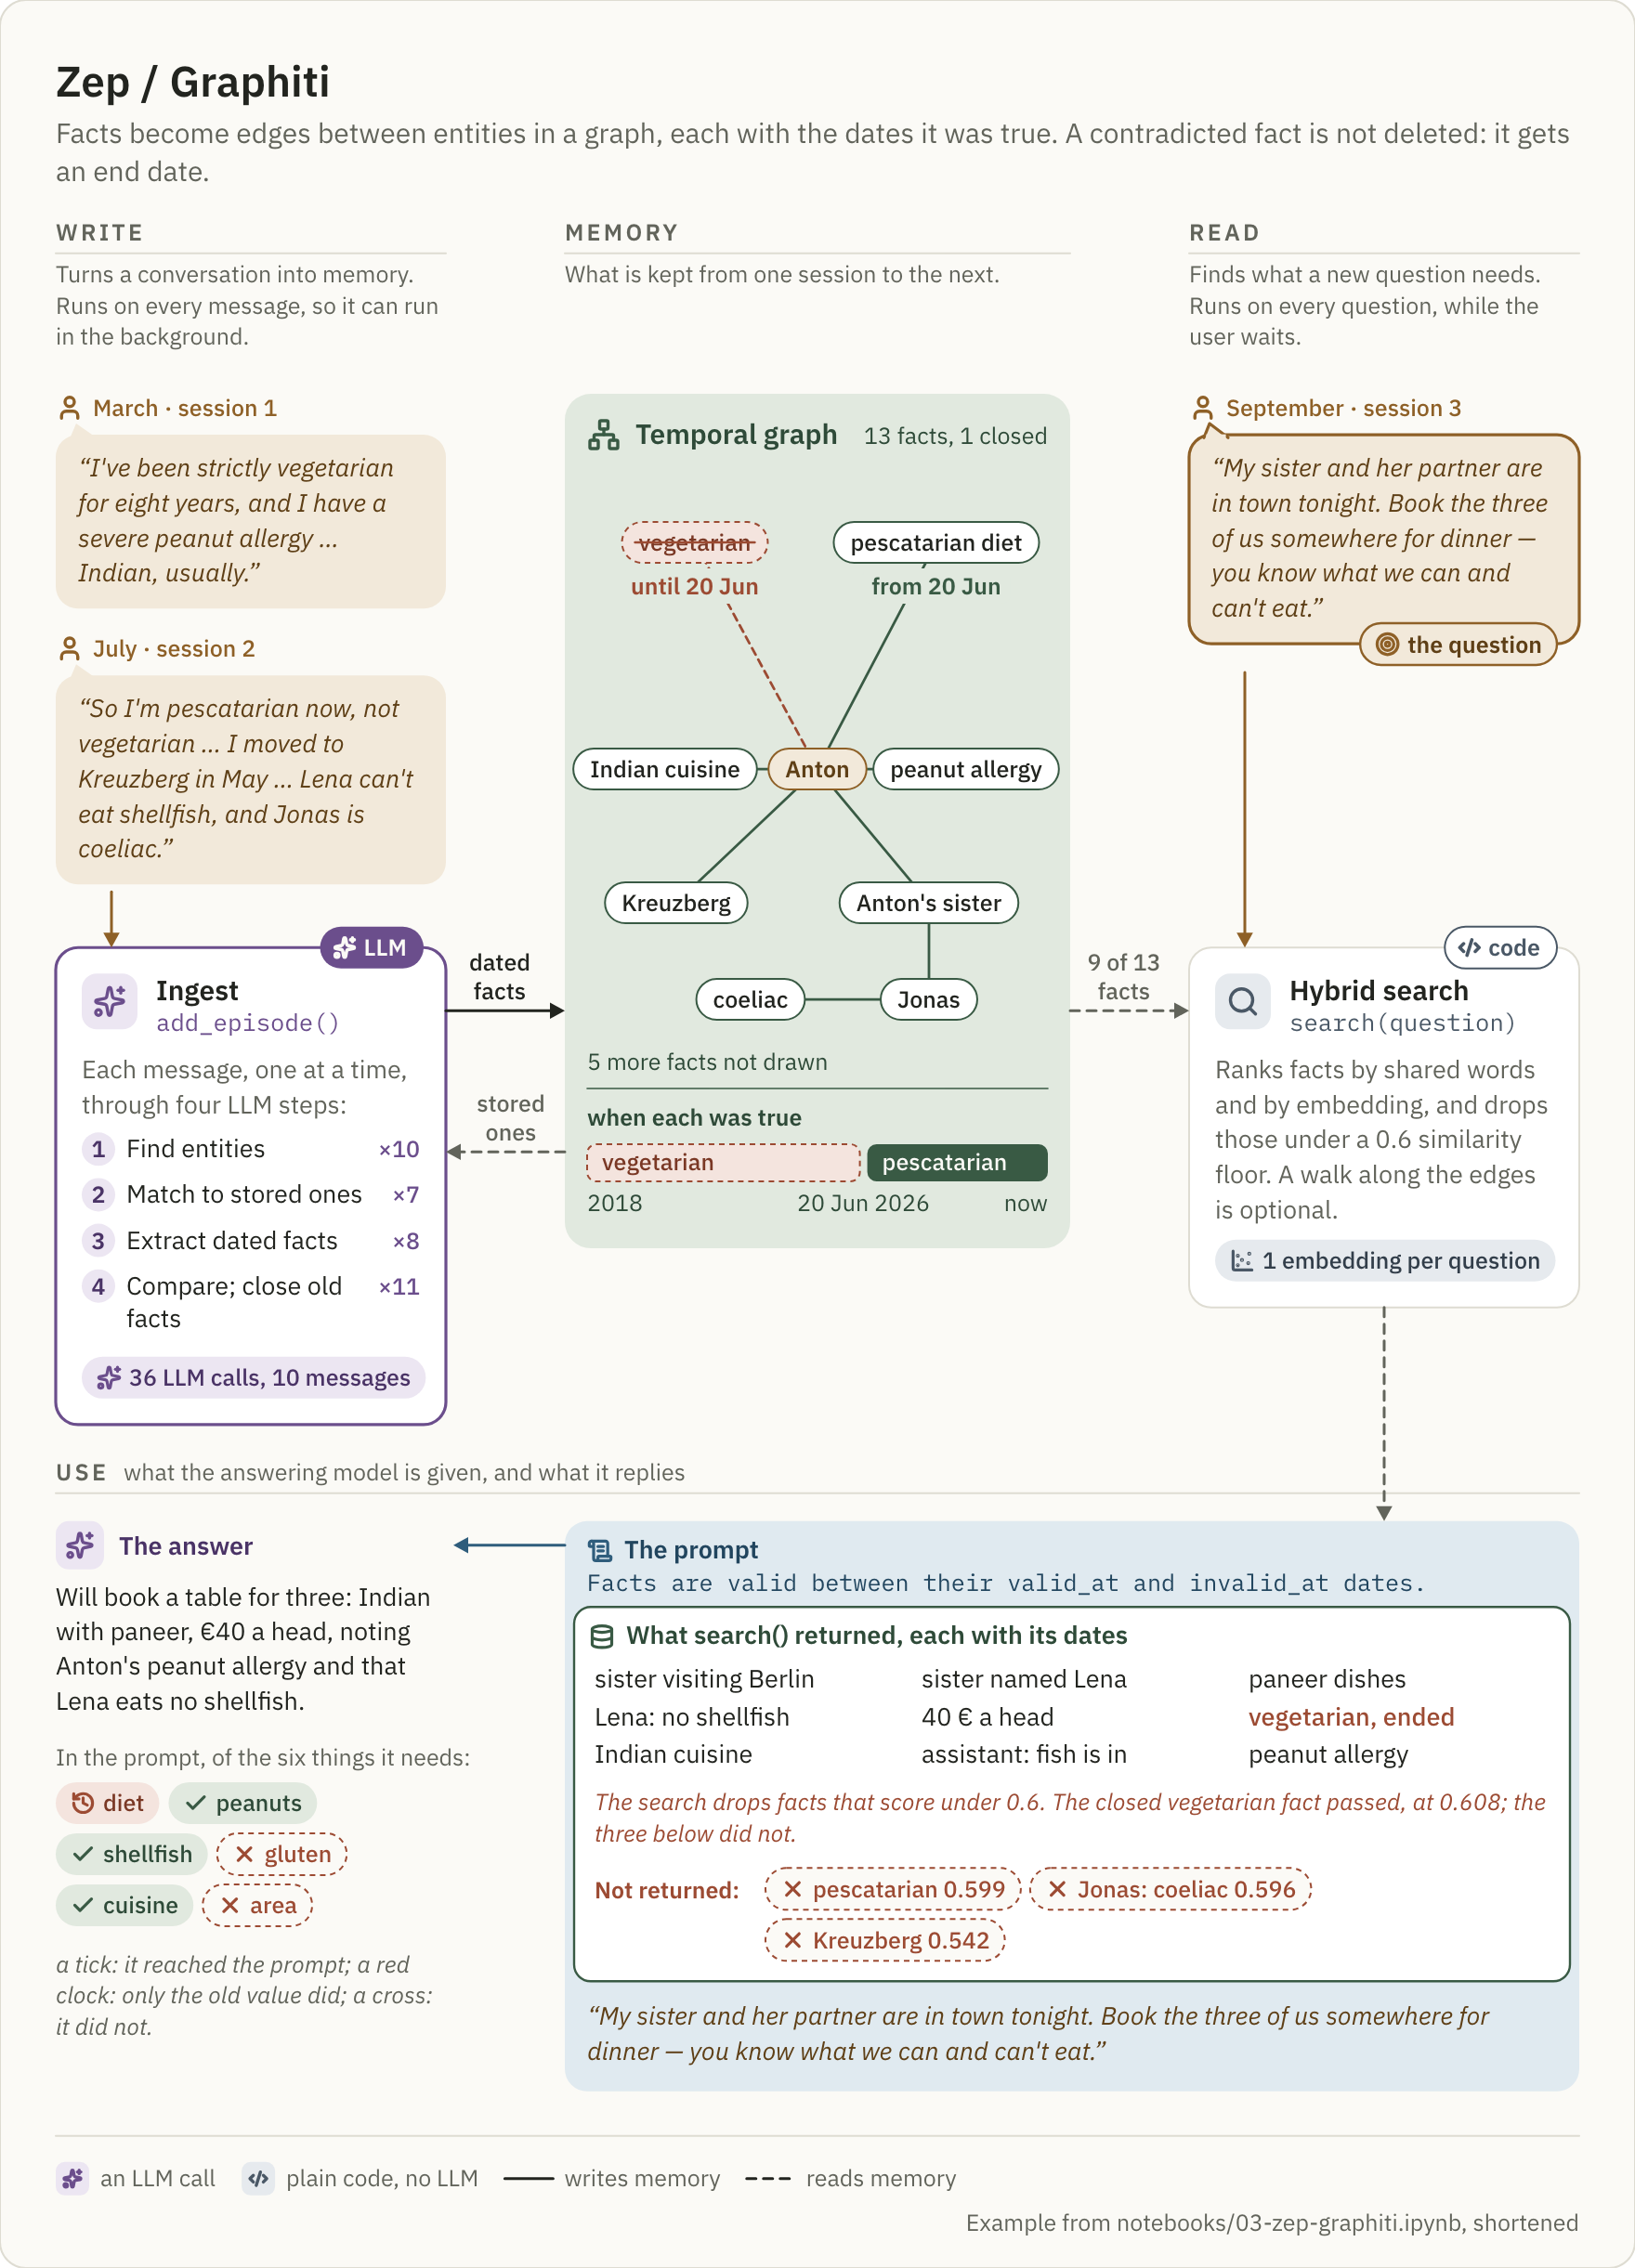
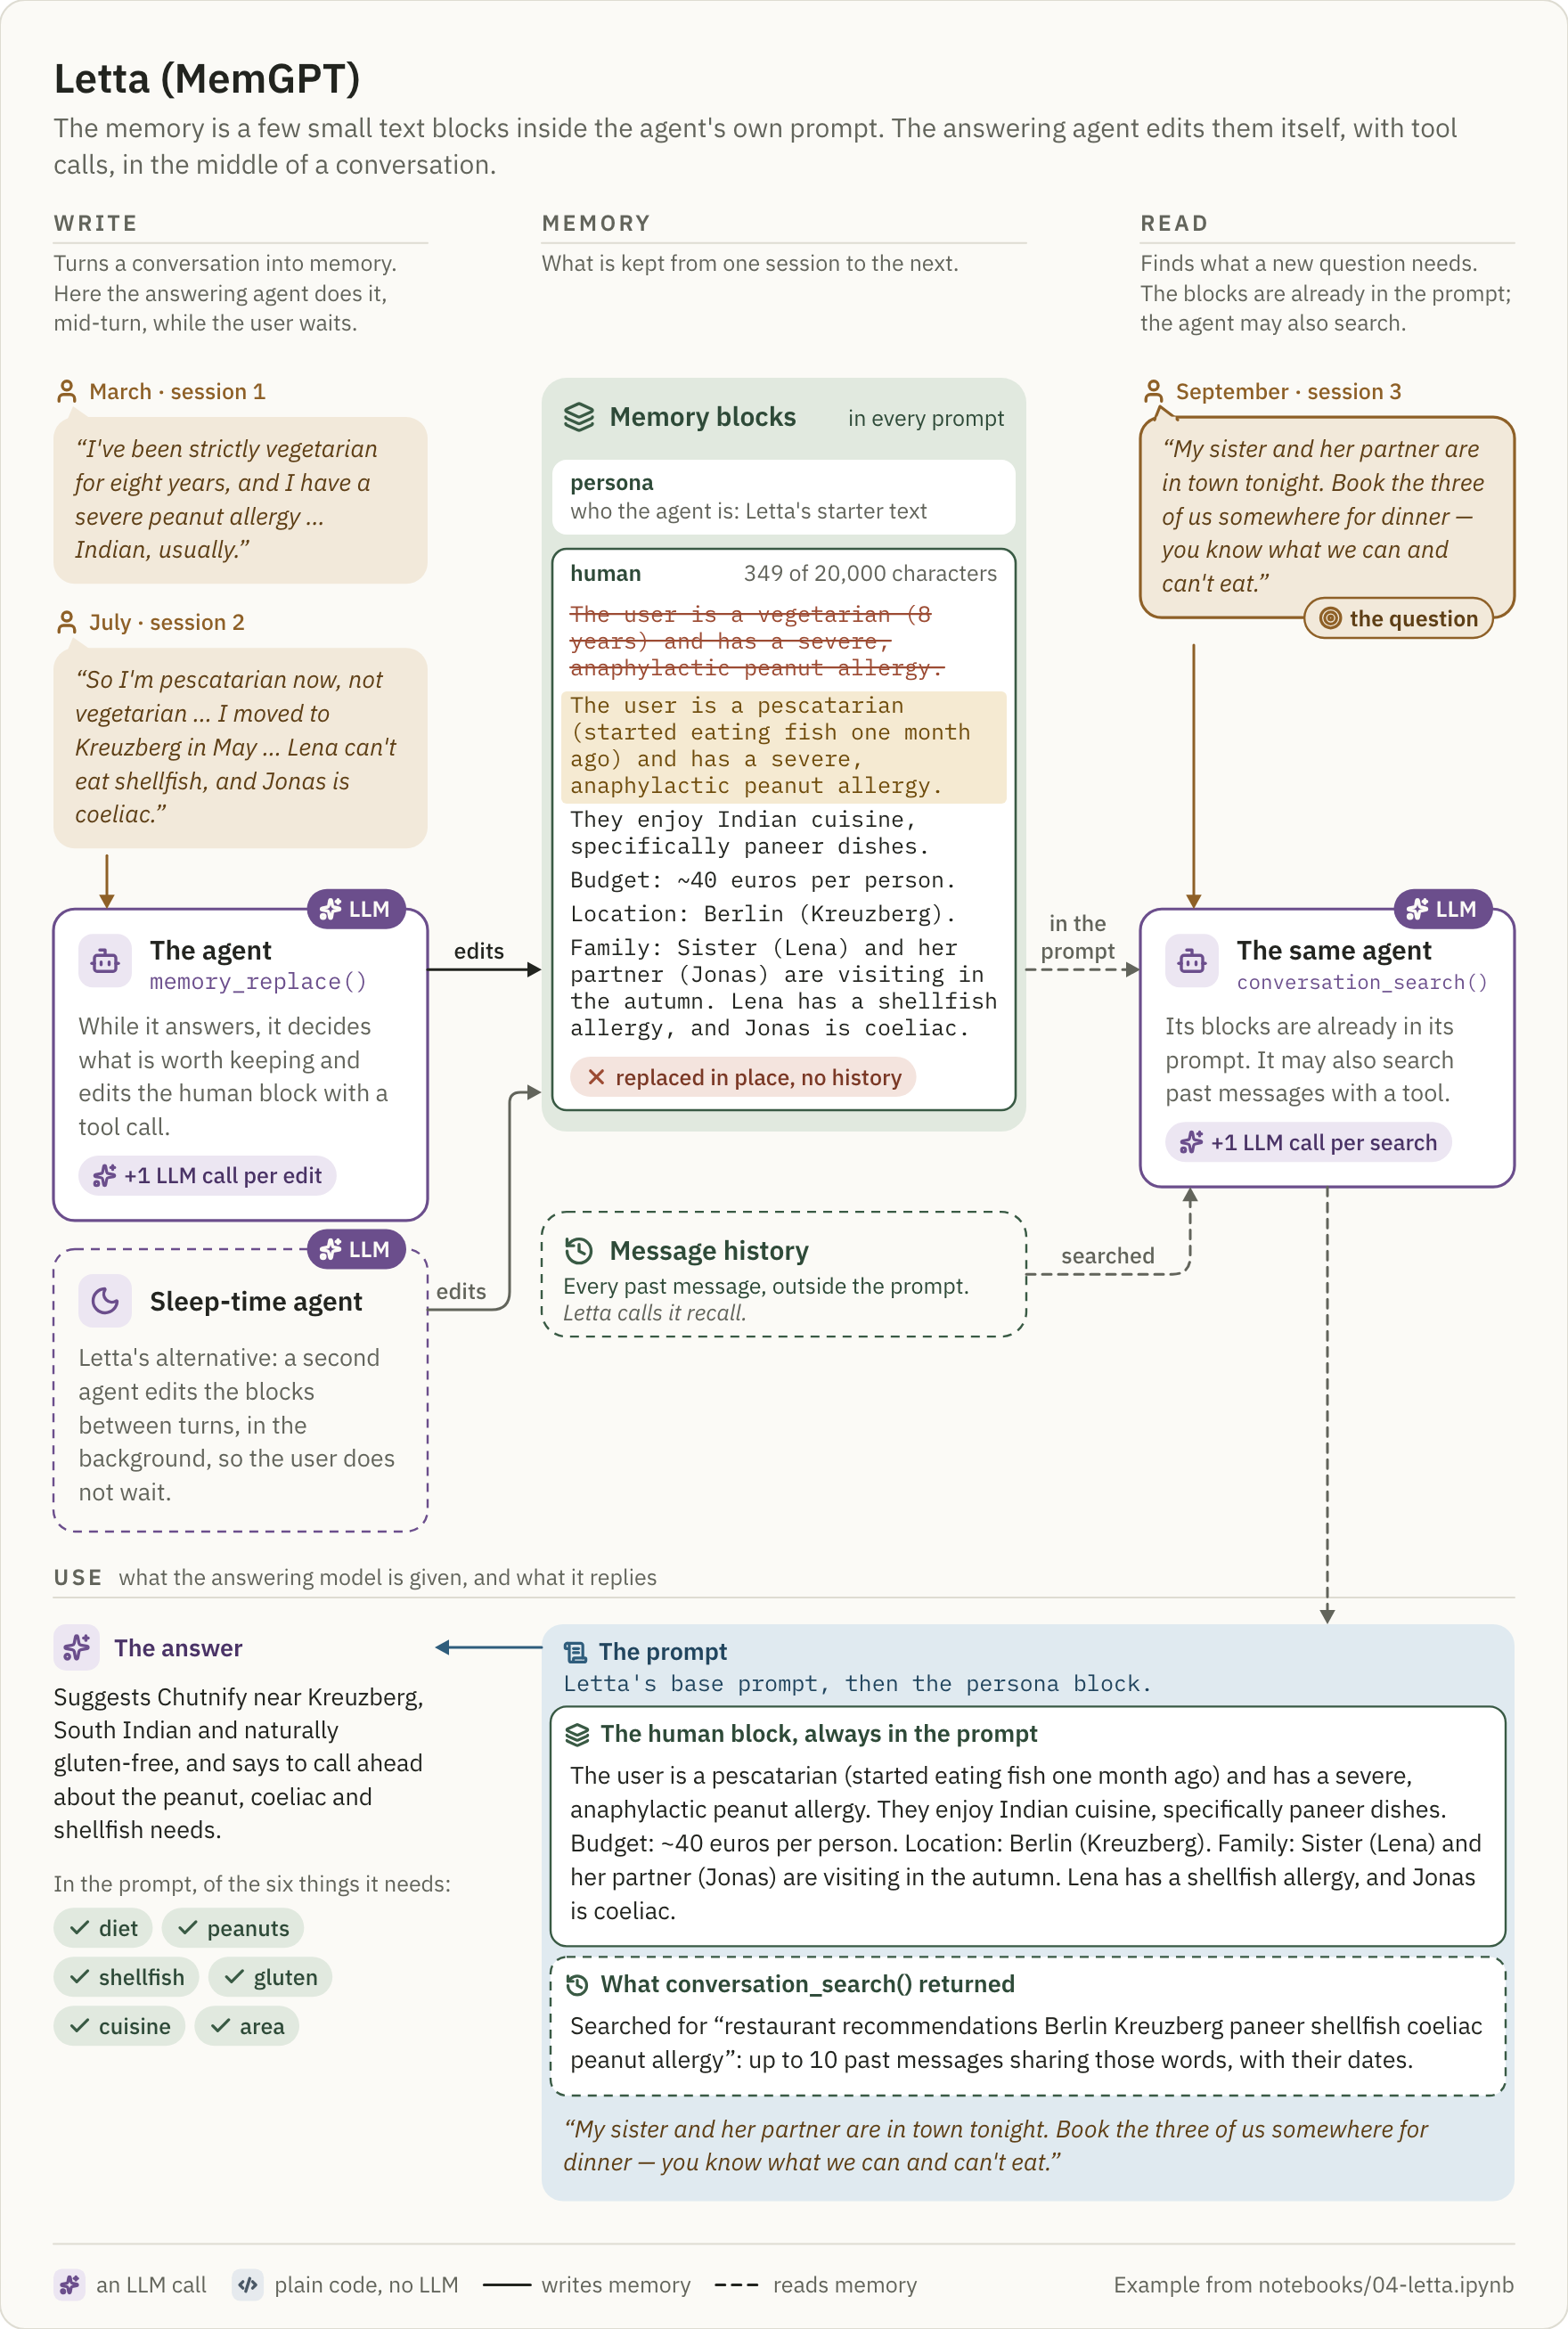
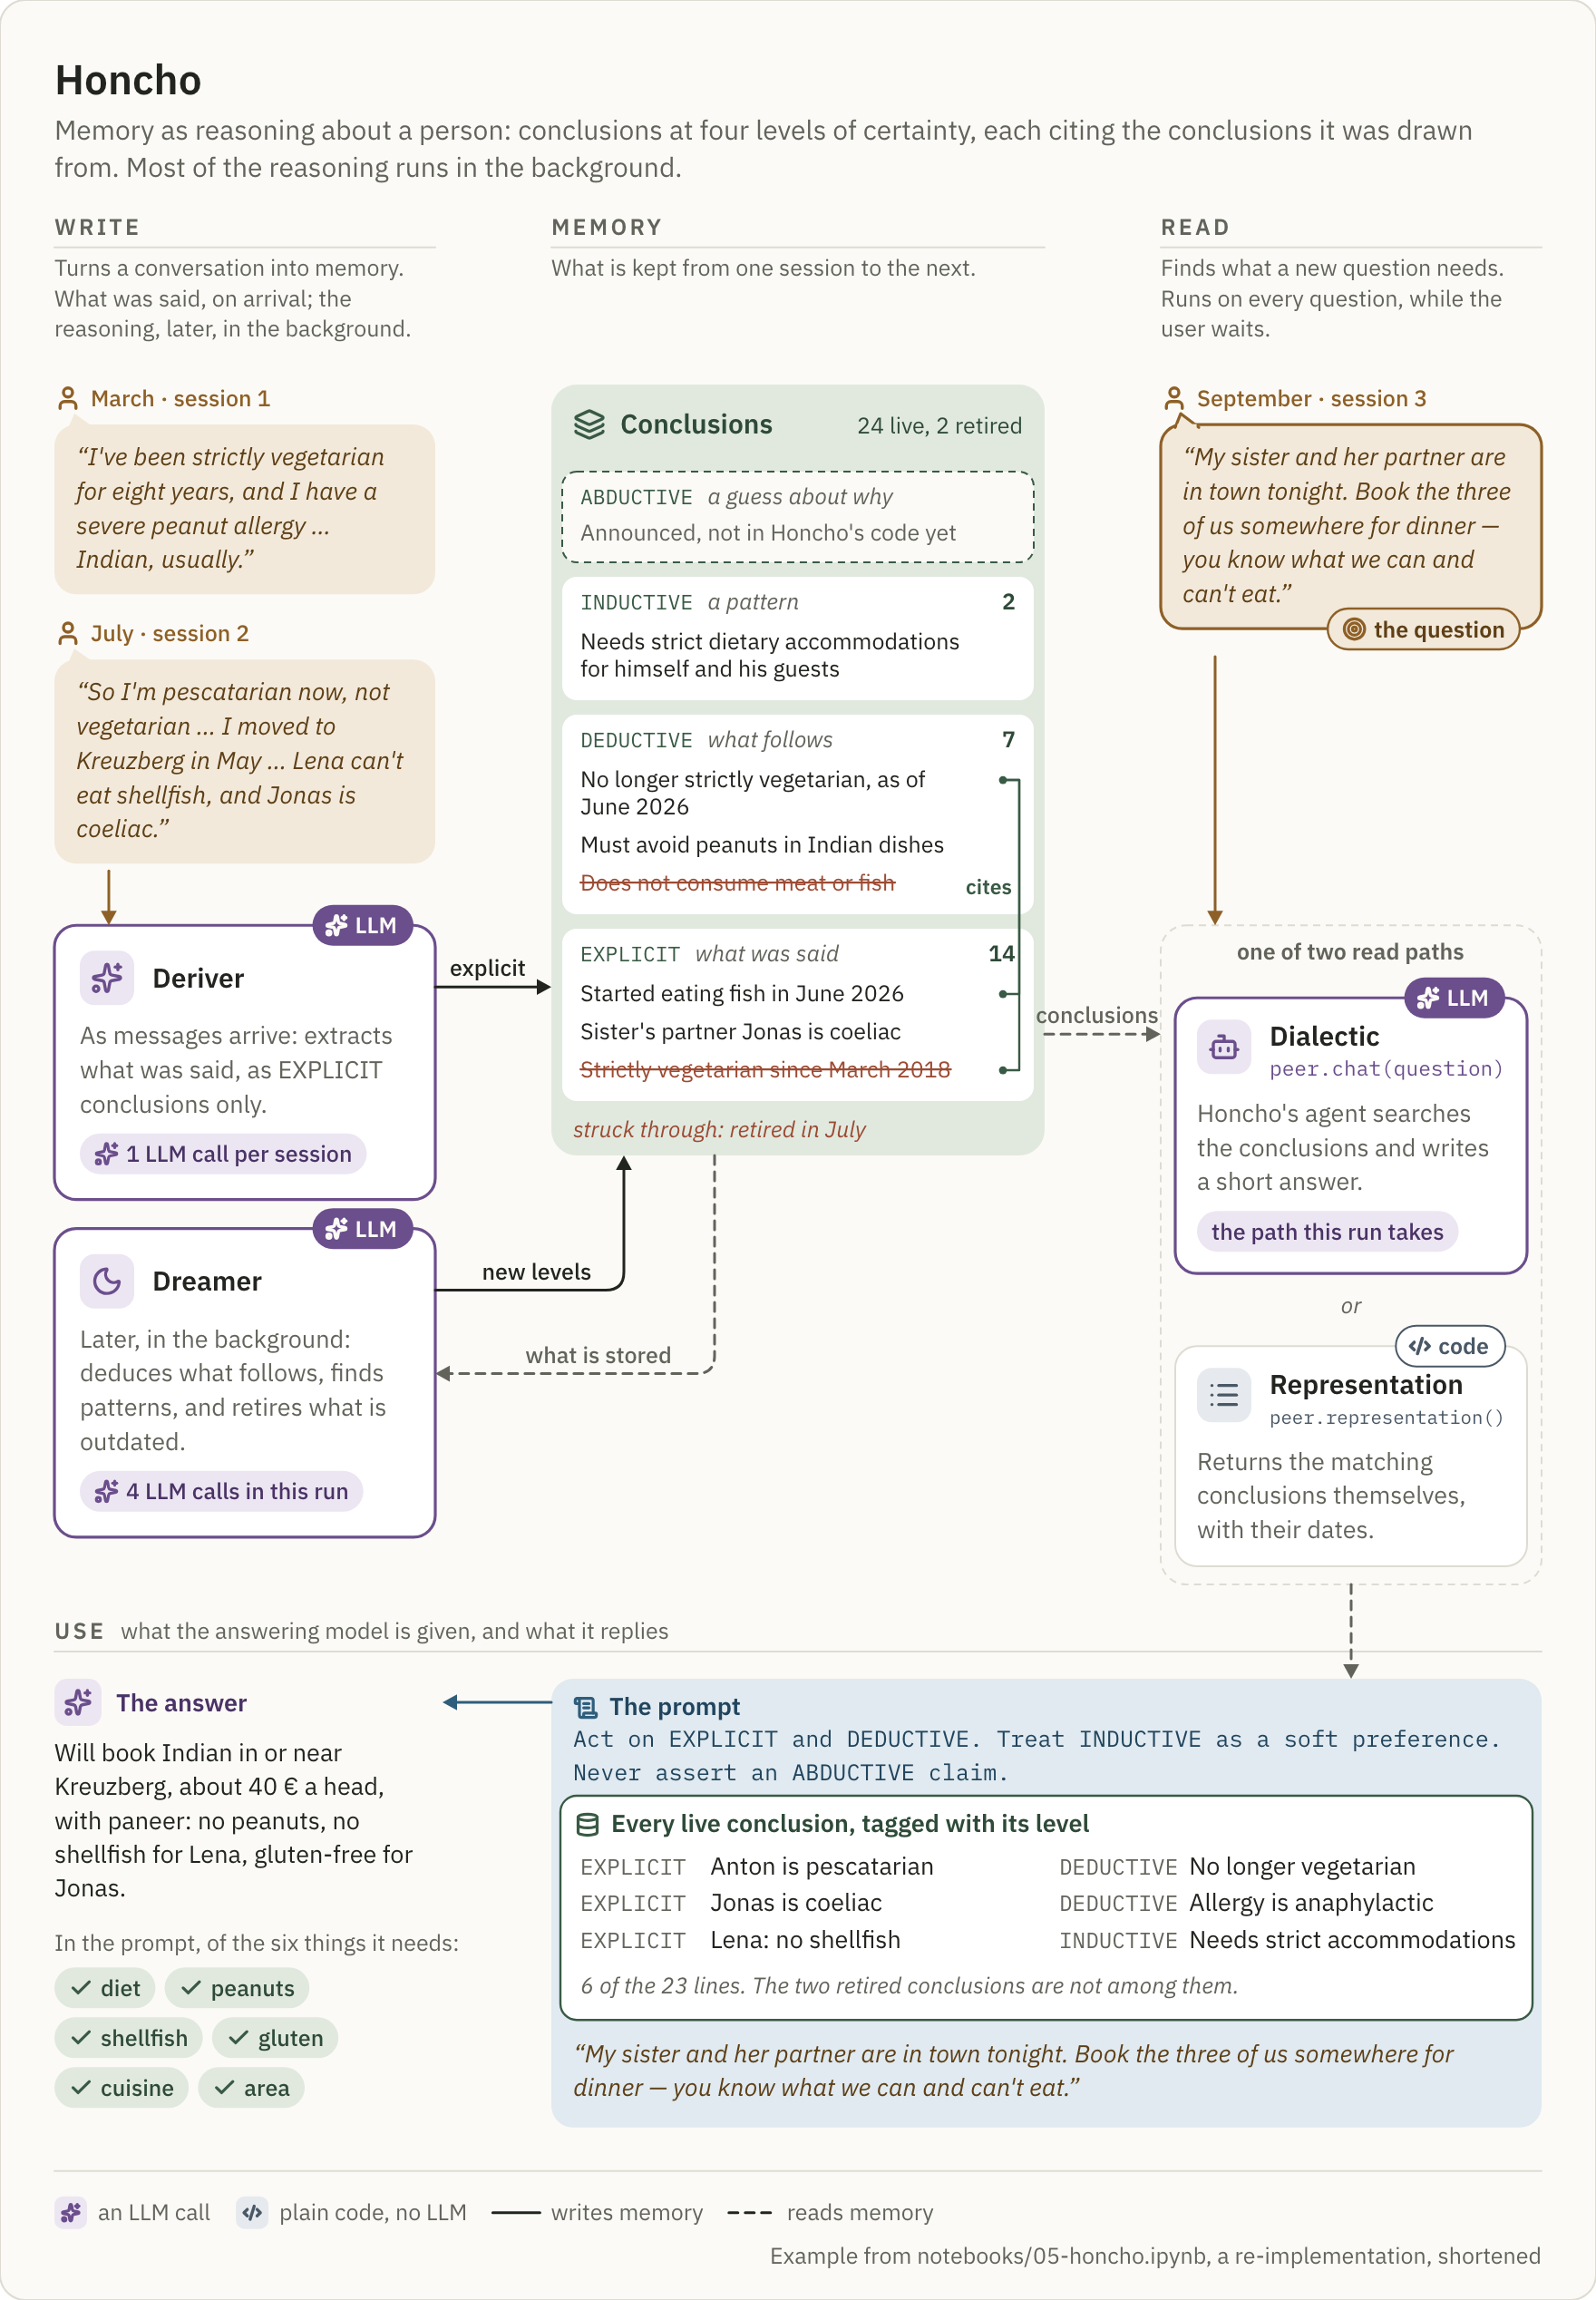
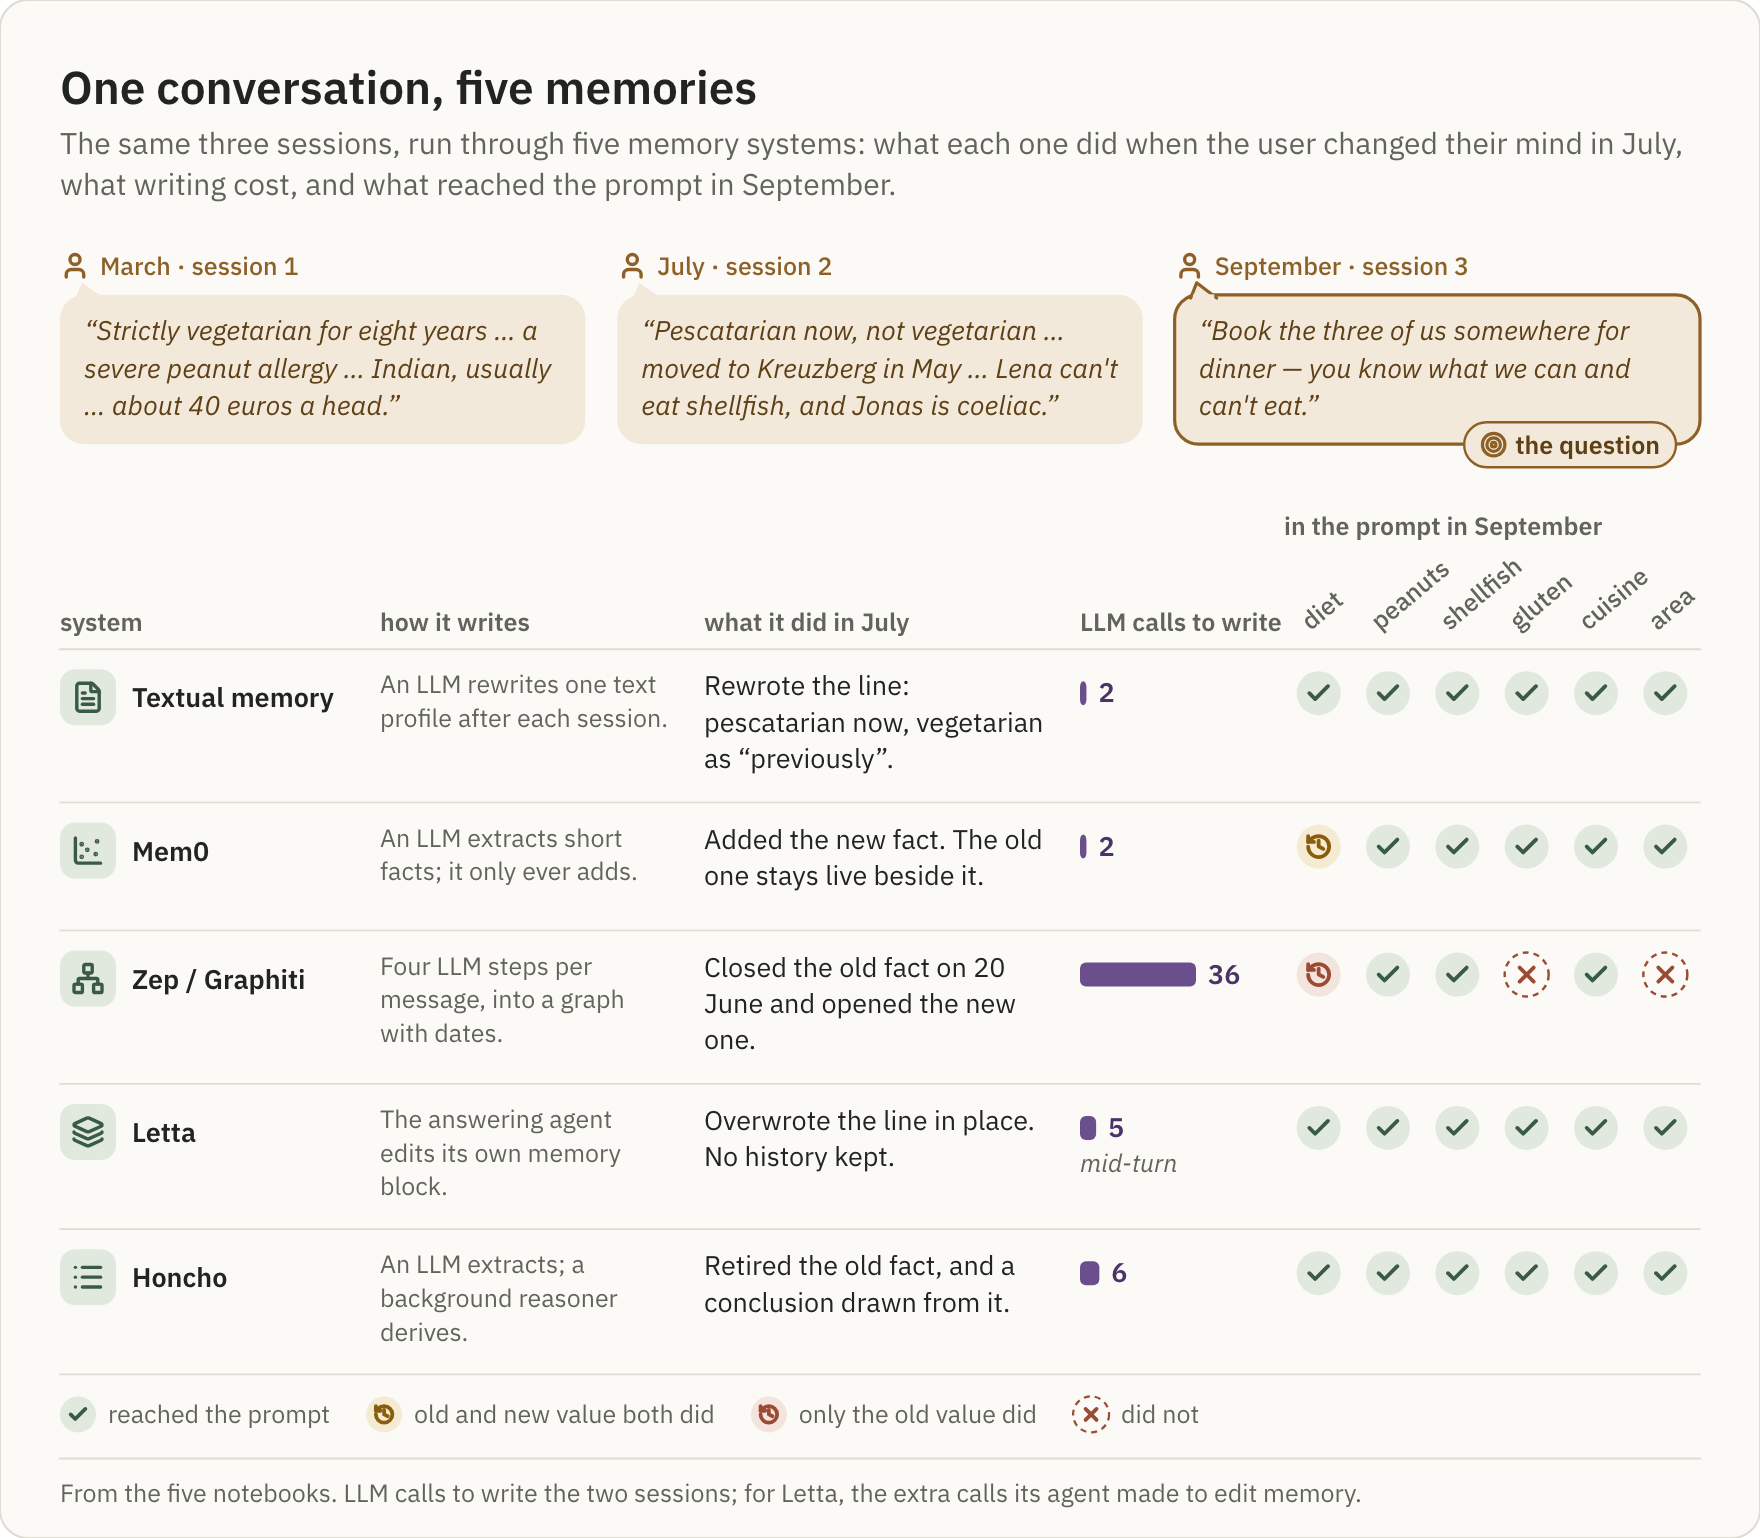
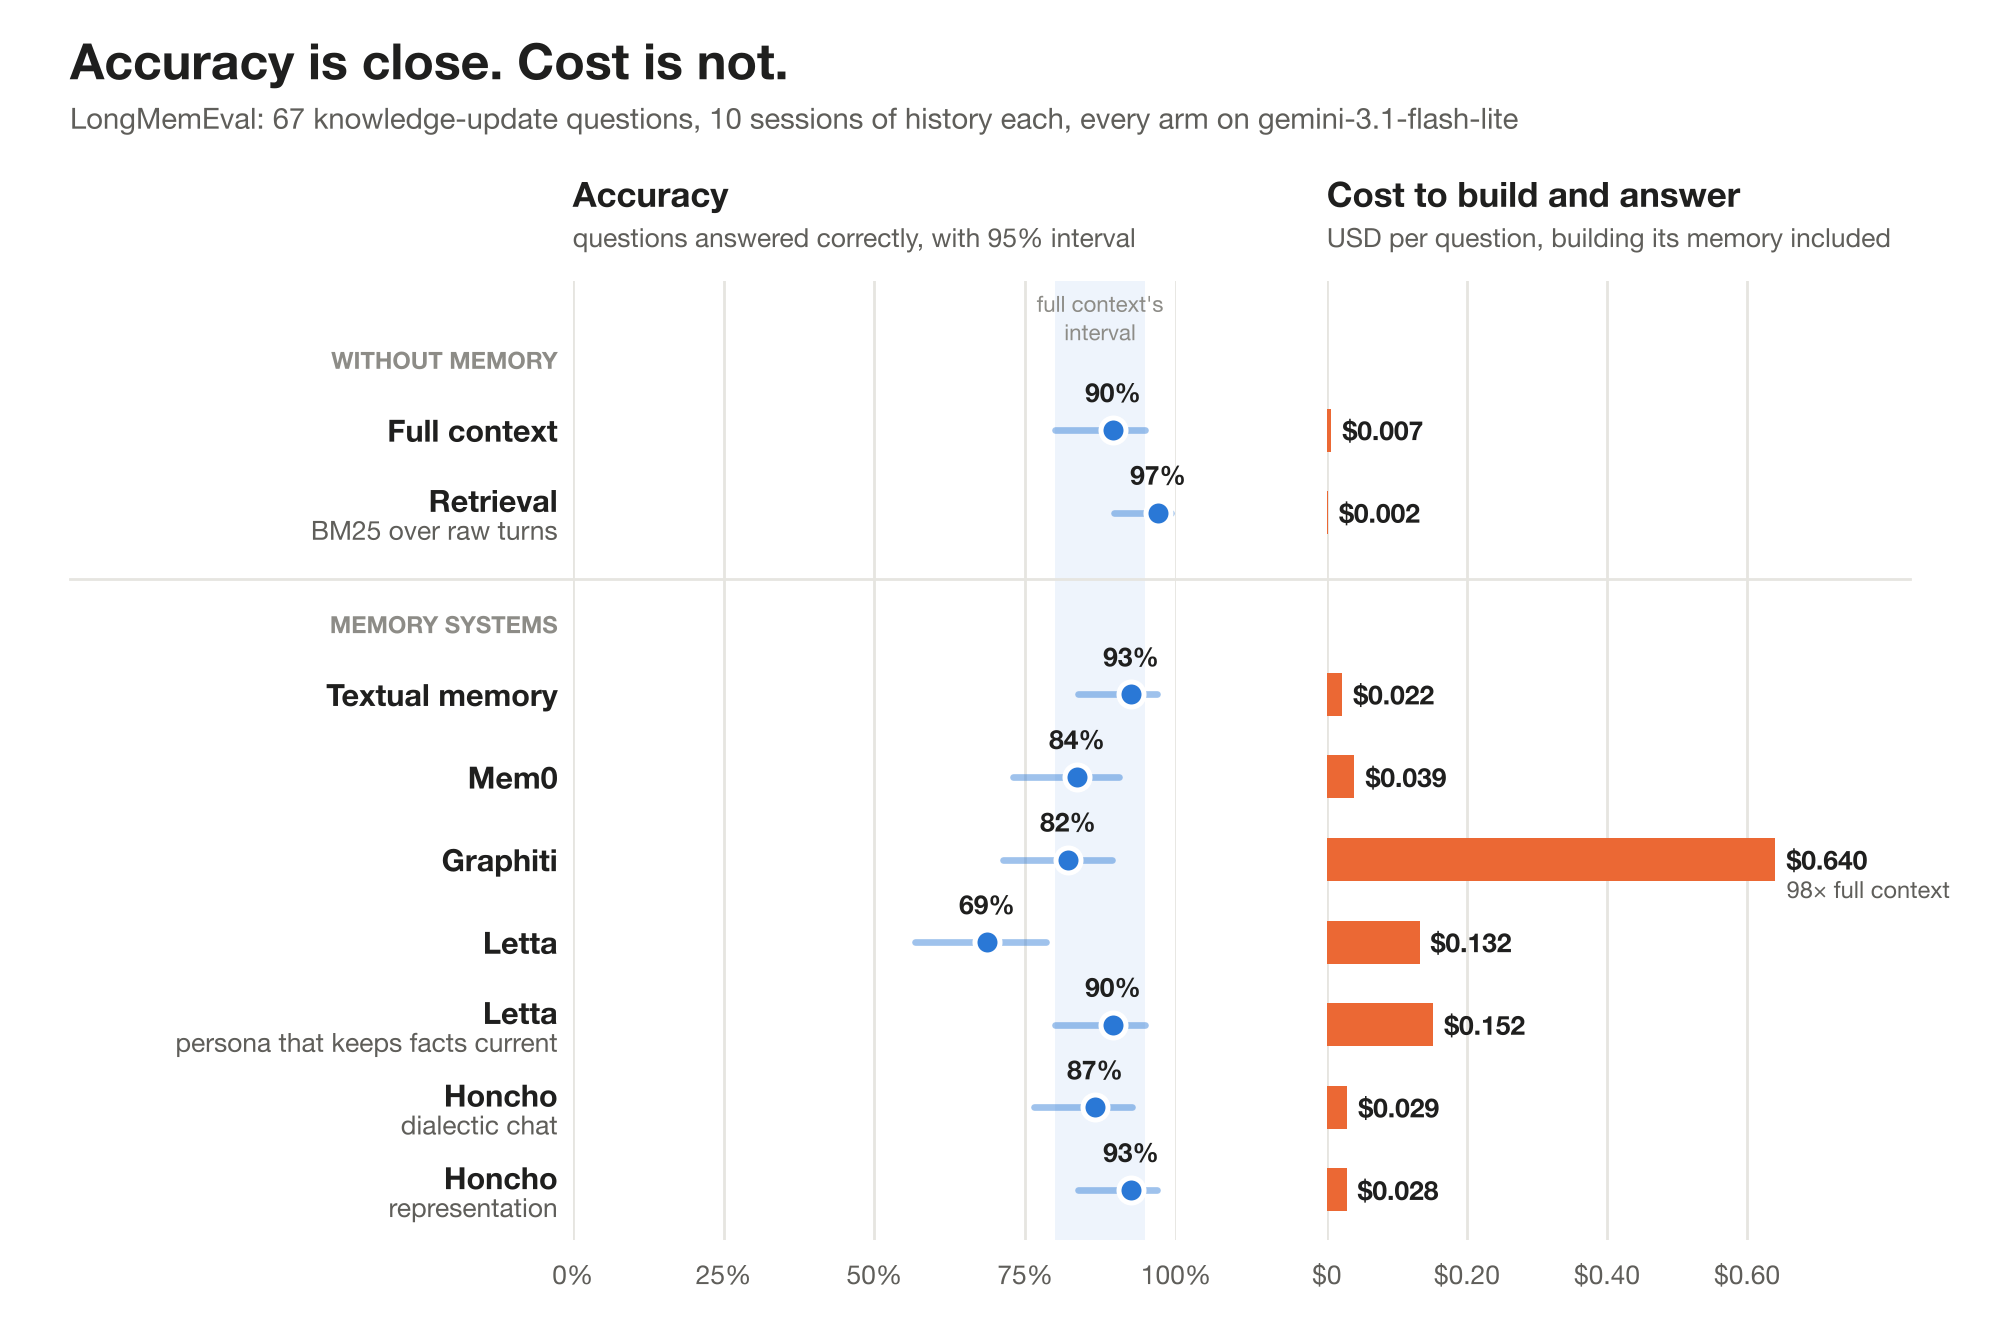
A comparison of agent memory systems that shows how each one works. One short conversation, in which a user changes their mind, runs through LLM memory systems chosen to represent each architecture, from plain full context and a textual memory to Mem0, Zep/Graphiti, Letta and Honcho, with every model call shown: what was extracted, what was overwritten, what was retrieved, and what it cost. The same systems are then run on the knowledge-update questions of LongMemEval, with accuracy, intervals and cost per question.

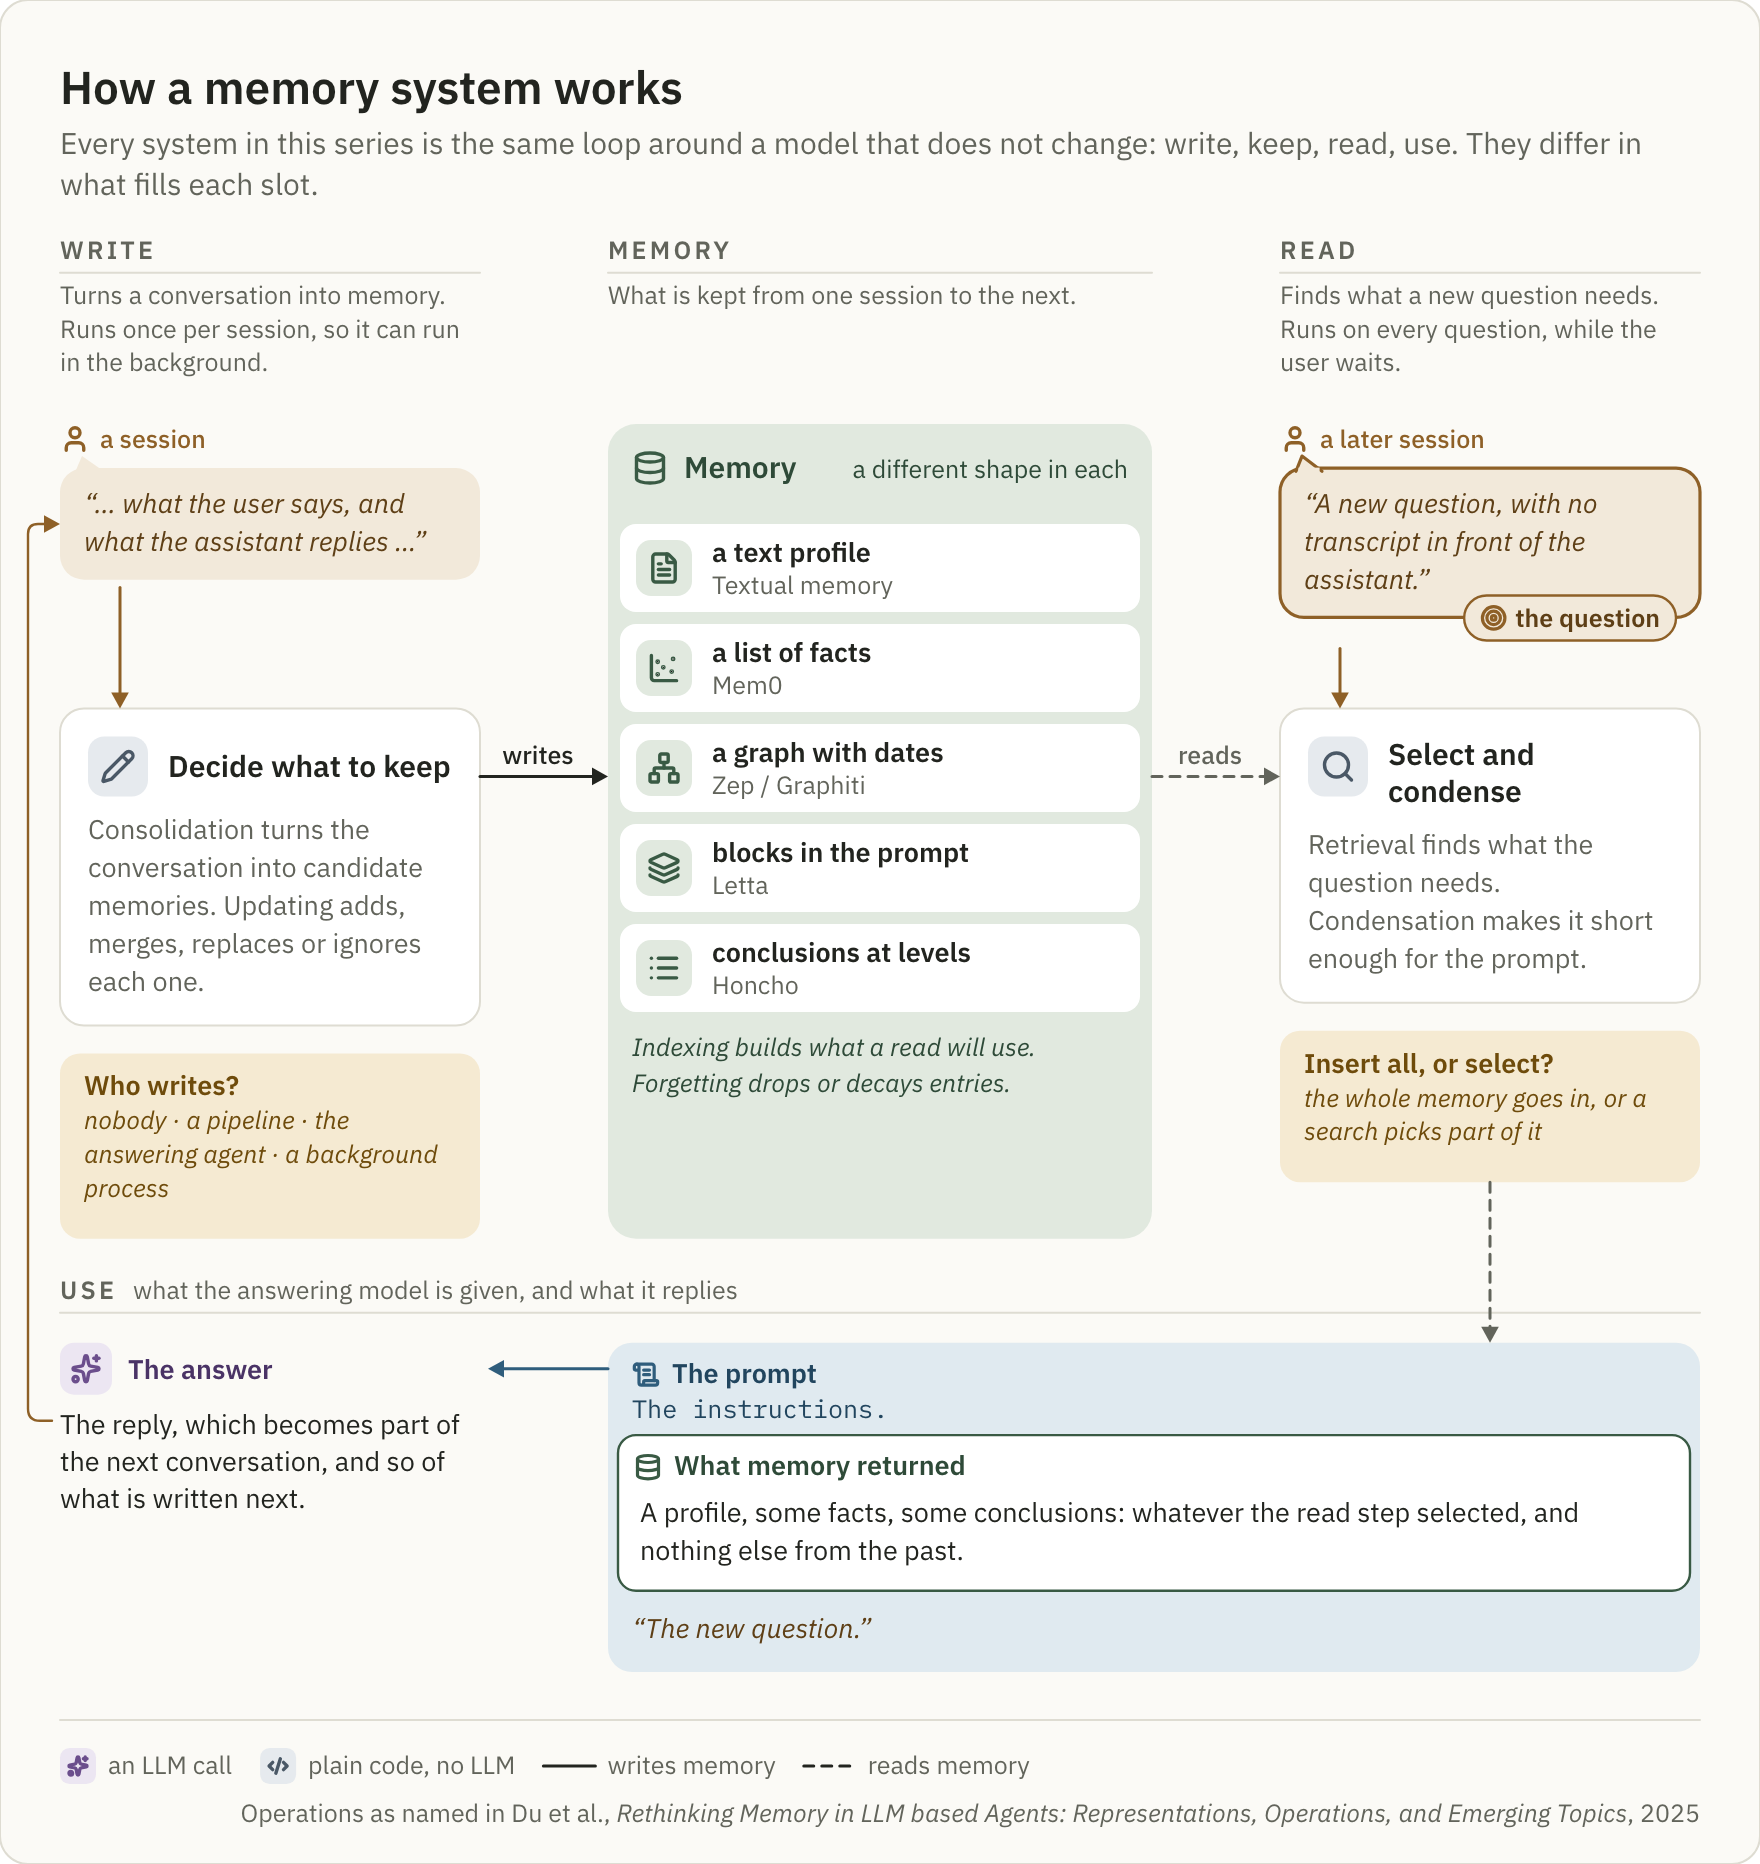
The loop every memory system is built on, from who writes the memory to what the answering model is given.
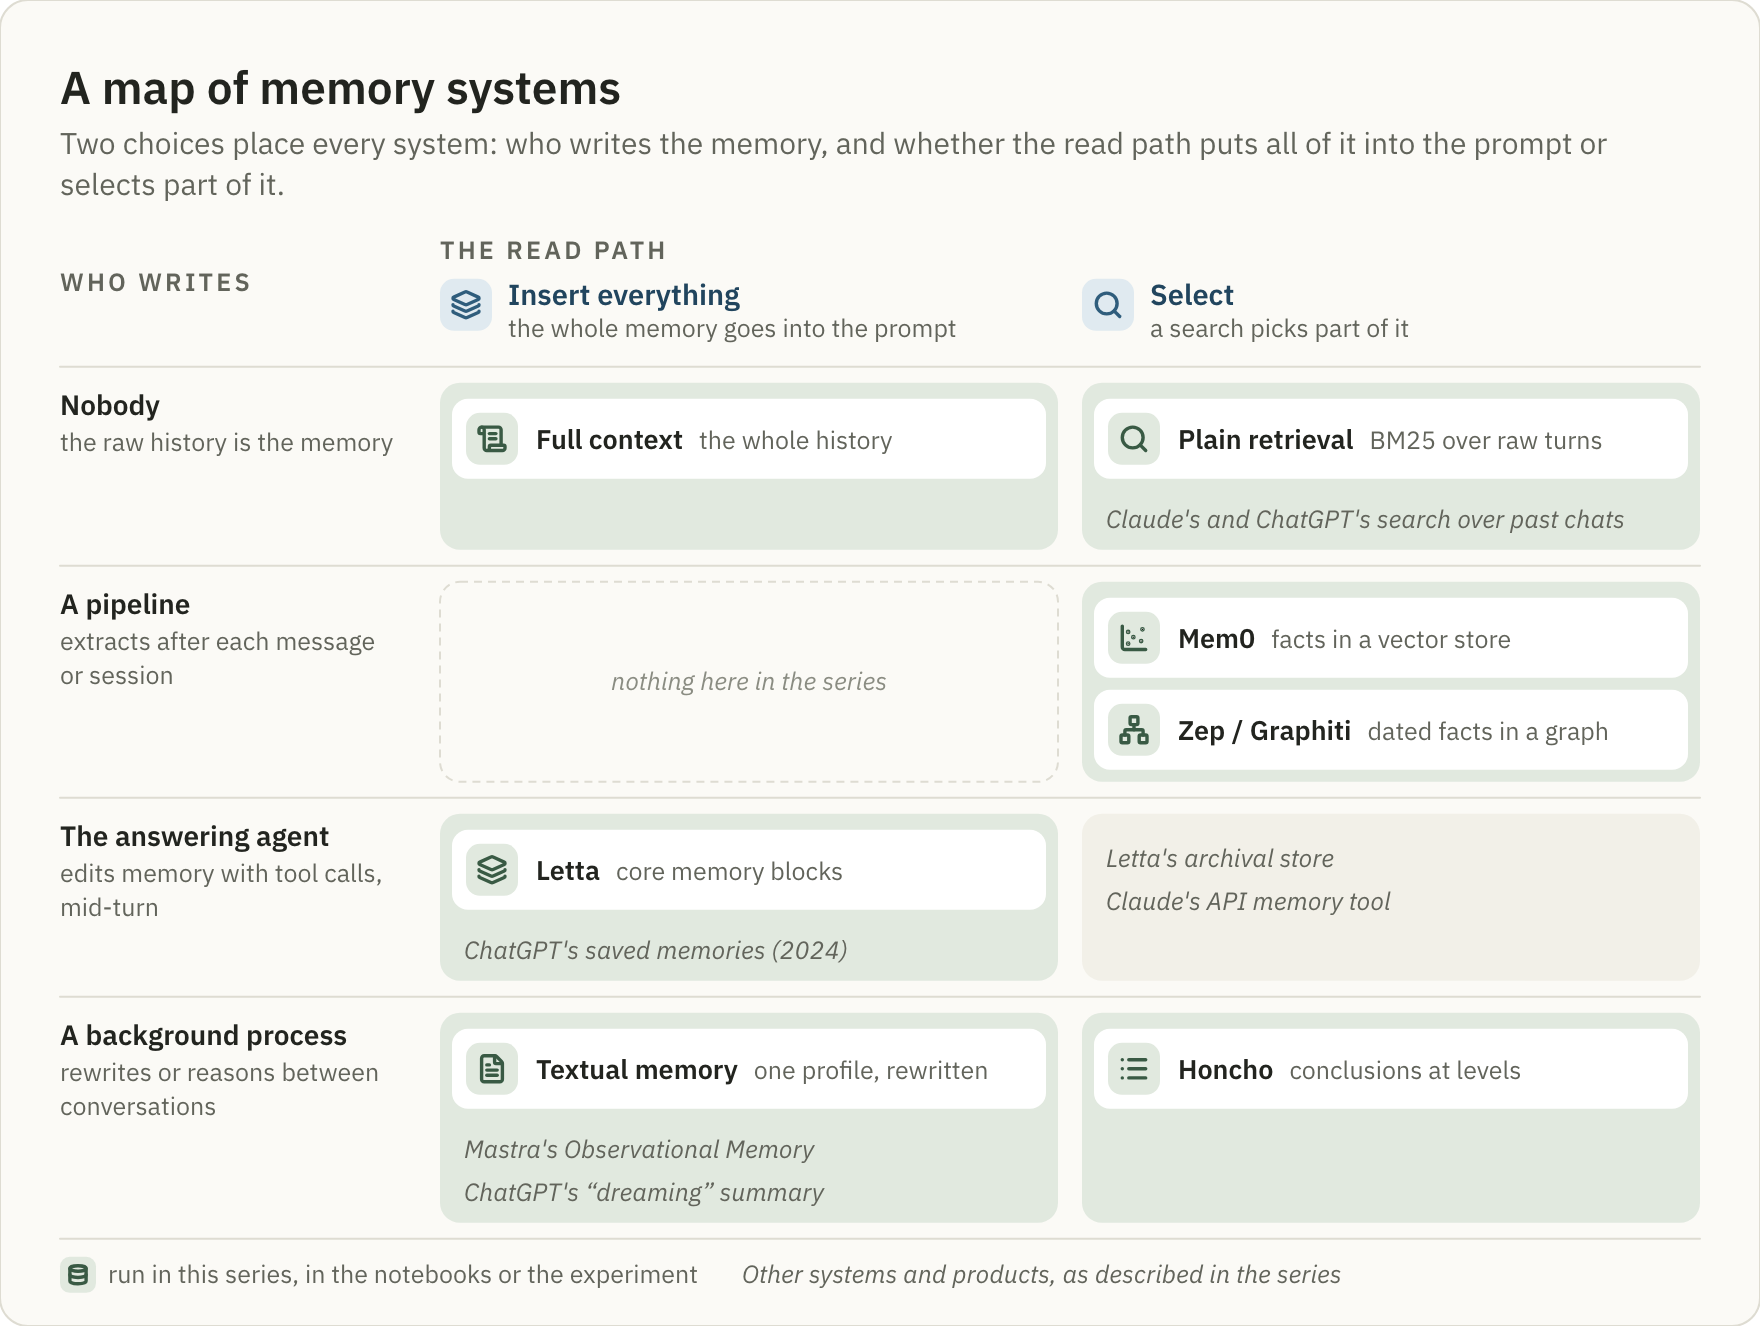
A map of the systems by who writes the memory and whether the whole memory or a search result goes into the prompt.
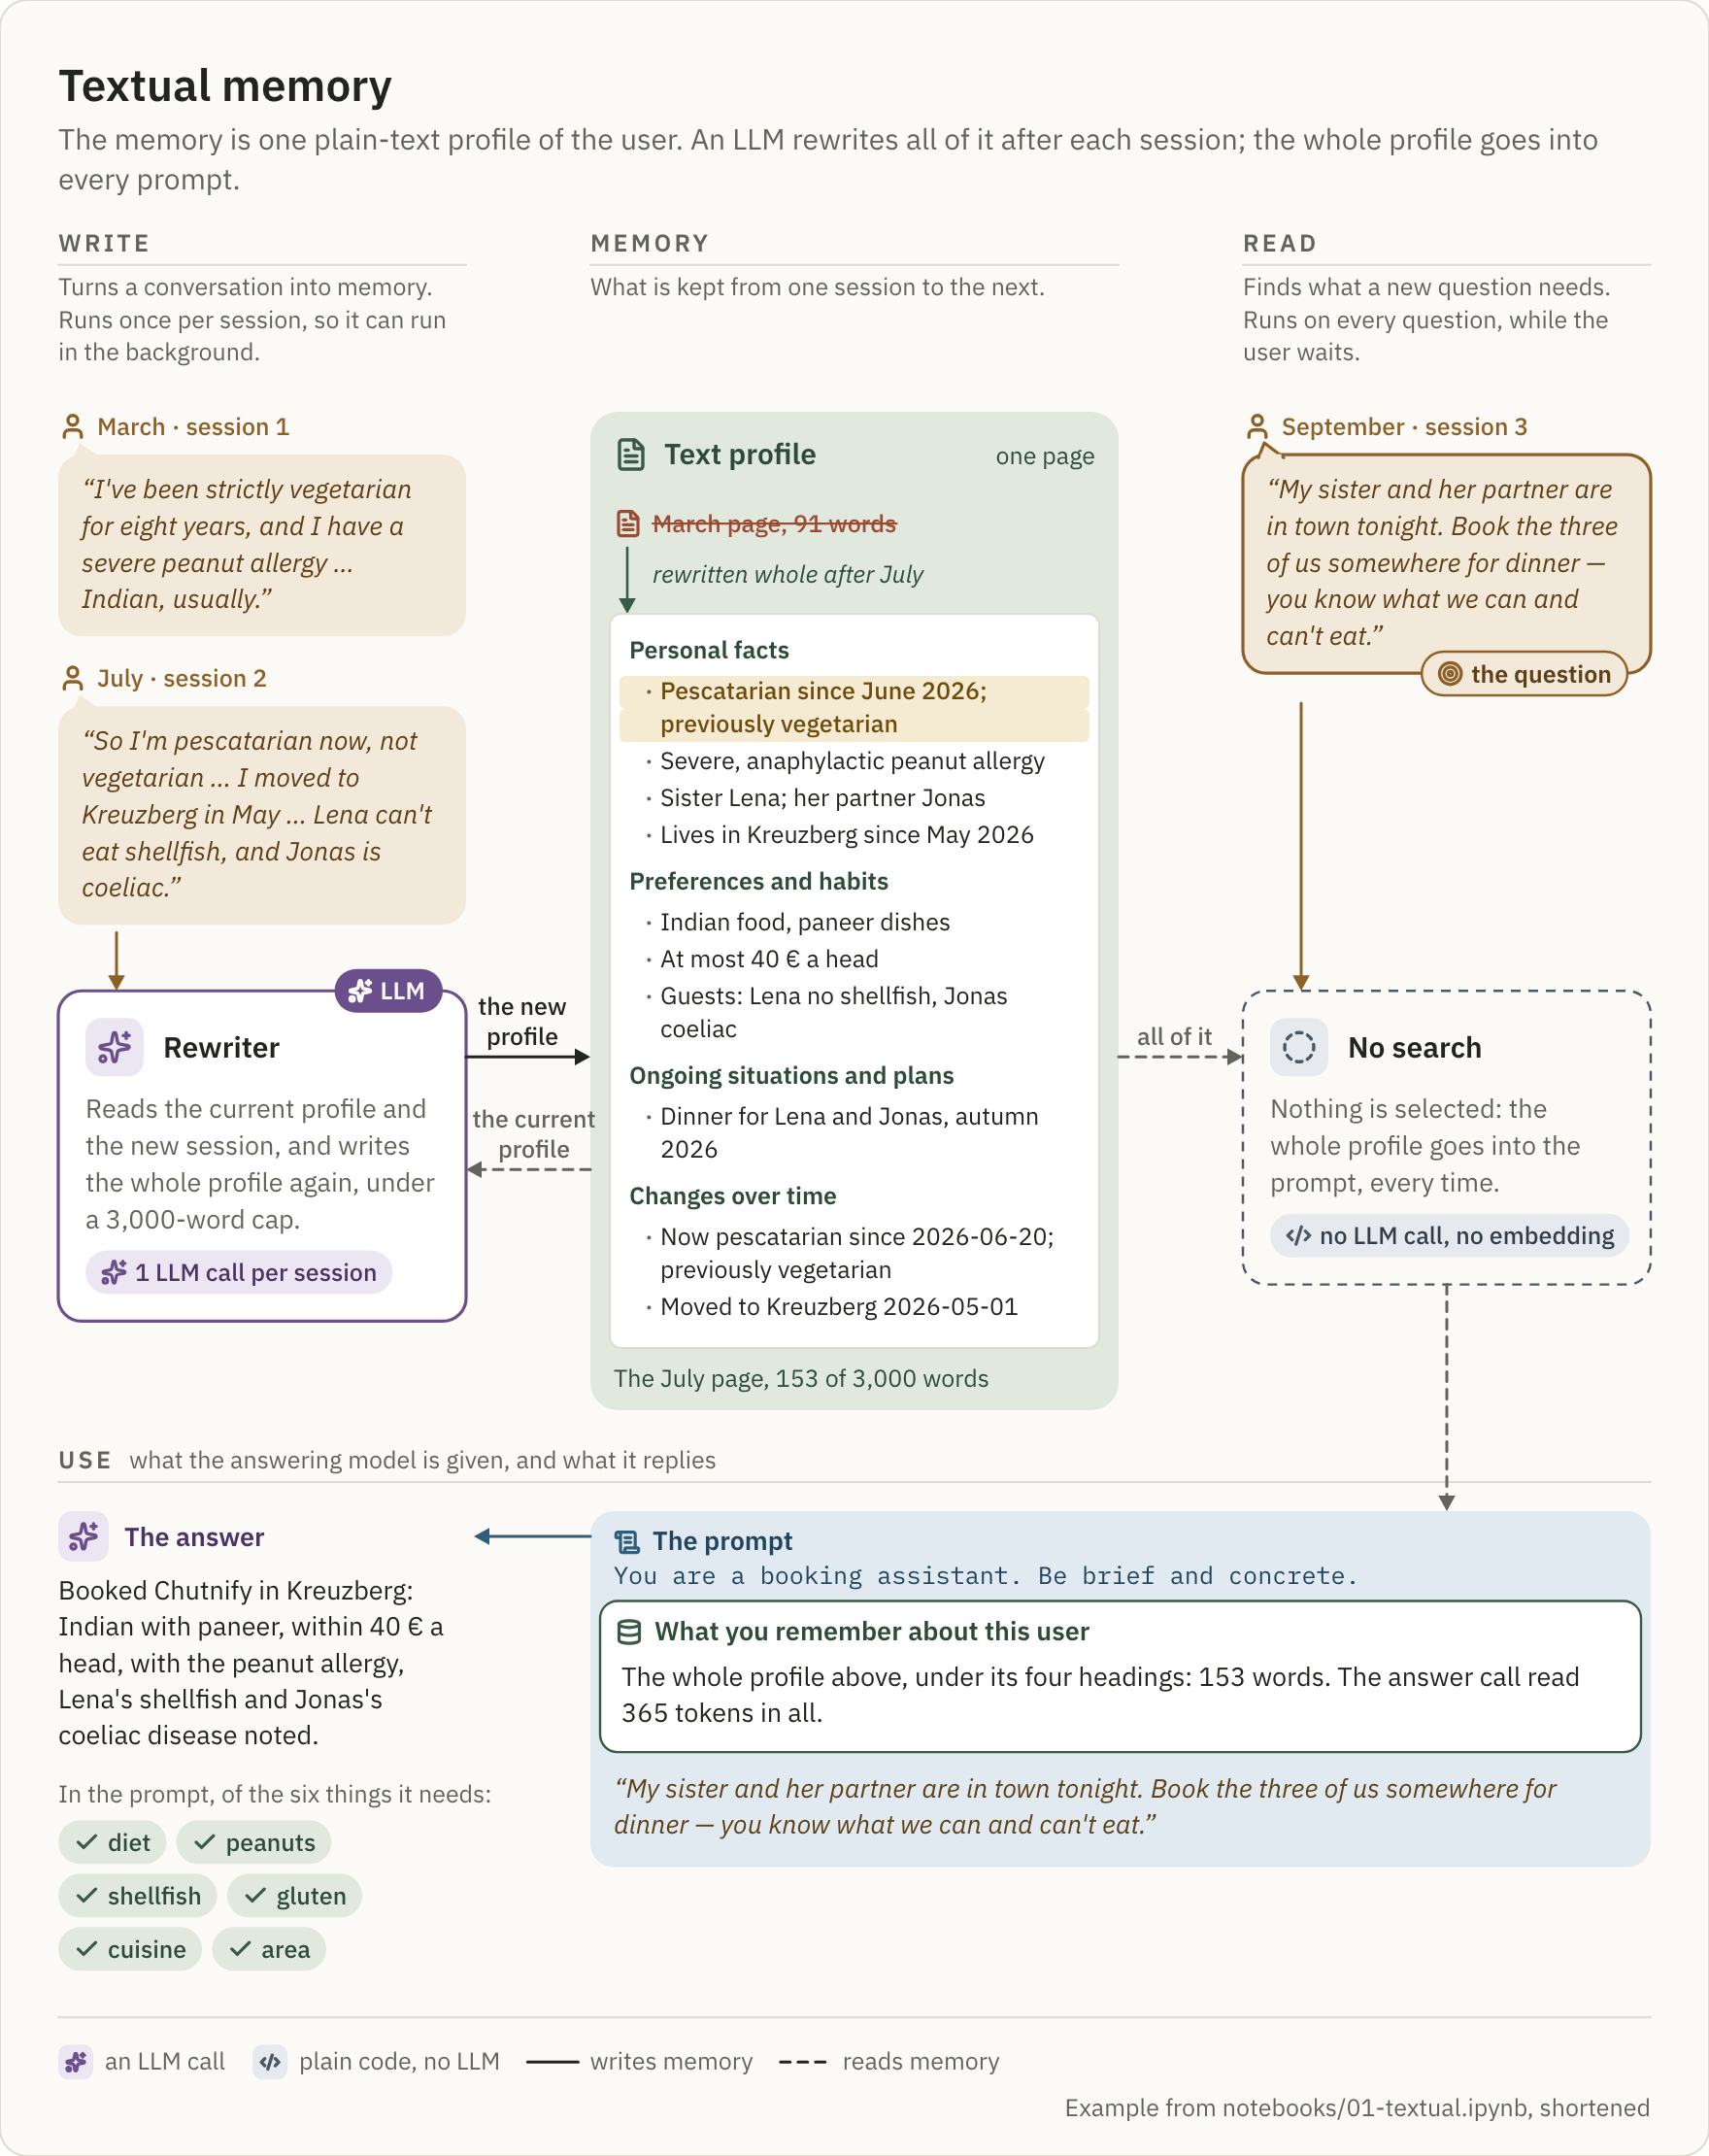
Textual memory, one profile rewritten in the background, traced through three sessions.
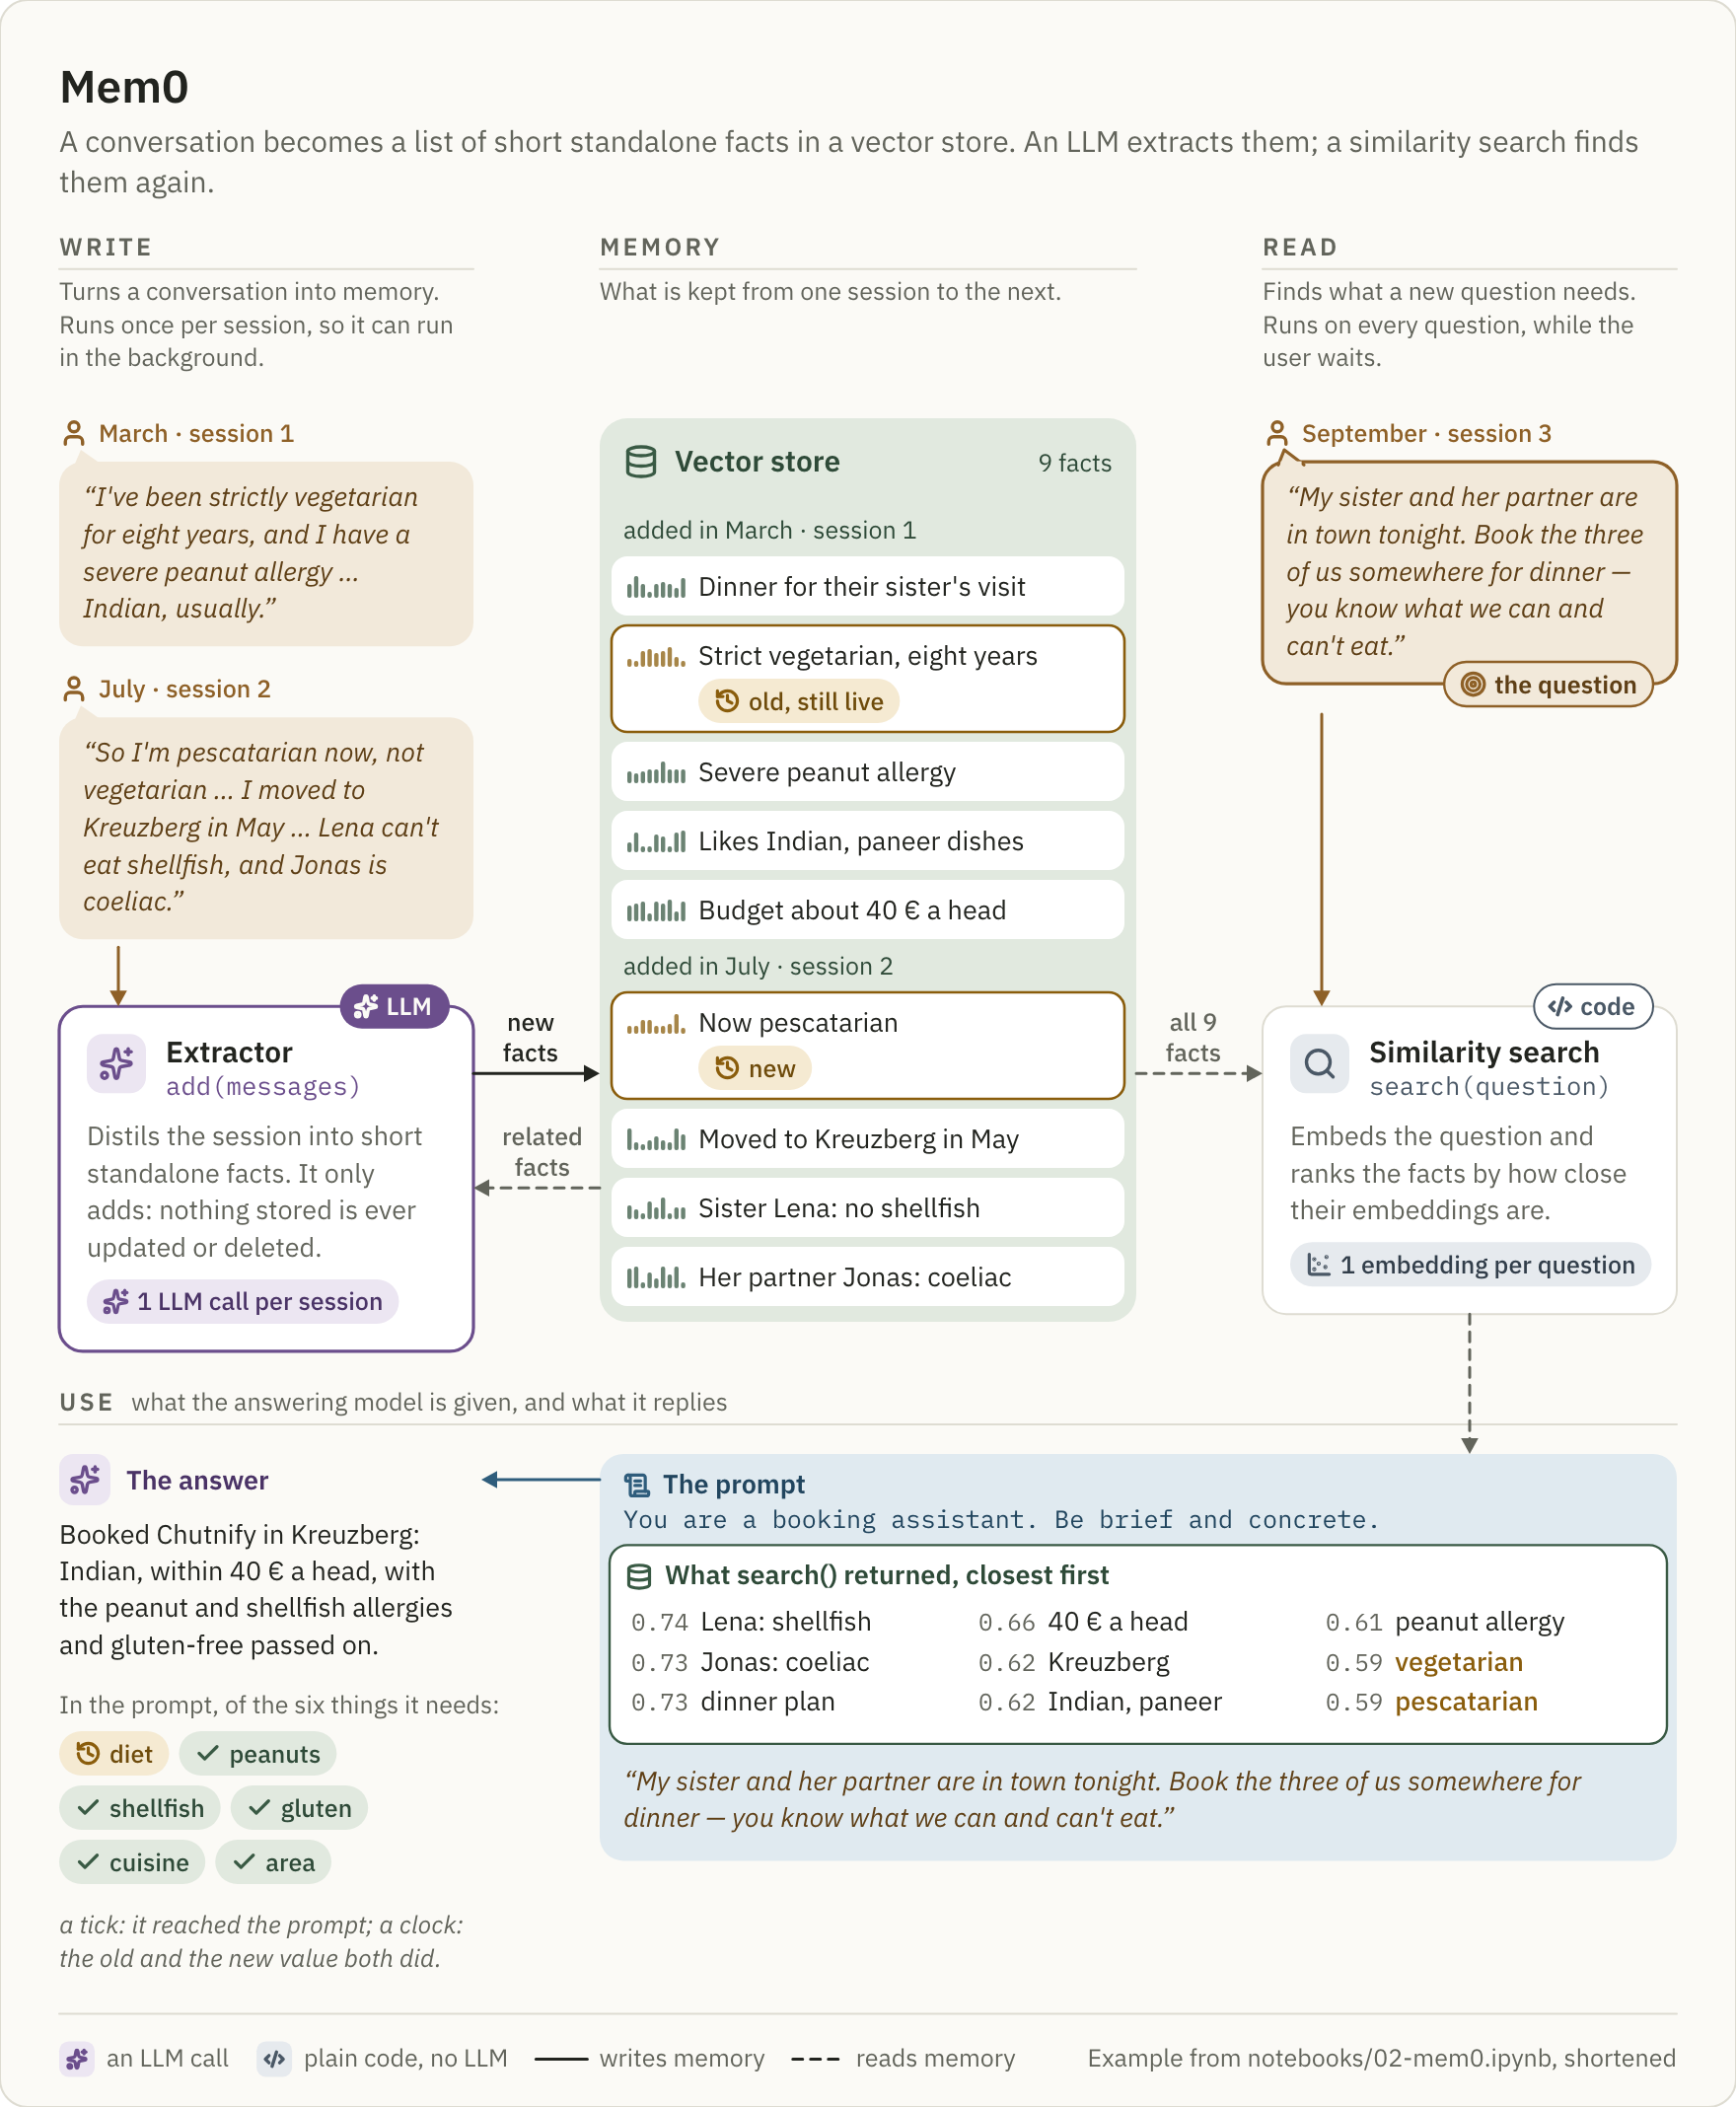
Mem0, facts extracted into a vector store, where the old diet stays live next to the new one.
Zep and Graphiti, a dated graph in which the old fact is closed and the new one opened.
Letta, where the answering agent edits its own memory blocks with tool calls mid-turn.
Honcho, a background reasoner that draws conclusions at several levels and retires them when a fact changes.
The same three sessions through five systems, with the calls each one made and what reached the prompt.
Accuracy with its 95% interval, and the cost of building the memory and answering, on 67 LongMemEval questions.
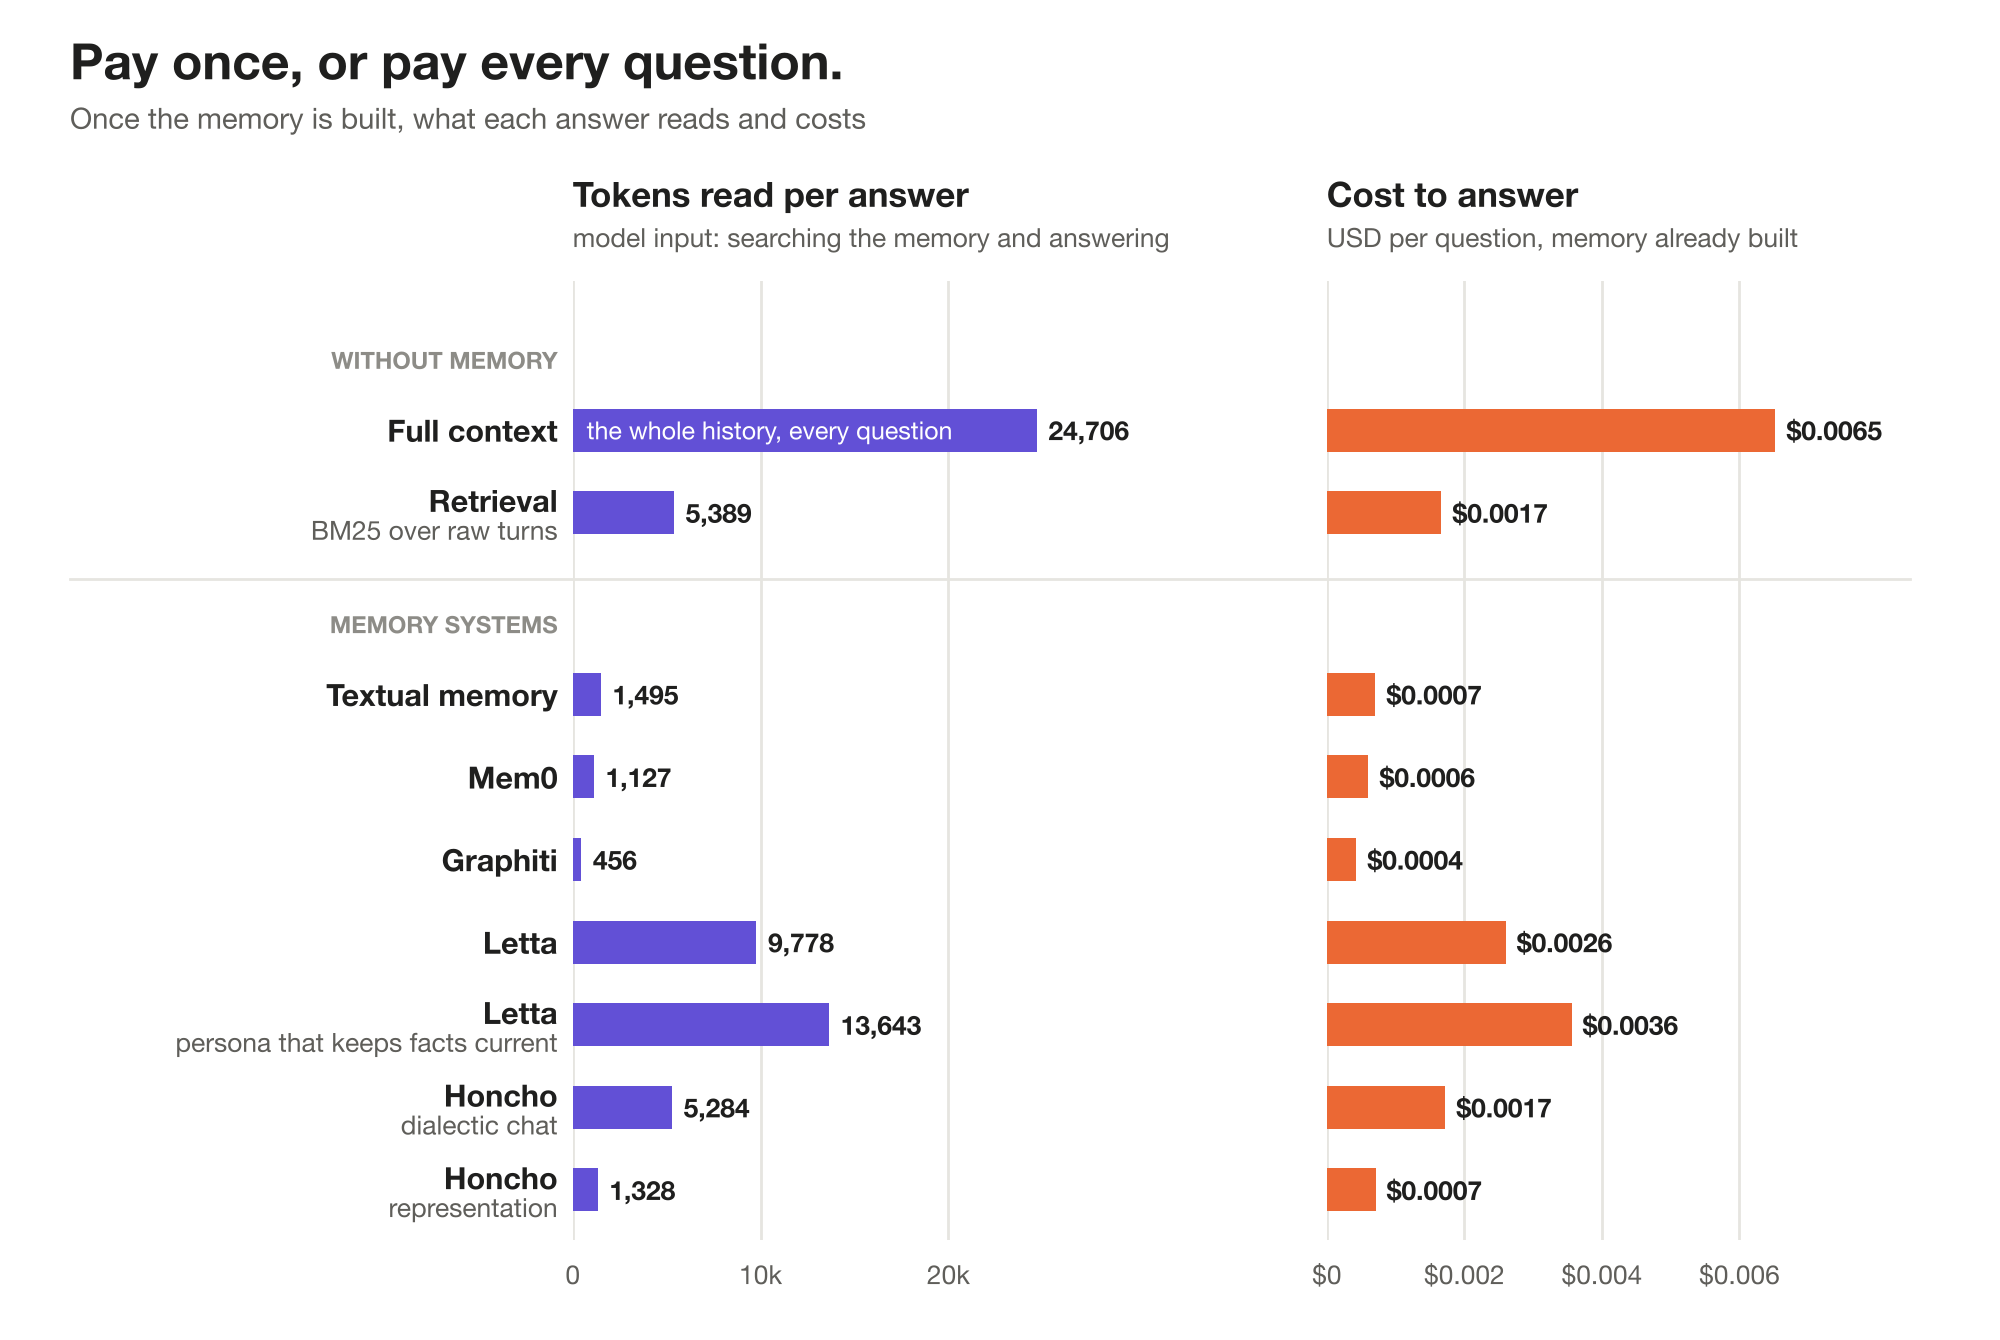
Once the memory is built, the tokens each answer reads and what it costs against full context.
  • llm agents
  • agent memory
  • llm evaluation
  • longmemeval
  • mem0
  • graphiti
  • letta
  • honcho

Mandarin Speech Coach

prototype

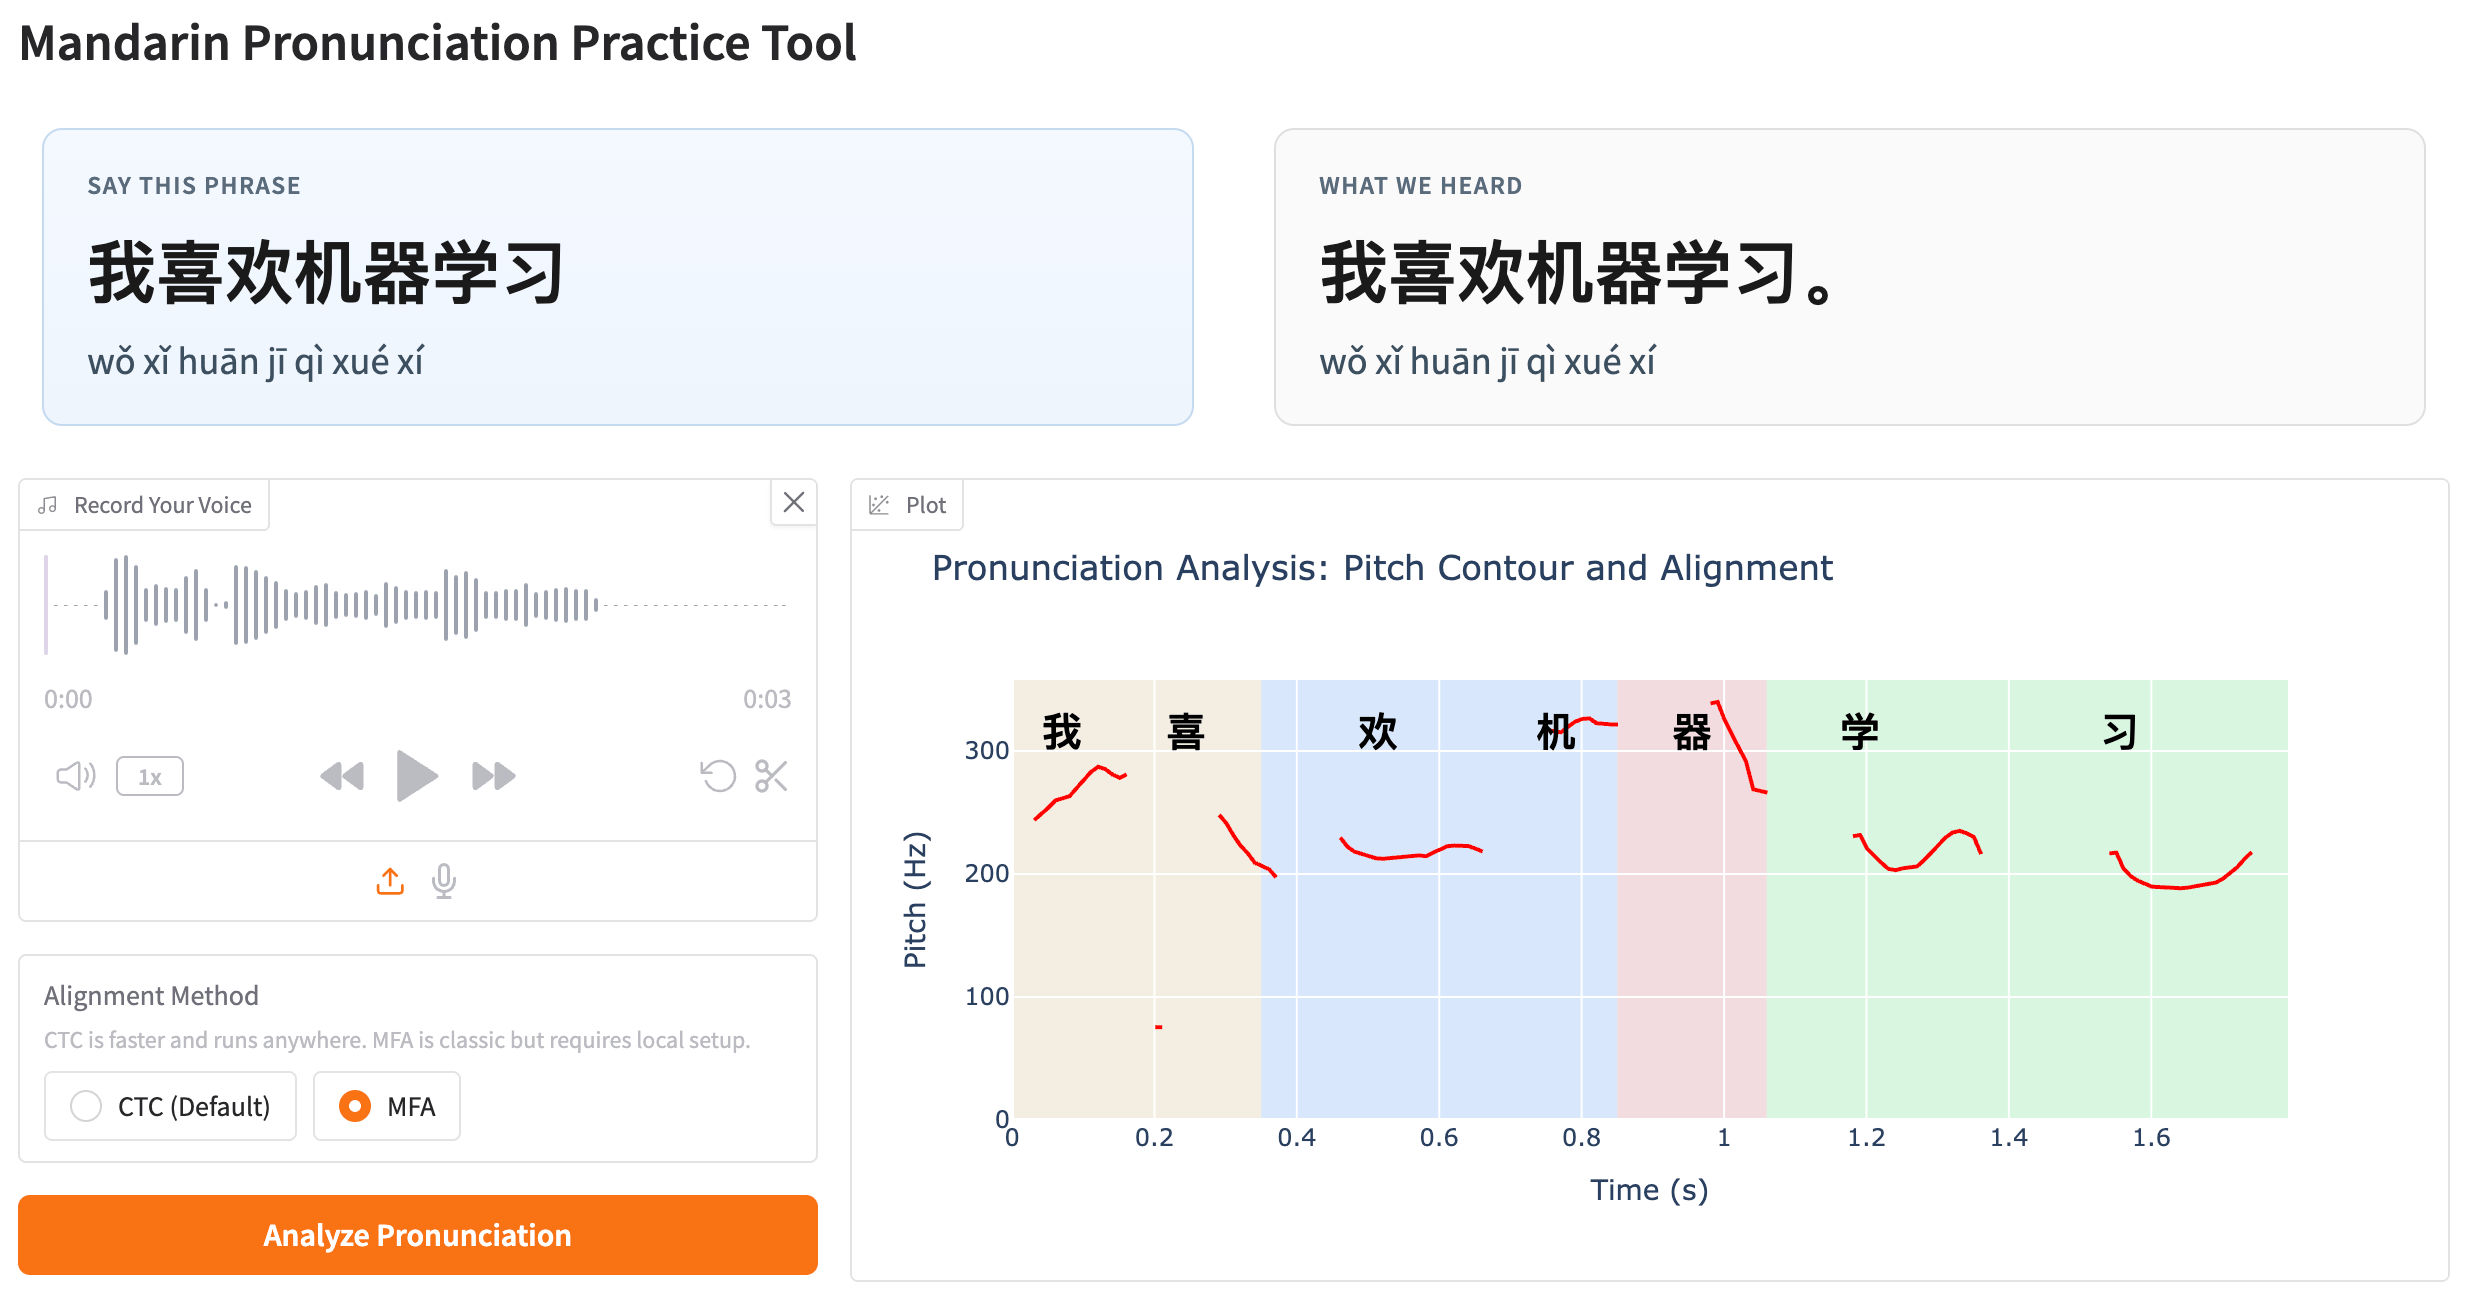
A different way to practise Mandarin tones. Other tools assess your pronunciation with a score; this one shows you what you said: your own pitch contour against the target phrase, aligned character by character and drawn in tone colours, so you can see which tone went wrong and how. To draw it, the recording is transcribed, force-aligned to its characters and pitch-tracked.

One phrase, your pitch contour against the target, aligned per character.
  • speech
  • pronunciation
  • mandarin
  • forced alignment
  • wav2vec2
  • whisper
  • pitch tracking
  • language learning

Retrieval and ranking

2 projects

Spoken Usage Retrieval

active

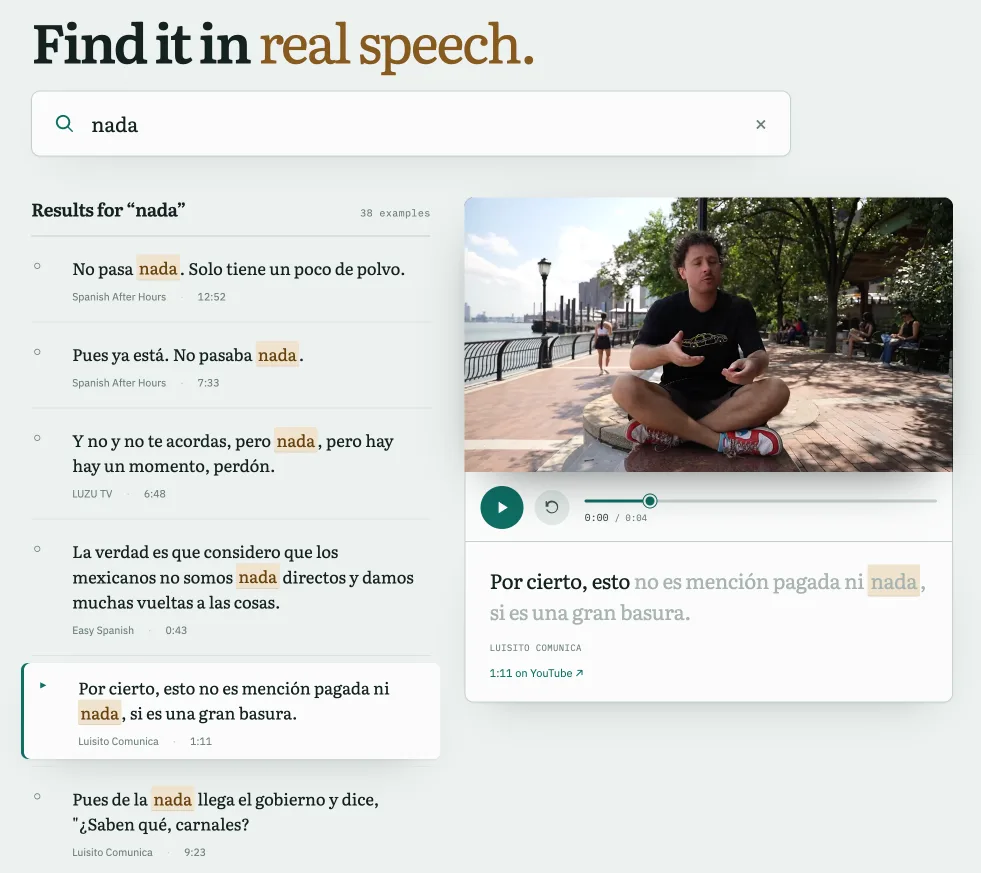
An information-retrieval system over native speech: it finds real uses of a word or phrase and plays the exact moment each is spoken. An indexing pipeline builds the corpus from the captions of curated YouTube channels. Retrieval matches words and short phrases by surface form and by lemma, and results are ranked and diversified across videos. Design decisions, from the lemmatiser for each language to aligning speech with subtitles, were made by experiments and measurement.

The web demo, searching Spanish speech for a phrase.
  • information retrieval
  • ranking
  • search
  • speech
  • forced alignment
  • nlp
  • language learning
  • python
Task Concept Retrieval

active

A retrieval test bed: given a task headline from a planner, return the one icon that conveys it, or nothing. The matching signal is generated: a vision model describes each of the 4,257 icons (what it shows, which tasks it suits, which it does not), and that description, never the icon's name, is what gets matched. Retrieval is built to be fast and to run locally, with small embedding and reranking models instead of an LLM, and a calibrated gate abstains when no icon is good enough.

  • information retrieval
  • semantic search
  • embeddings
  • sentence embeddings
  • reranking
  • calibration
  • python
Reading research papers with LLM agents

designed by measurement 3 projects

A set of tools for keeping your own library of research papers and reading it with the help of a coding agent, which finds new papers, explains them and answers questions across the whole library. Every part was designed by measurement (the text format the agent reads, the prompts, the models), and the experiments are in the repository. The library works on its own in Claude Code. To read a paper with its chat side by side, open it in Carrel on a tablet or a Mac, or in PDF Viewer for VS Code; in either, a citation in the chat opens the paper at the cited page.

Agentic paper library

active

Your own library of research papers, filed in your own topic tree, with a coding agent to help you work with it: find new papers, understand one, and answer a question across the whole library. Each paper is kept twice: the PDF, for you to read, and its text layer with every page marked, which the agent searches across the library and cites by page (a format chosen among alternatives by experiment). Skills add and remove papers and file each in its topic, write an overview to read first and a literature review of an area, and find papers by their text or by their meaning.

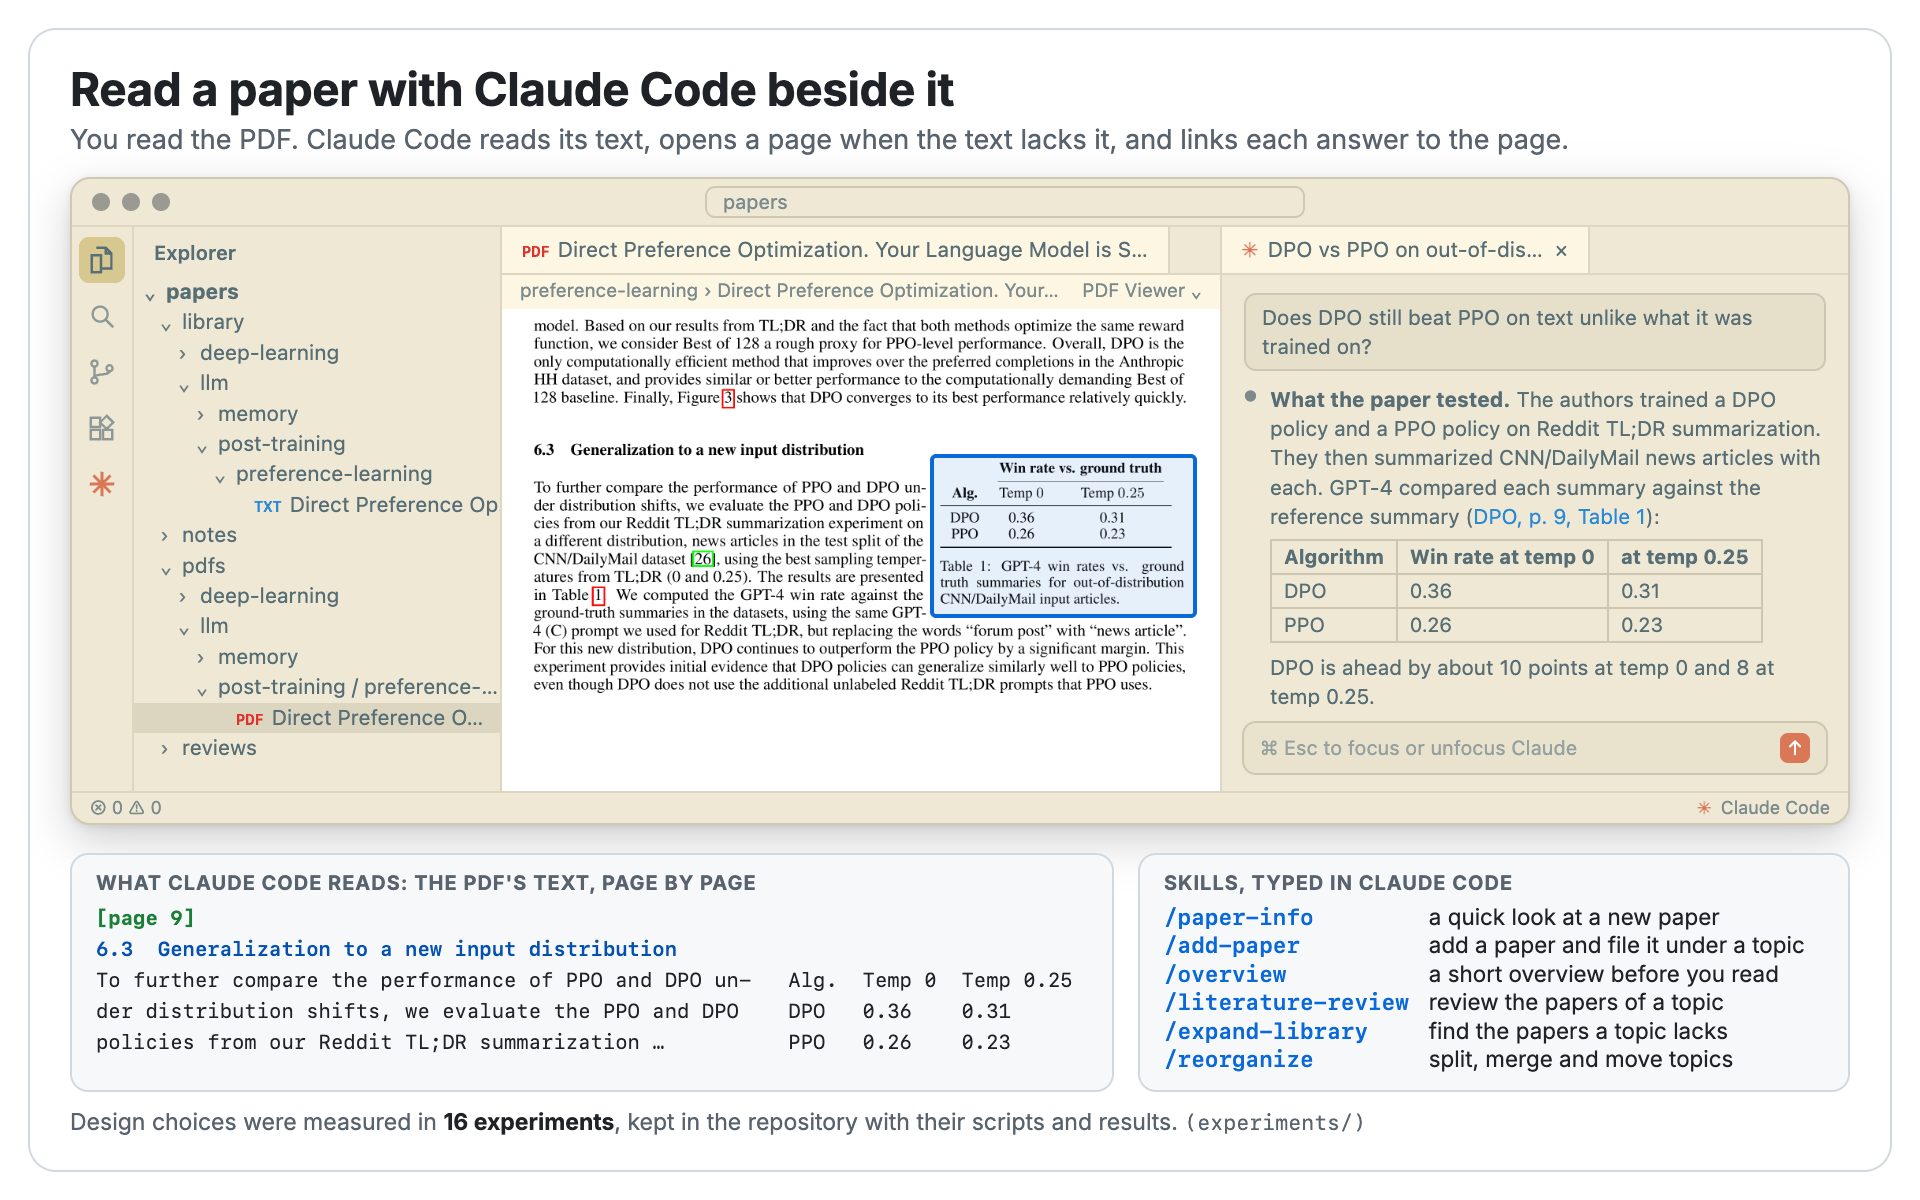
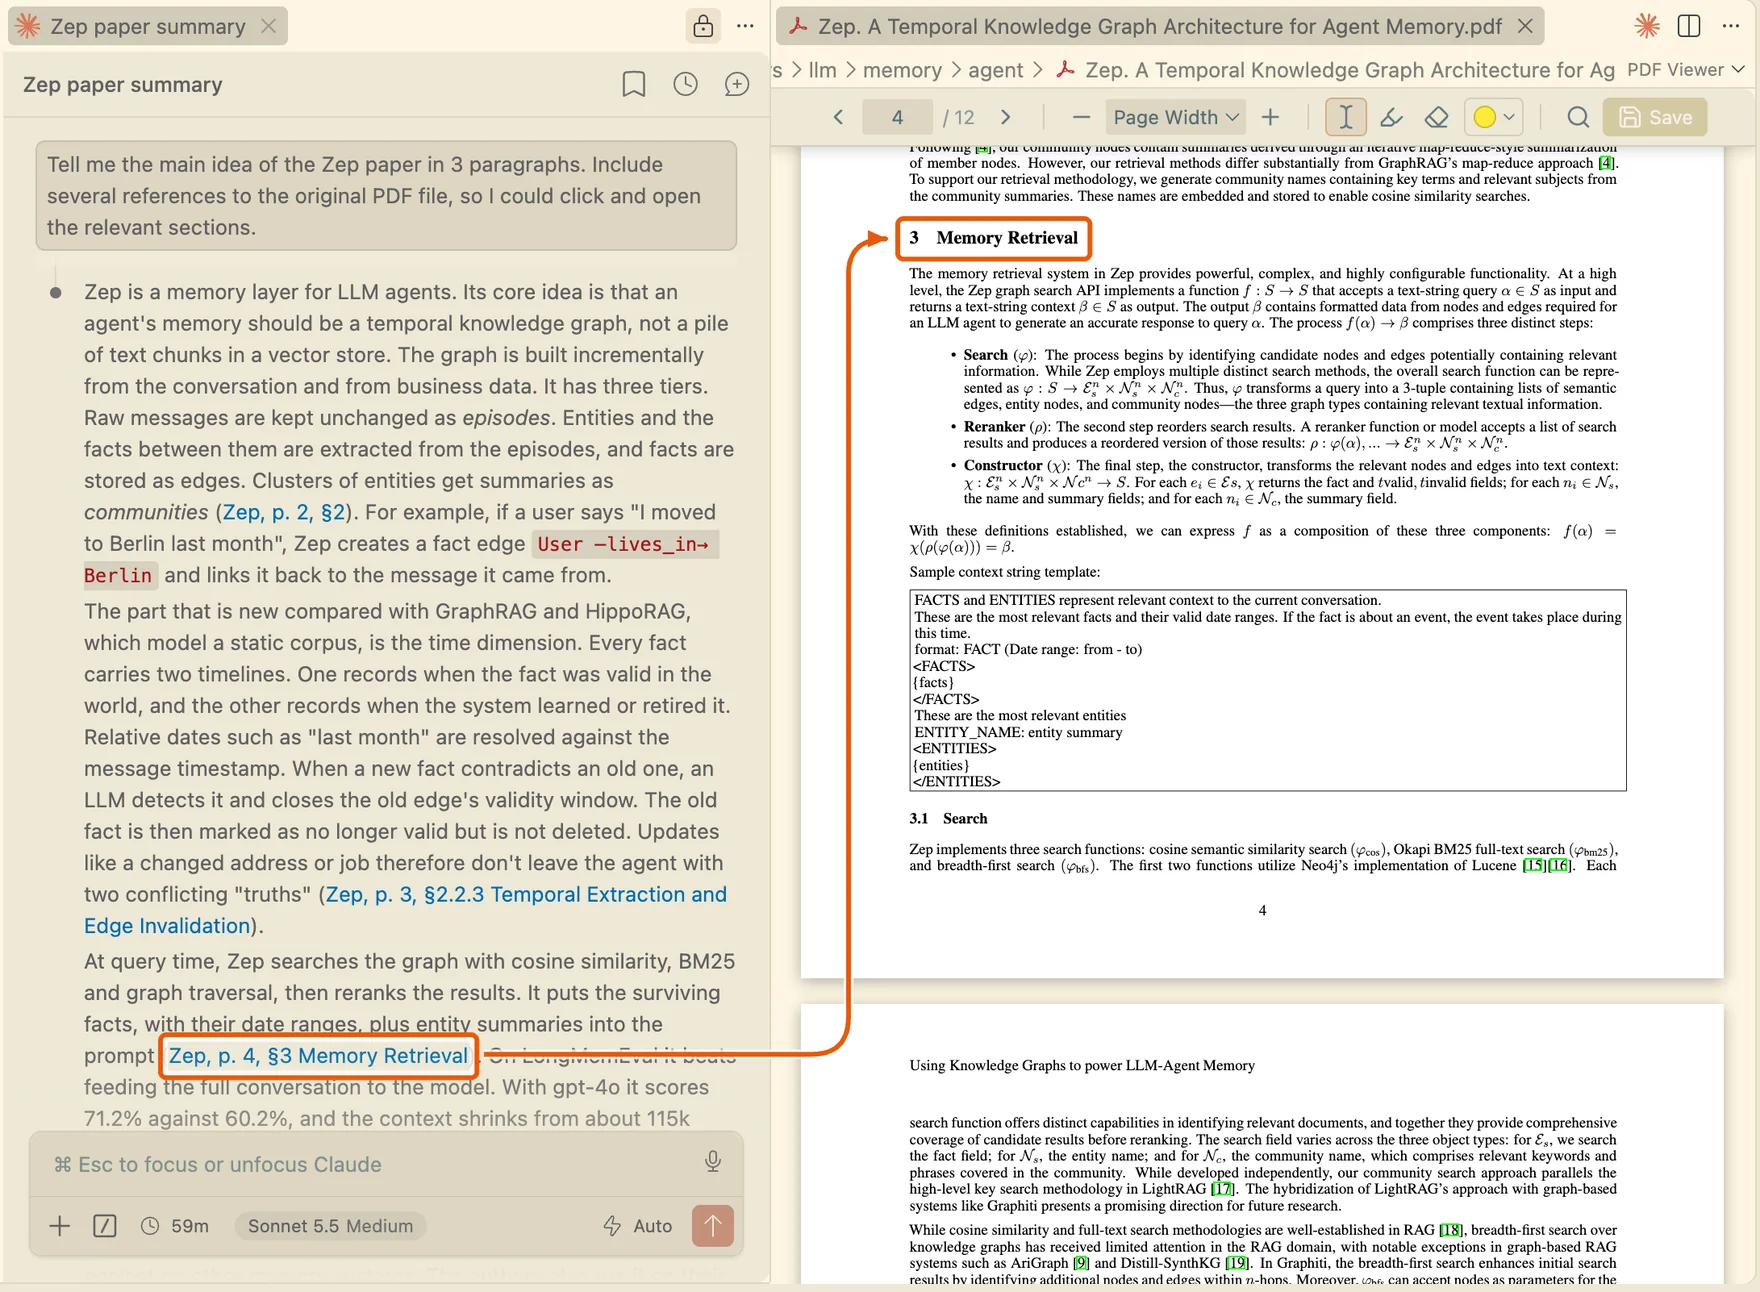
Reading a paper's PDF in VS Code with Claude Code beside it; the answer links to the page and the table.
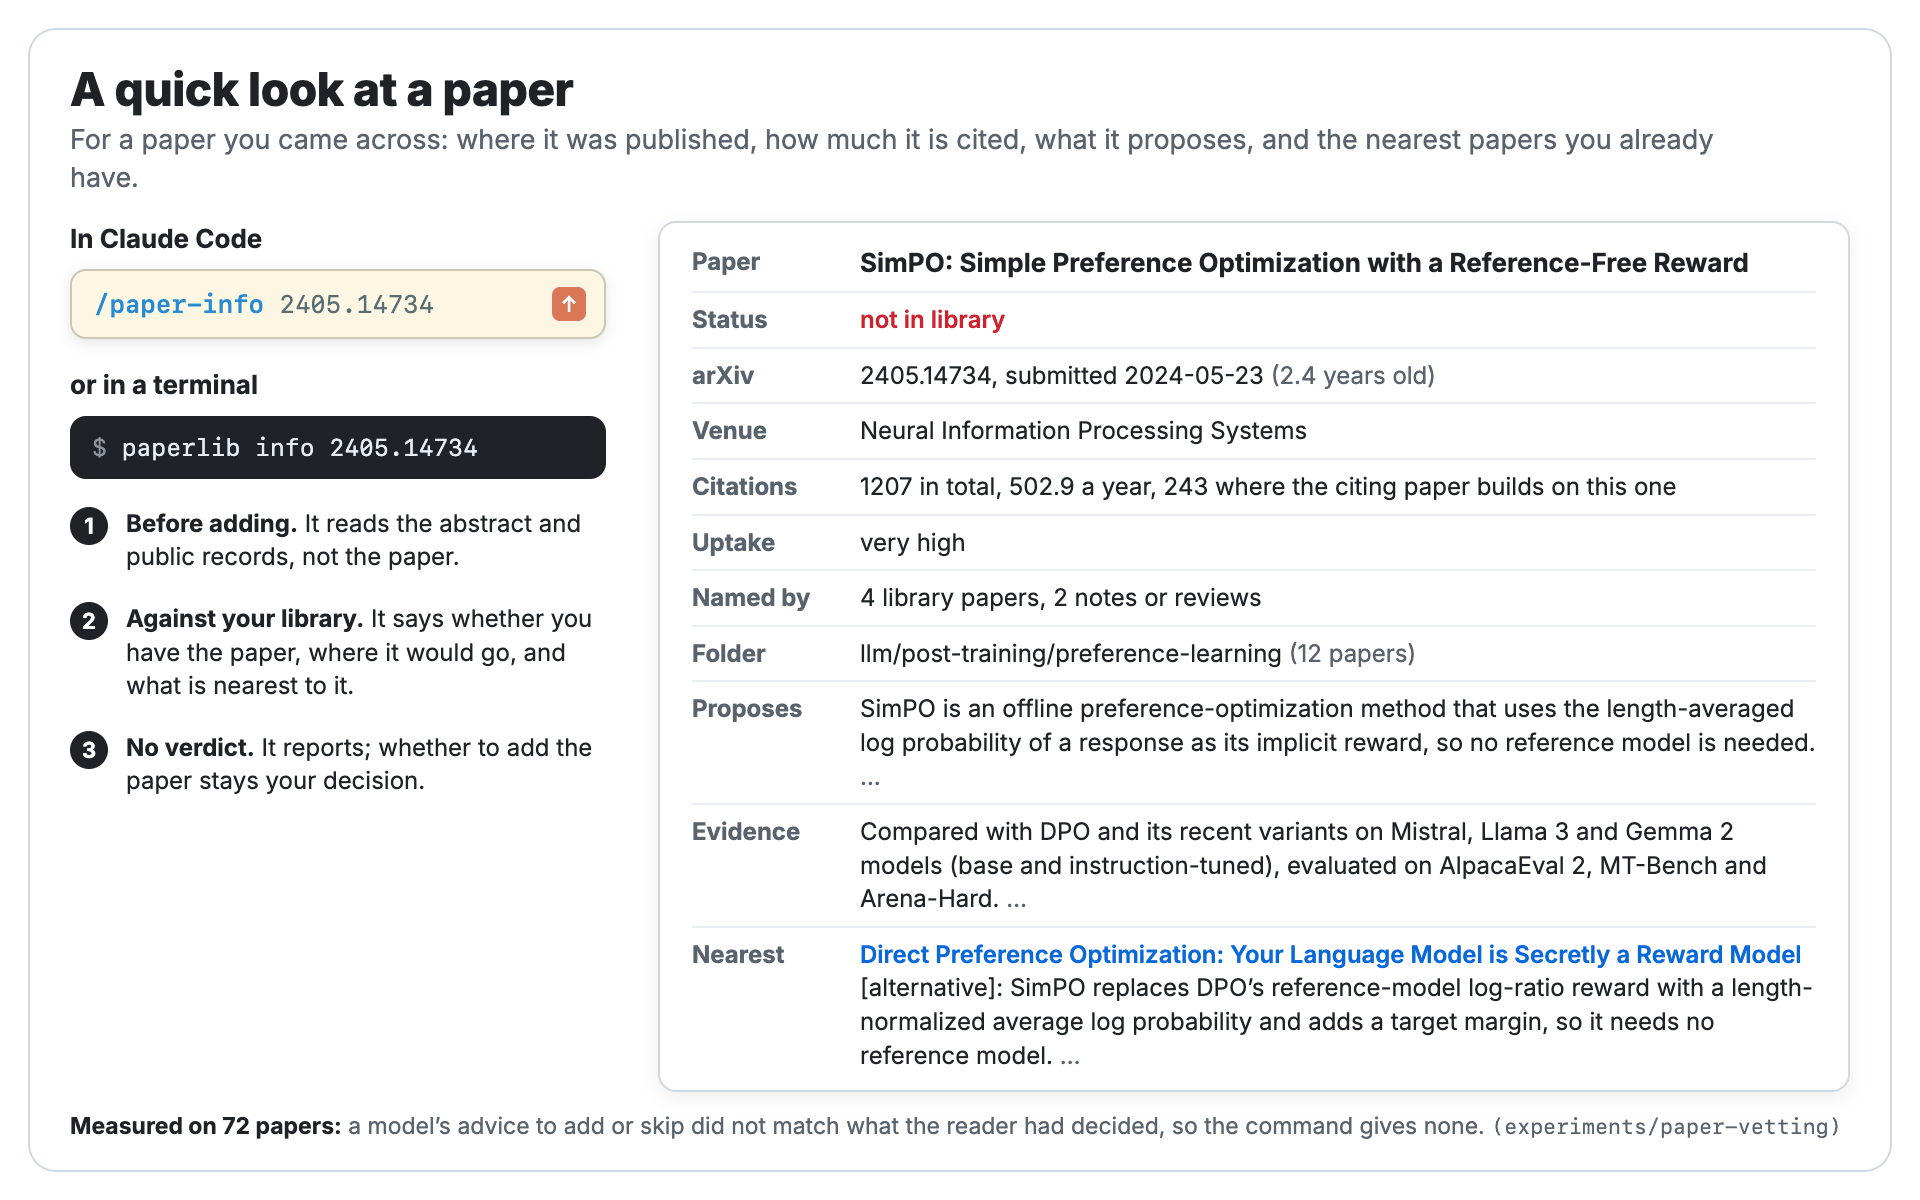
A quick look at a paper before adding it, from public records, with its nearest paper in the library.
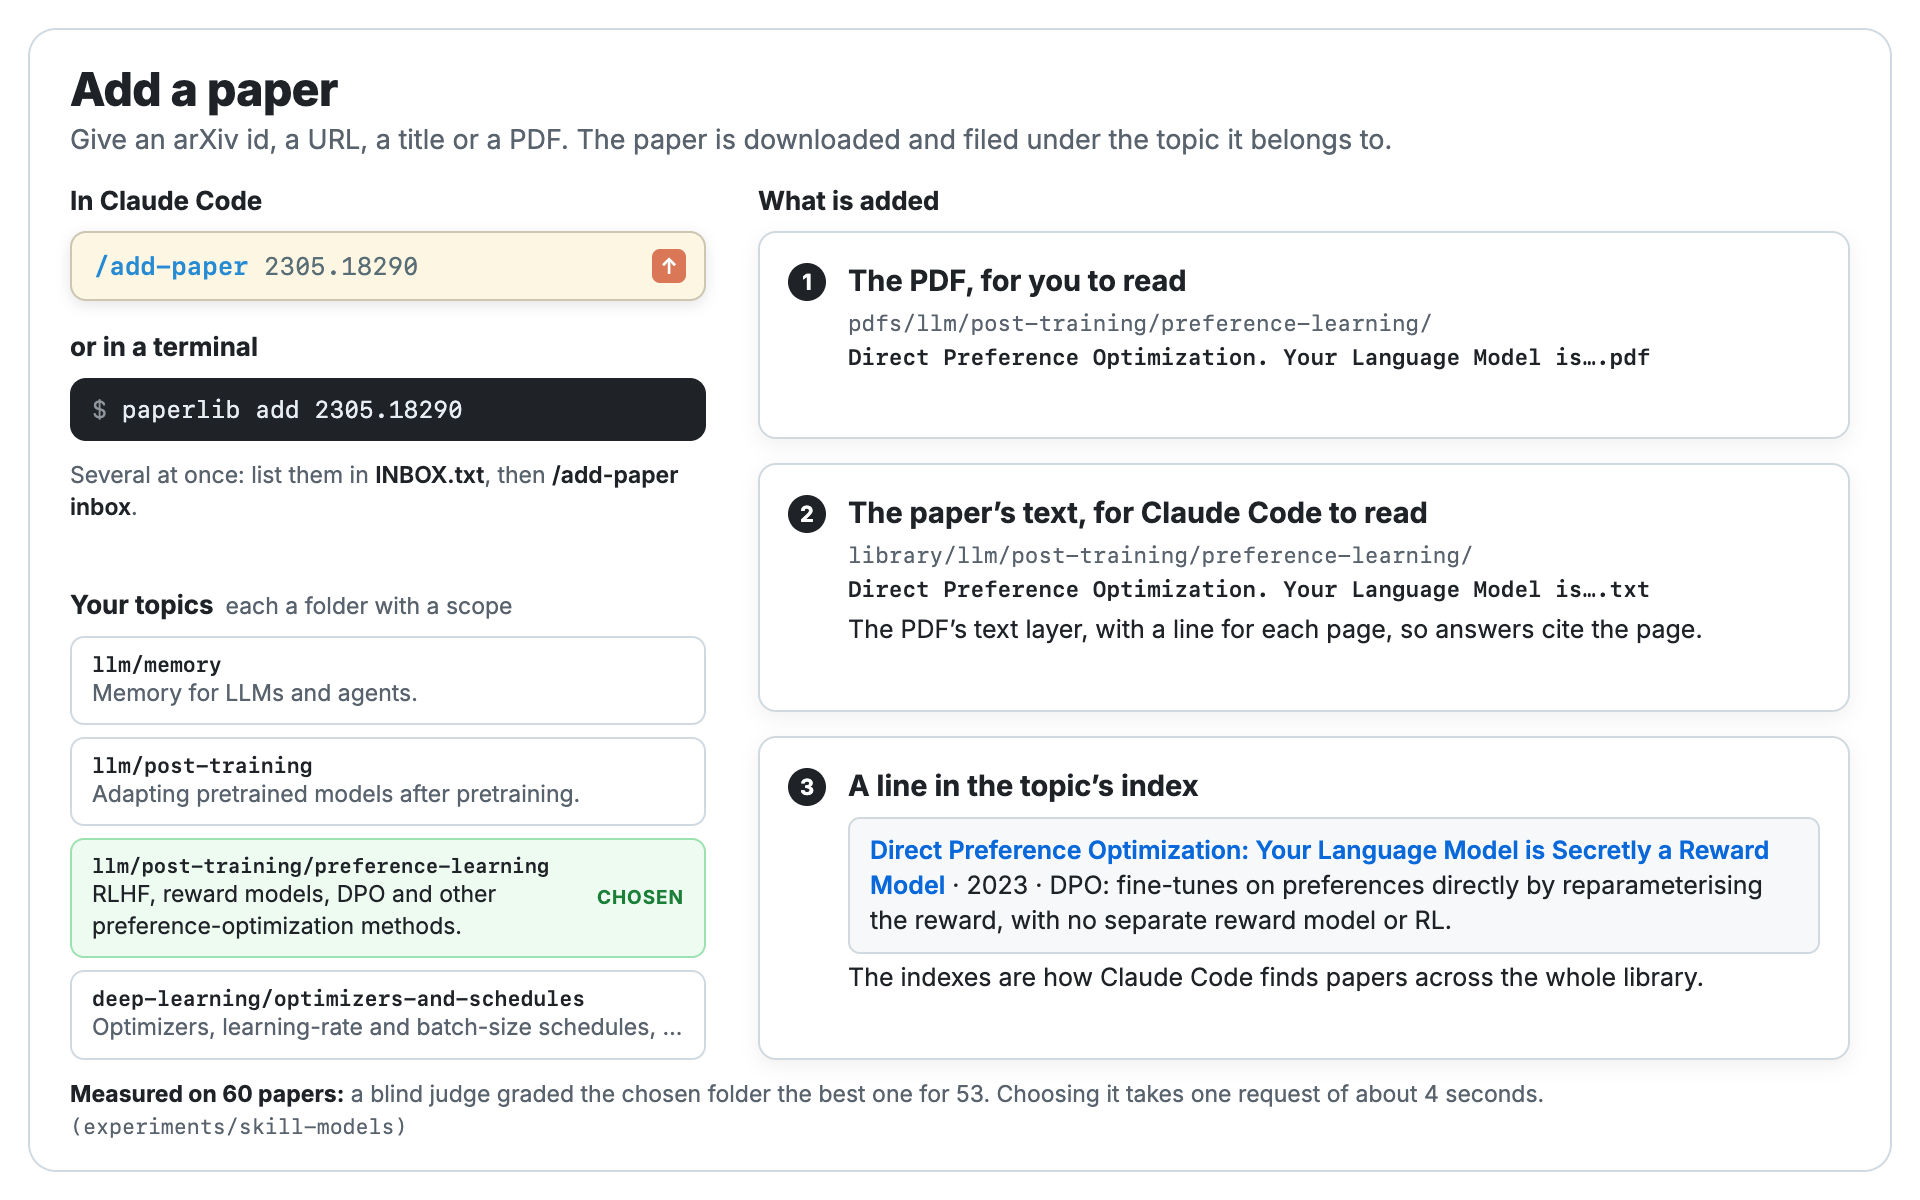
Adding a paper, with the topic folder chosen from the declared tree, the PDF and its text kept, and a summary line written.
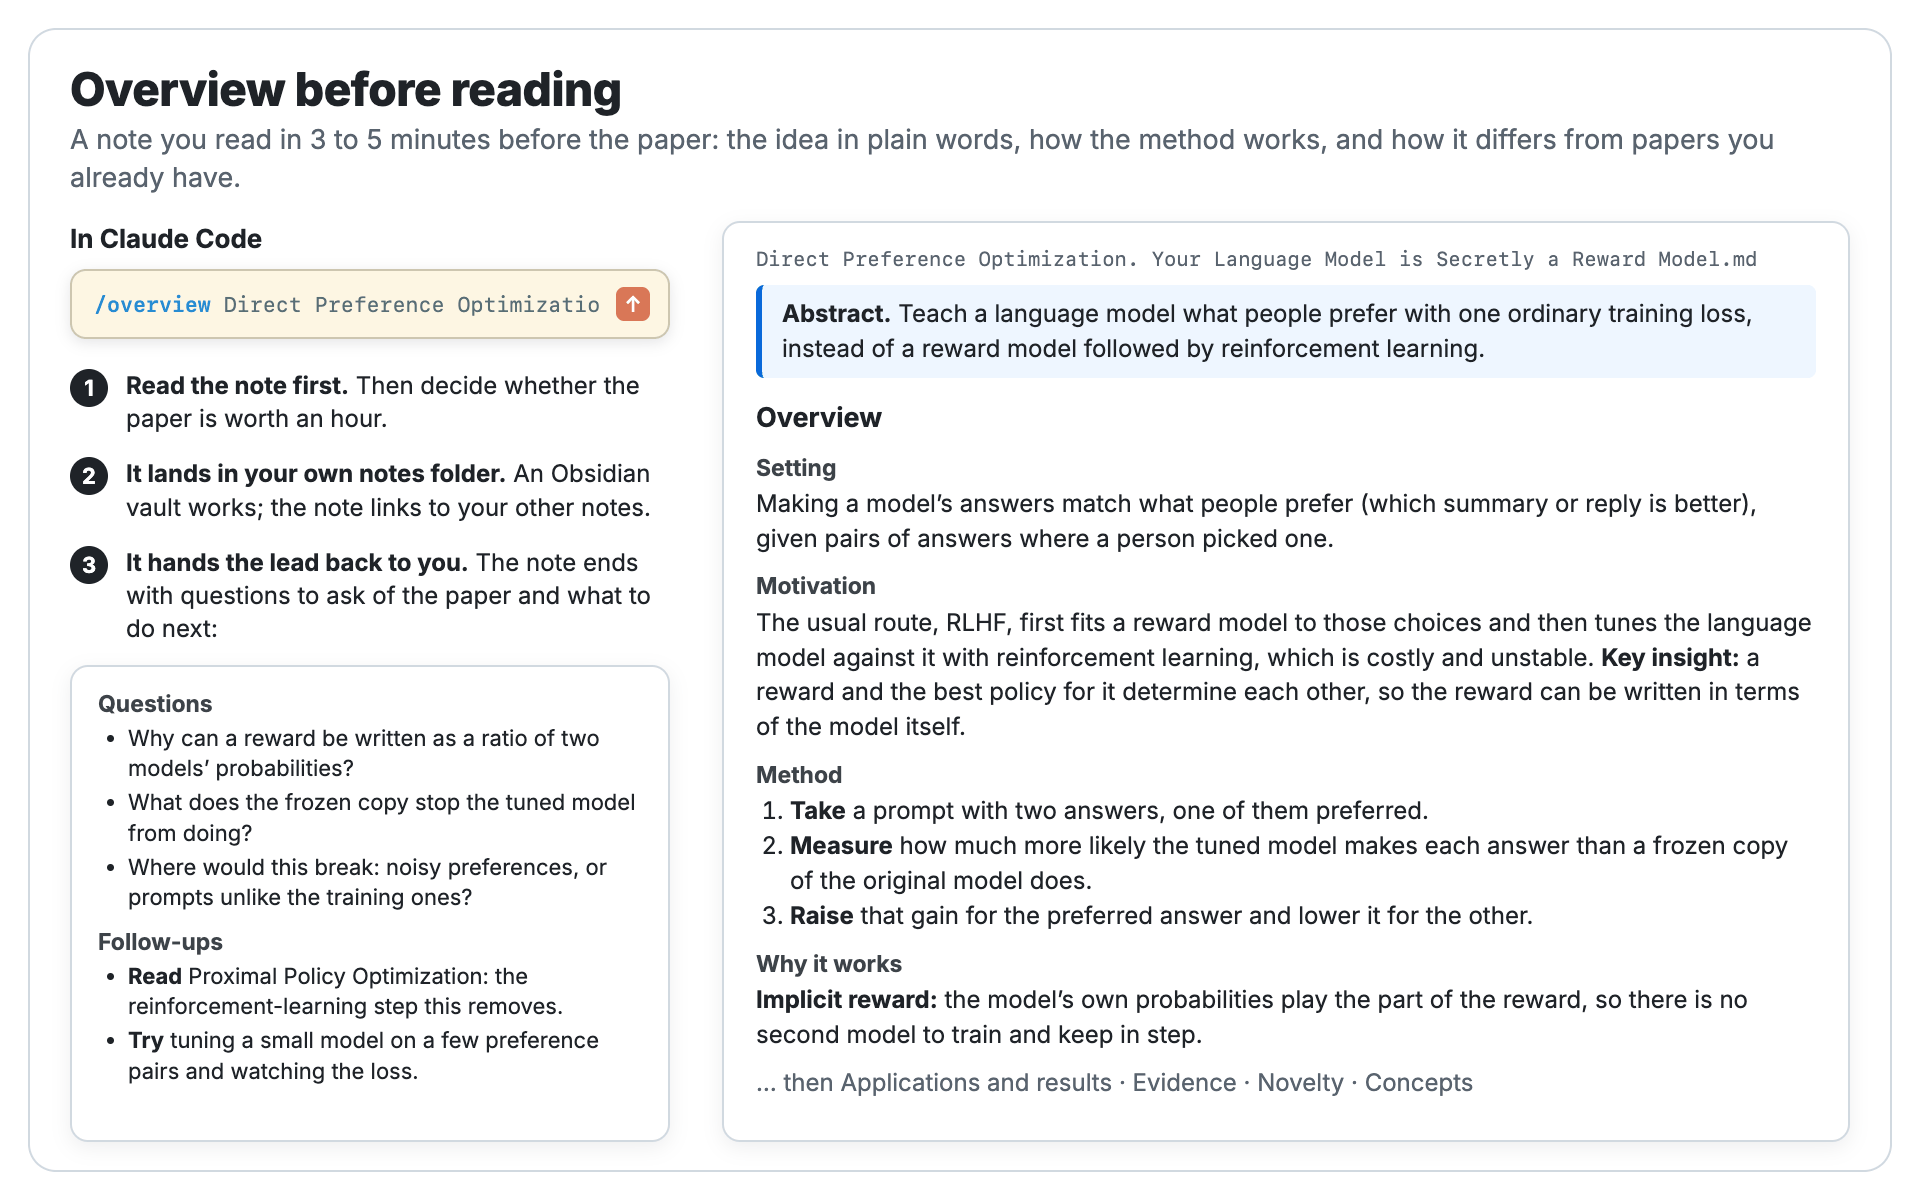
The overview note a skill writes for a paper, to read in a few minutes before the paper itself.
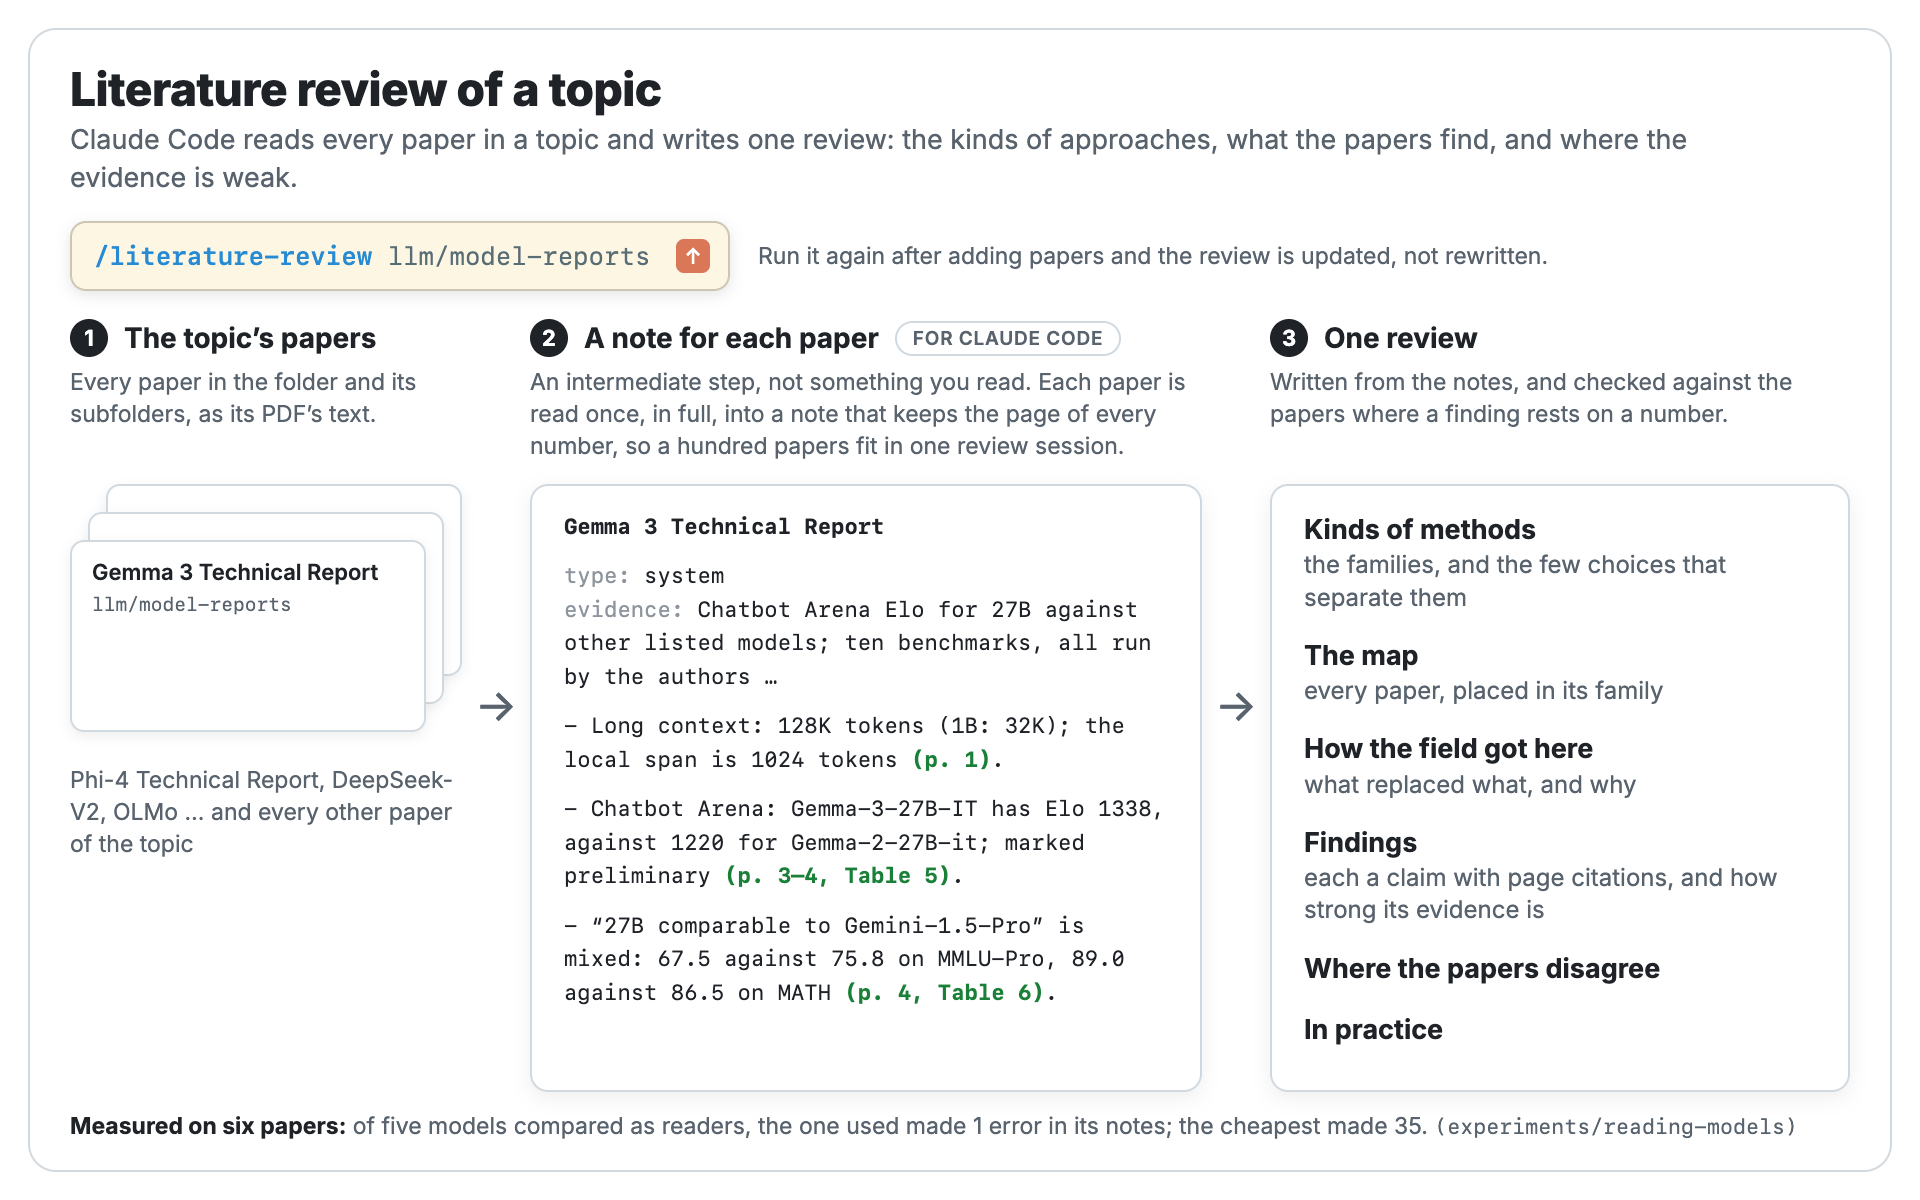
A literature review of a topic, written from one note for each paper.
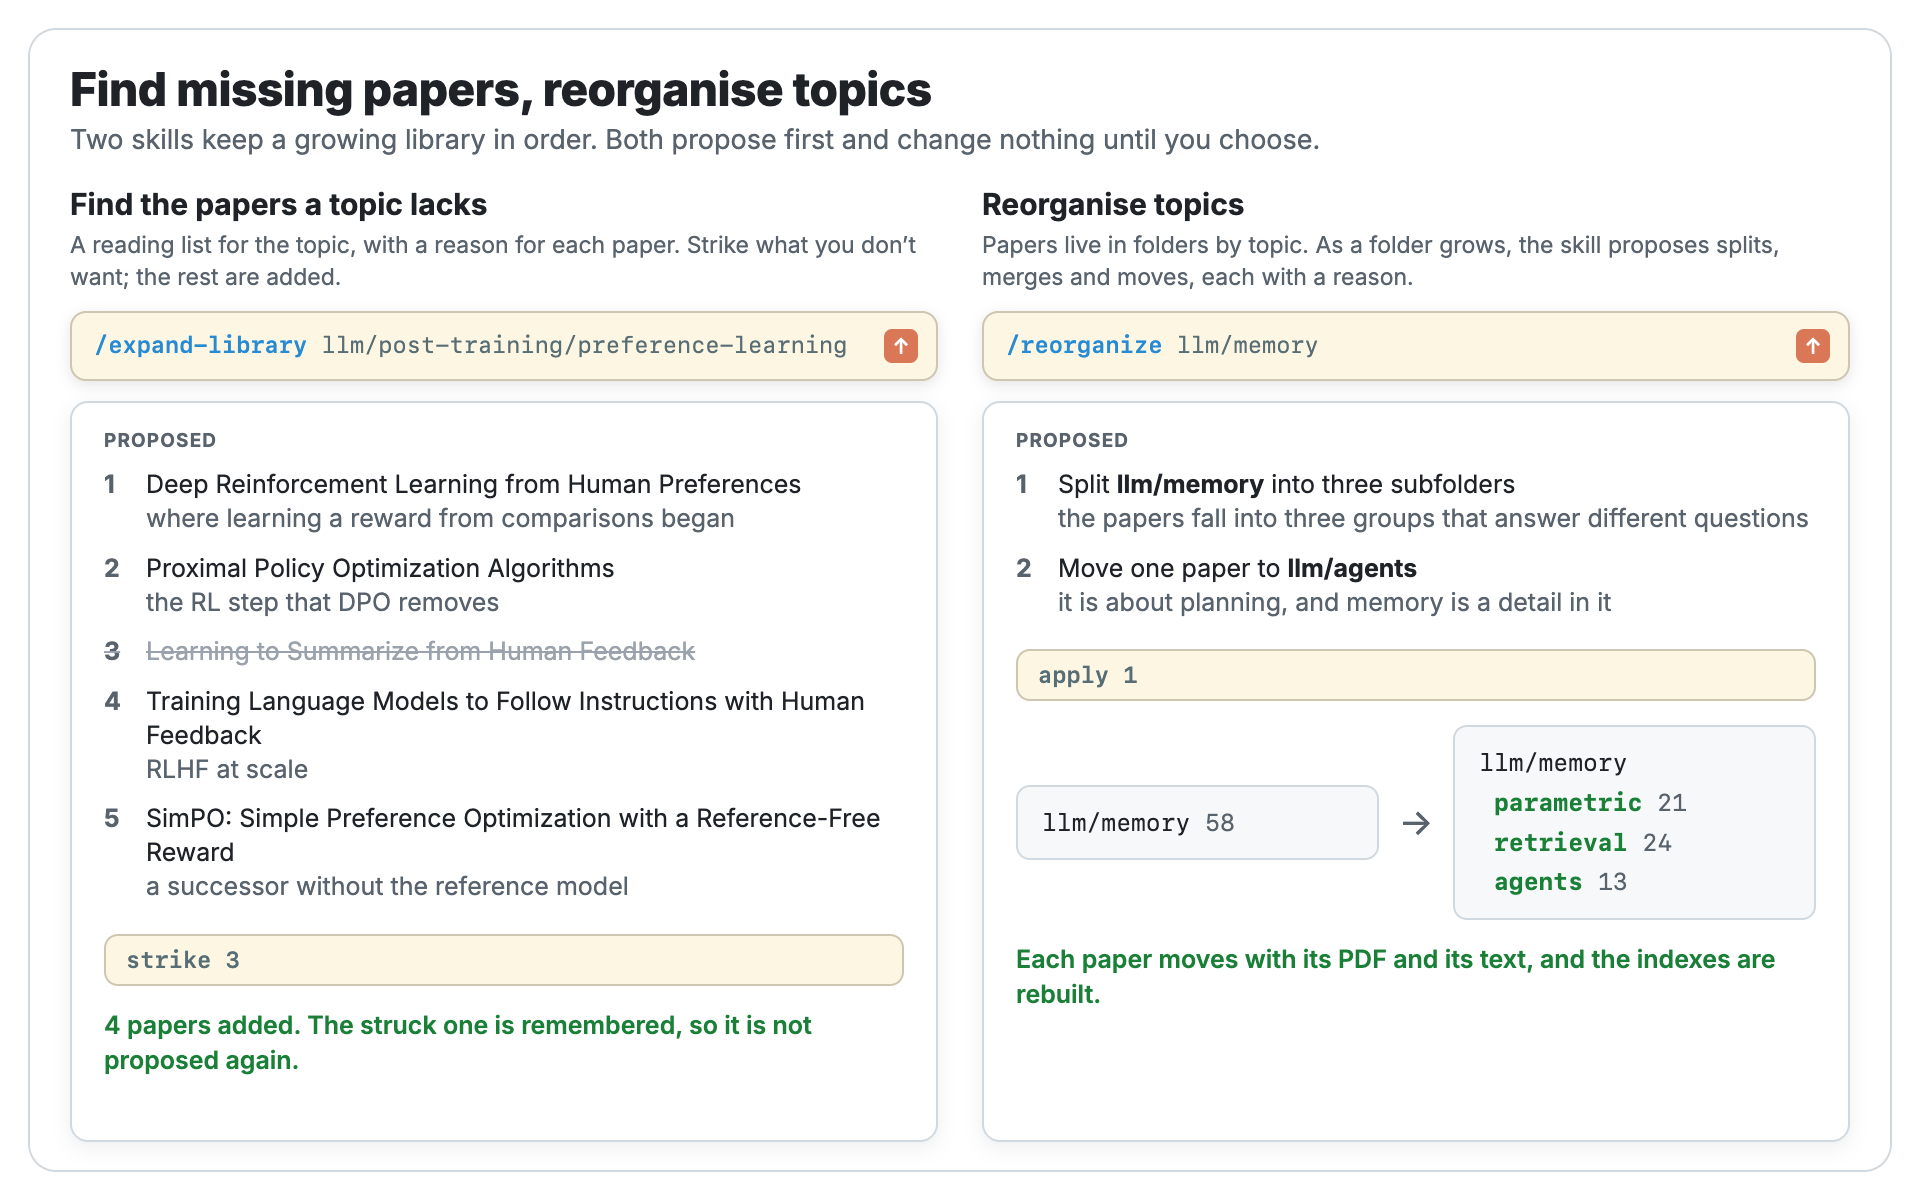
Finding missing papers for a topic, and proposing splits and merges of its folders; nothing changes until you choose.
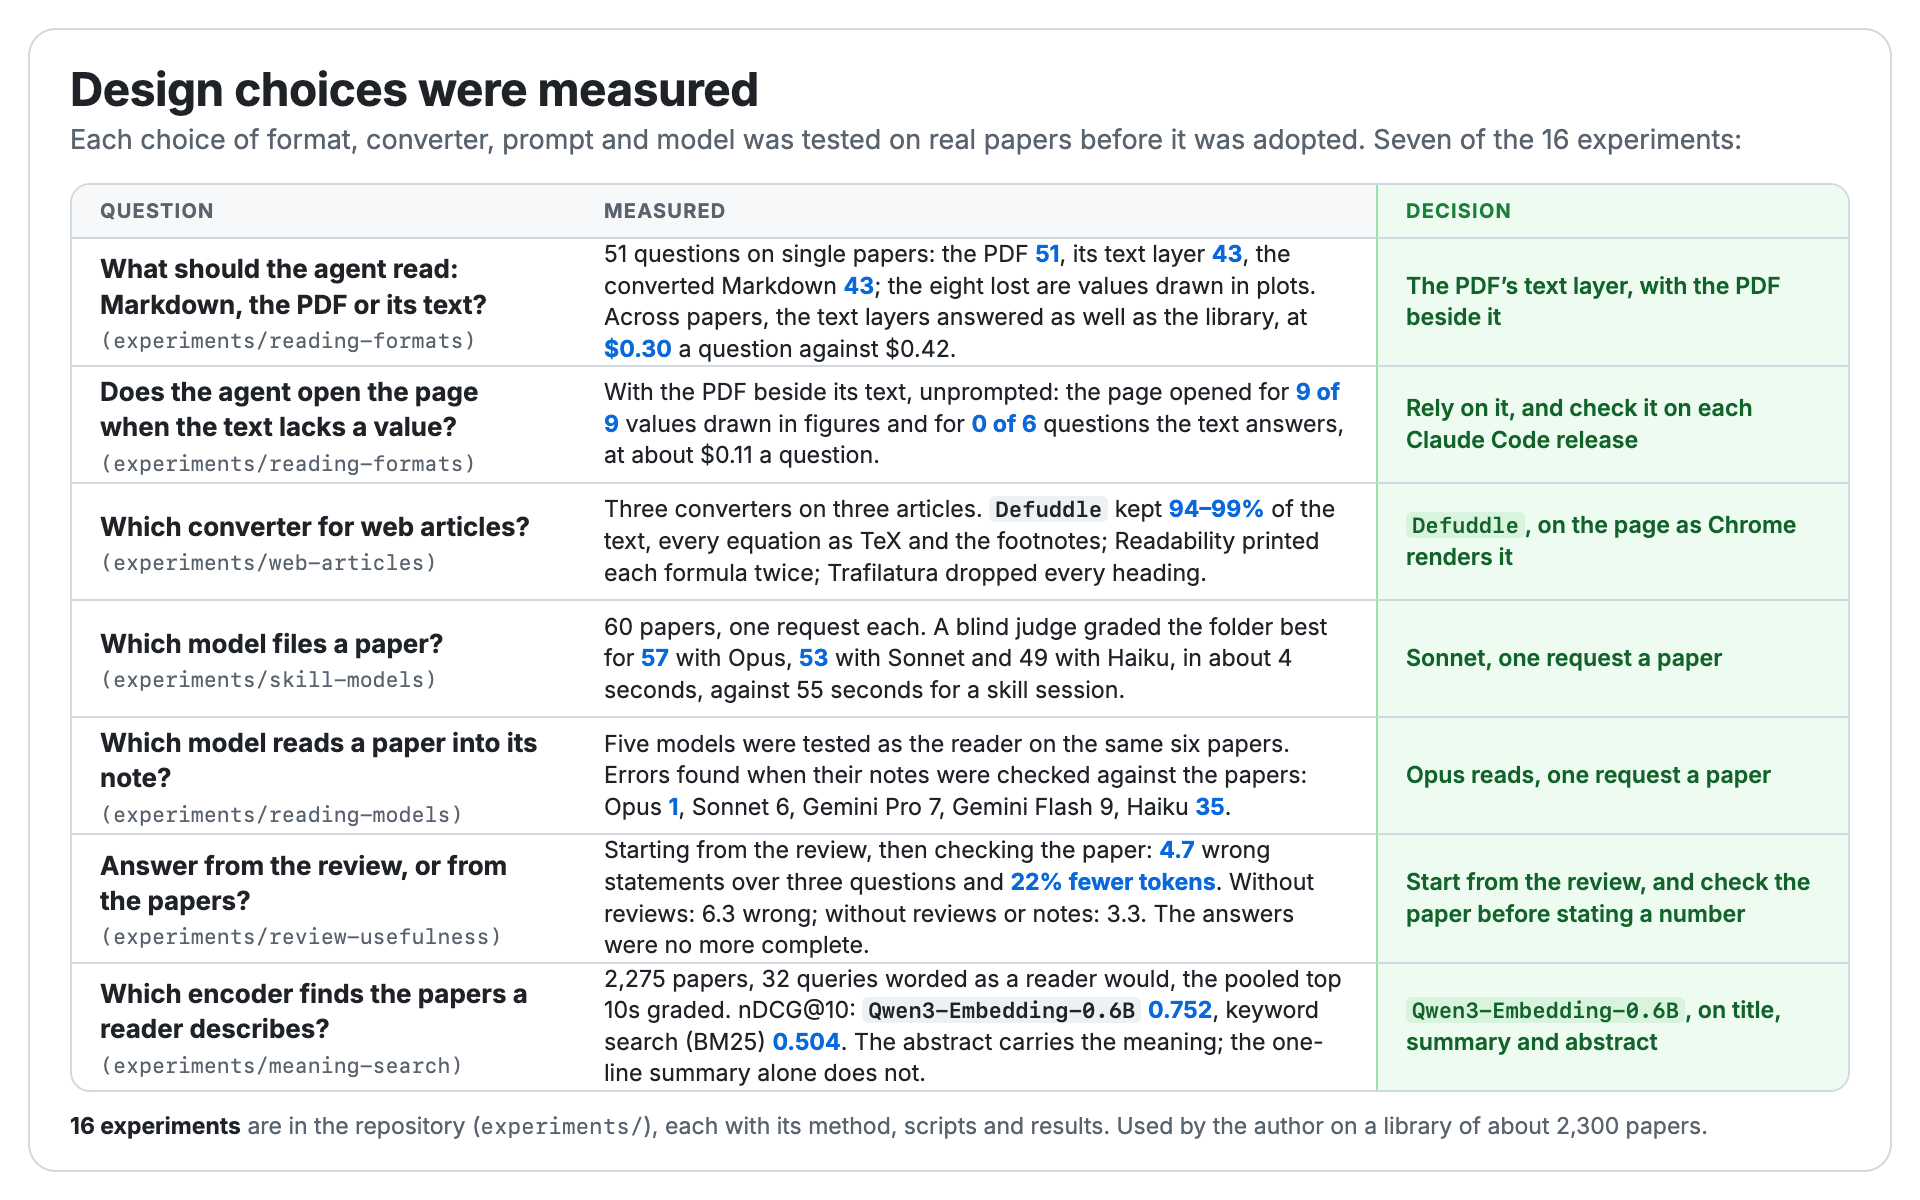
Seven of the 16 experiments behind the design, each with what was measured and what was decided.

Works with Carrel · PDF Viewer for VS Code

  • ai agents
  • context engineering
  • llm evaluation
  • research papers
  • semantic search
  • pdf extraction
  • claude code

Carrel

active

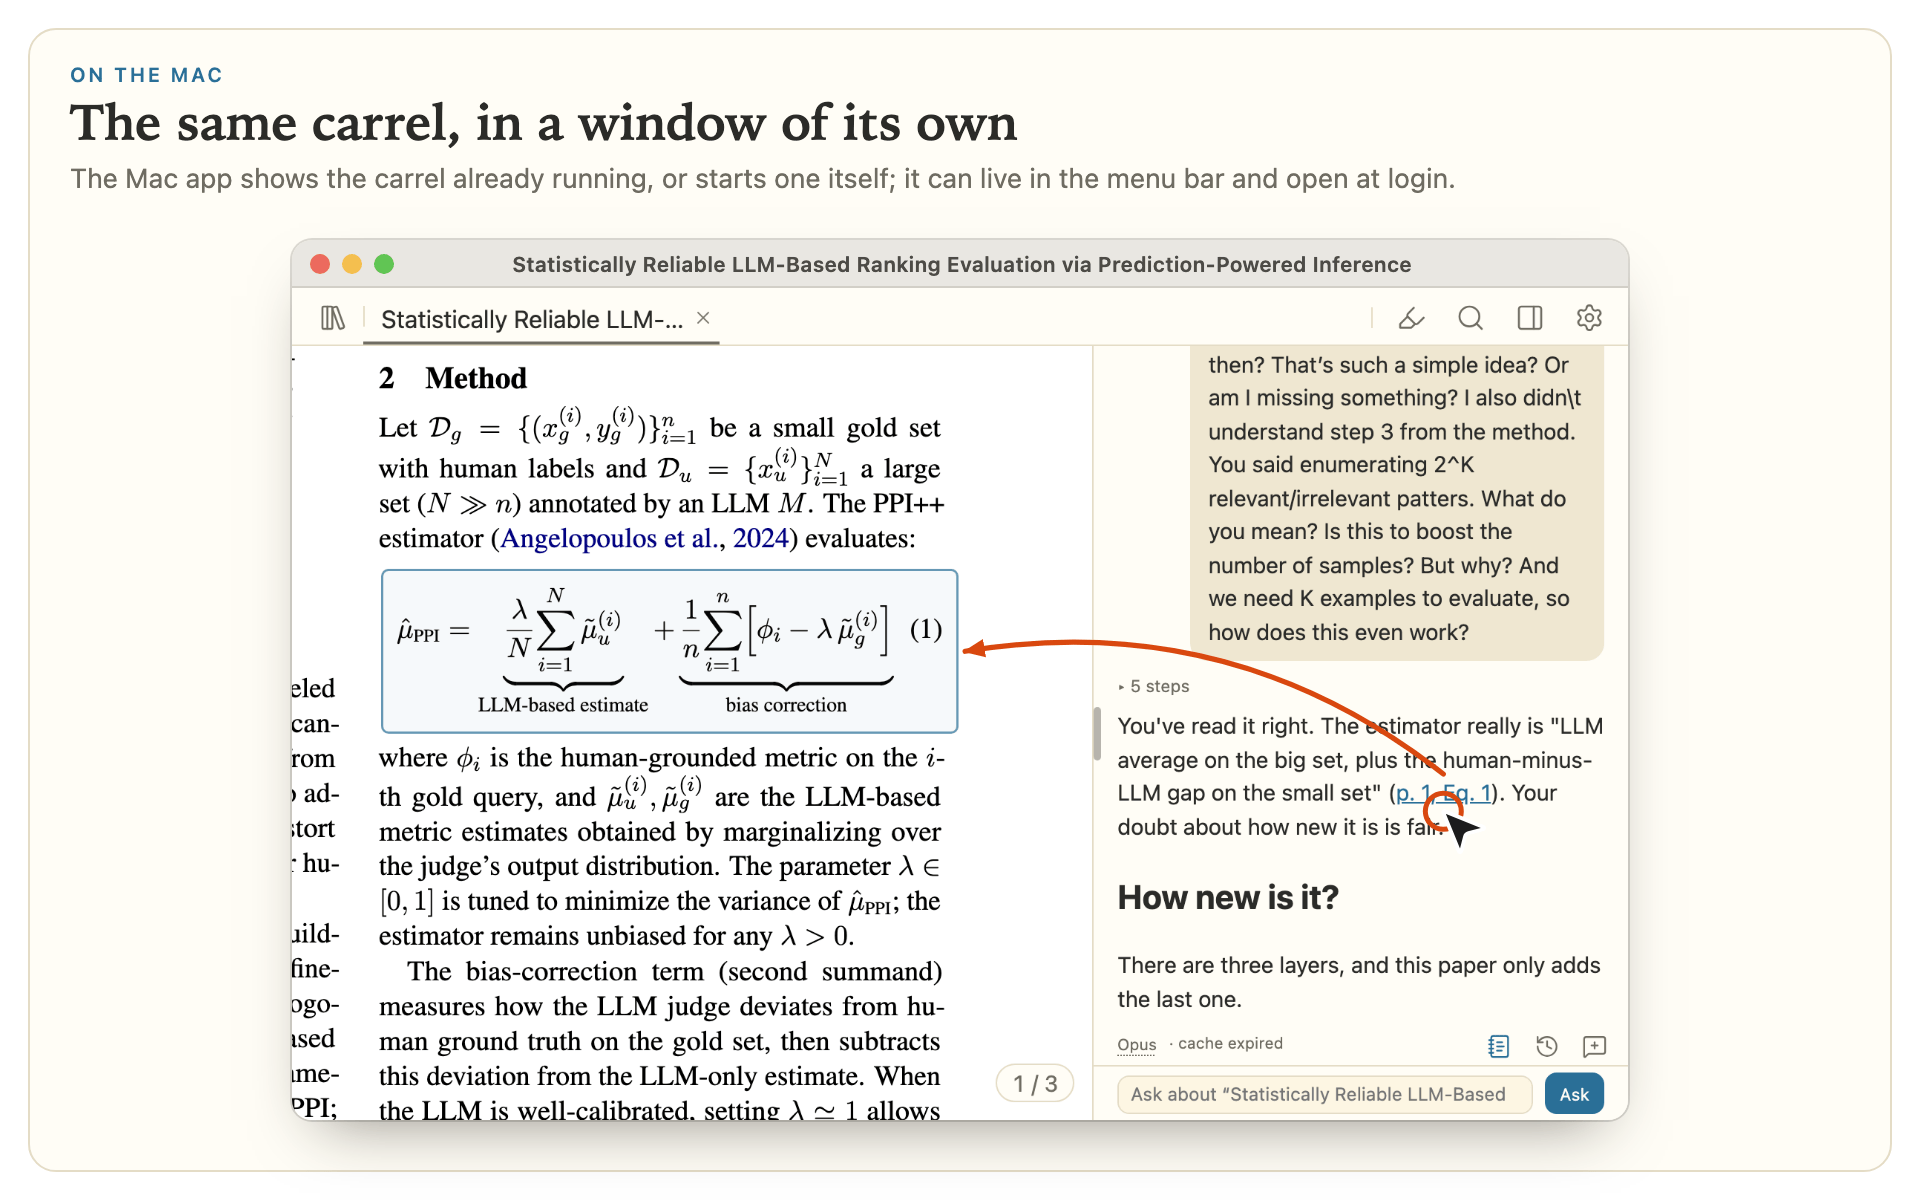
A reader app for an agentic paper library, on a tablet or a Mac, with the paper and its Claude Code chat in one place. Open a paper and you see the PDF and the chat side by side; when an answer cites a table or an equation, a tap turns the paper to that place and marks it. The whole library is there too: search over the papers' text and by meaning, their topics, overviews and literature reviews, and a map of the papers laid out by meaning. Chats are kept on the laptop, so a conversation started on the tablet carries on at the laptop, and back.

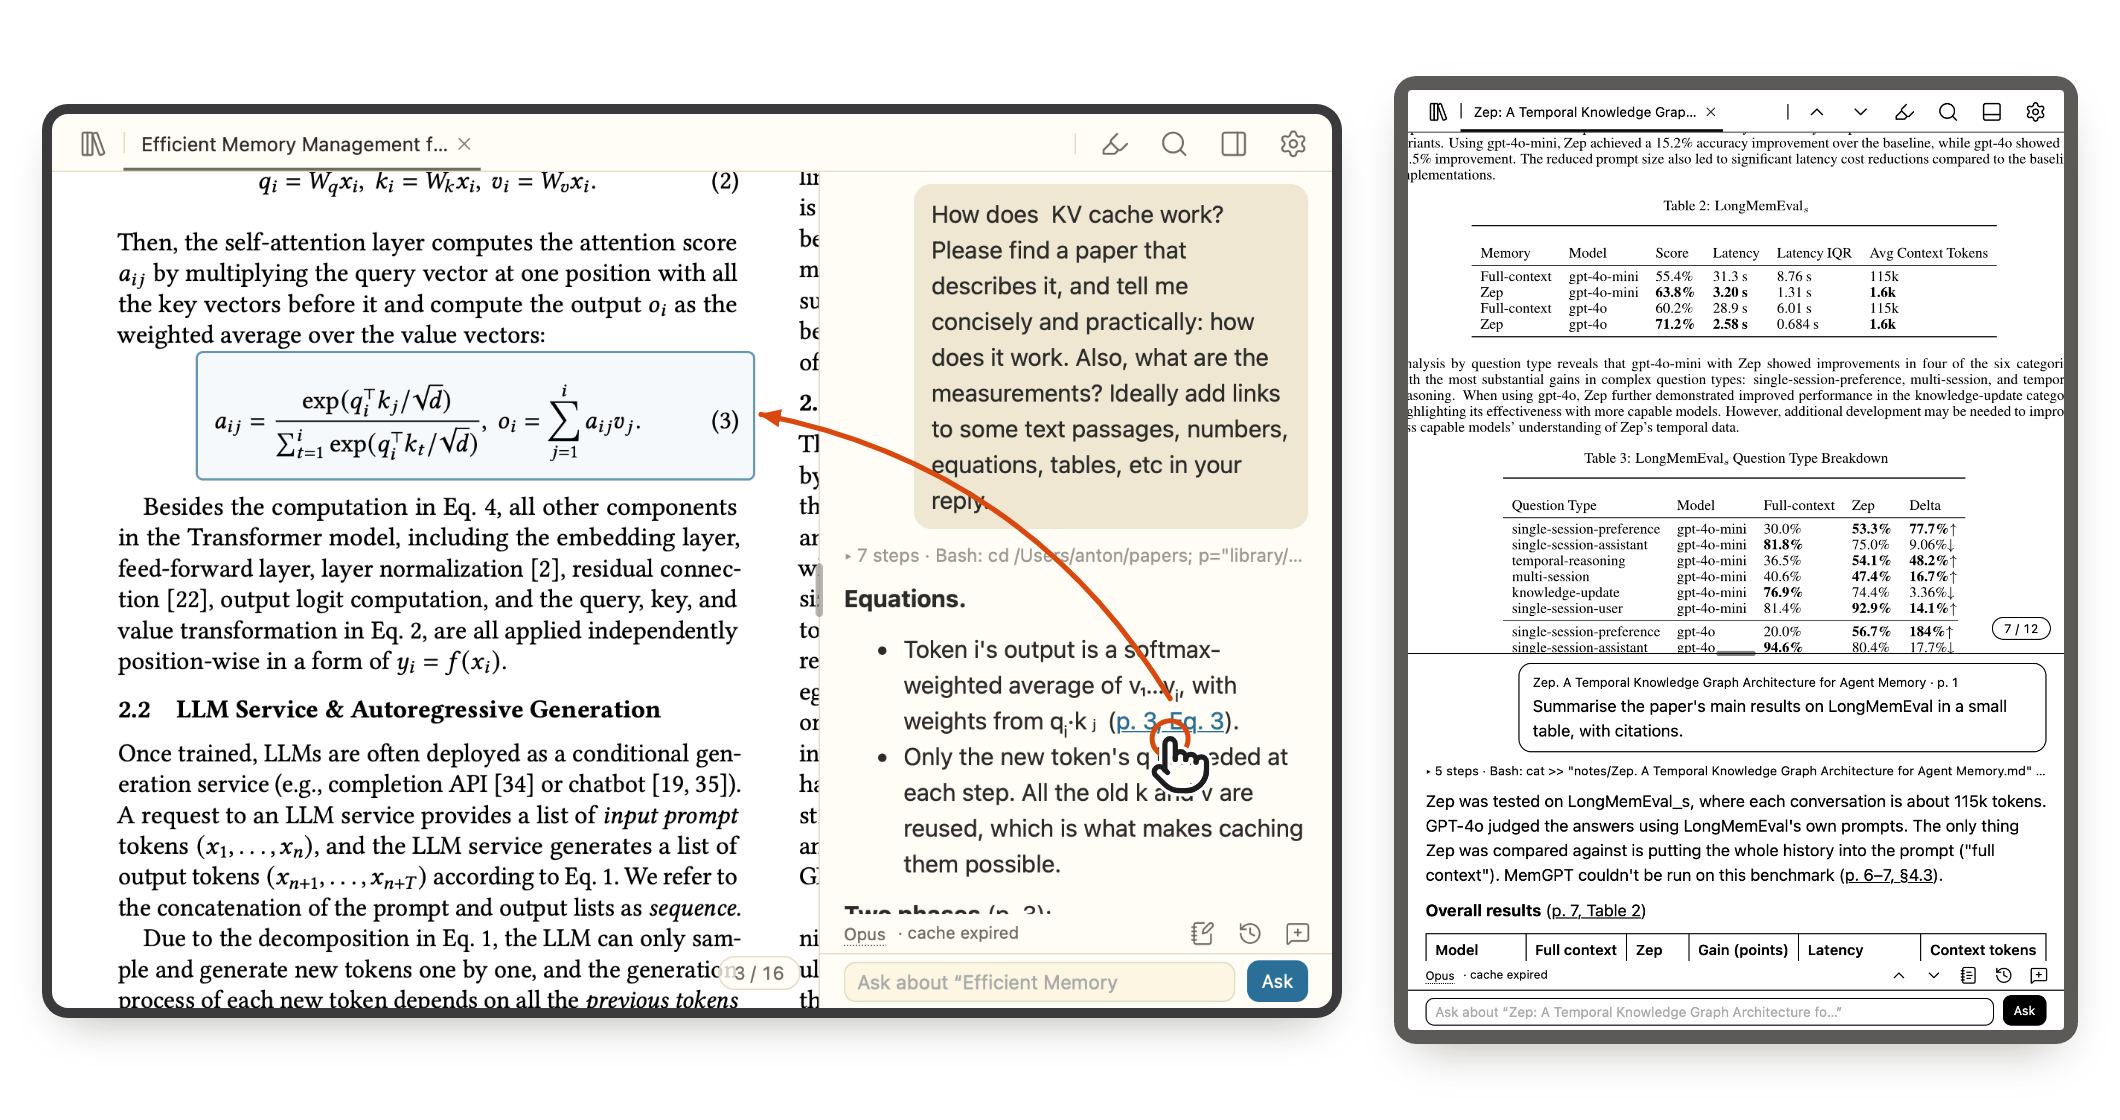
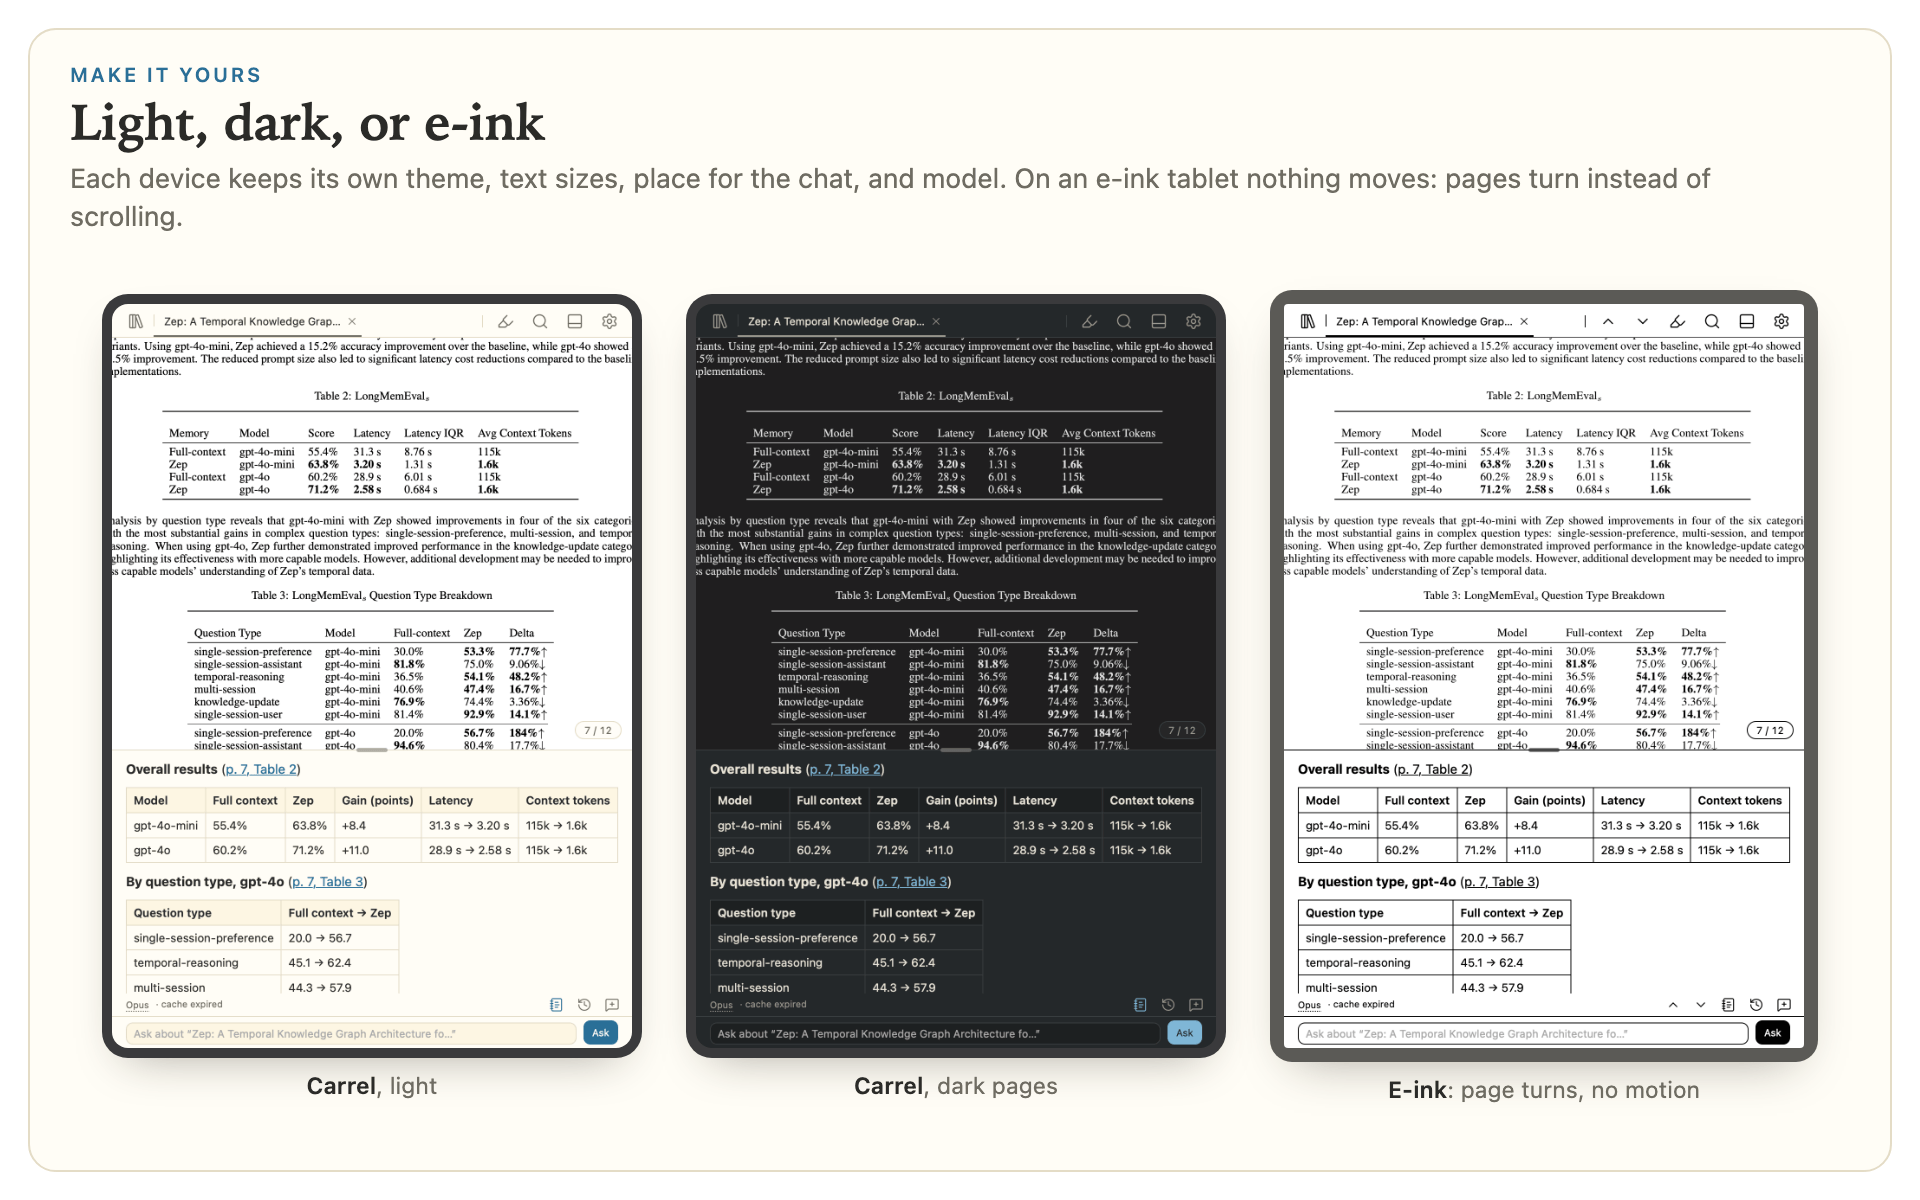
A citation followed on a tablet: the answer cites the paper's equation, and a tap turns the paper there and marks it. Beside it, the same reading on an e-ink tablet.
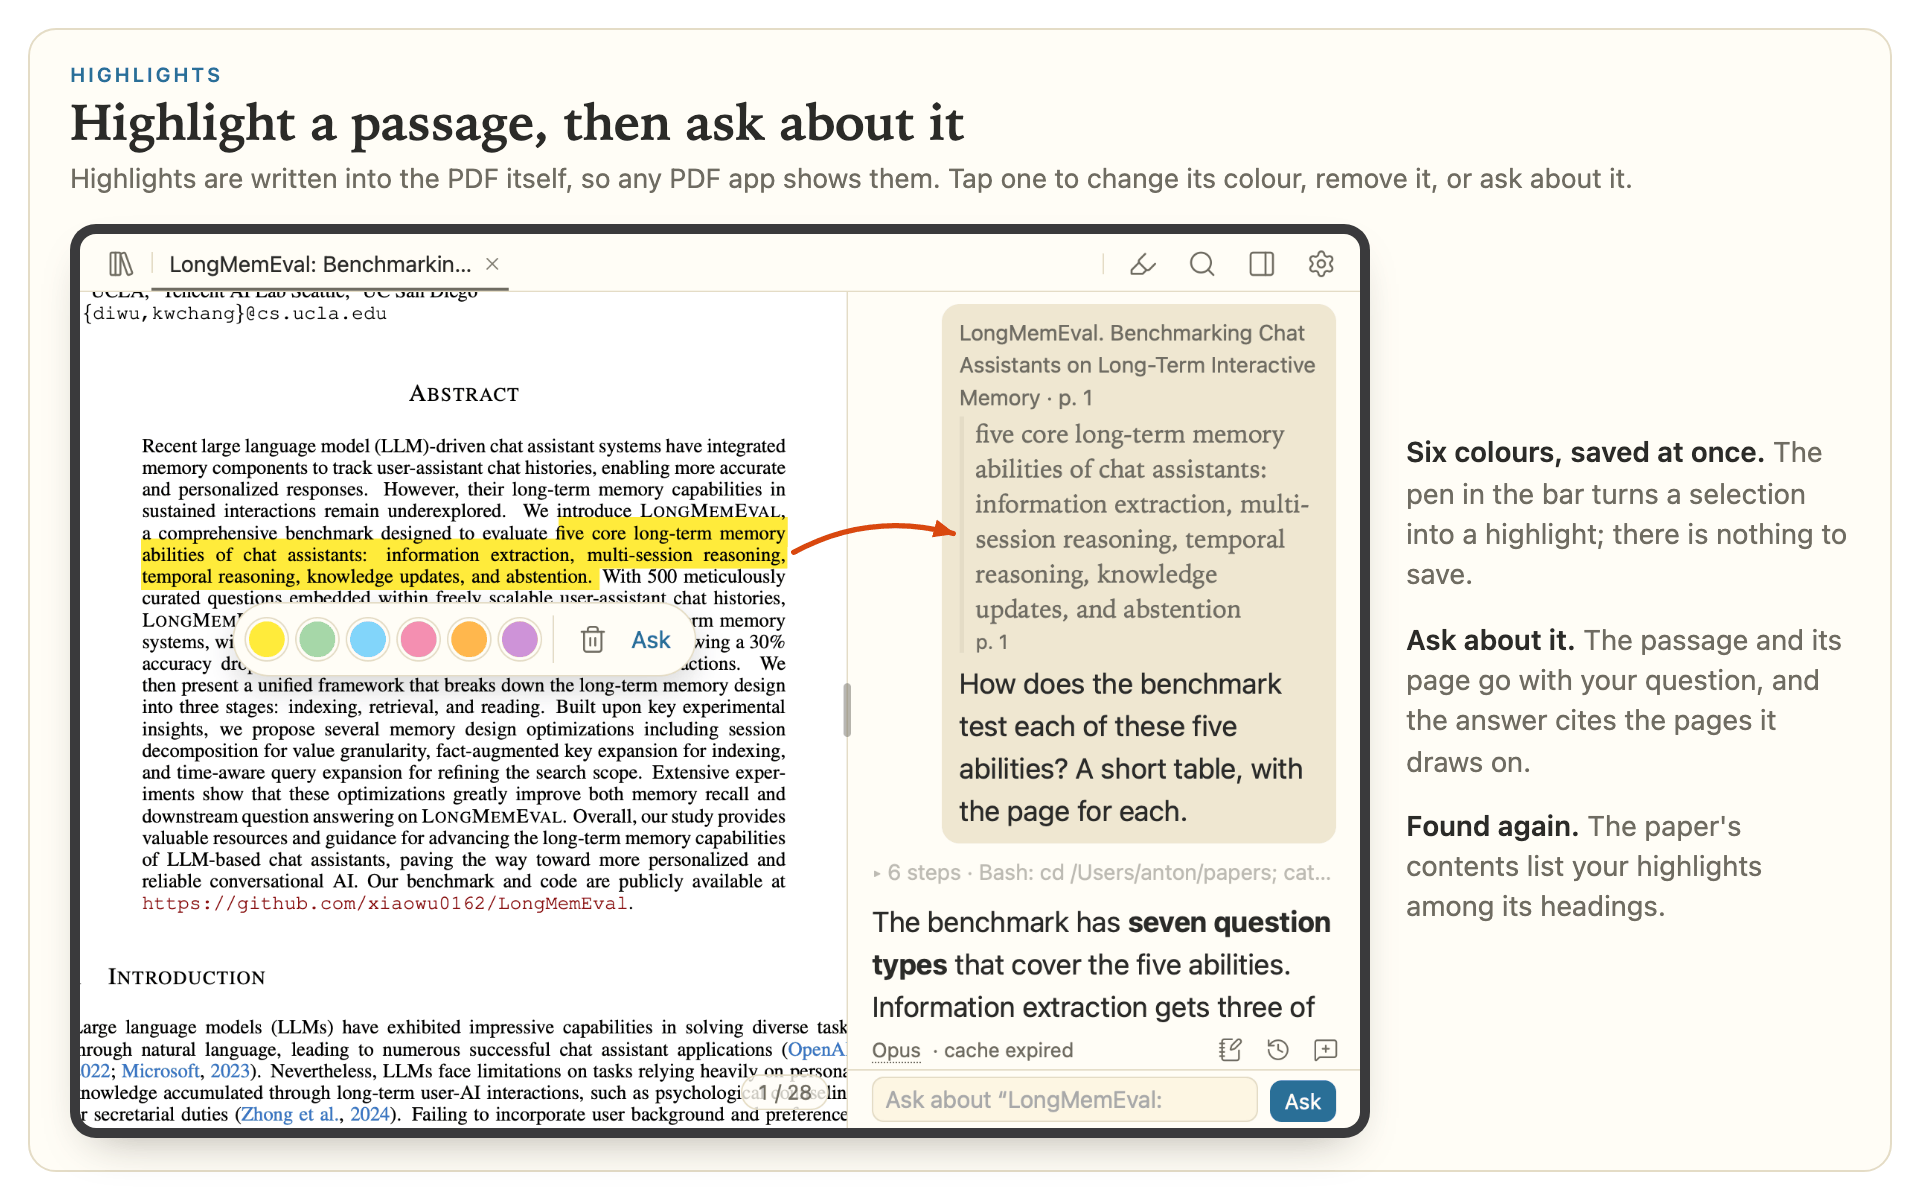
A highlight tapped and asked about, the passage carried into the chat; highlights are saved into the PDF itself.
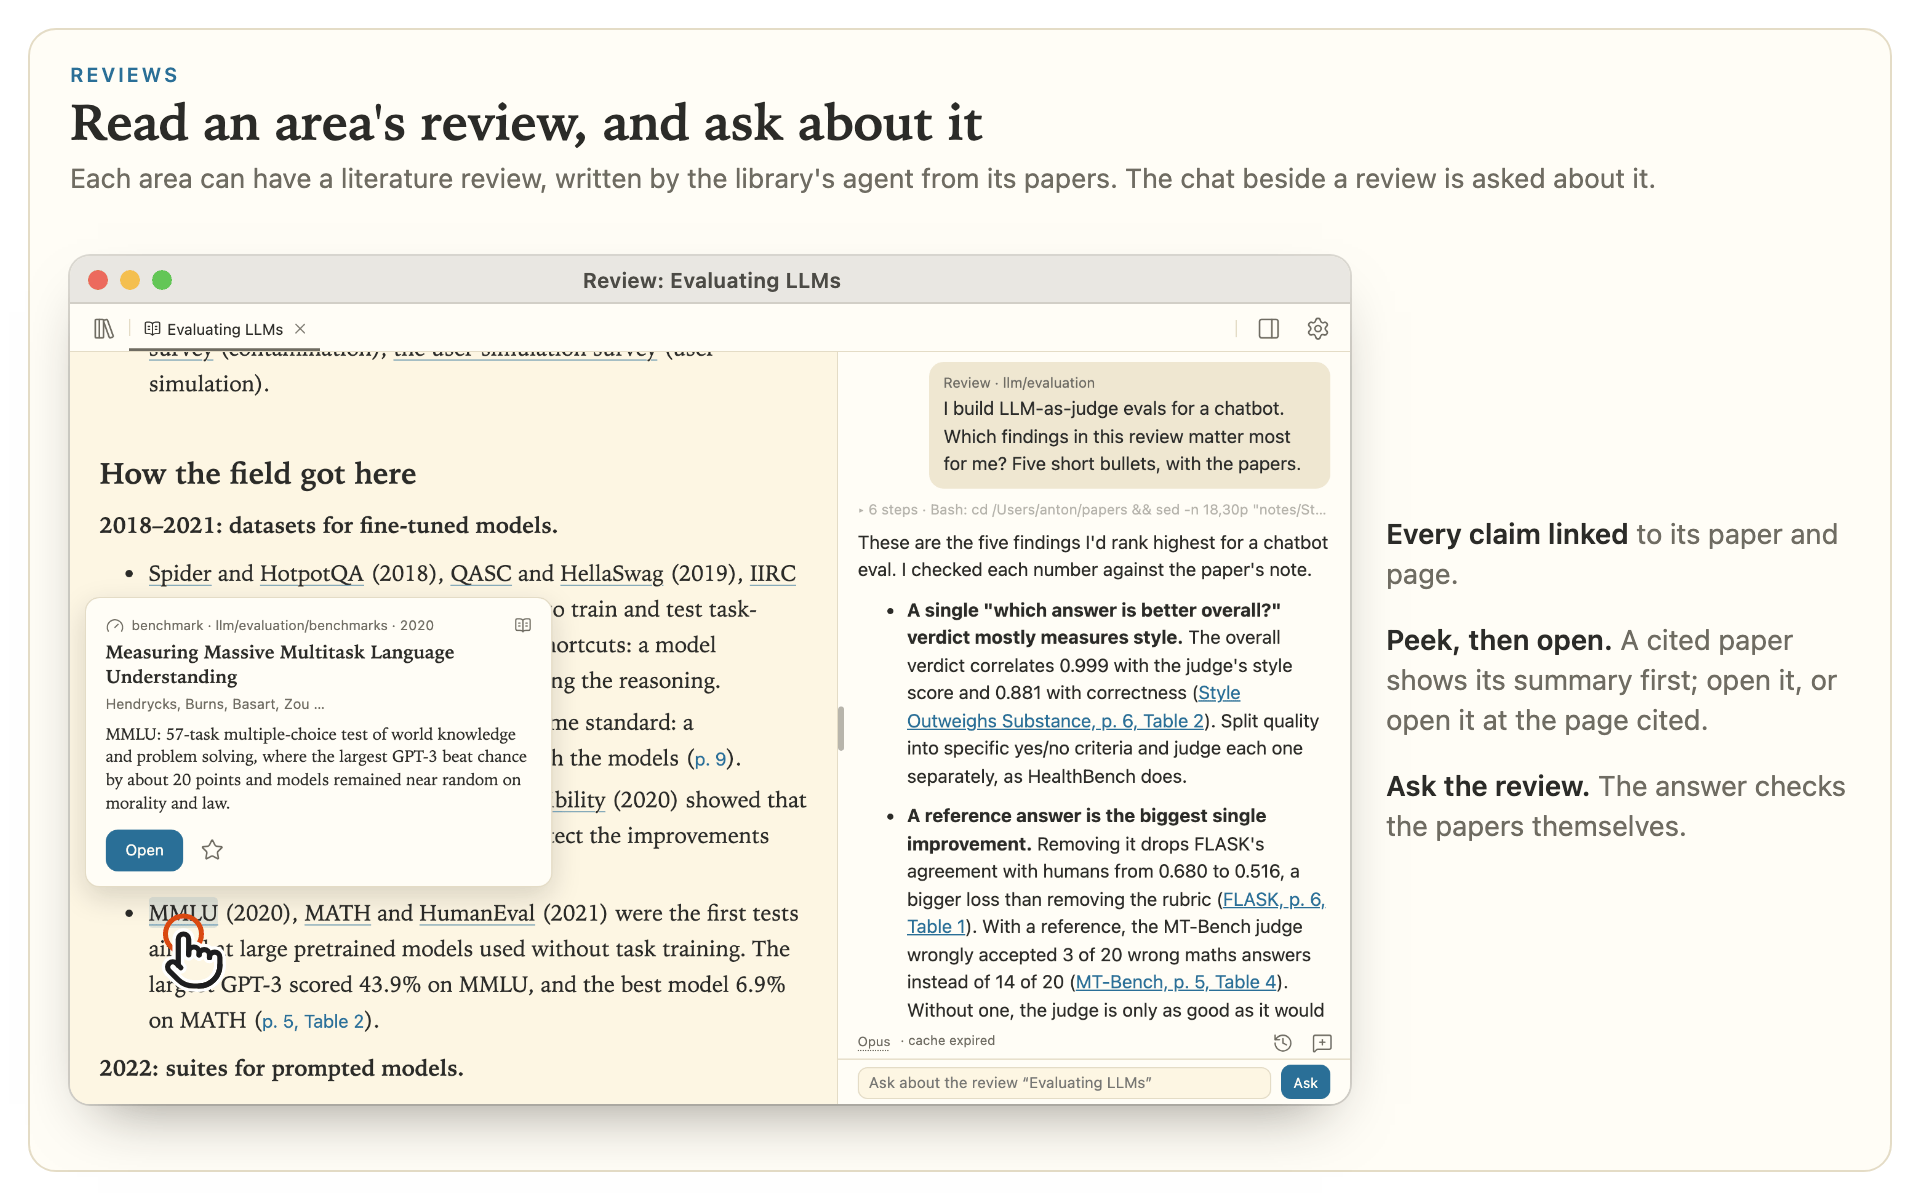
An area's literature review on the Mac, a peek at a paper it cites, and a chat asked about the review.
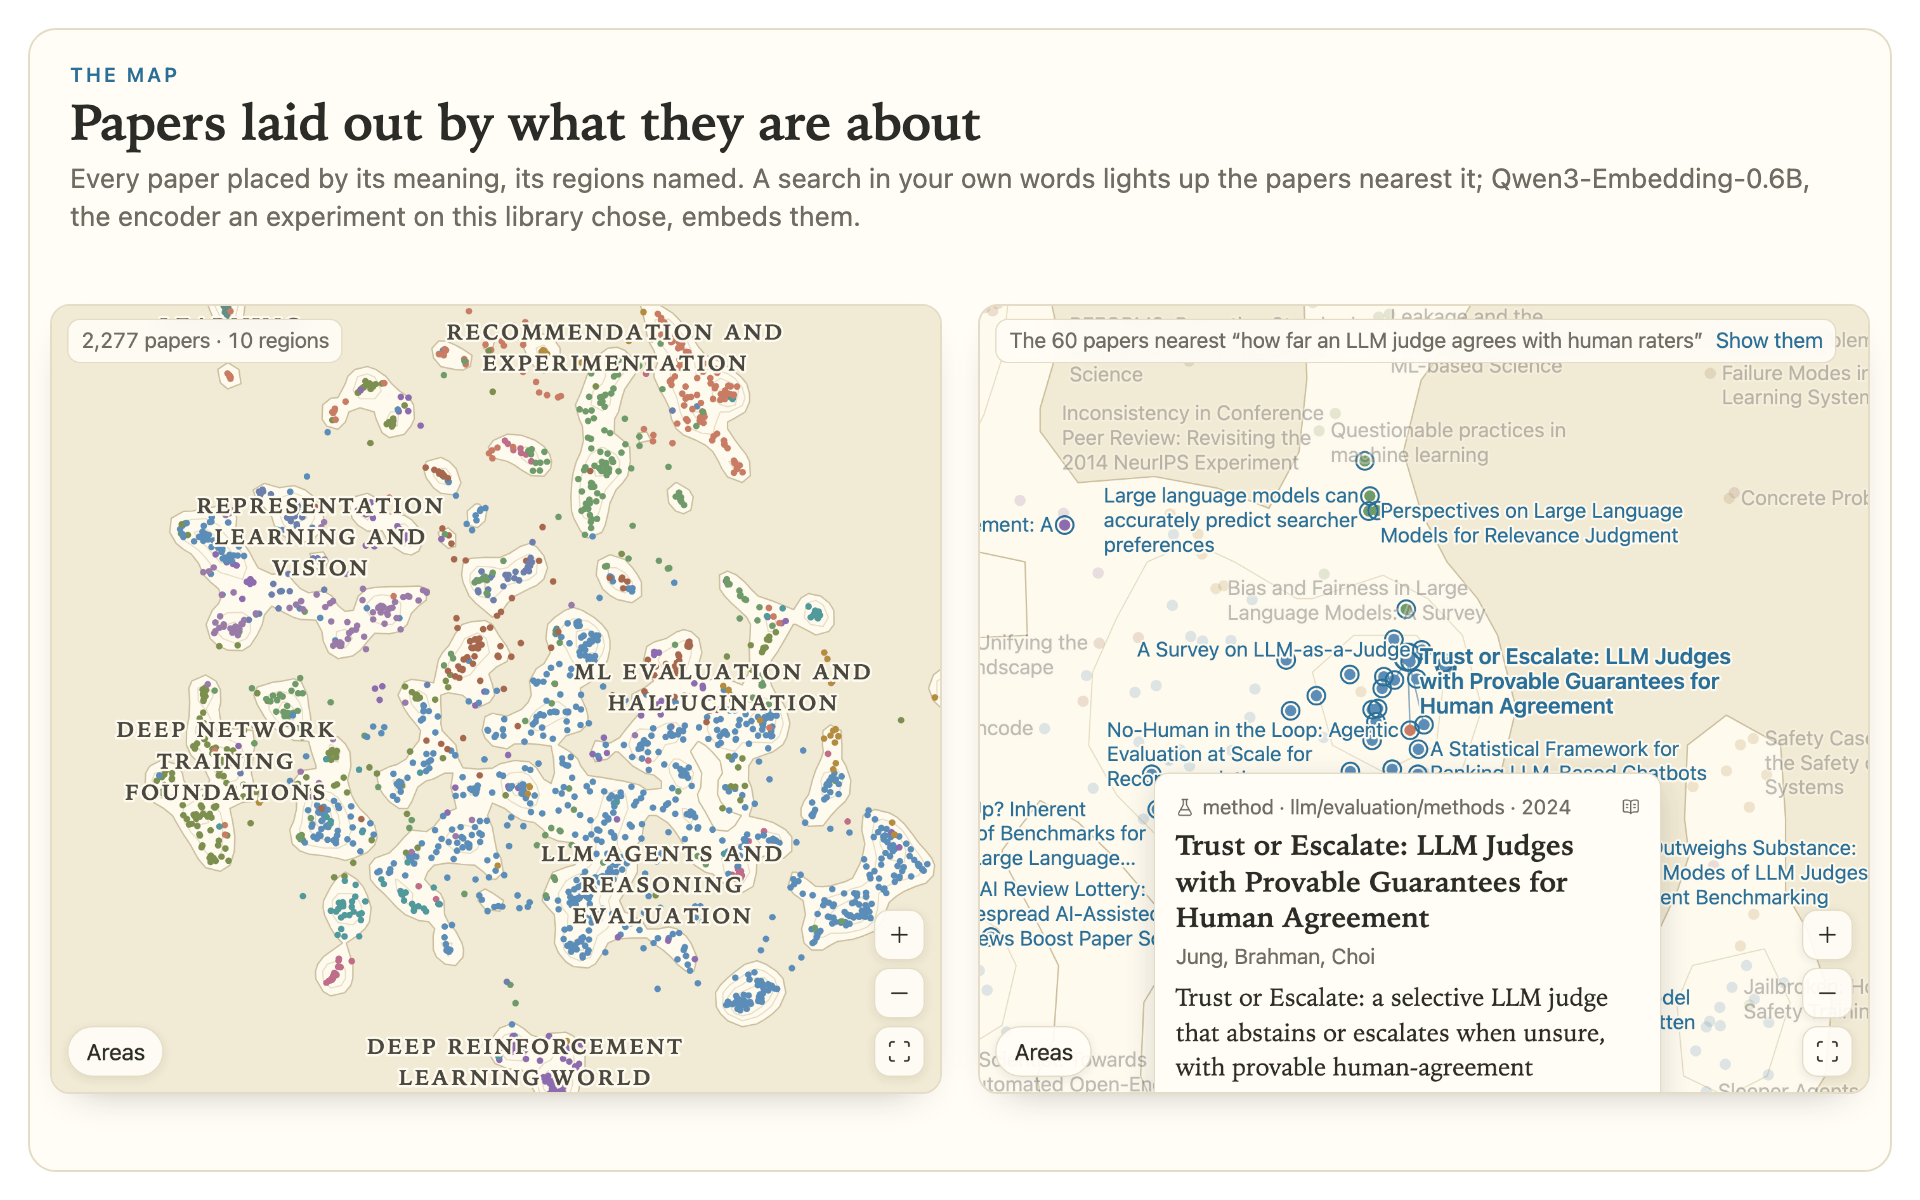
The library laid out by meaning, its regions named; nearer, lit by a meaning search for papers on LLM judges, one open in a peek.
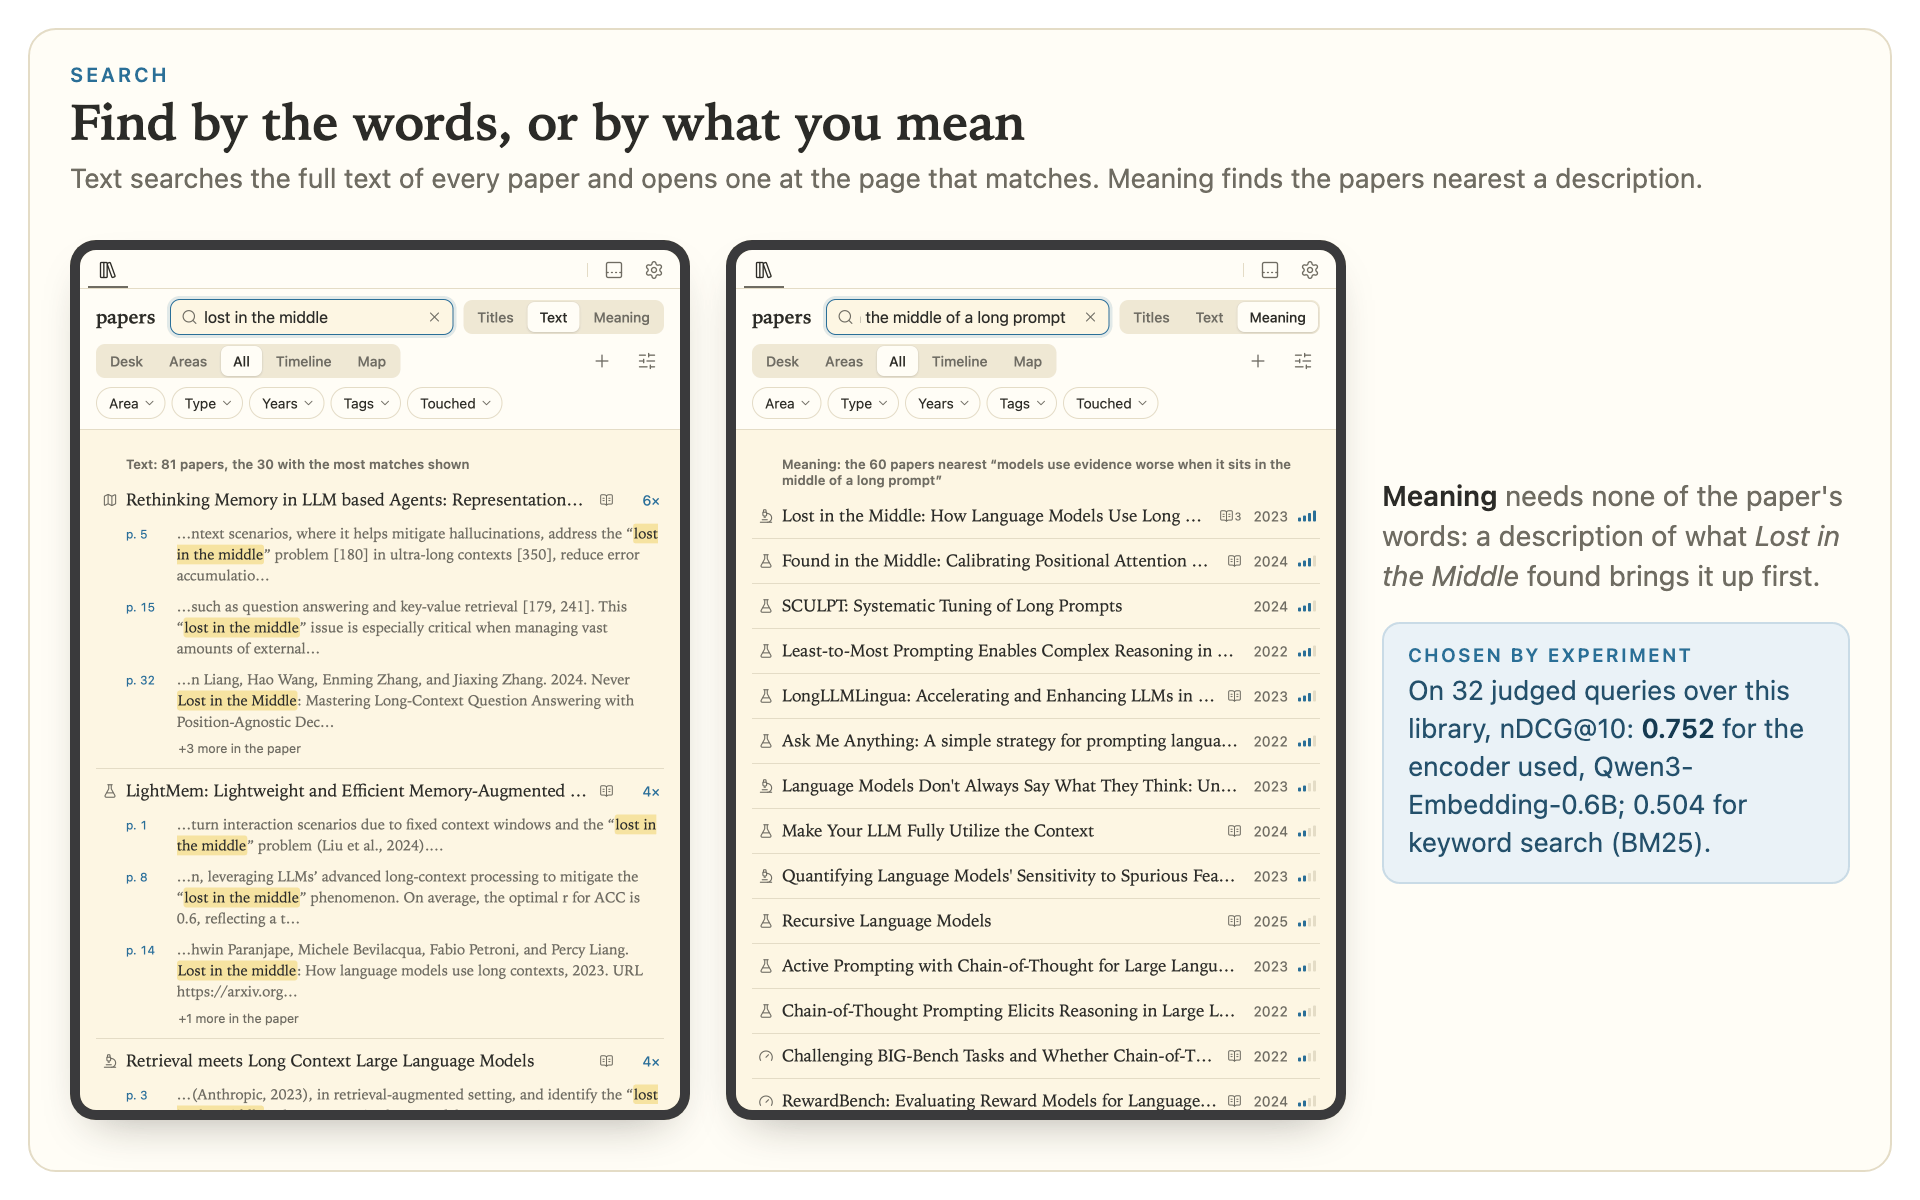
Searching the papers' full text, and searching by a description of what a paper found.
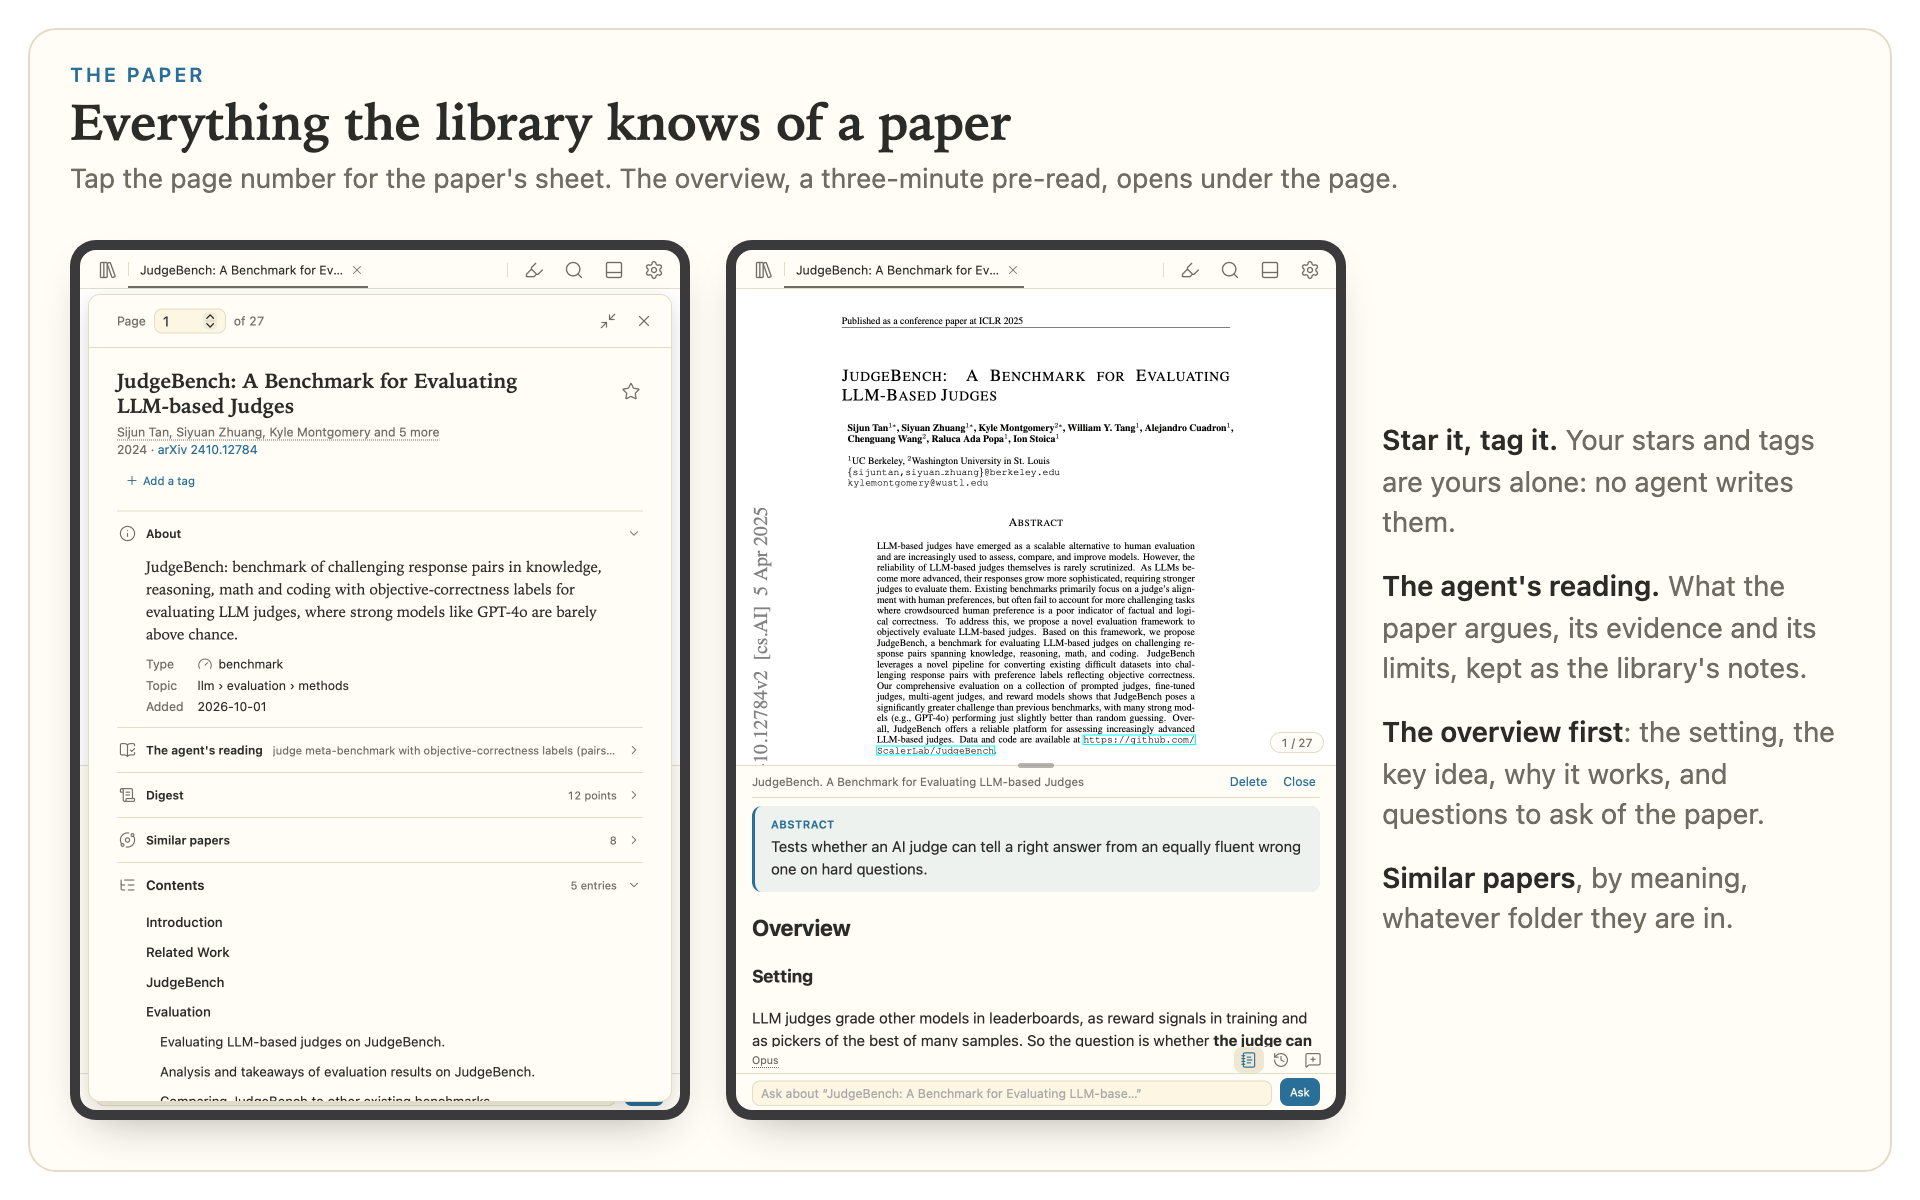
What the library knows of a paper, and the overview note to read before it.
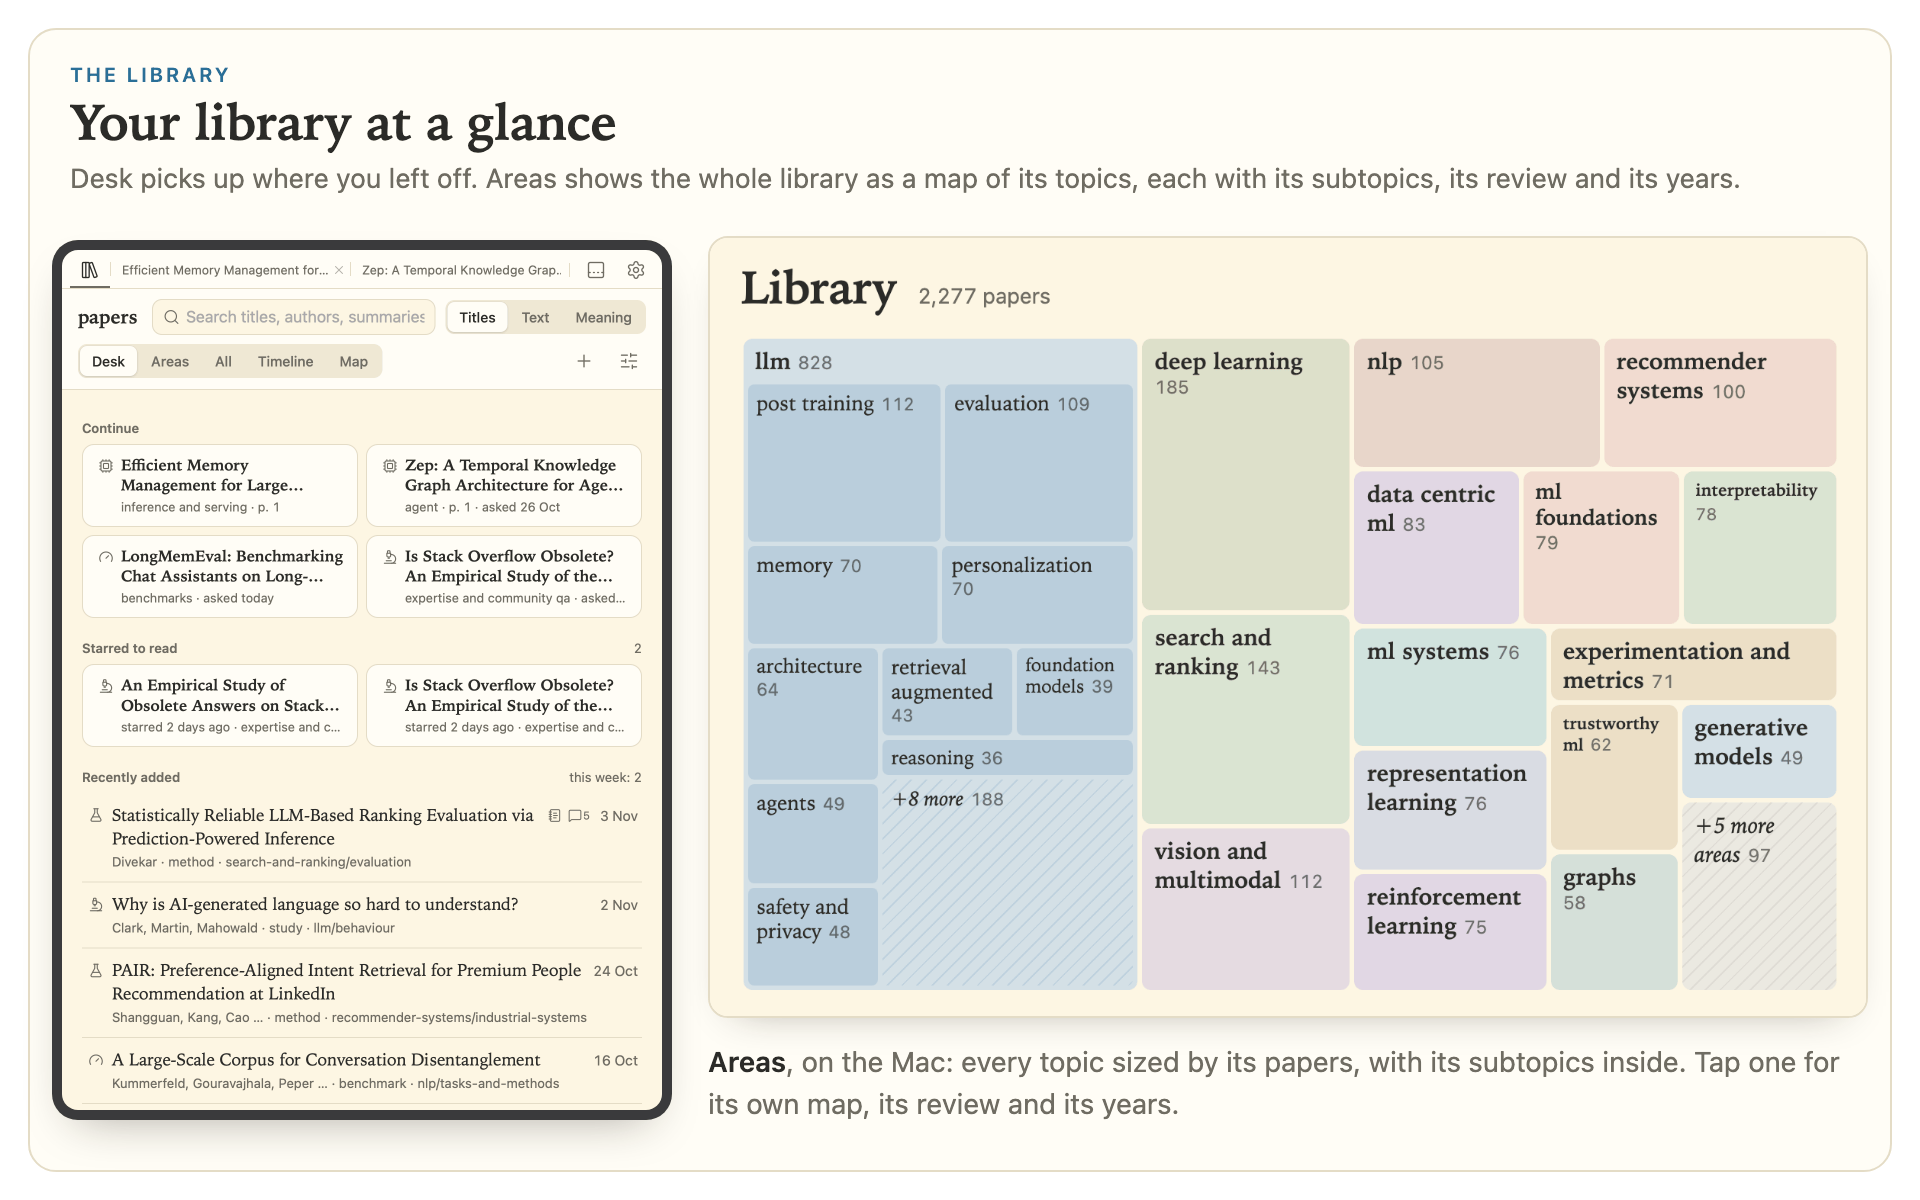
Desk, where reading picks up again, and the whole library as a map of its topics.
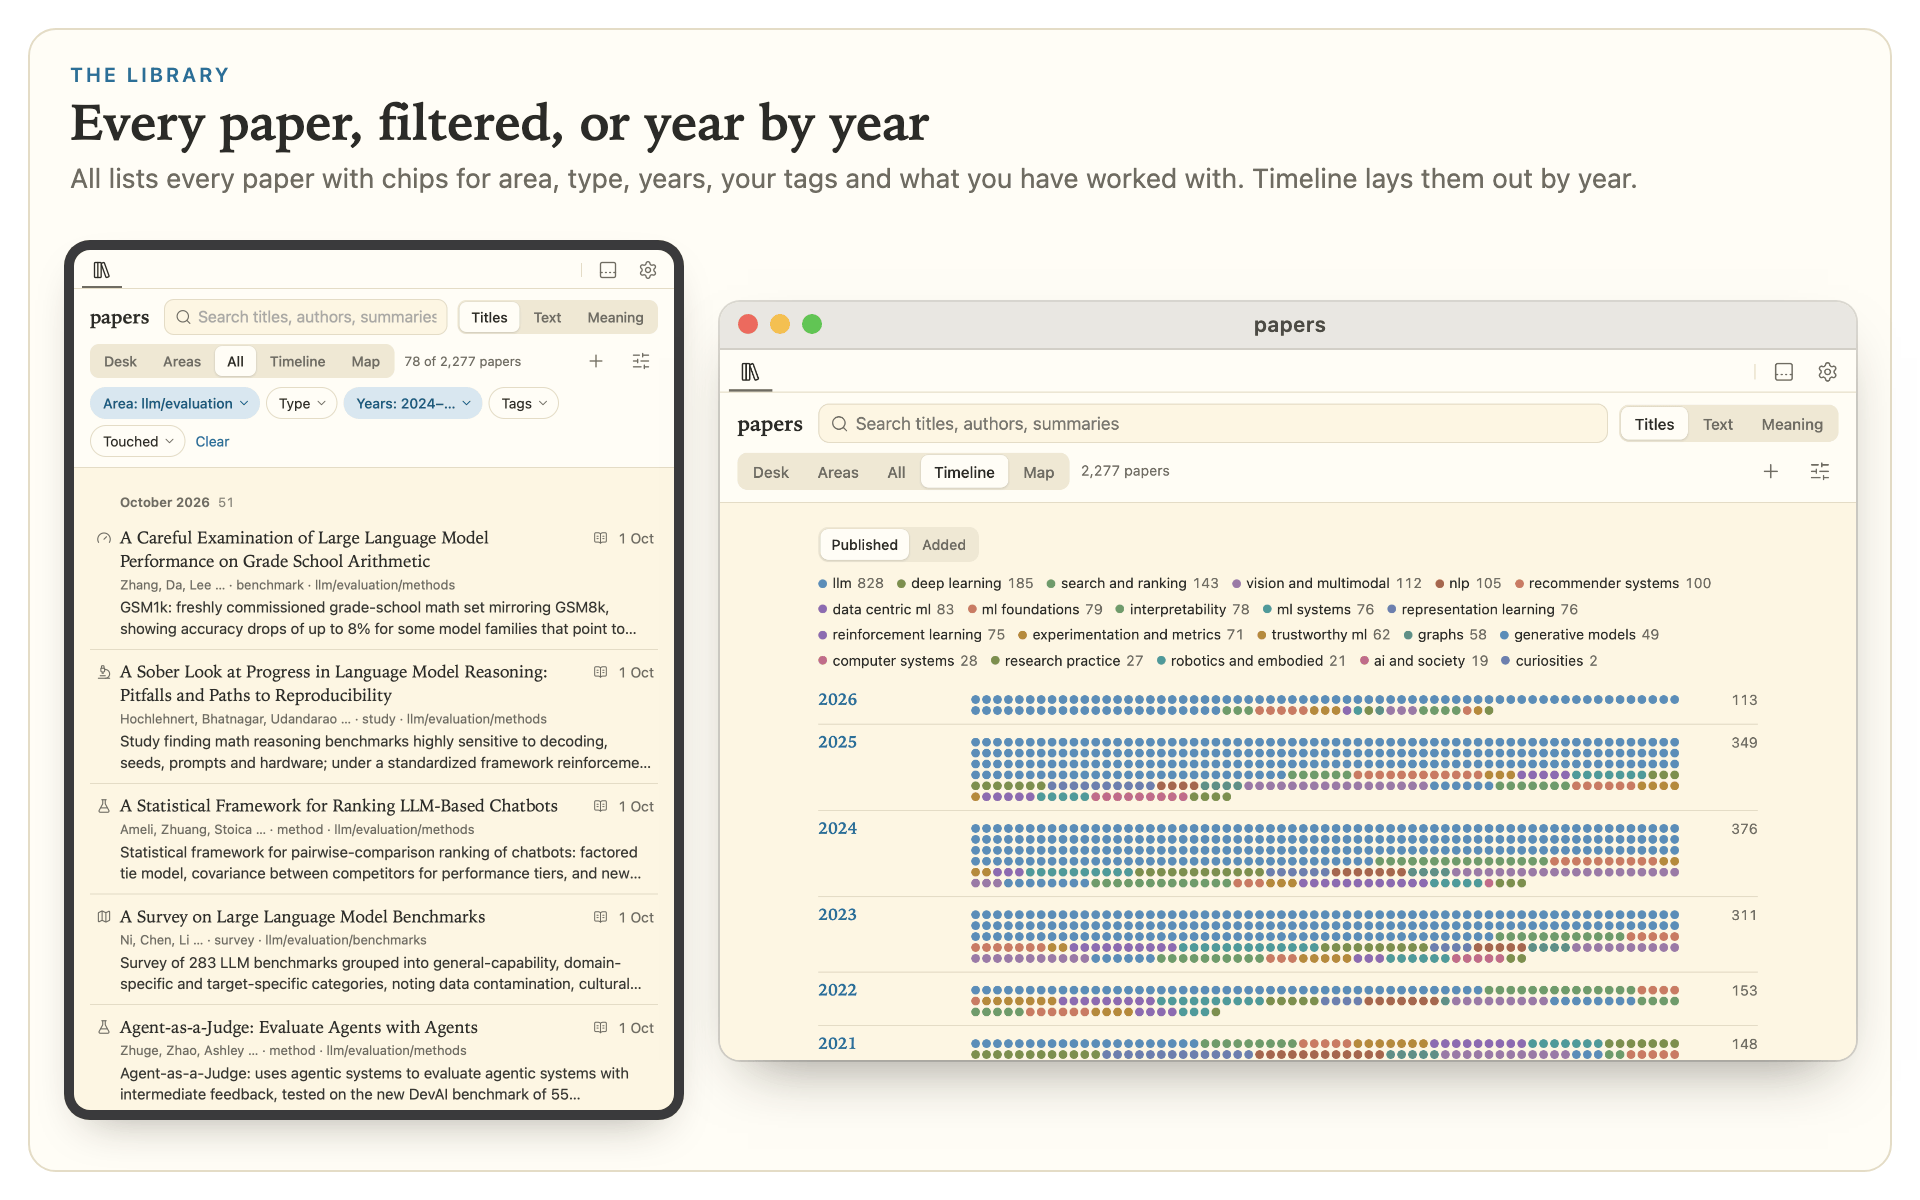
Every paper, filtered by area and years, and the library year by year.
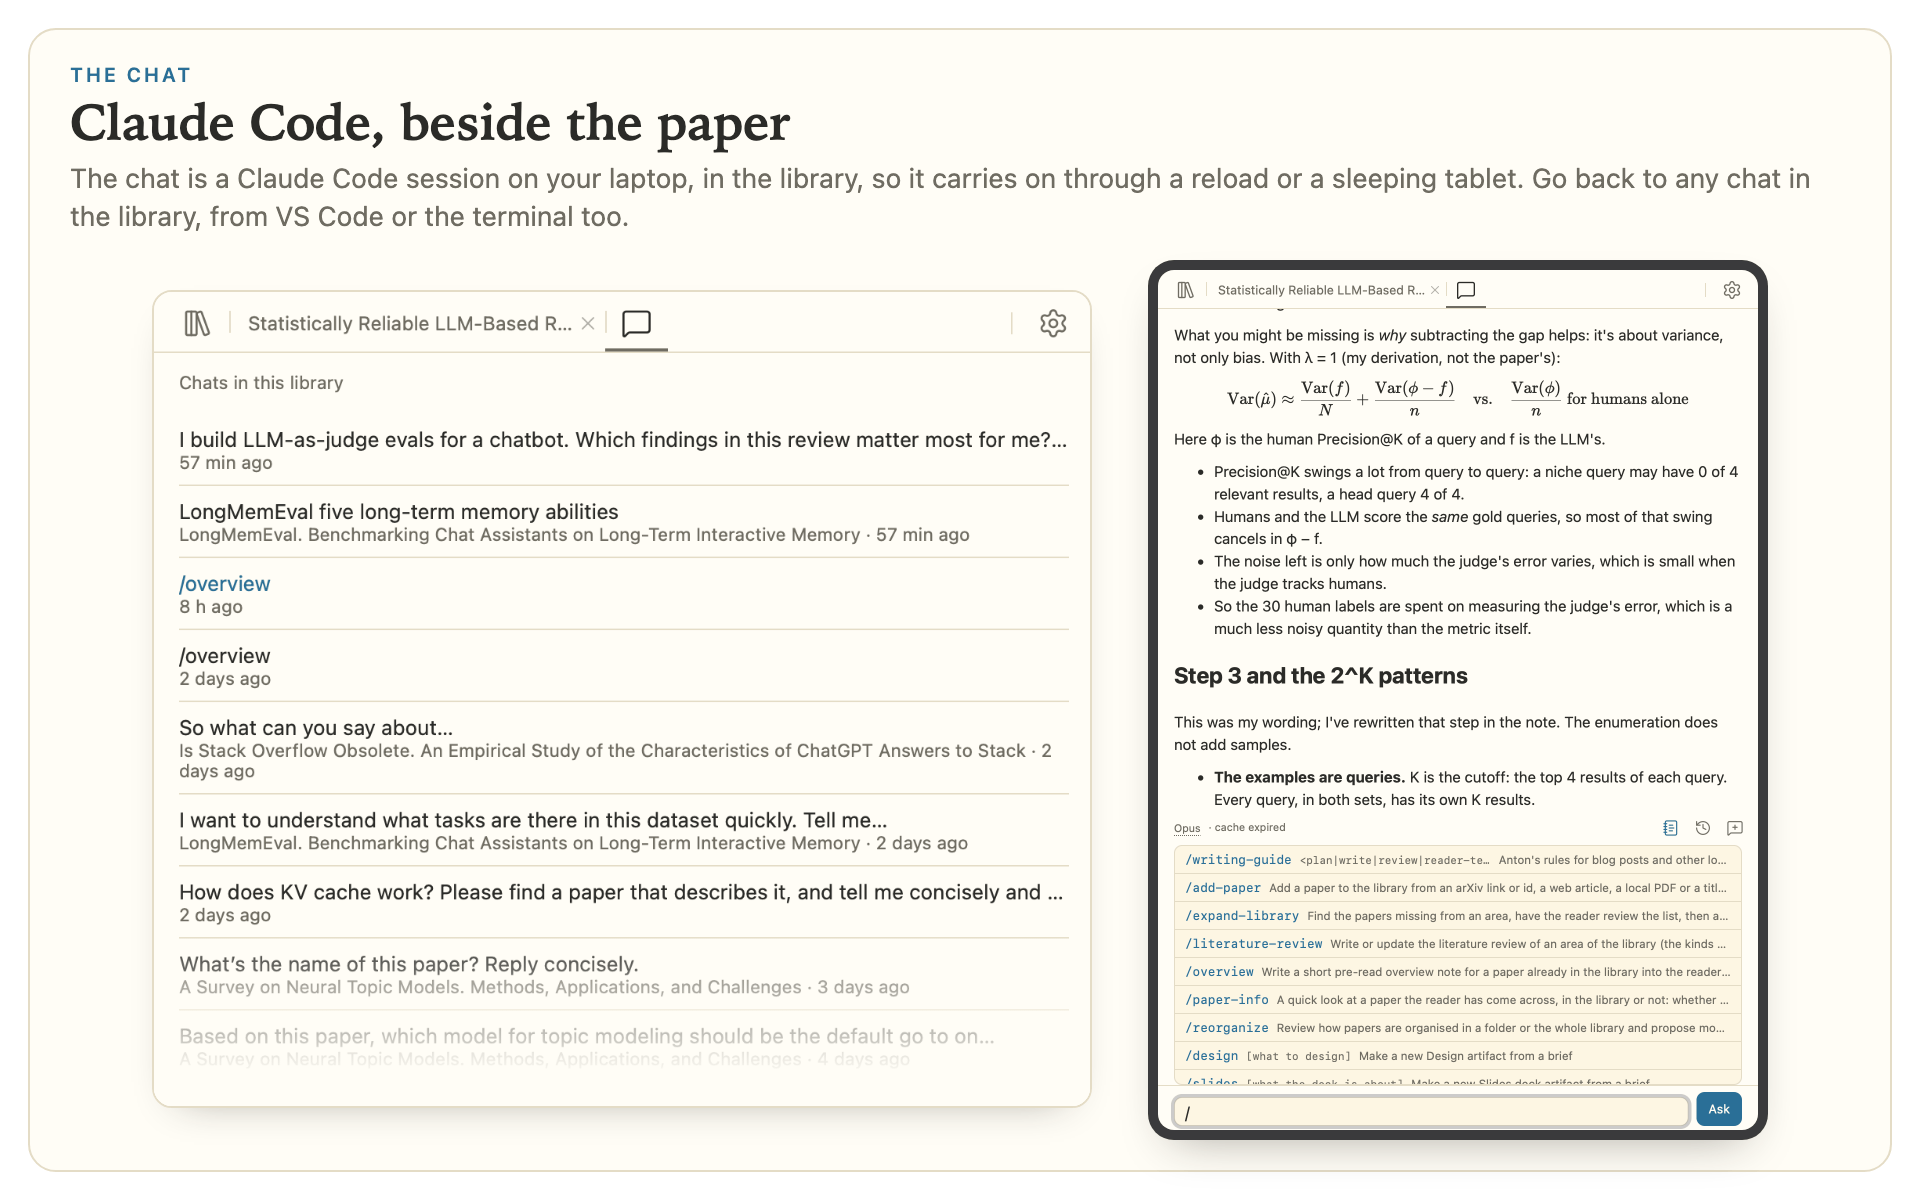
The library's chats, from carrel, VS Code and the terminal, and its slash commands.
One paper and its chat in light, dark and e-ink.
The Mac app, where a click on the answer's citation marks the passage it cites.

Works with Agentic paper library

  • claude code
  • ai agents
  • research papers
  • semantic search
  • embeddings
  • pdf viewer
  • tablet
  • e ink
  • tailscale

PDF Viewer for VS Code

A plain PDF viewer for VS Code, built for reading papers with a coding agent: a citation in the chat opens the paper beside it at the cited section, table or page, and highlights are saved into the PDF. It works with any PDF, and with an agentic paper library.

Clicking a citation in Claude Code's answer opens the PDF beside the chat at that section.

Works with Agentic paper library

  • vscode extension
  • pdf viewer
  • research papers
  • claude code

Agentic planning and context engineering

2 projects

A plain-text planning system with an LLM agent working beside you on the plan, and a capture mechanism that feeds it: a set protocol for saving anything from a phone, a browser or the laptop, prepared so that the agent can use it well. The capture pipeline's design choices were made by measurement in experiments.

Agentic Org Planner

active

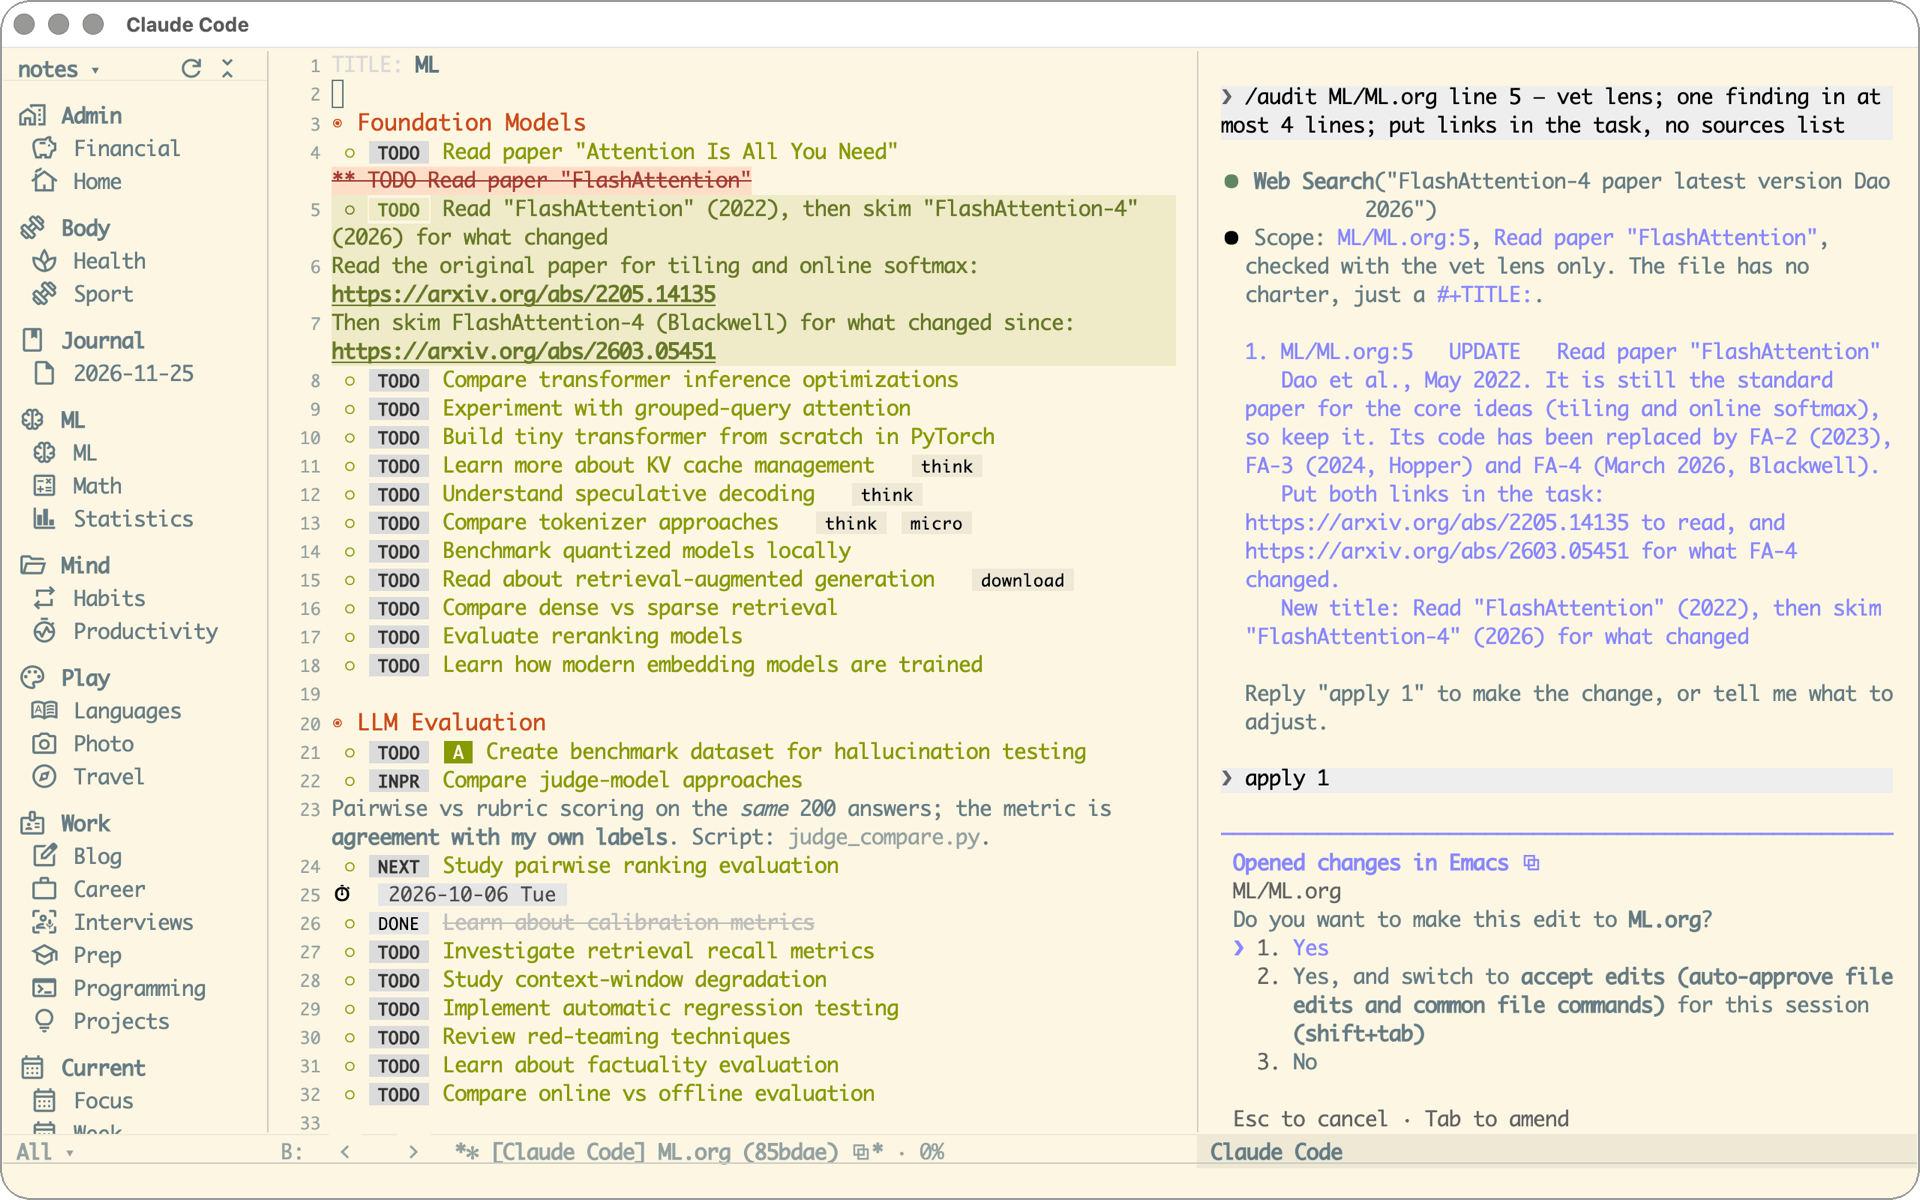
A planning system in plain-text Org files in which an LLM agent is a working participant. The agent knows the file and selection in front of you and the conventions of your plan; it adds and edits tasks and files what you captured during the day, showing each change as a diff to accept or reject. Underneath is a complete Emacs configuration that renders plans cleanly: an agenda with a timeline, a calendar, views of your tasks, Git sync and other features.

Claude Code audits a plan file: one finding, and the change it proposes shown inline in the file.
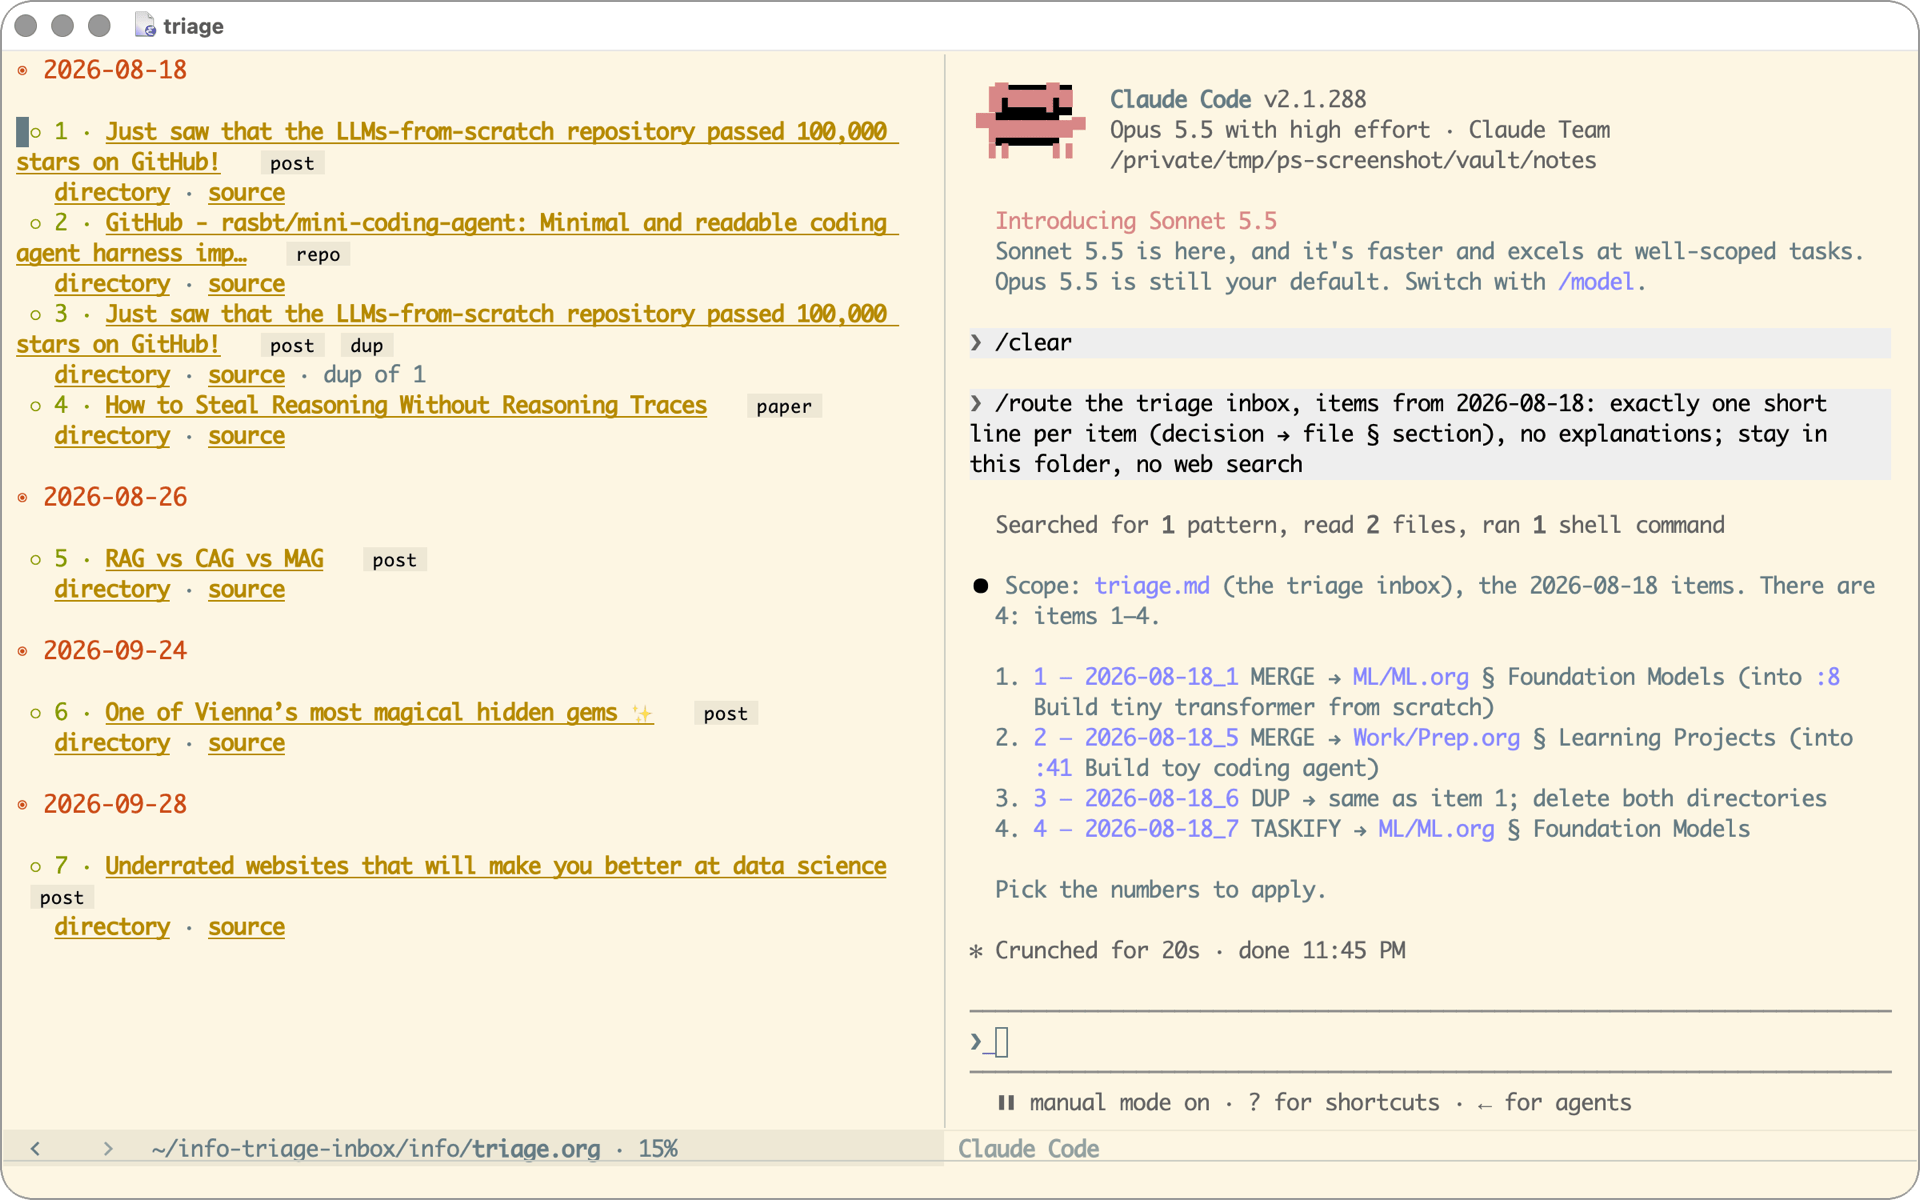
Routing a day's captured items: two merged into existing tasks, a duplicate caught, one new task.
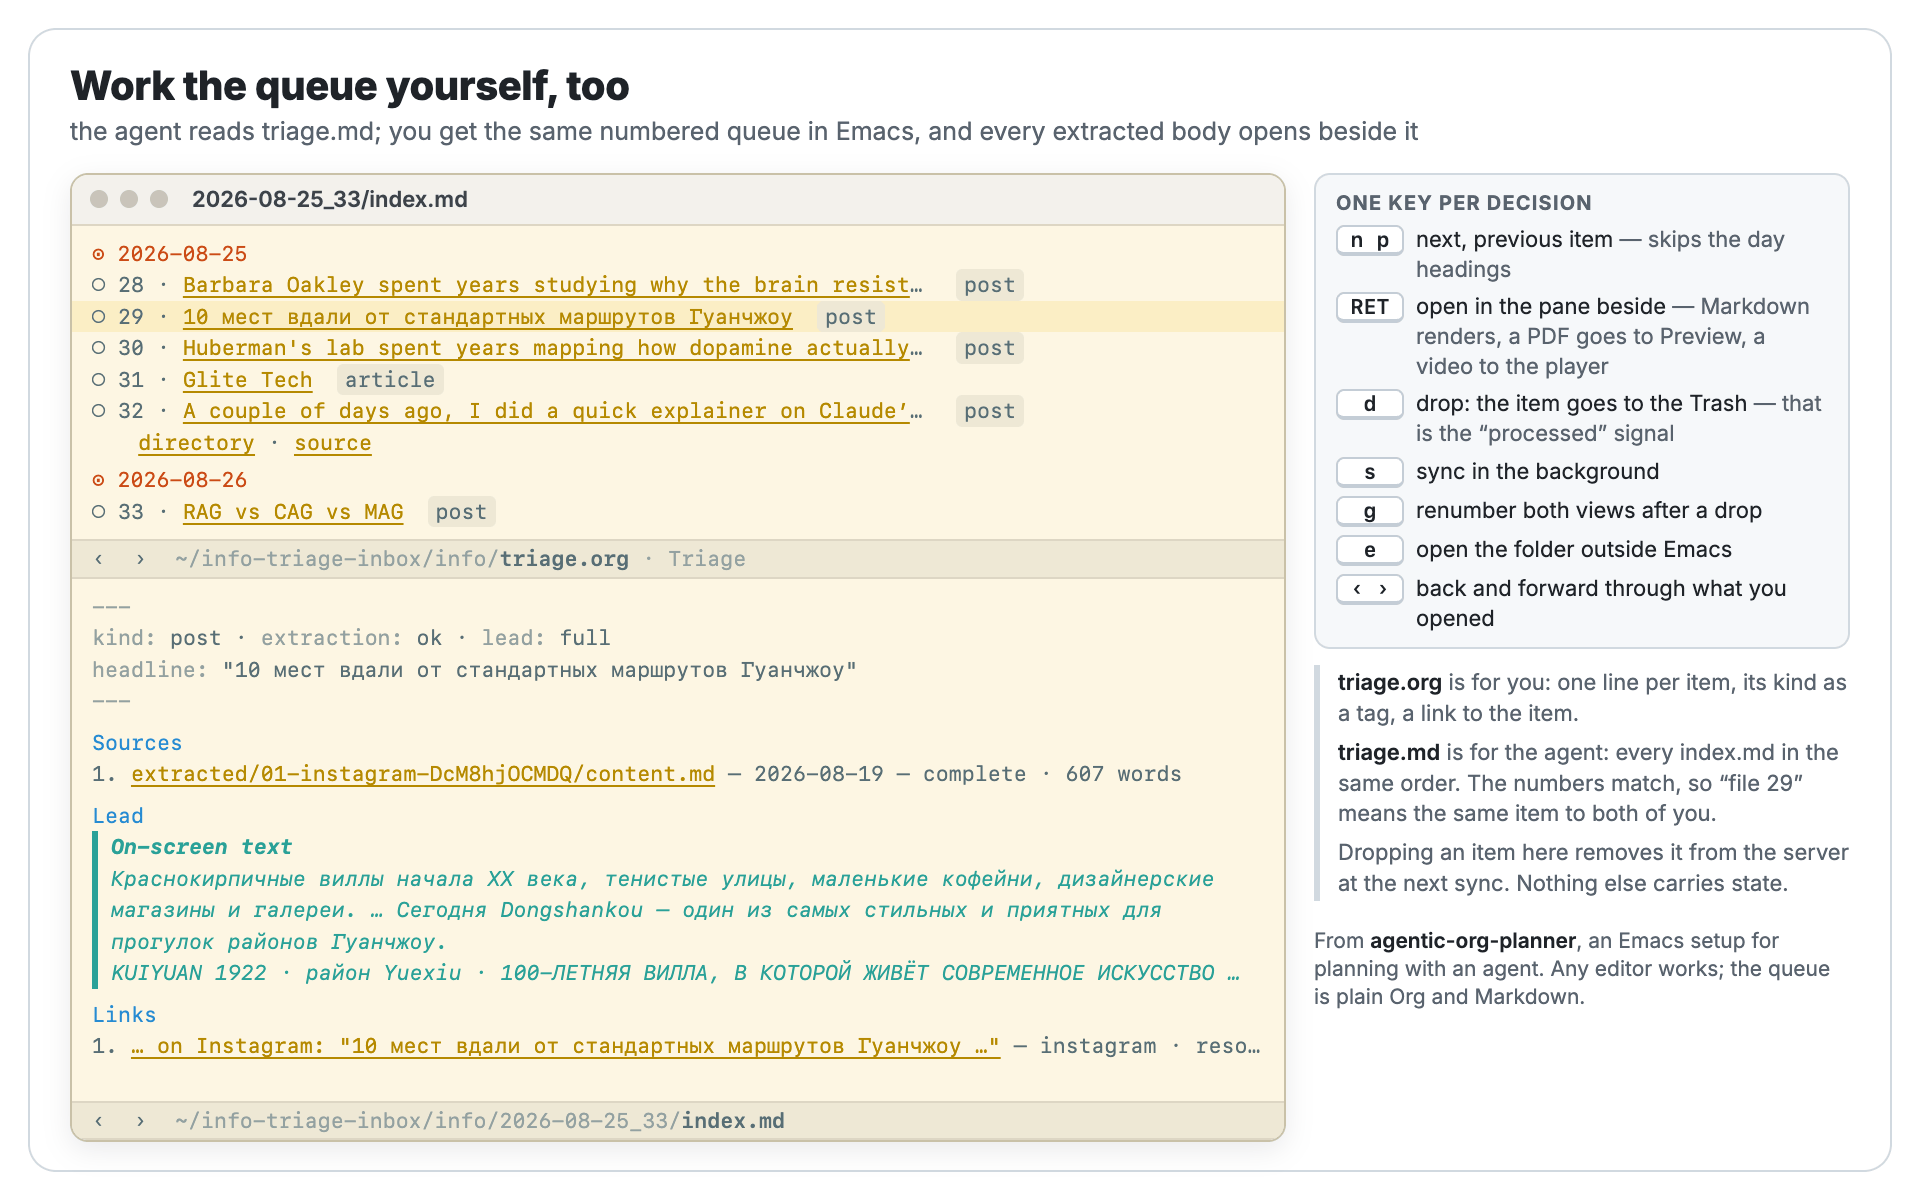
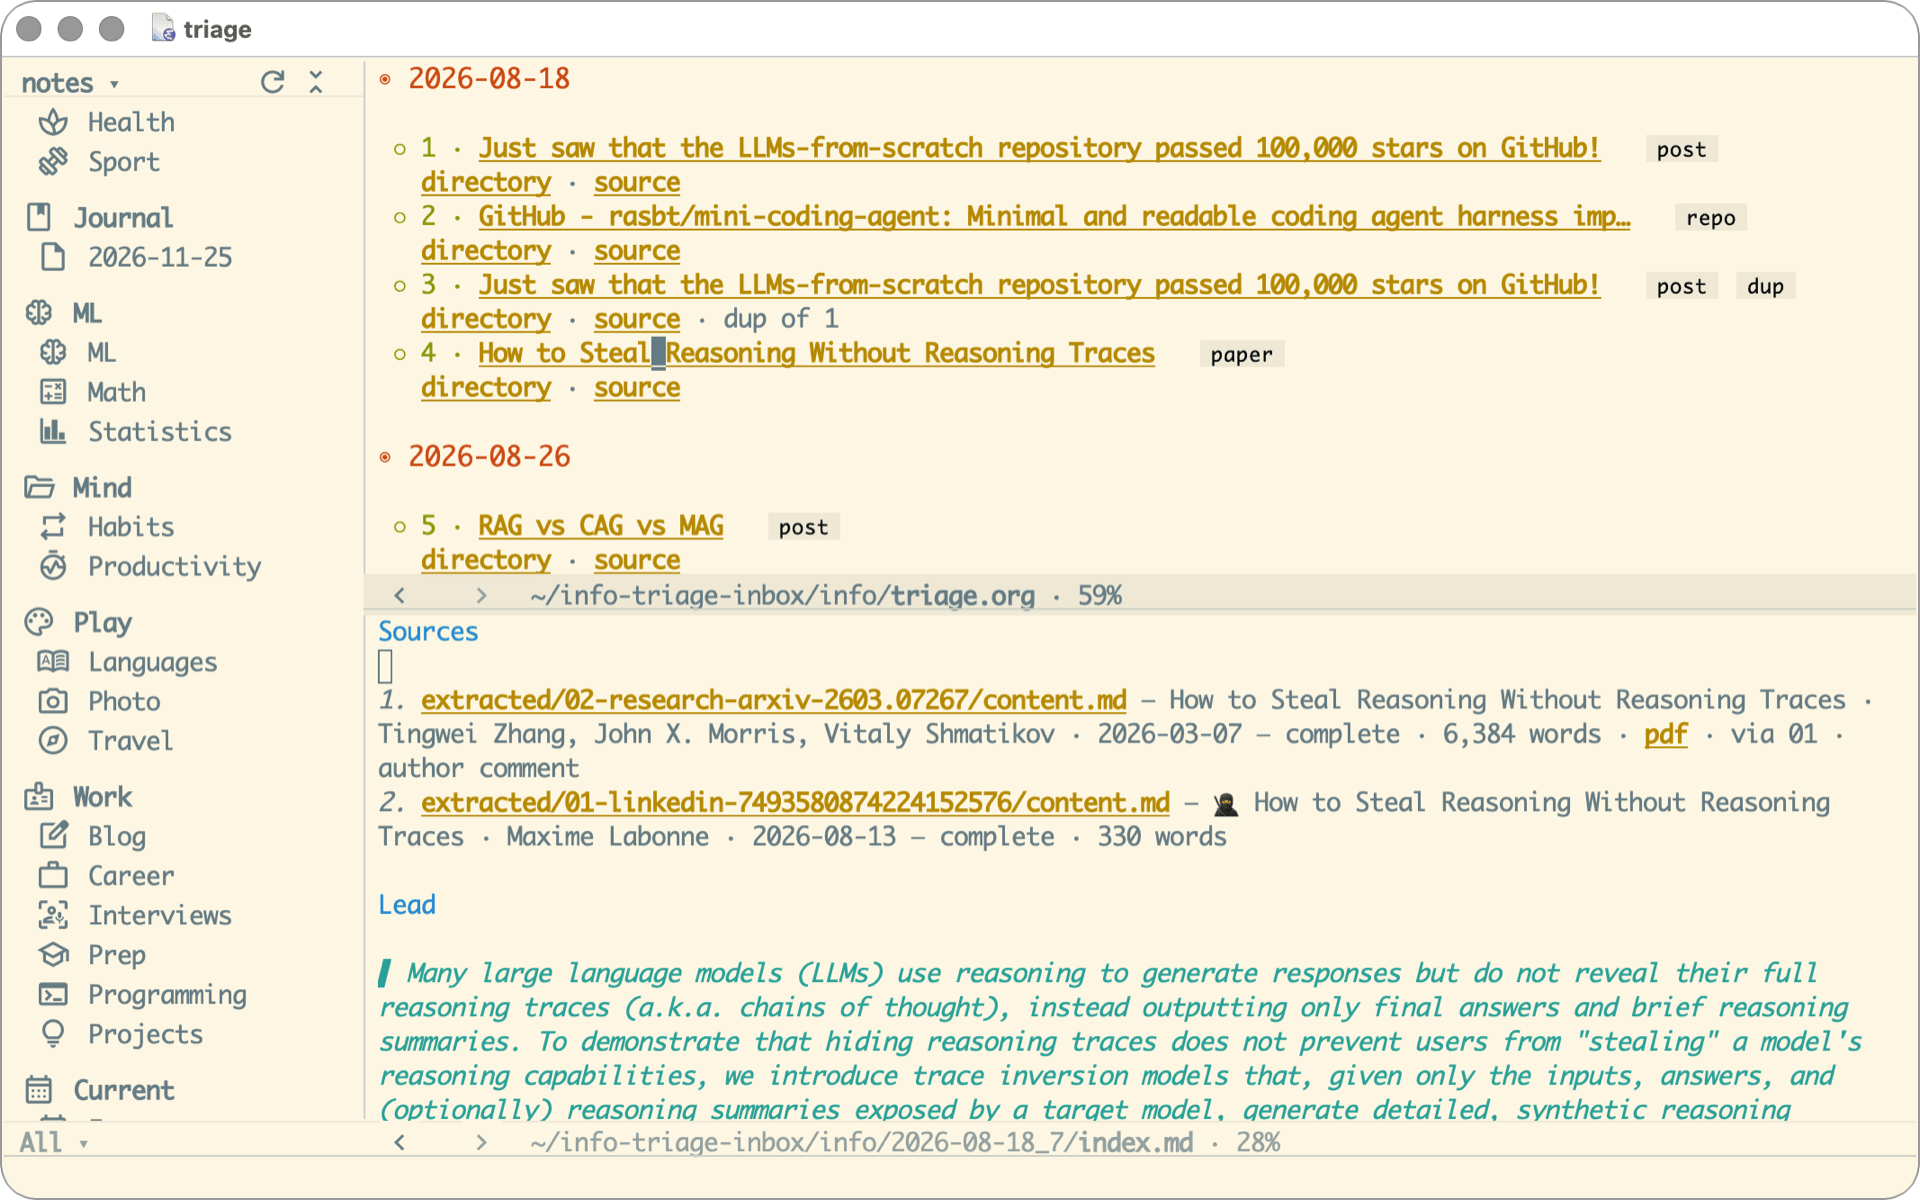
The capture inbox, with what was extracted from the selected paper below the queue.
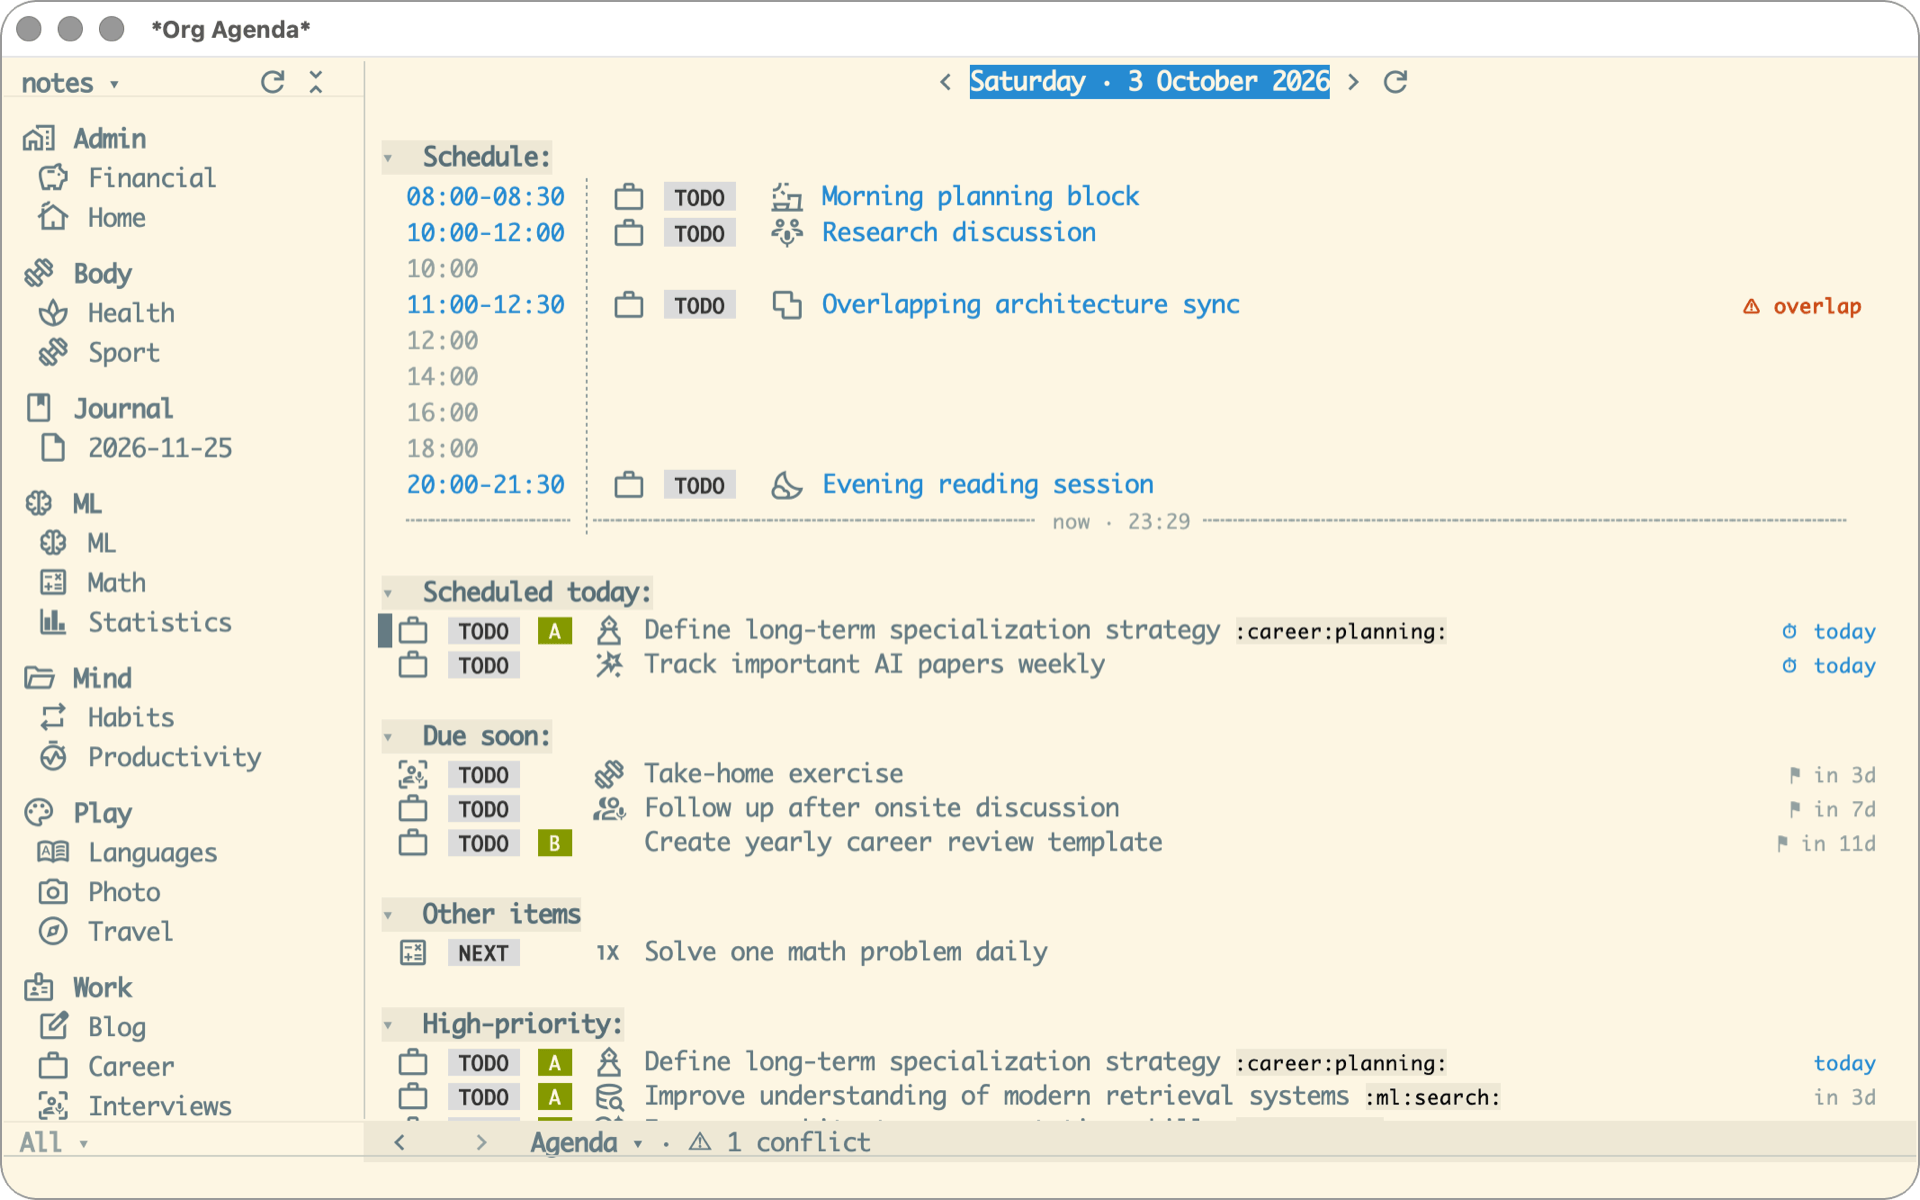
Today's agenda, a timeline with a now-line and a warning on two overlapping meetings.
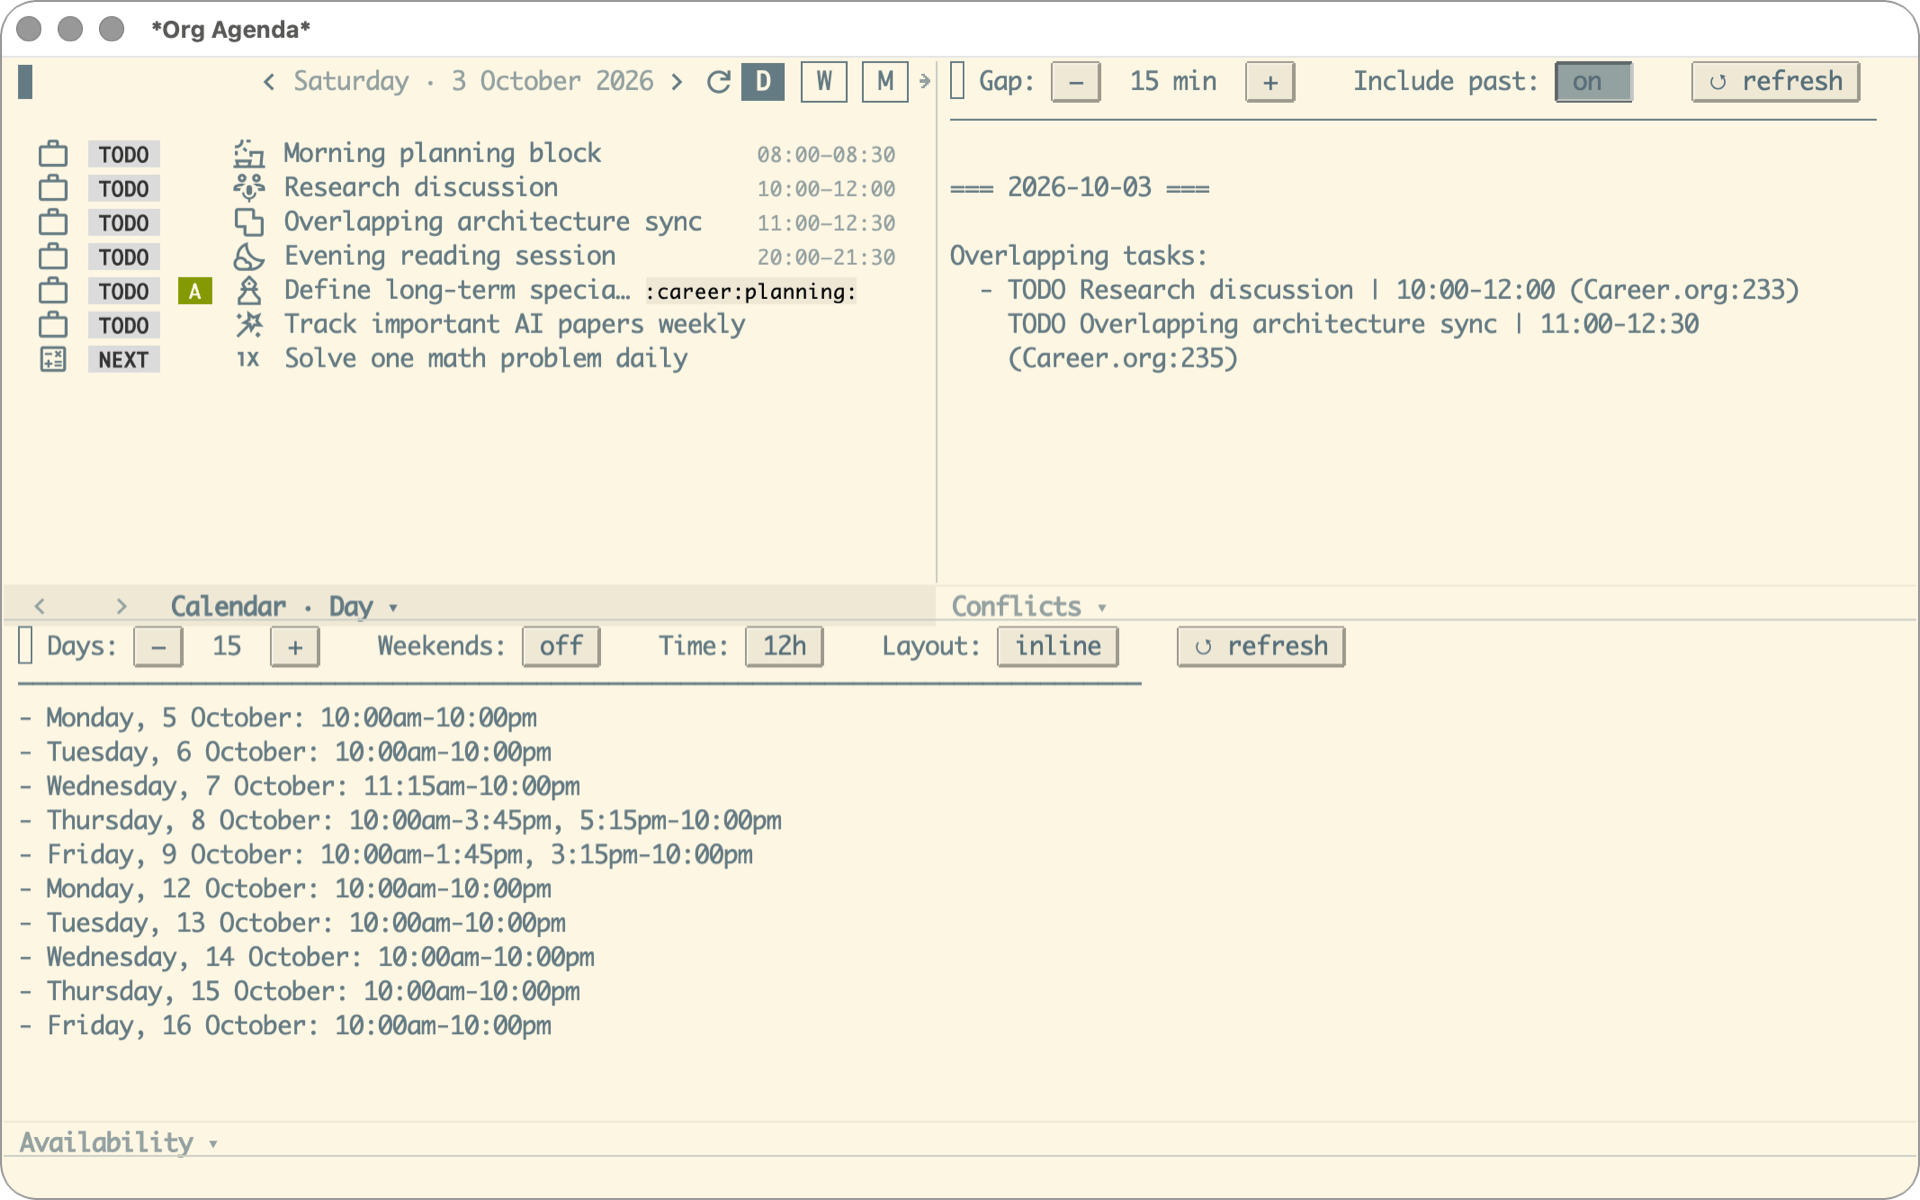
The day's calendar beside the conflicts view, and free slots for the next two weeks.
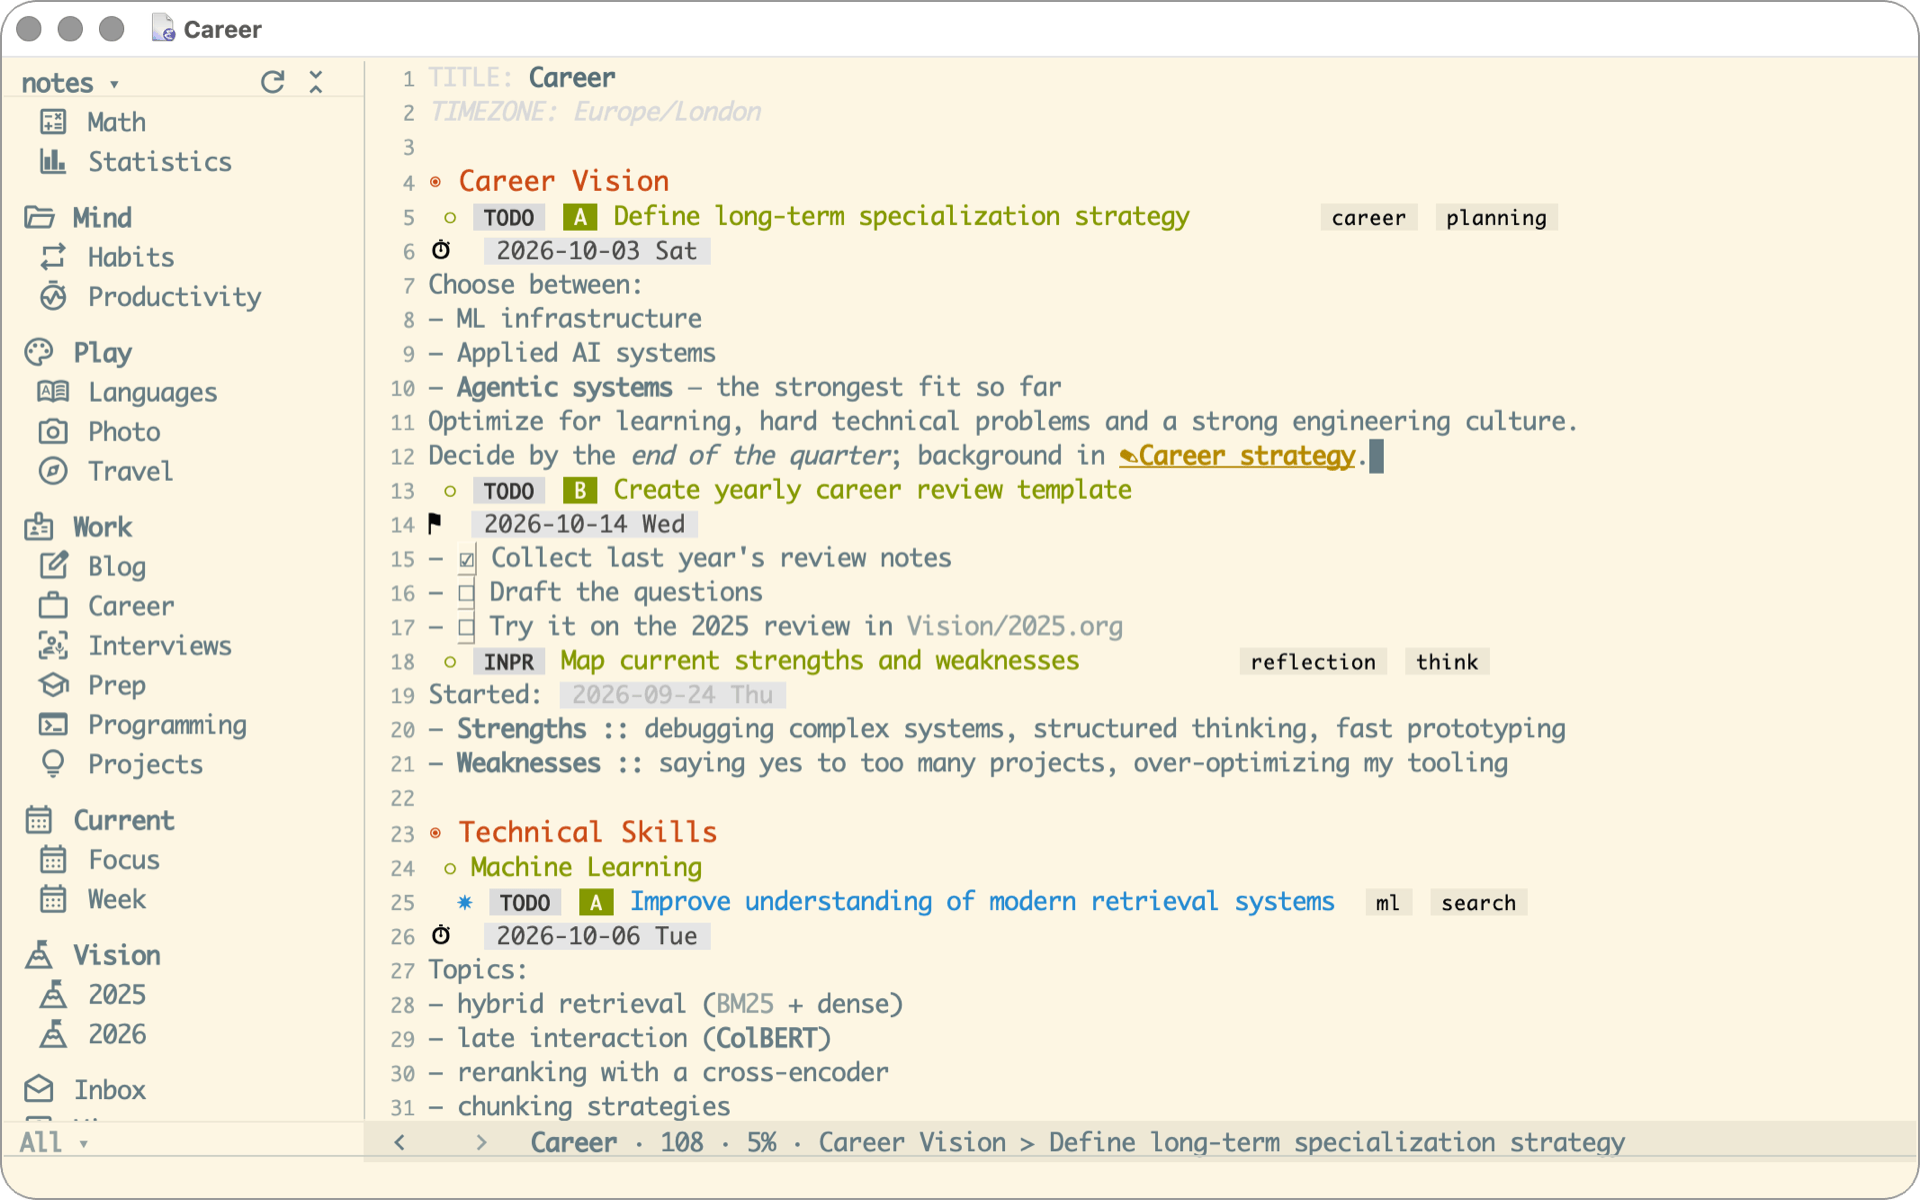
A plan file as it is displayed, with status and priority badges, tags and checklists.

Works with Agent context pipeline

  • emacs
  • org mode
  • ai agents
  • claude code
  • context engineering
  • planning
  • productivity

Agent context pipeline

active

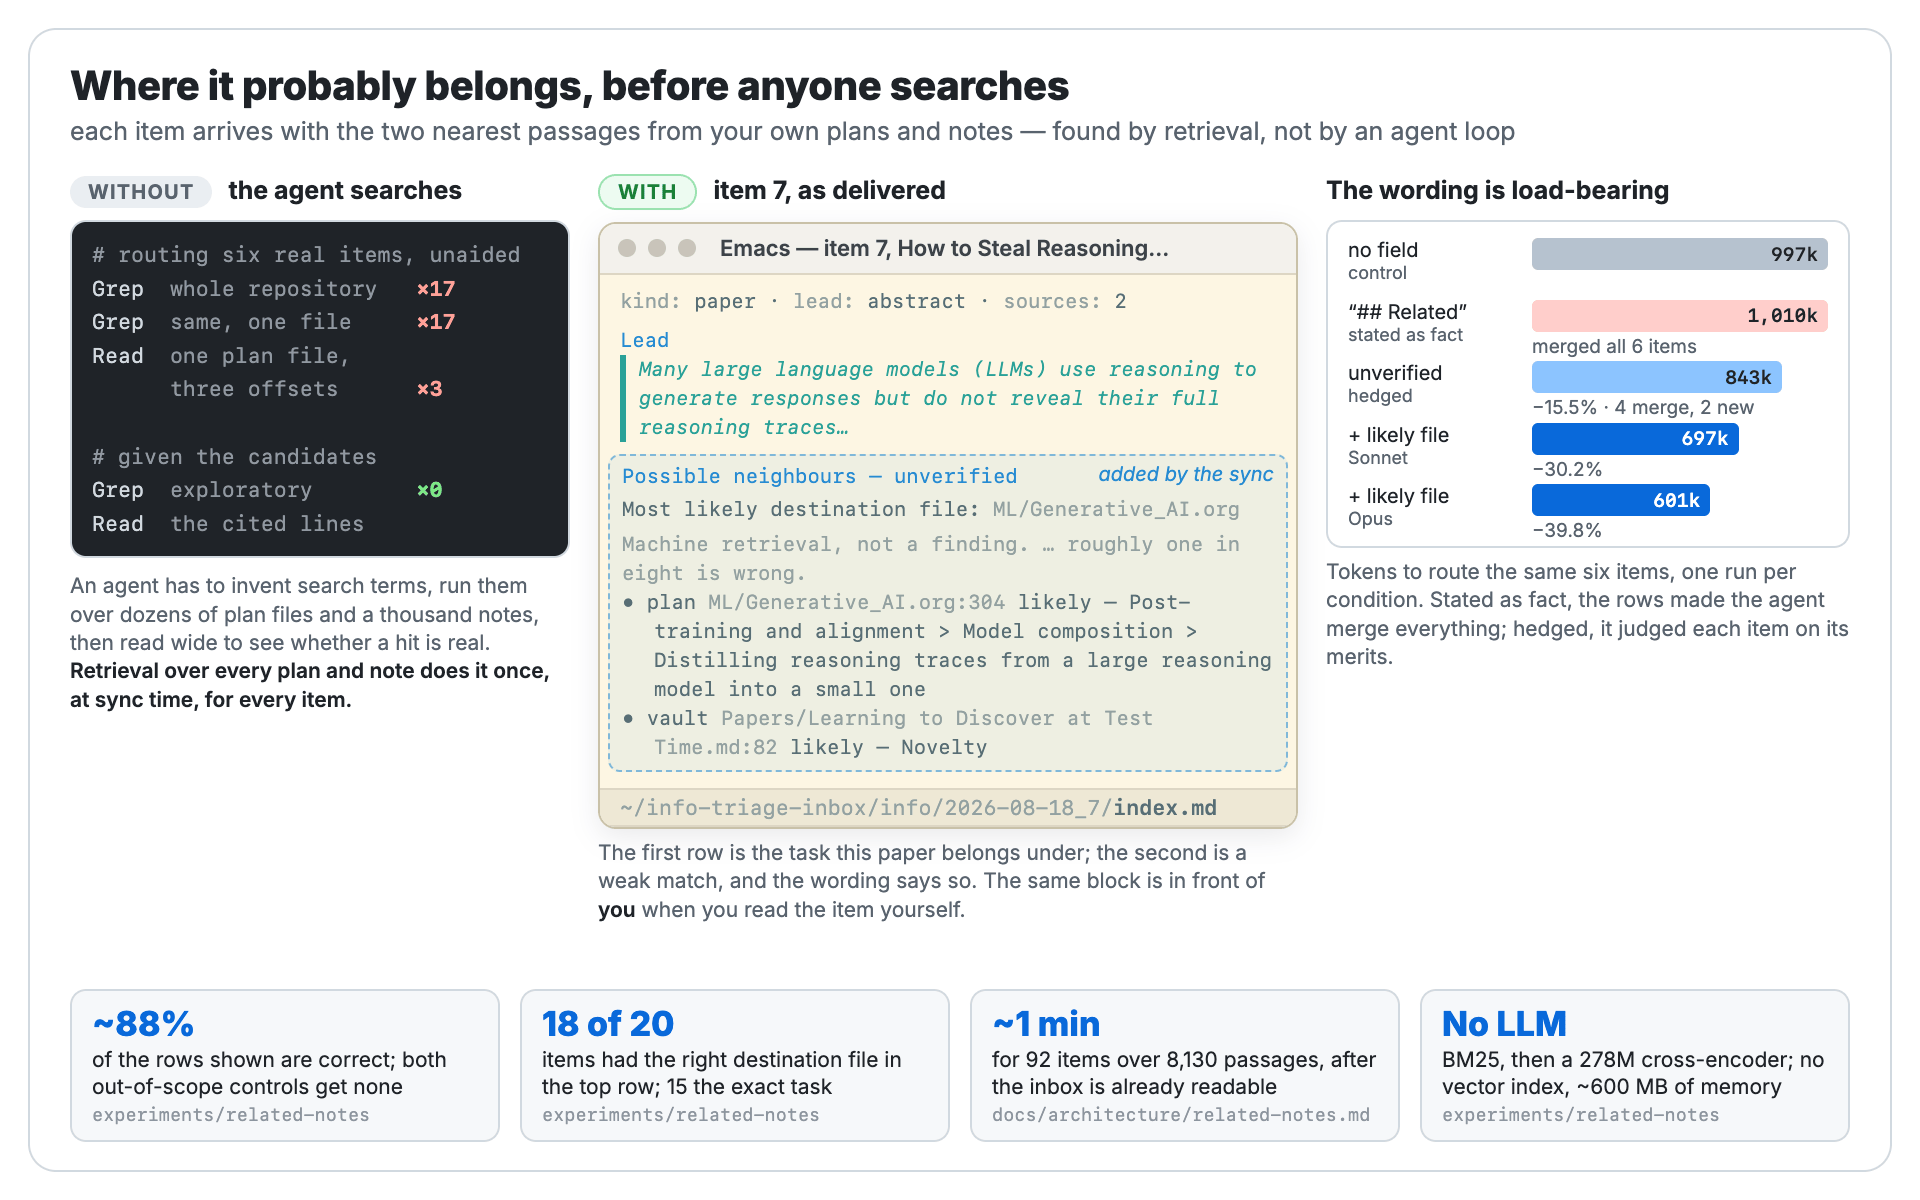
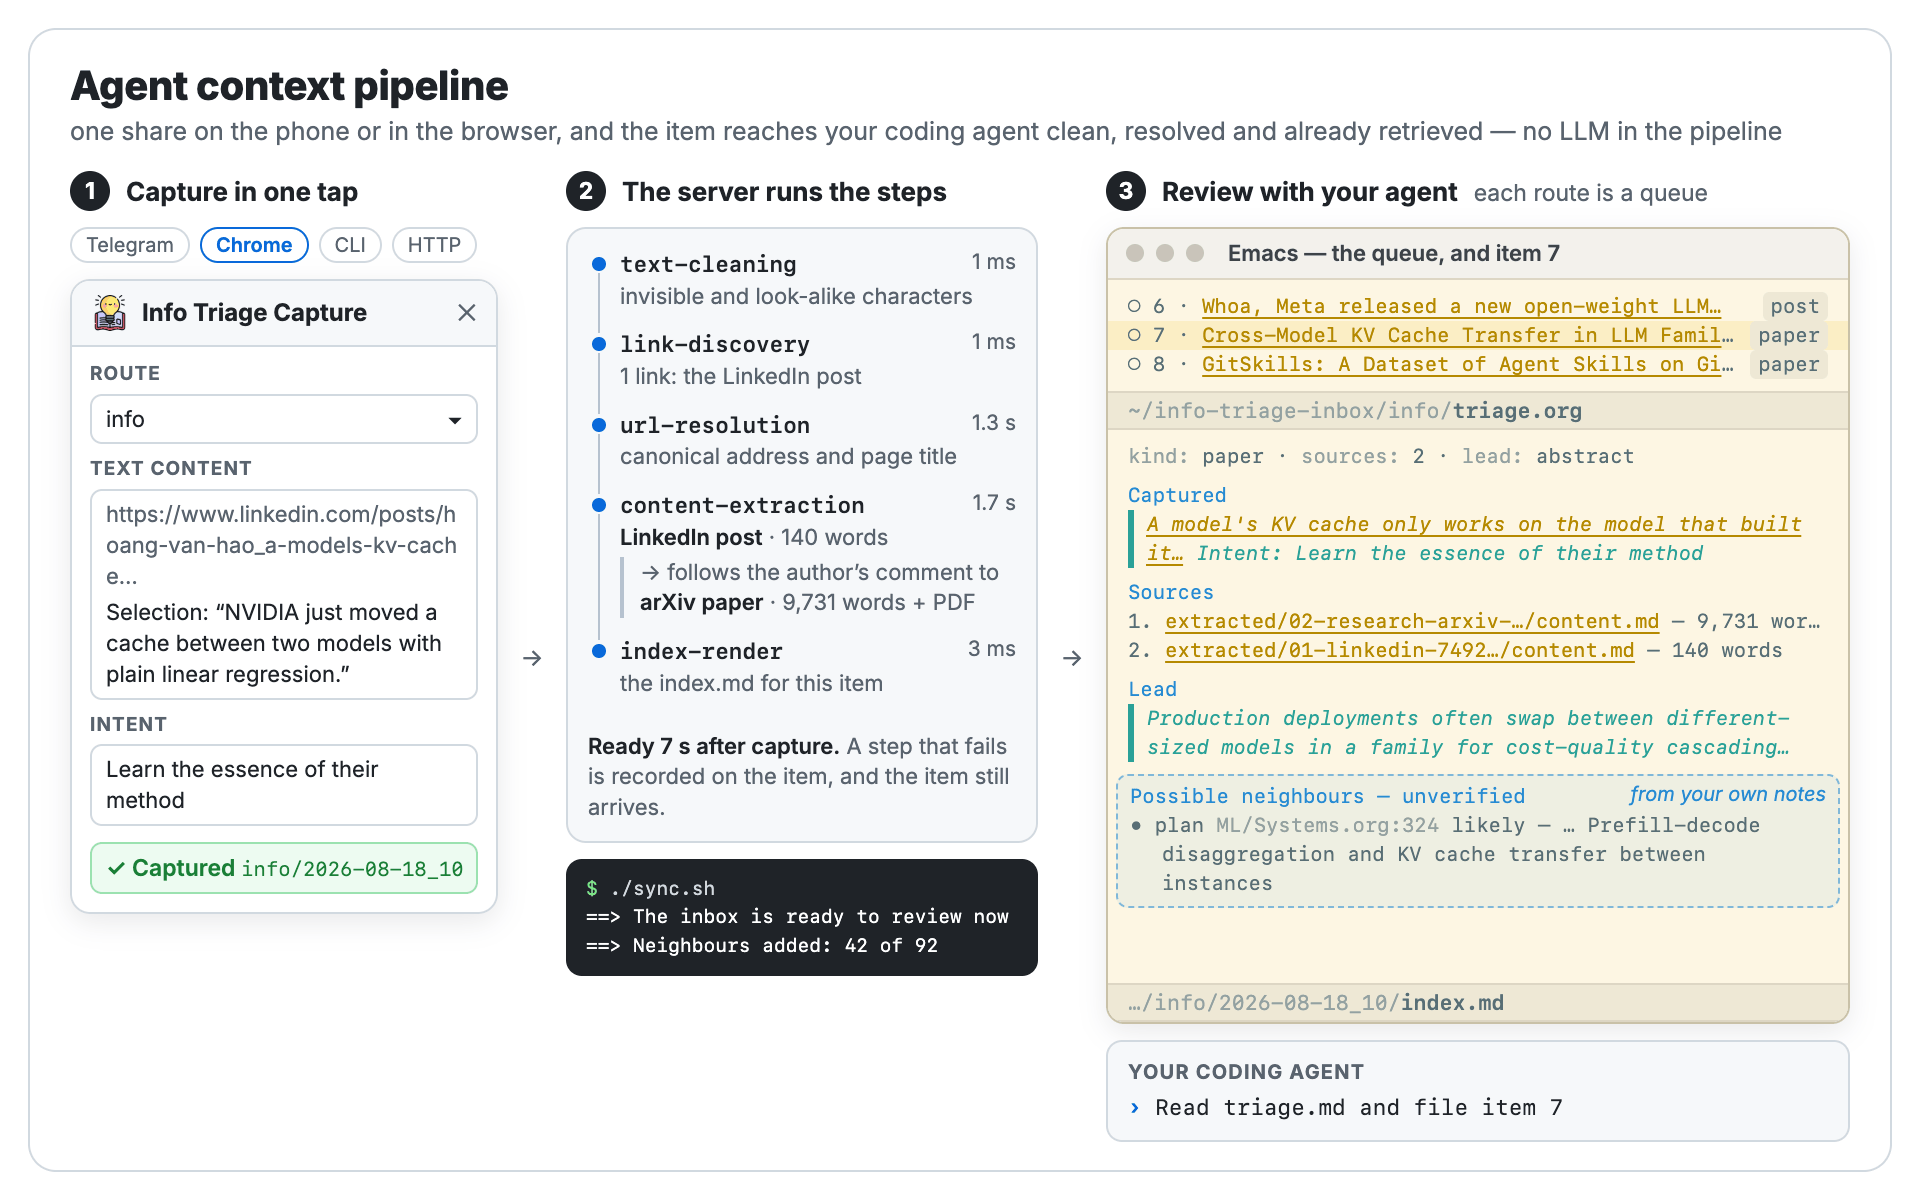
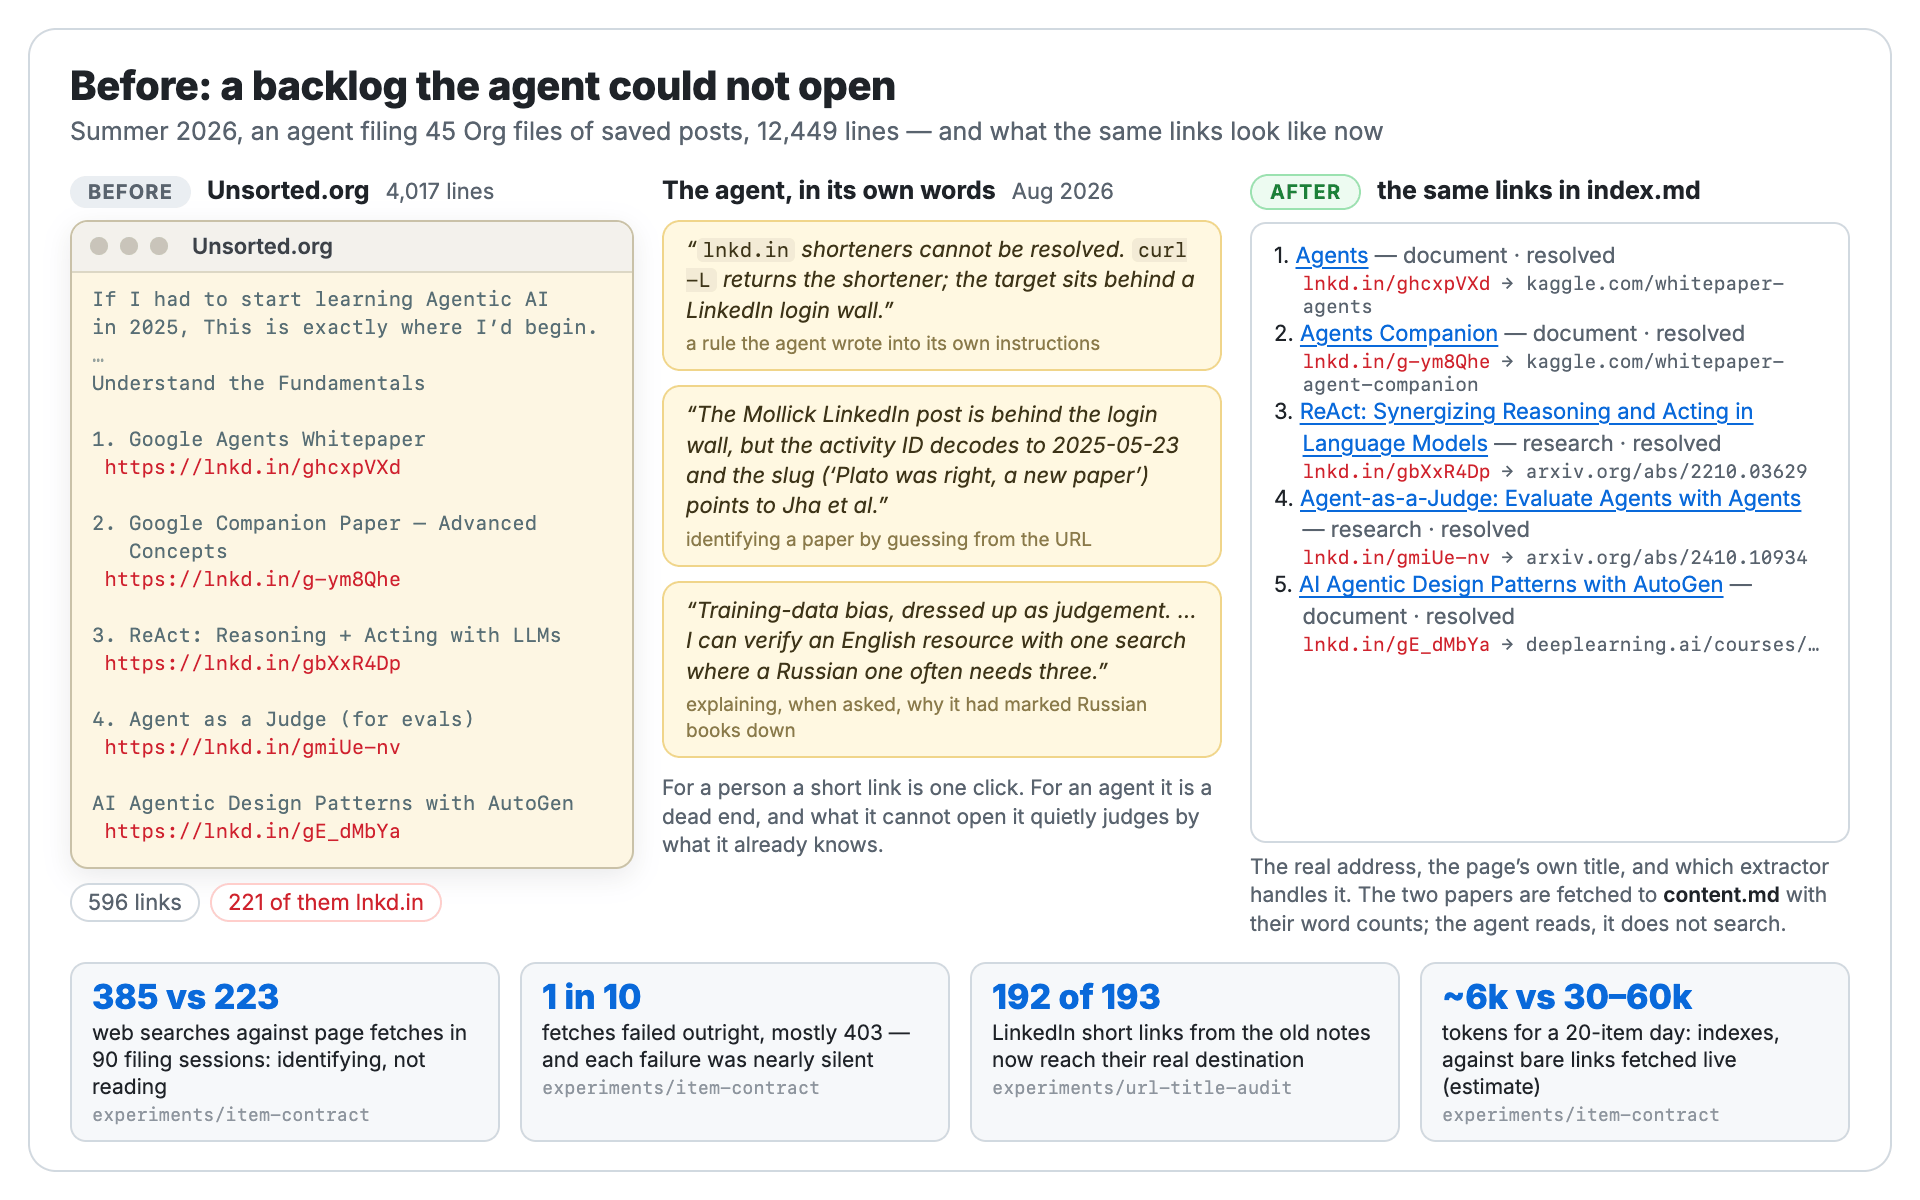
The capture side of a planning system: a self-hosted pipeline between what you come across during the day and the agent that sorts it into your plan. It captures from a phone, a browser or the command line, extracts and cleans the content, resolves links and titles, and looks up related notes ahead of the agent (BM25 recall, a cross-encoder rerank, an abstain gate). In experiments it opened content the agent could not reach on its own, and the agent sorted the same items with 30–40% fewer tokens and no exploratory searches.

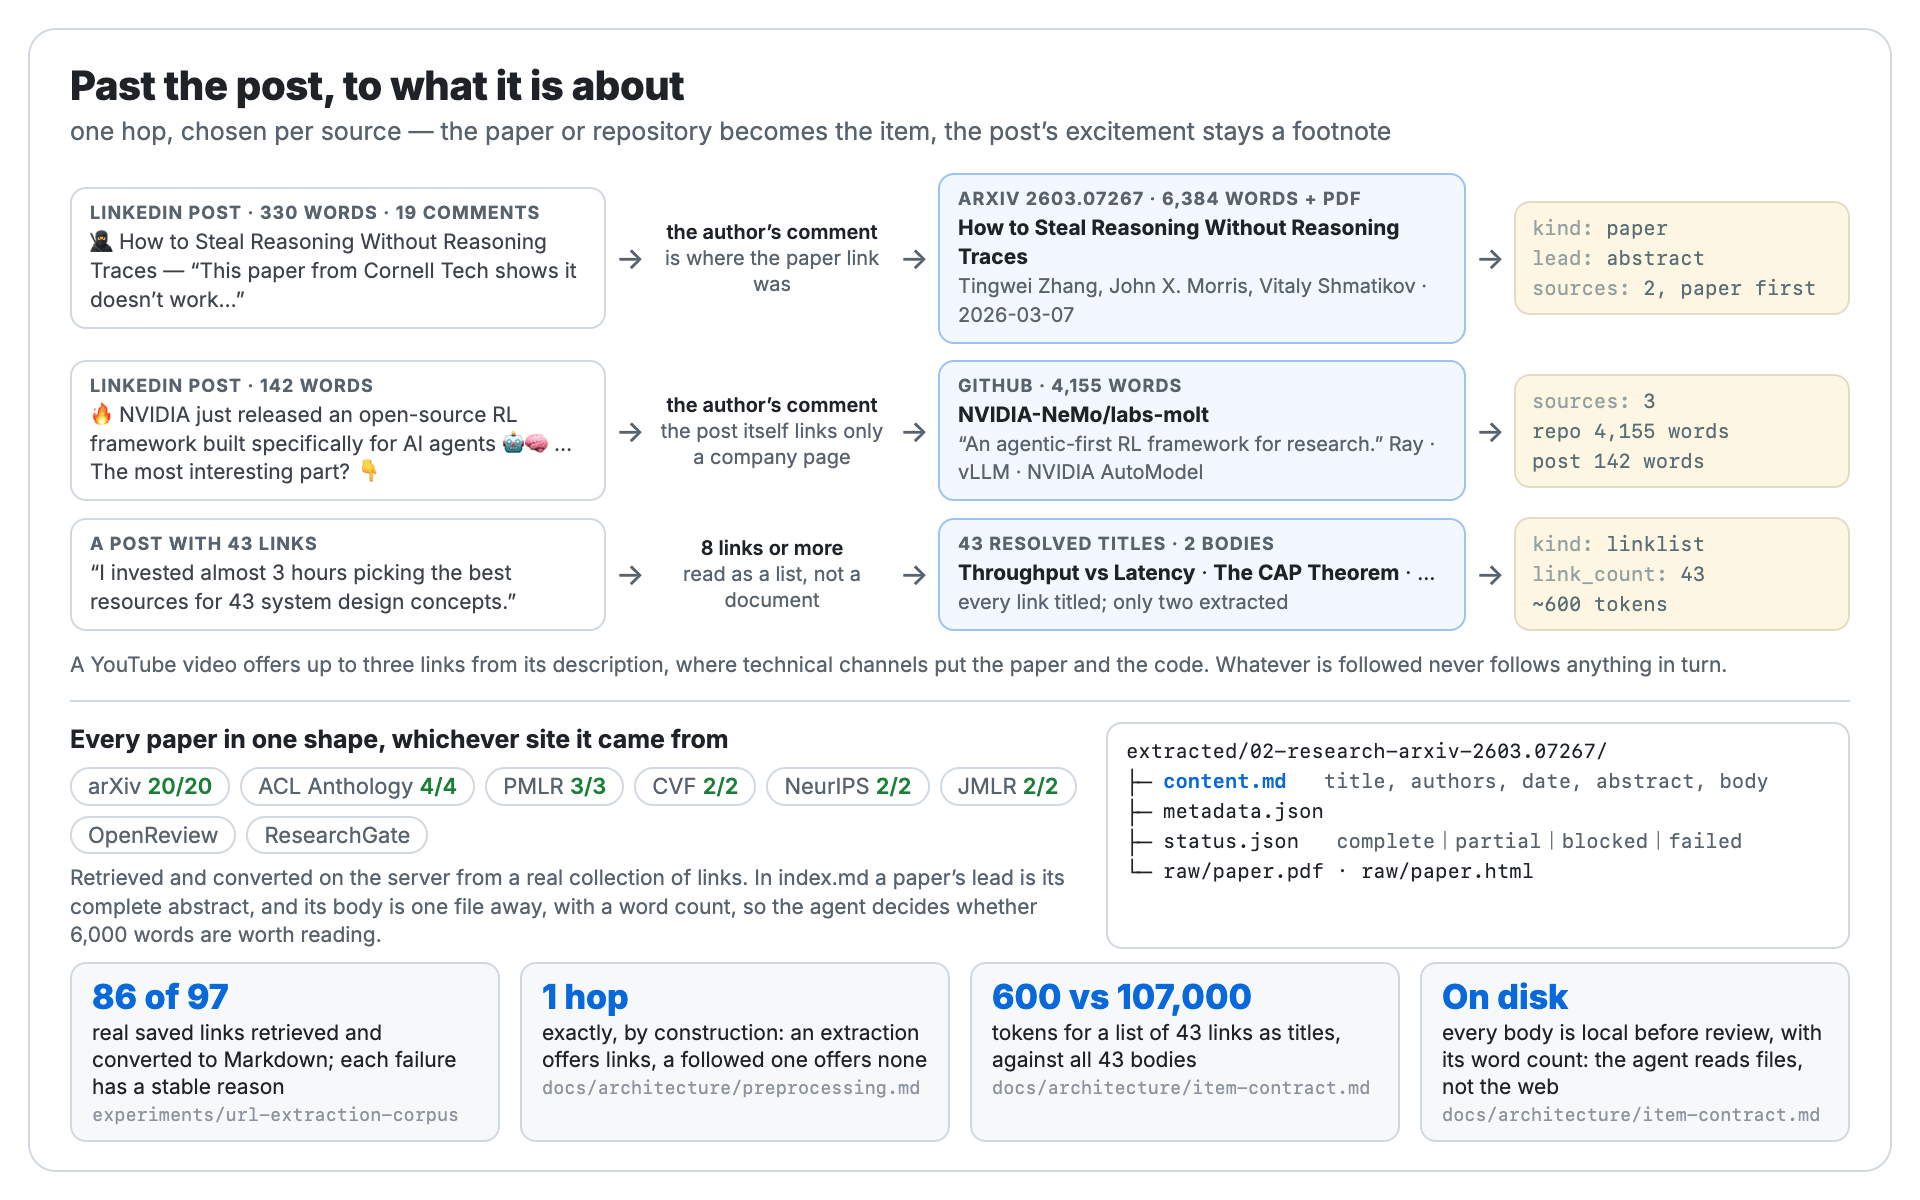
One item's way through the pipeline, from a captured LinkedIn post to a numbered entry the agent is asked to file.
The old backlog of unresolvable short links, and the same links as the index lists them now.
Three real cases of following a post to the paper or repository it is about.
Possible neighbours from the user's own notes, and what they save the agent in searches and tokens.
The queue in Emacs, with the selected item's index below it.

Works with Agentic Org Planner

  • context engineering
  • ai agents
  • information extraction
  • pdf extraction
  • ocr
  • speech to text
  • retrieval
  • self hosted

Applied LLM and speech systems

2 projects

Acervo

active

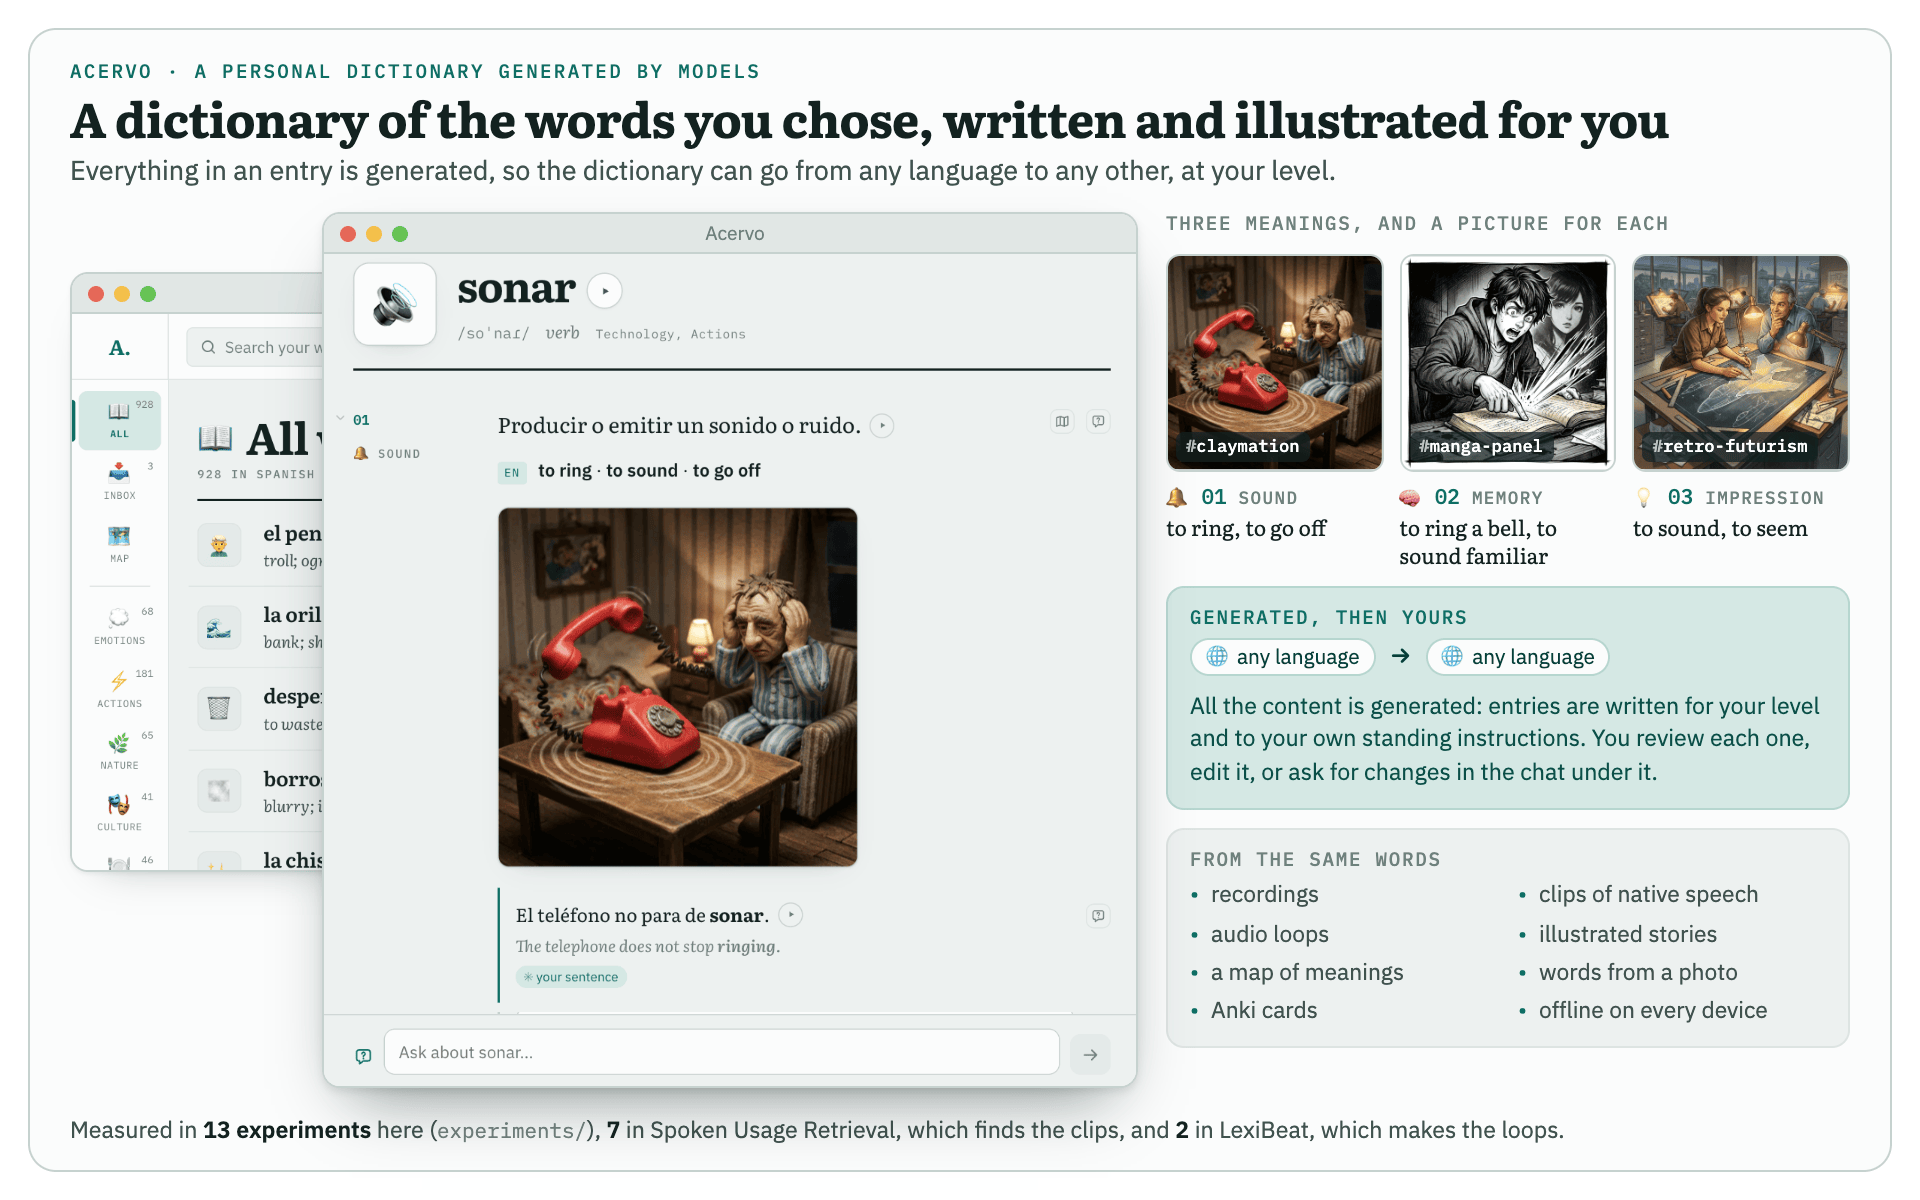
A self-hosted, offline-first personal dictionary whose content is generated by LLMs and multimodal models: you collect the words you want to learn, not the ones a dictionary chose. Paste a word or the sentence you met it in, and a language model writes the entry. Image models draw expressive illustrations for it, clips of native speakers using the word are selected from YouTube, and a handful of words become generated audio programmes and illustrated stories. Its design decisions were settled by experiments and measurement, kept in the repository.

One word's entry, with the picture drawn for each of its three meanings.
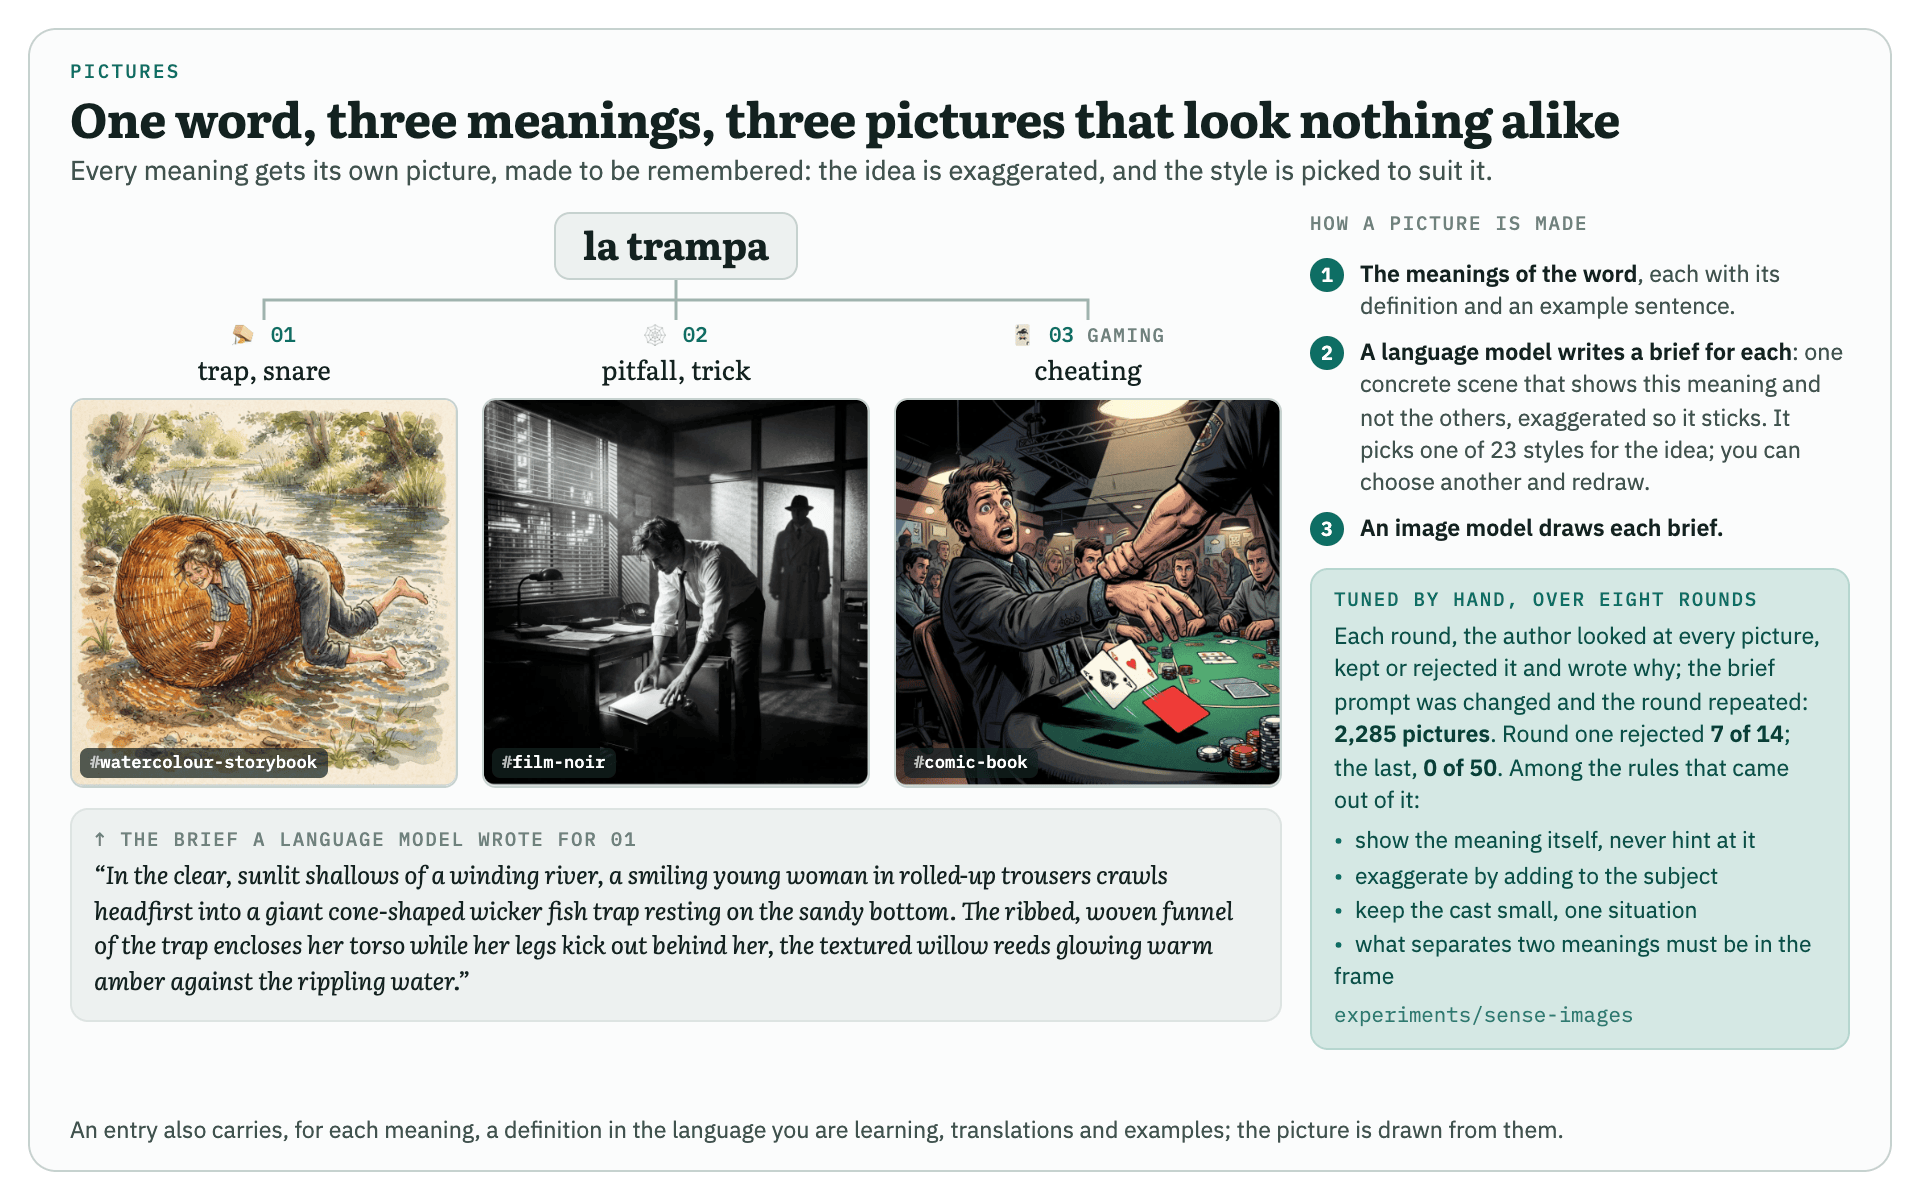
Three meanings of one word, each drawn in a different style from a brief a language model wrote.
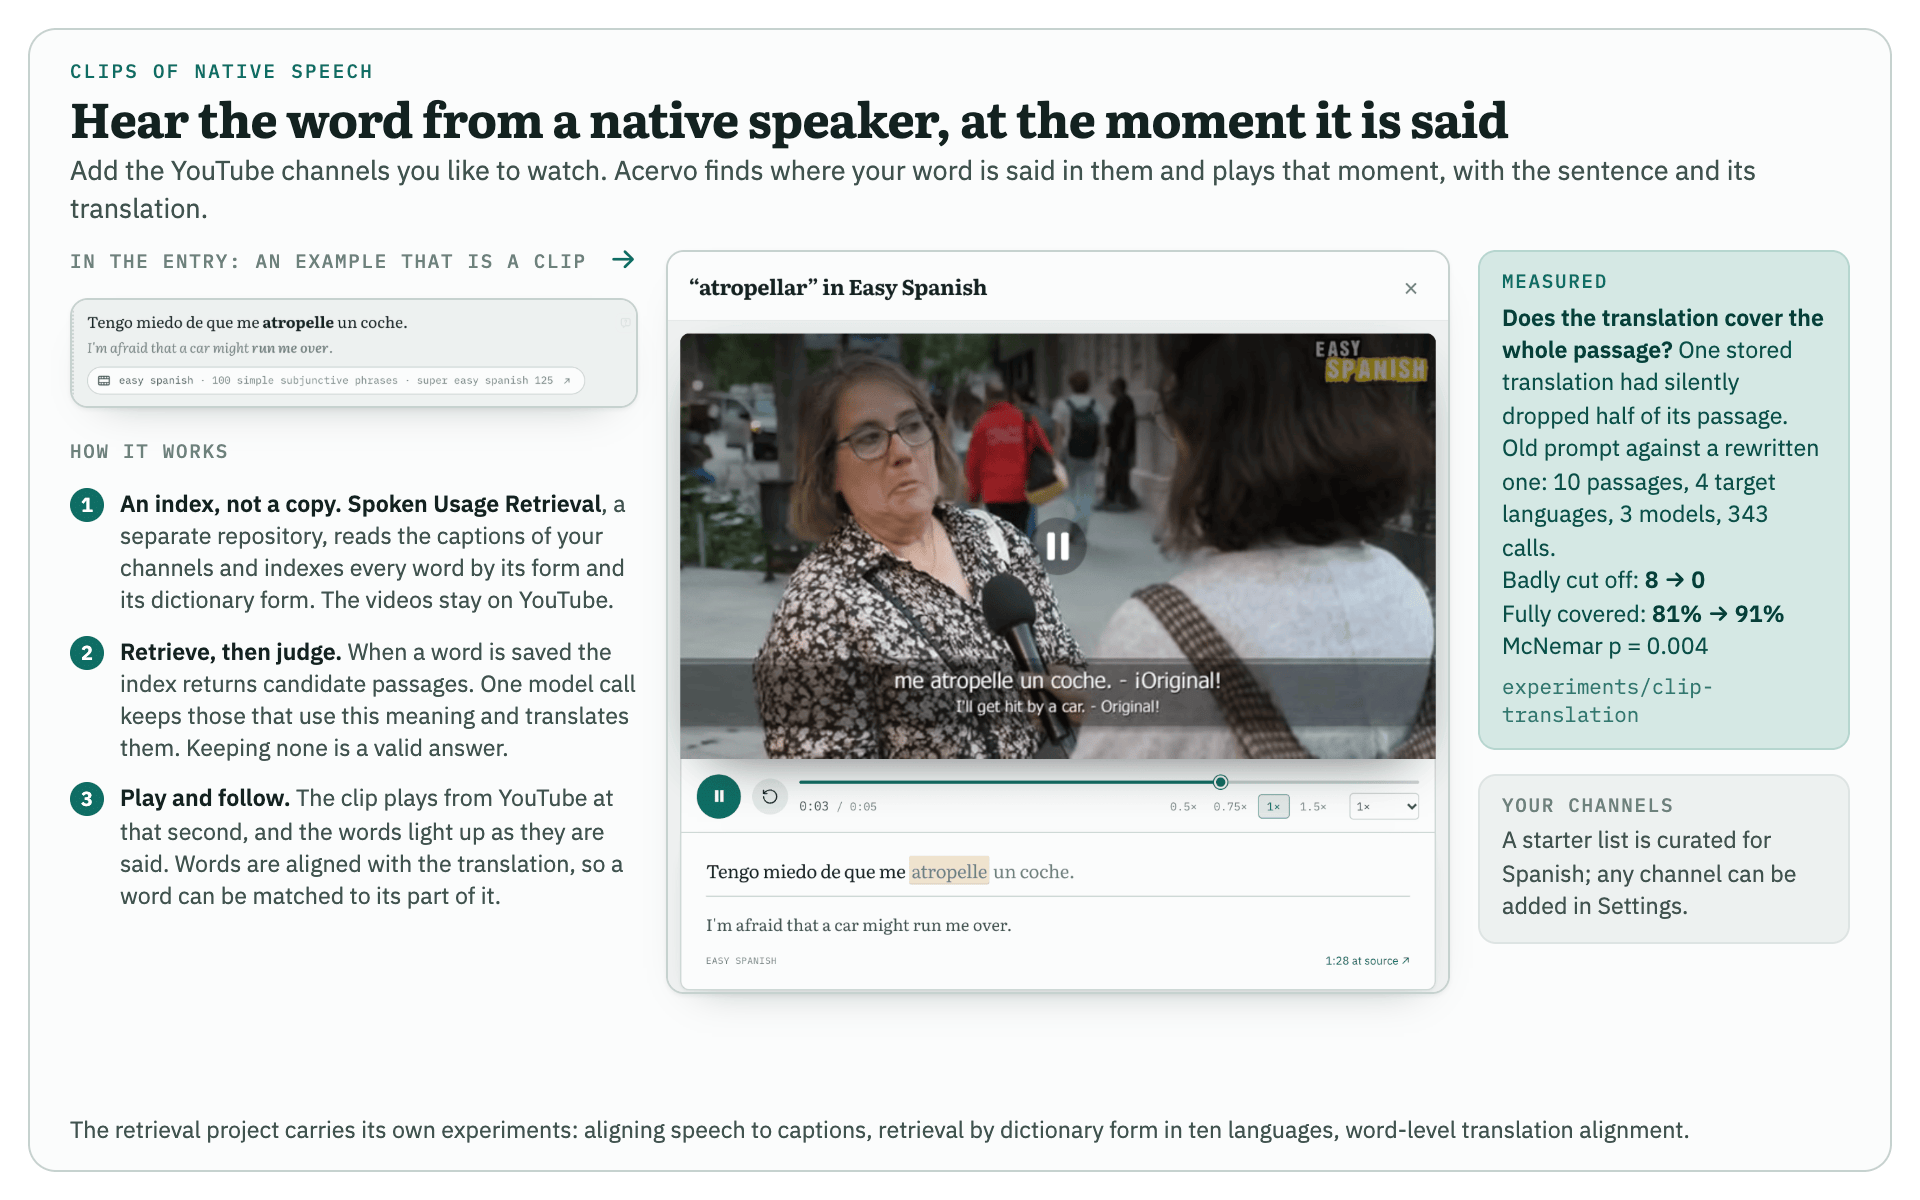
A clip of a native speaker using the word, with the passage and its translation.
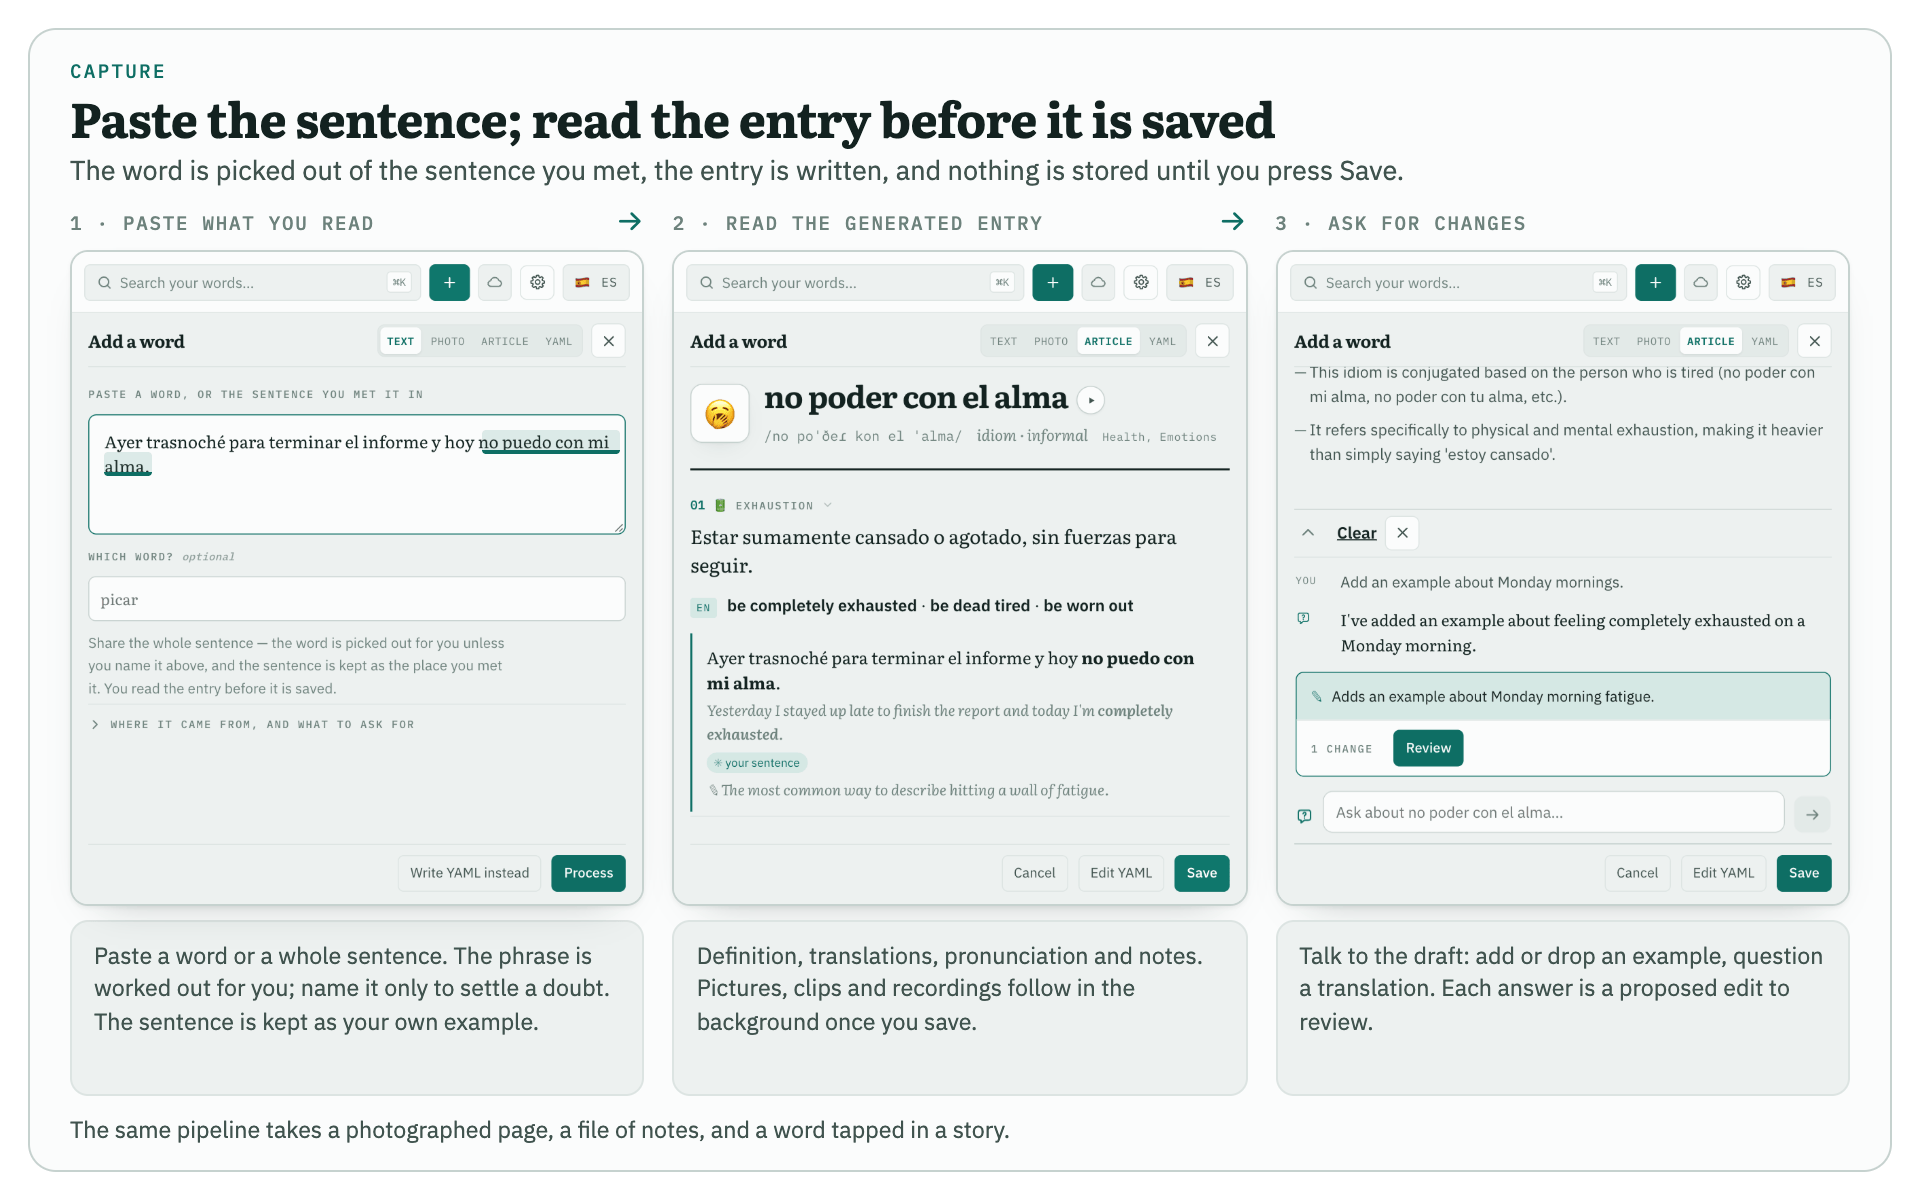
A pasted sentence and the entry drafted from it, shown for review before it is saved.
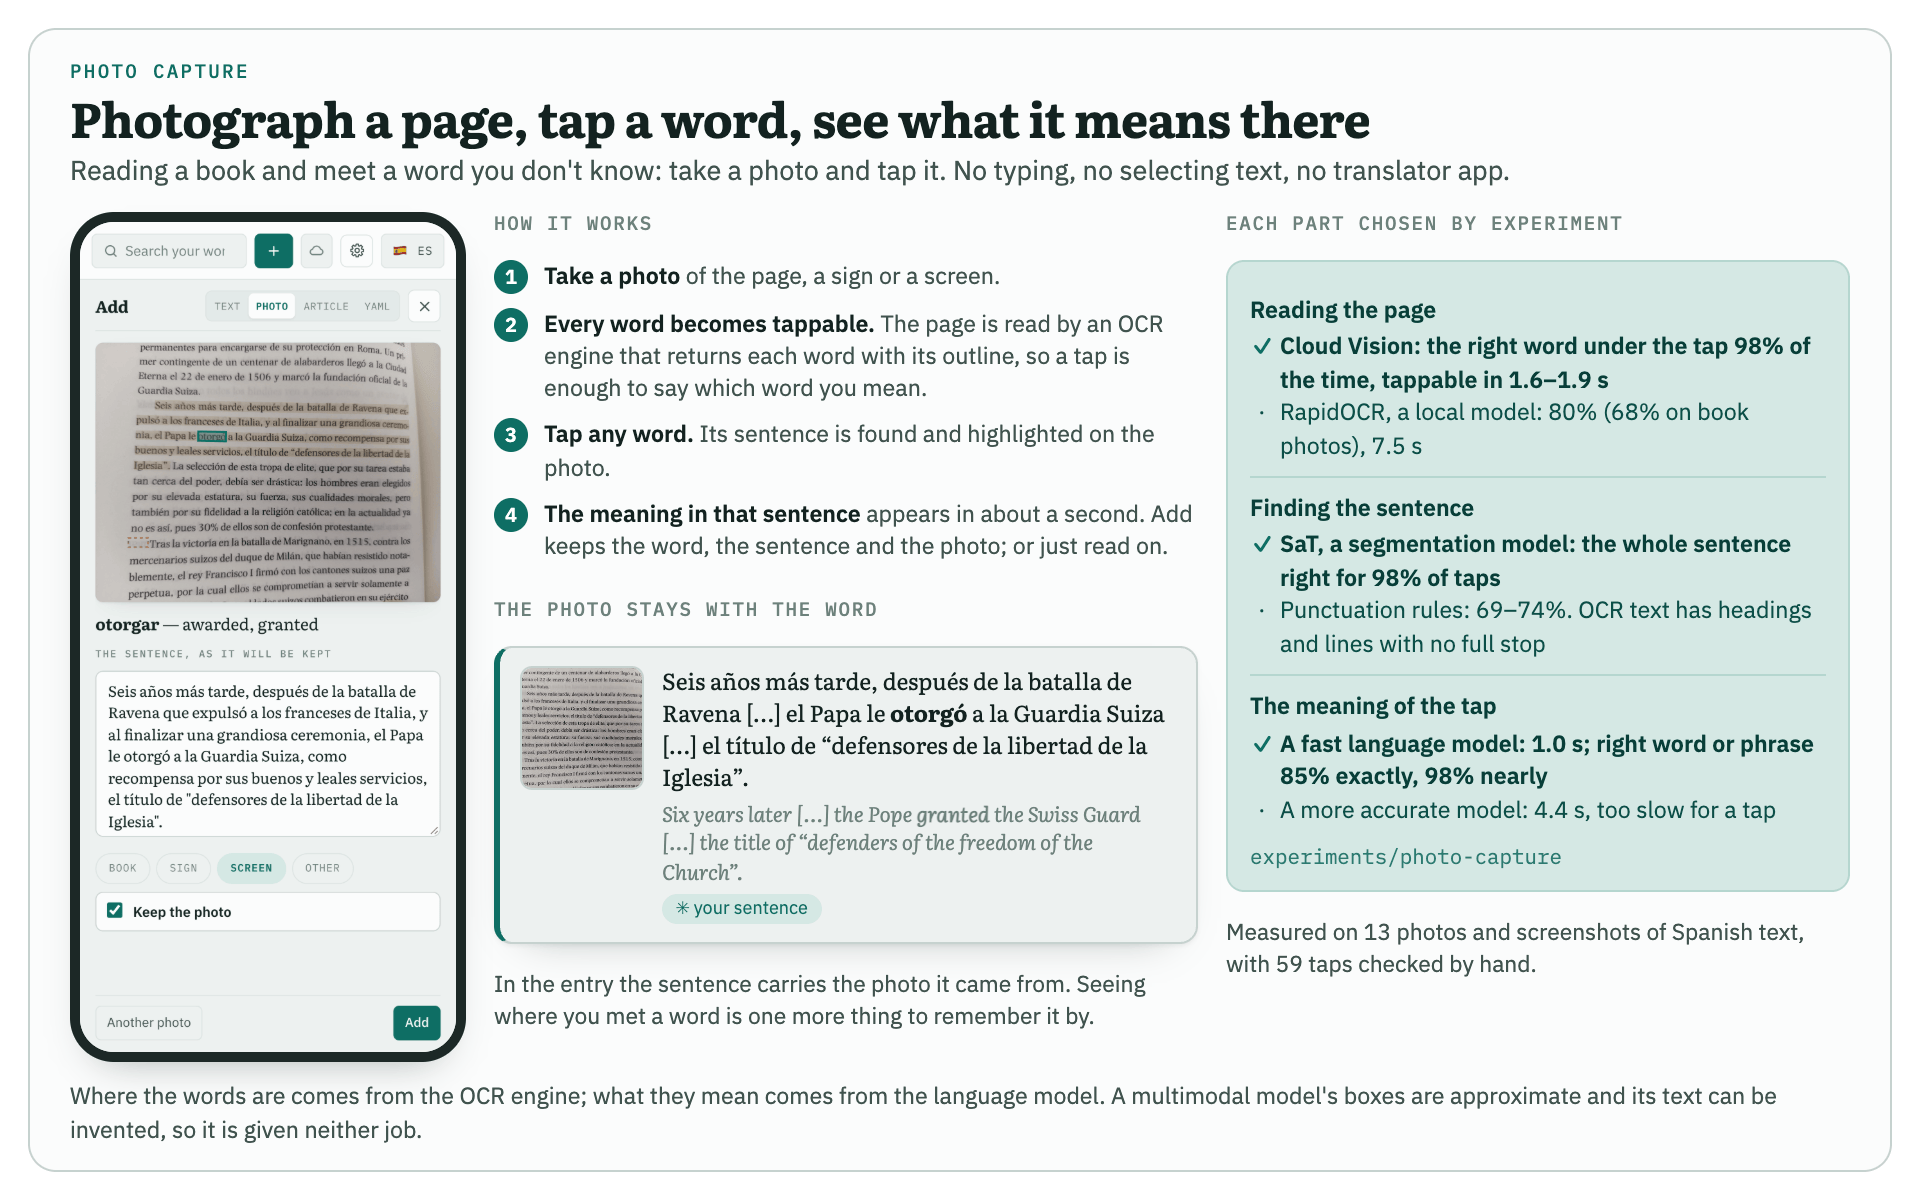
A photographed page with one word tapped, and what was measured to choose the OCR and the models.
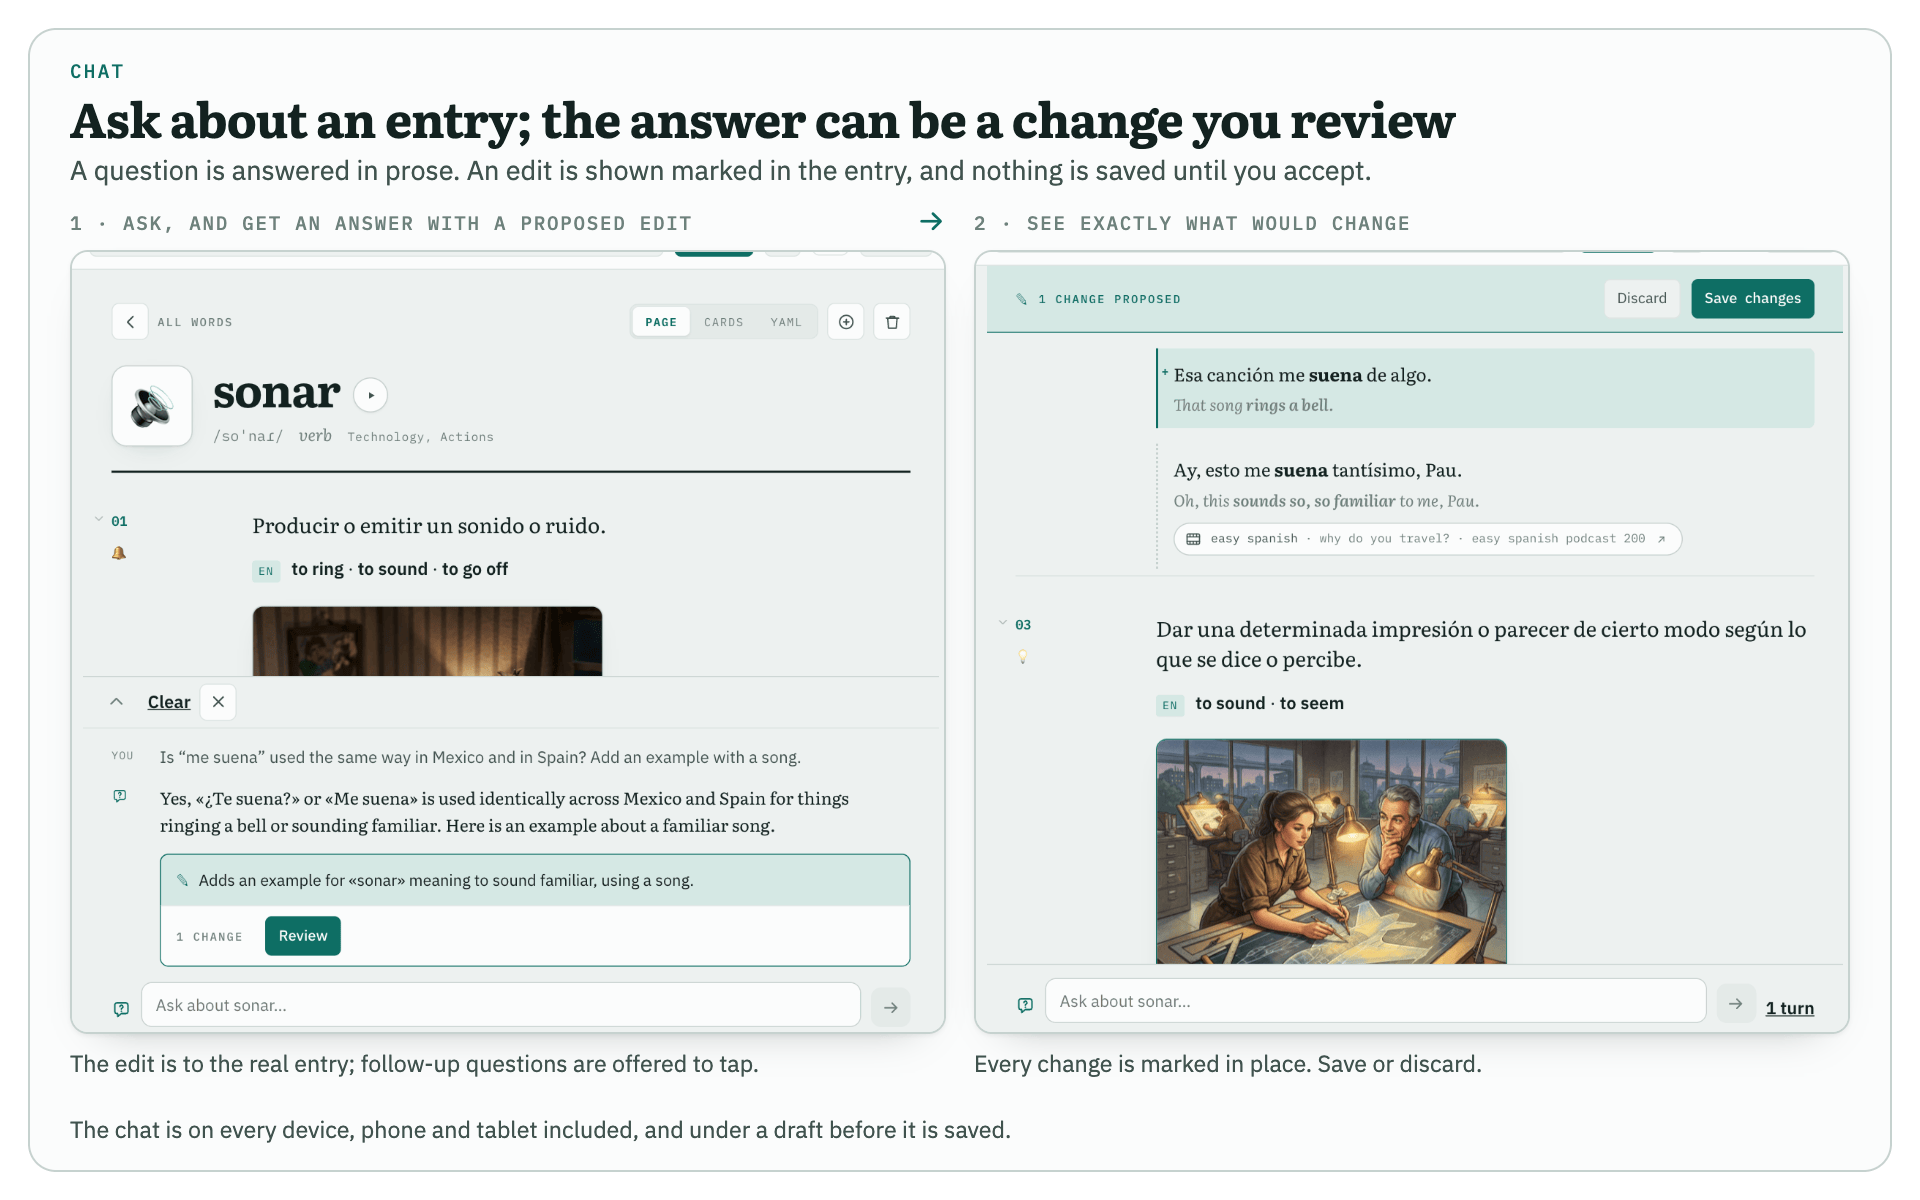
A question about an entry, and the change it proposes shown marked in the entry.
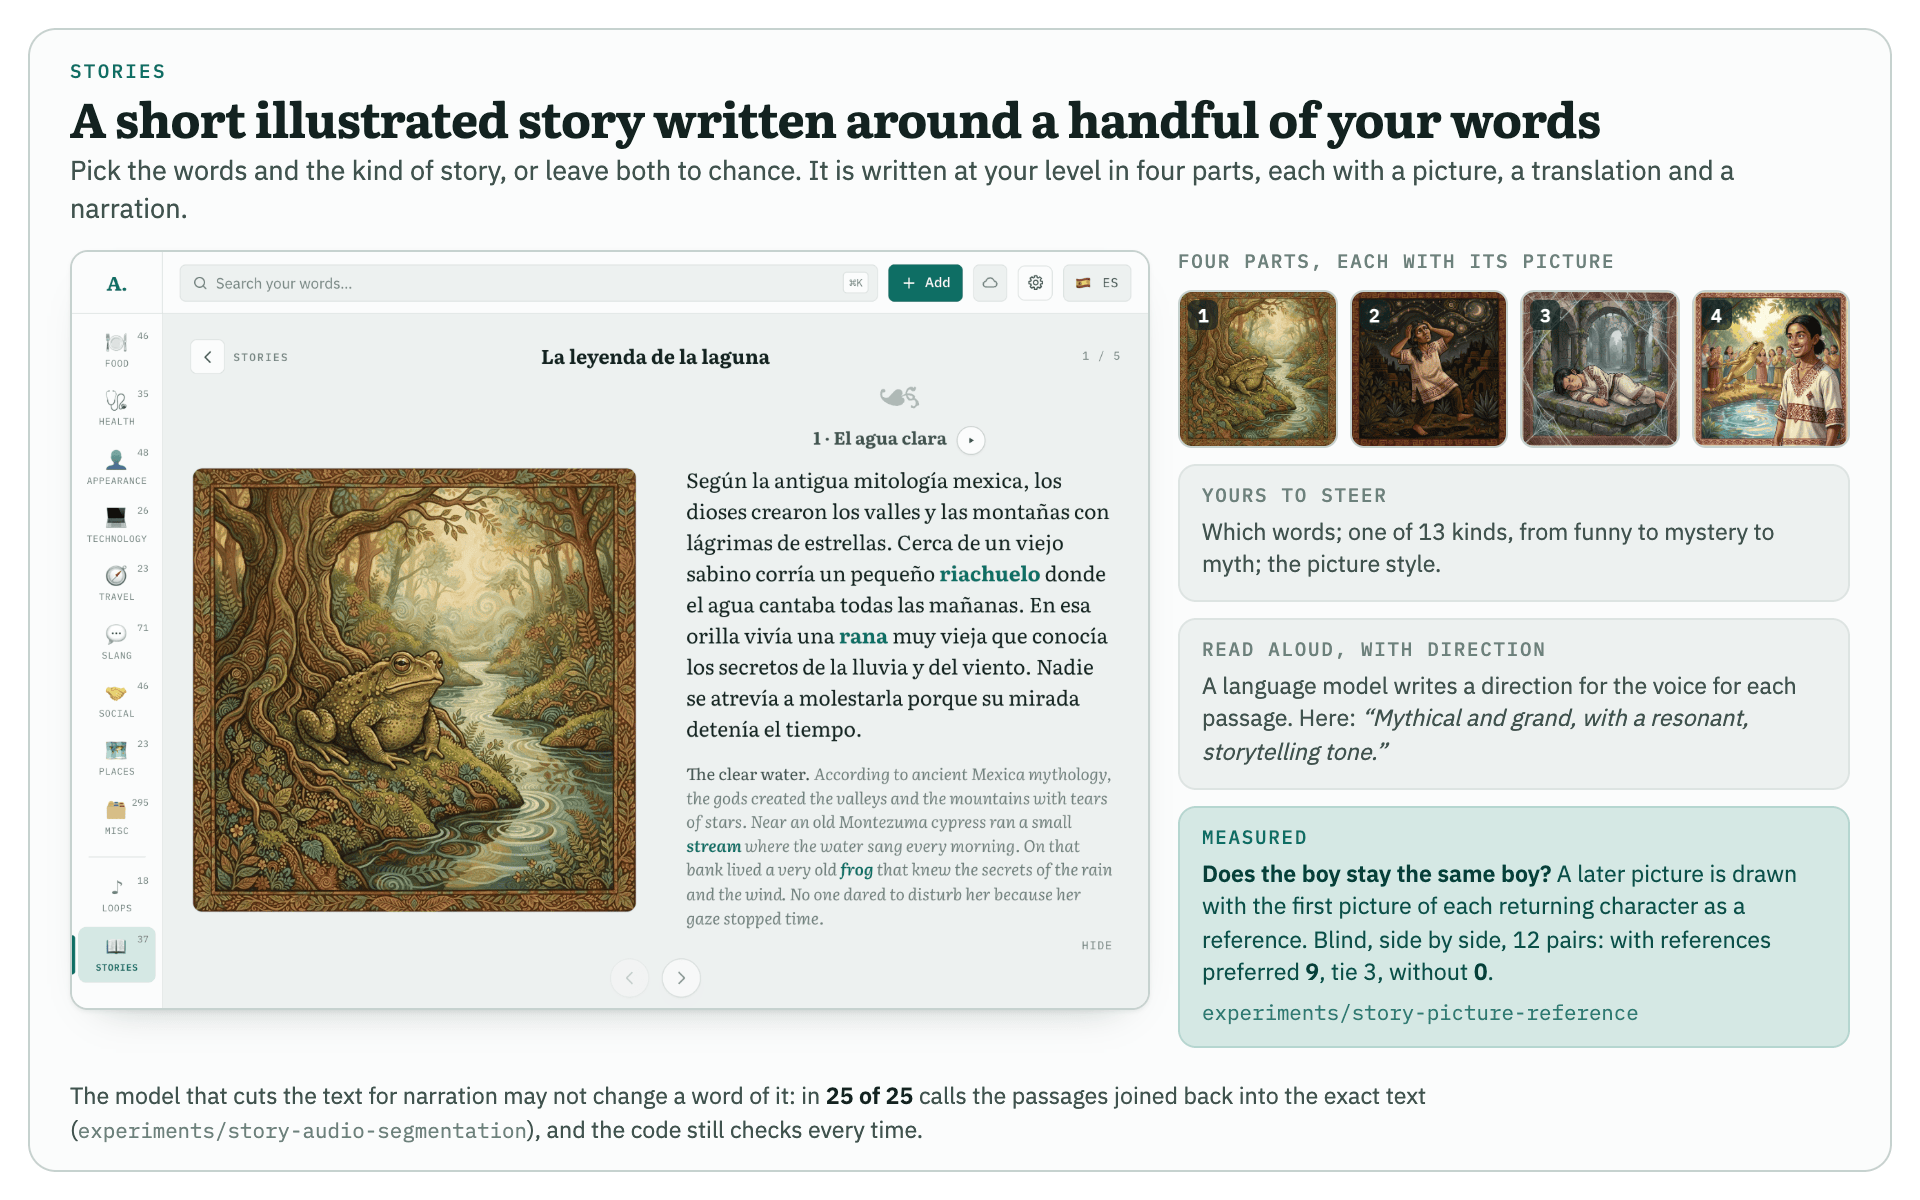
One part of an illustrated story written around the learner's words, and the story's four pictures.
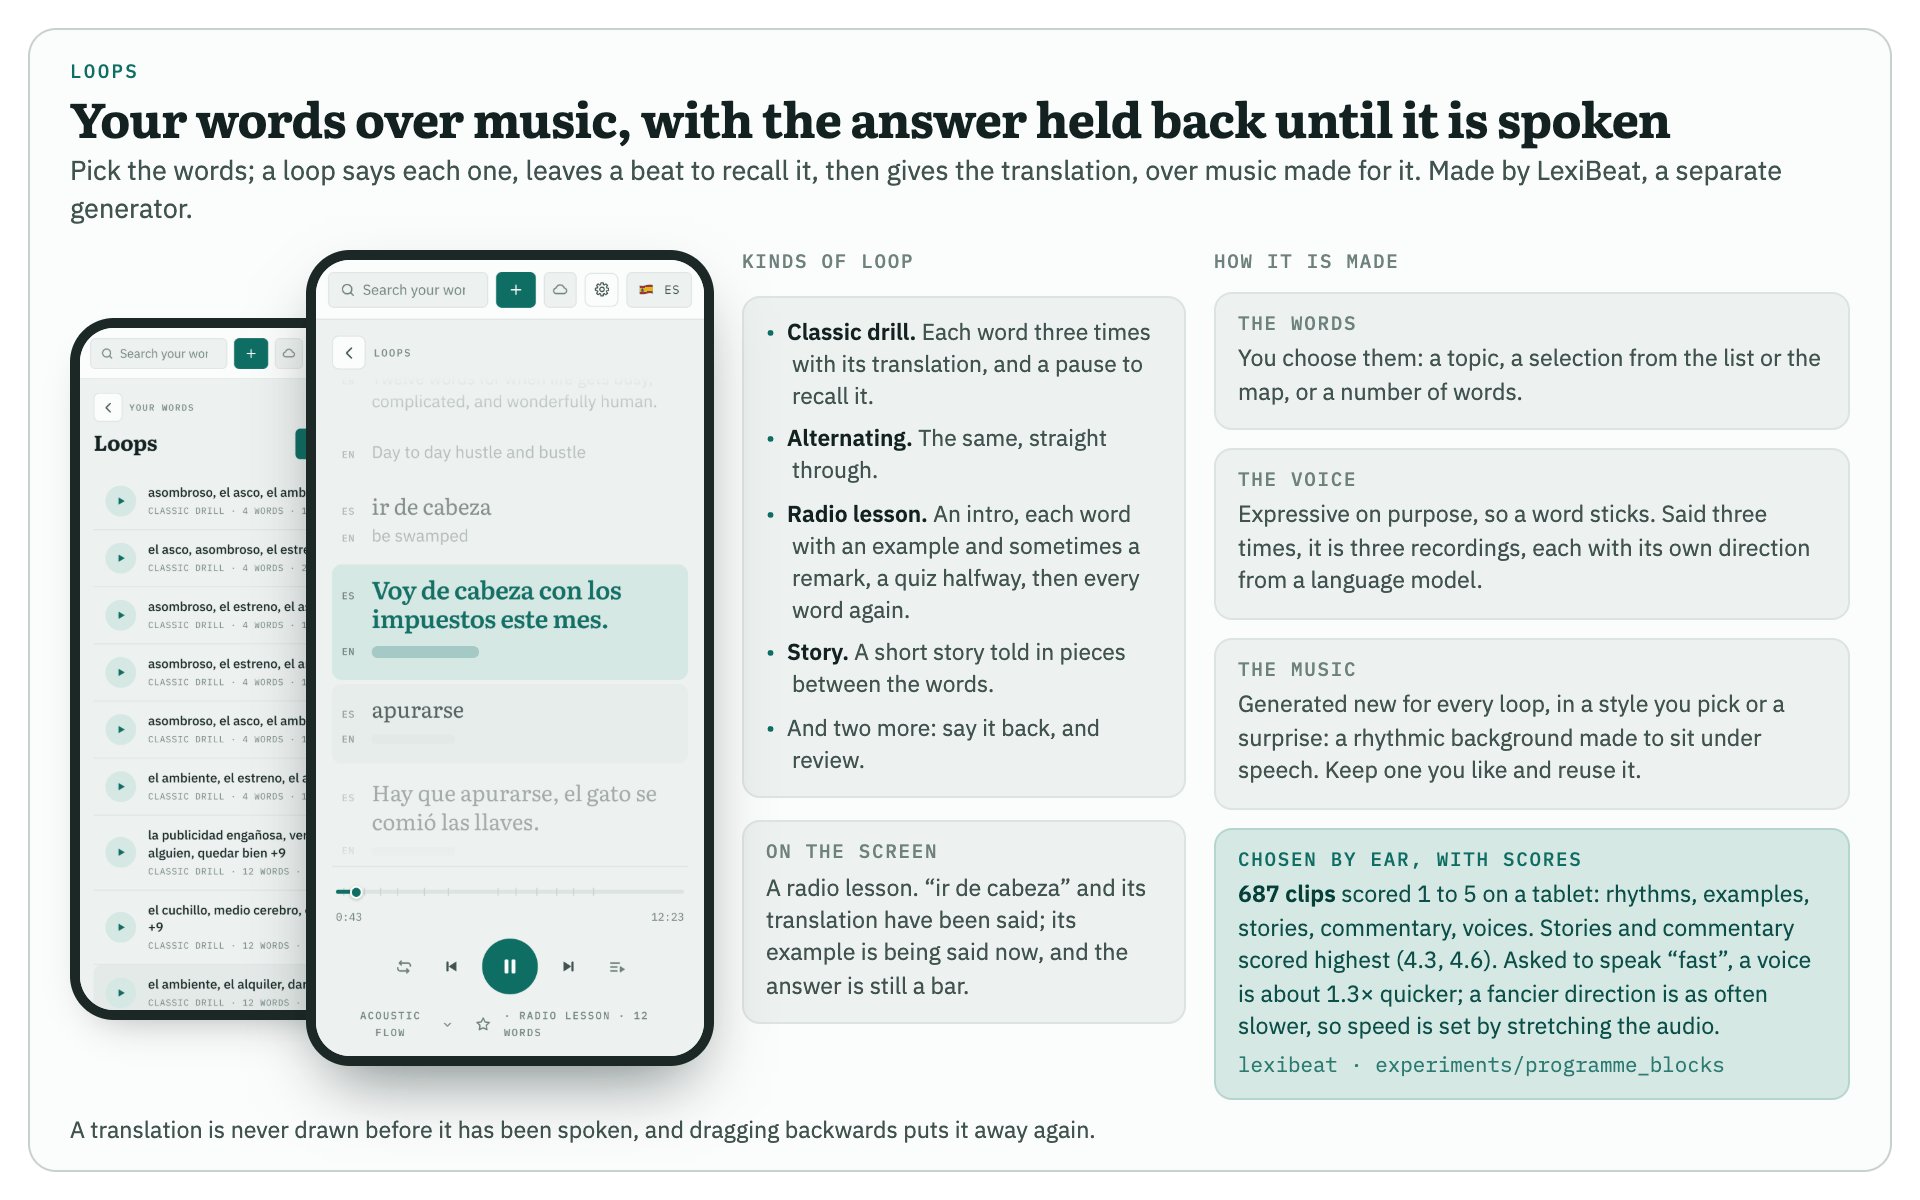
An audio loop playing on a phone, the translation held back until it is spoken.
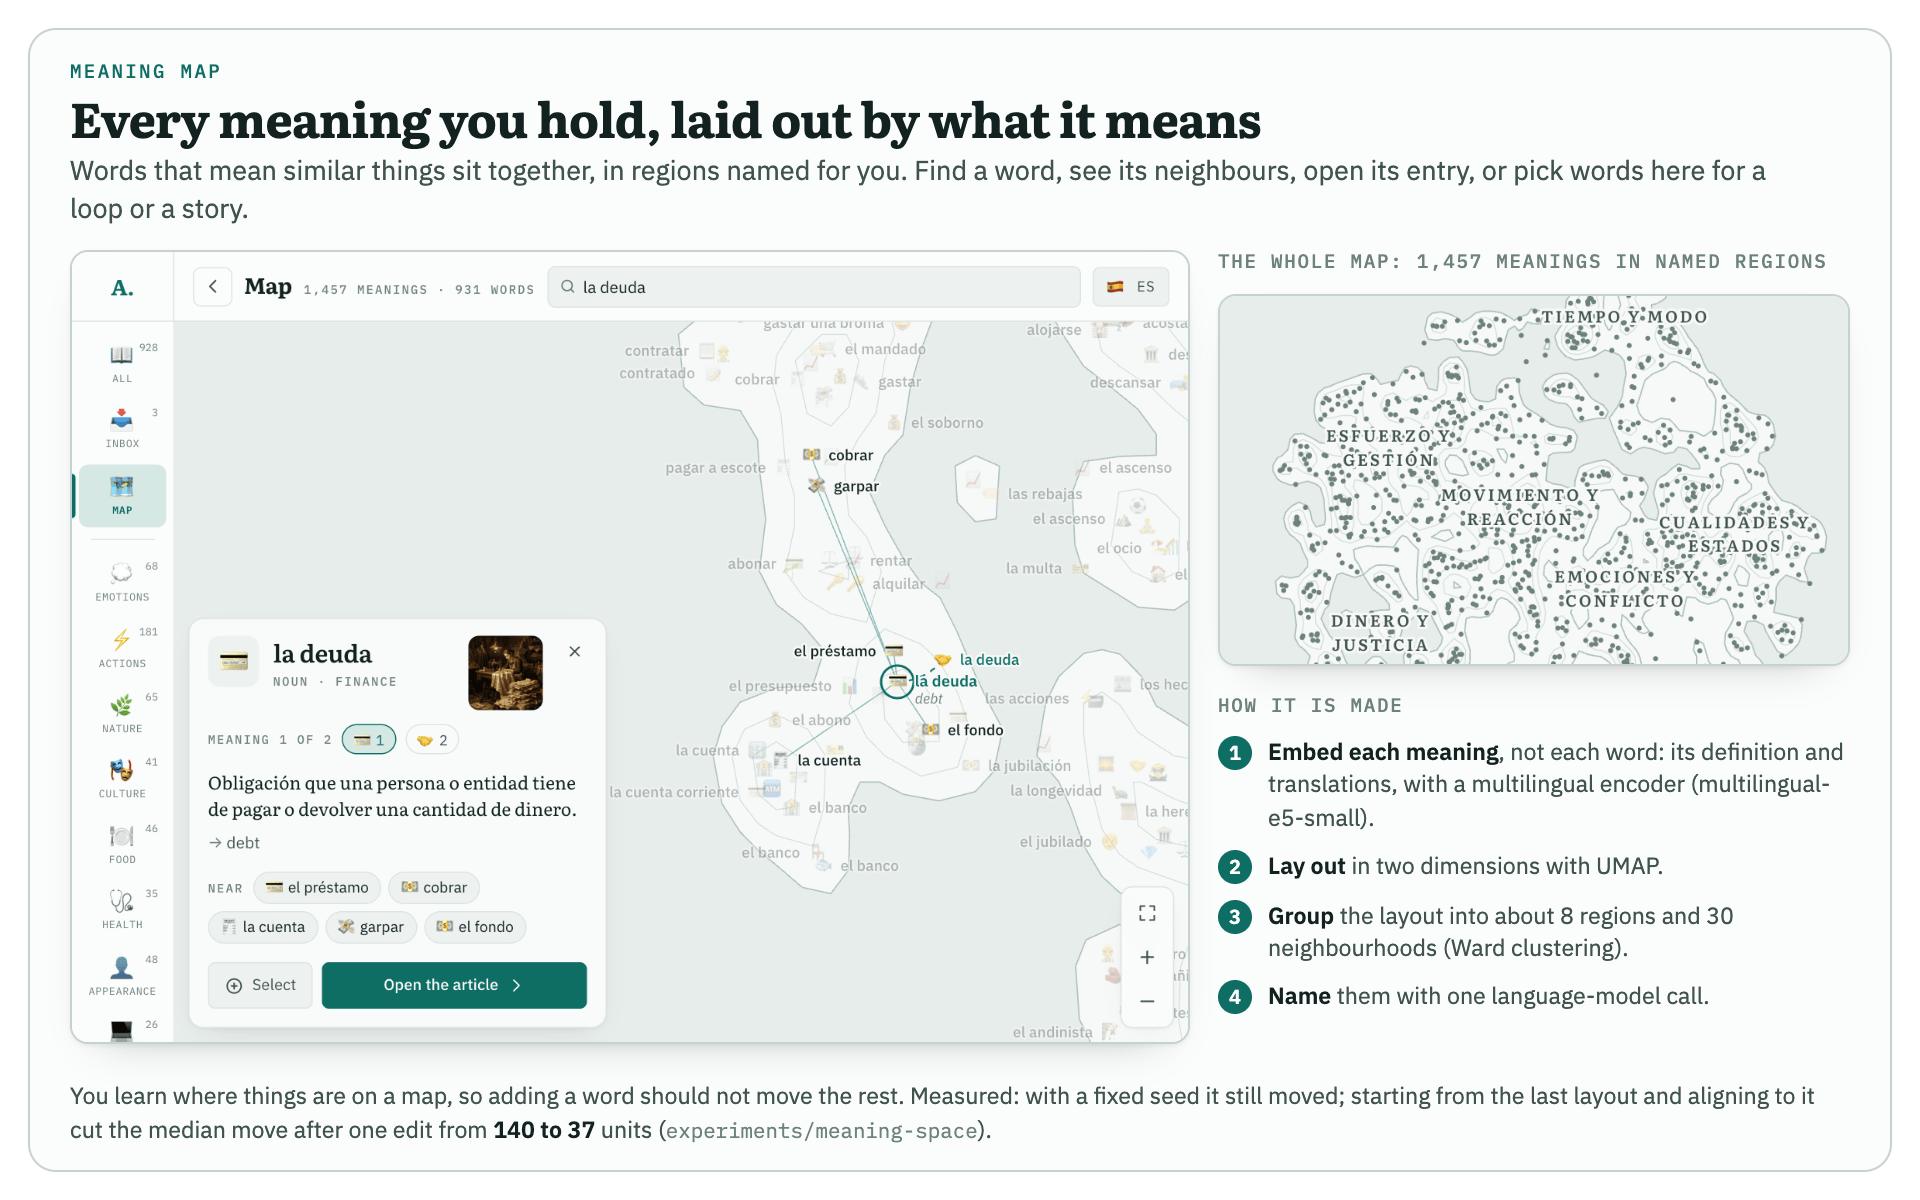
The map of 1,457 meanings, zoomed in on one word and its neighbours.
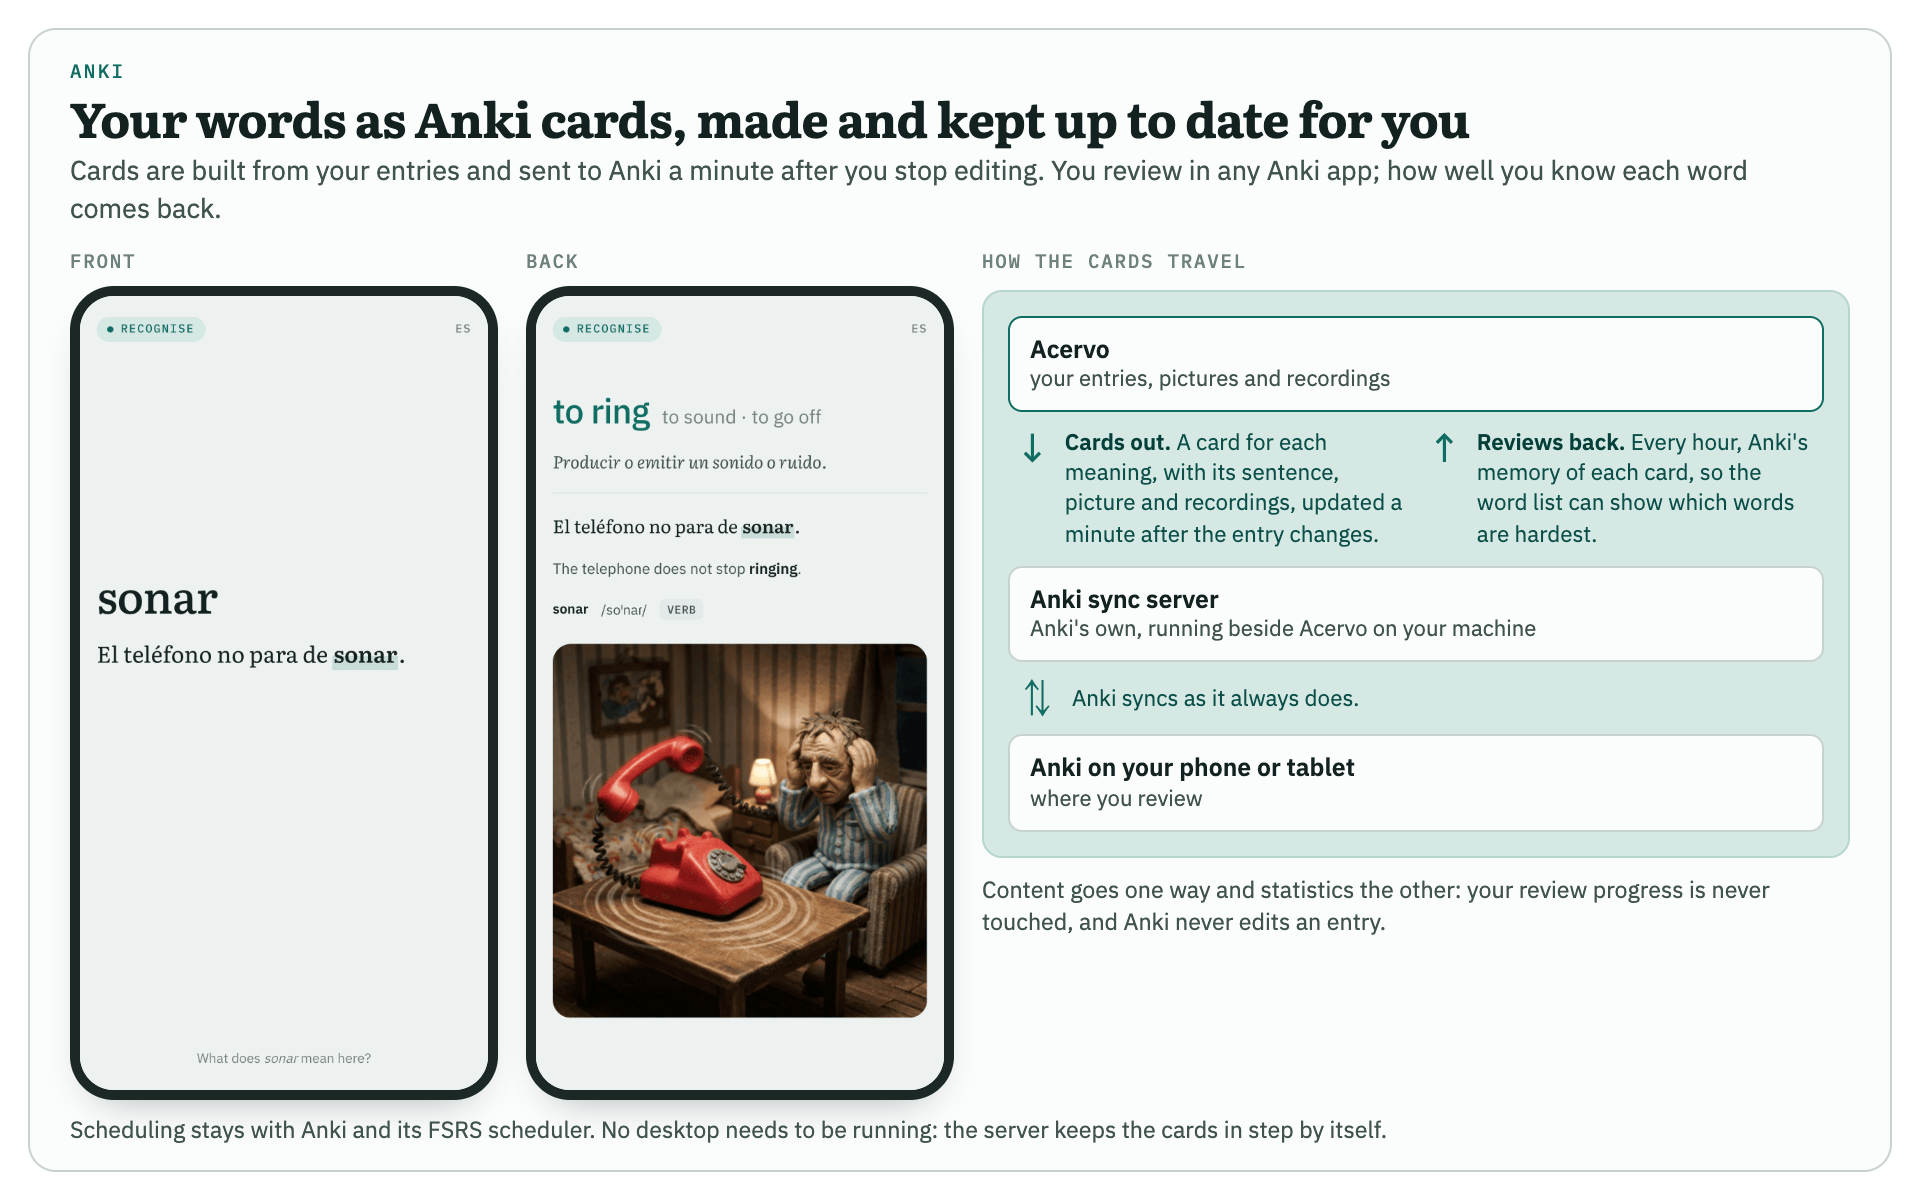
One Anki card built from an entry, and how cards go out and review state comes back.
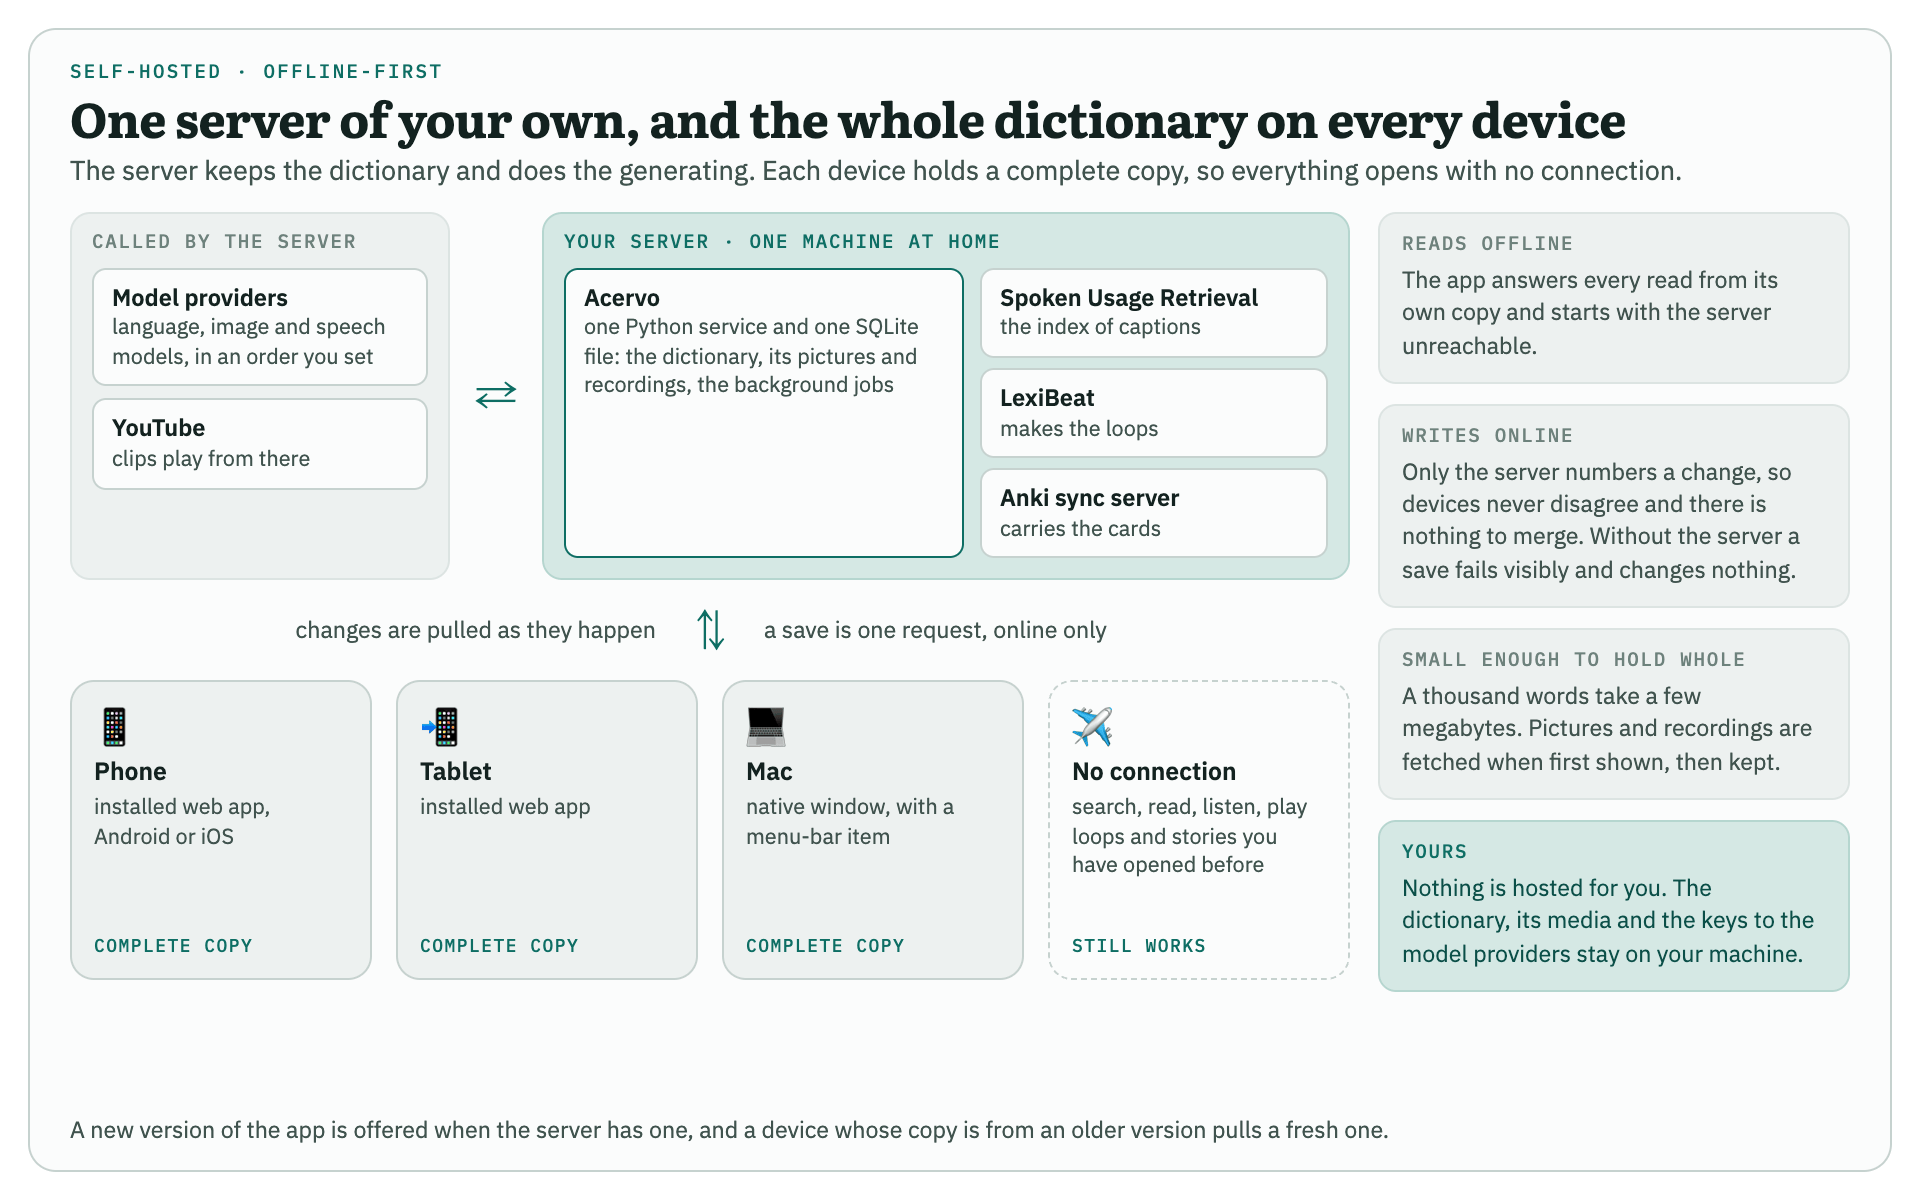
One self-hosted server, and a complete copy of the dictionary on every device.
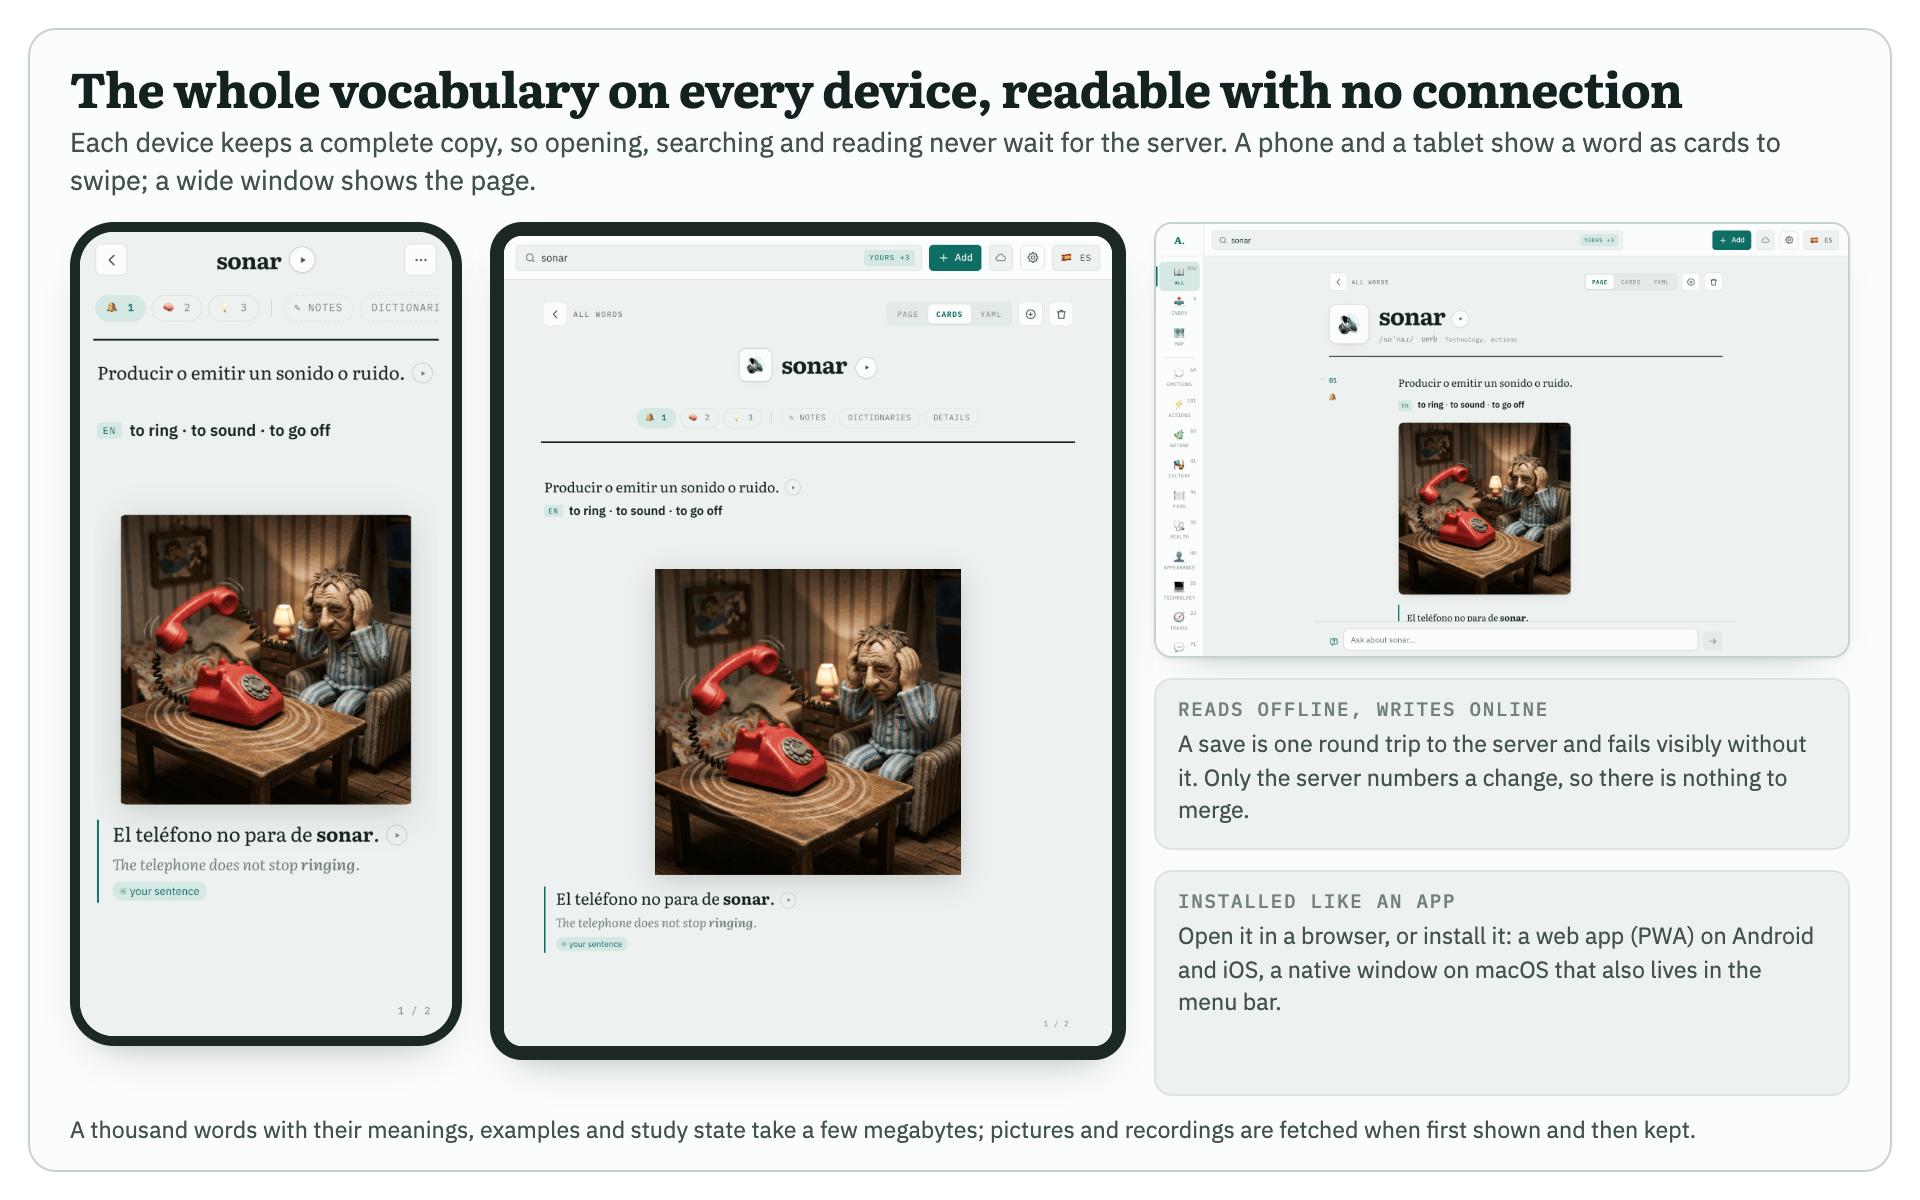
The same word on a phone, a tablet and a desktop, each holding the whole vocabulary offline.
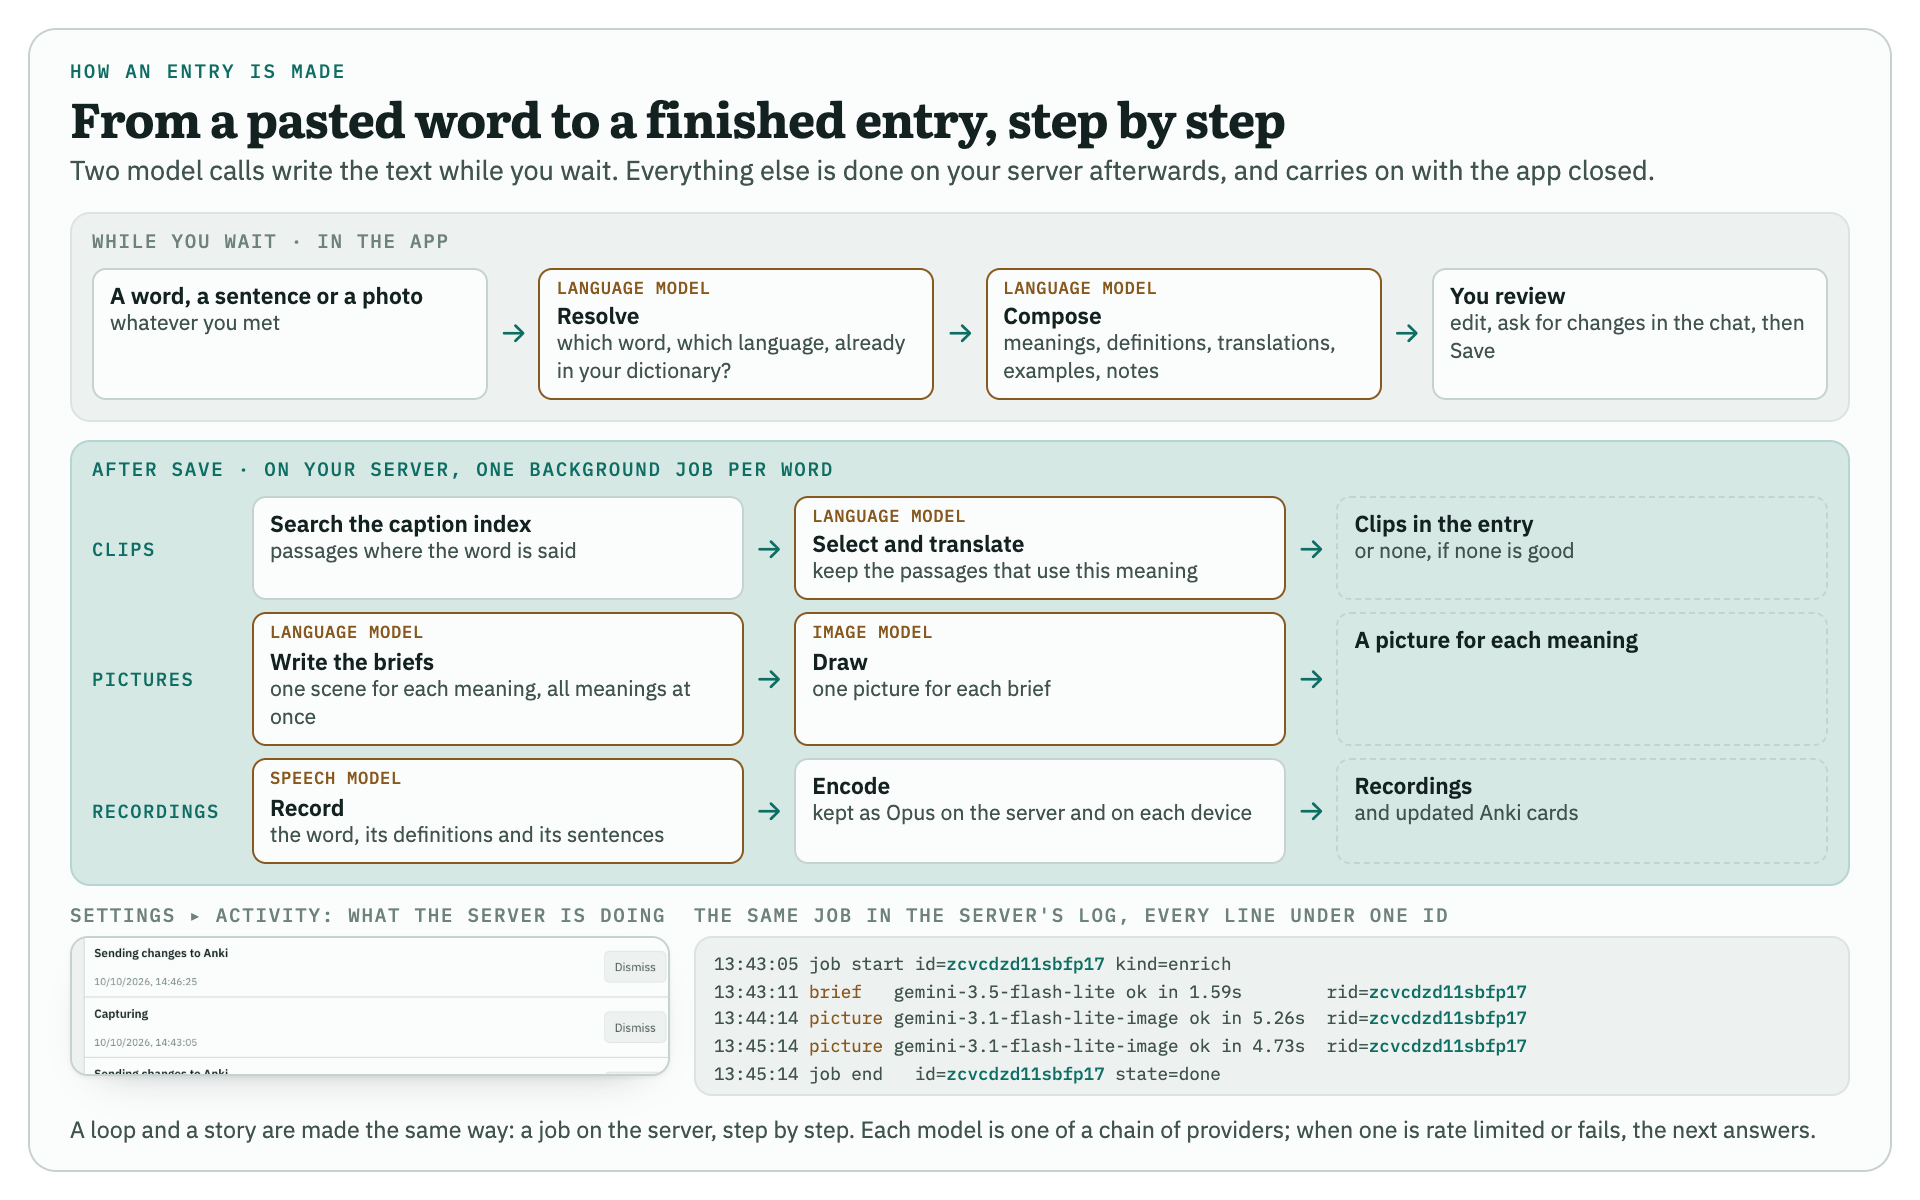
How an entry is made, from two model calls while you wait to the background job on the server.
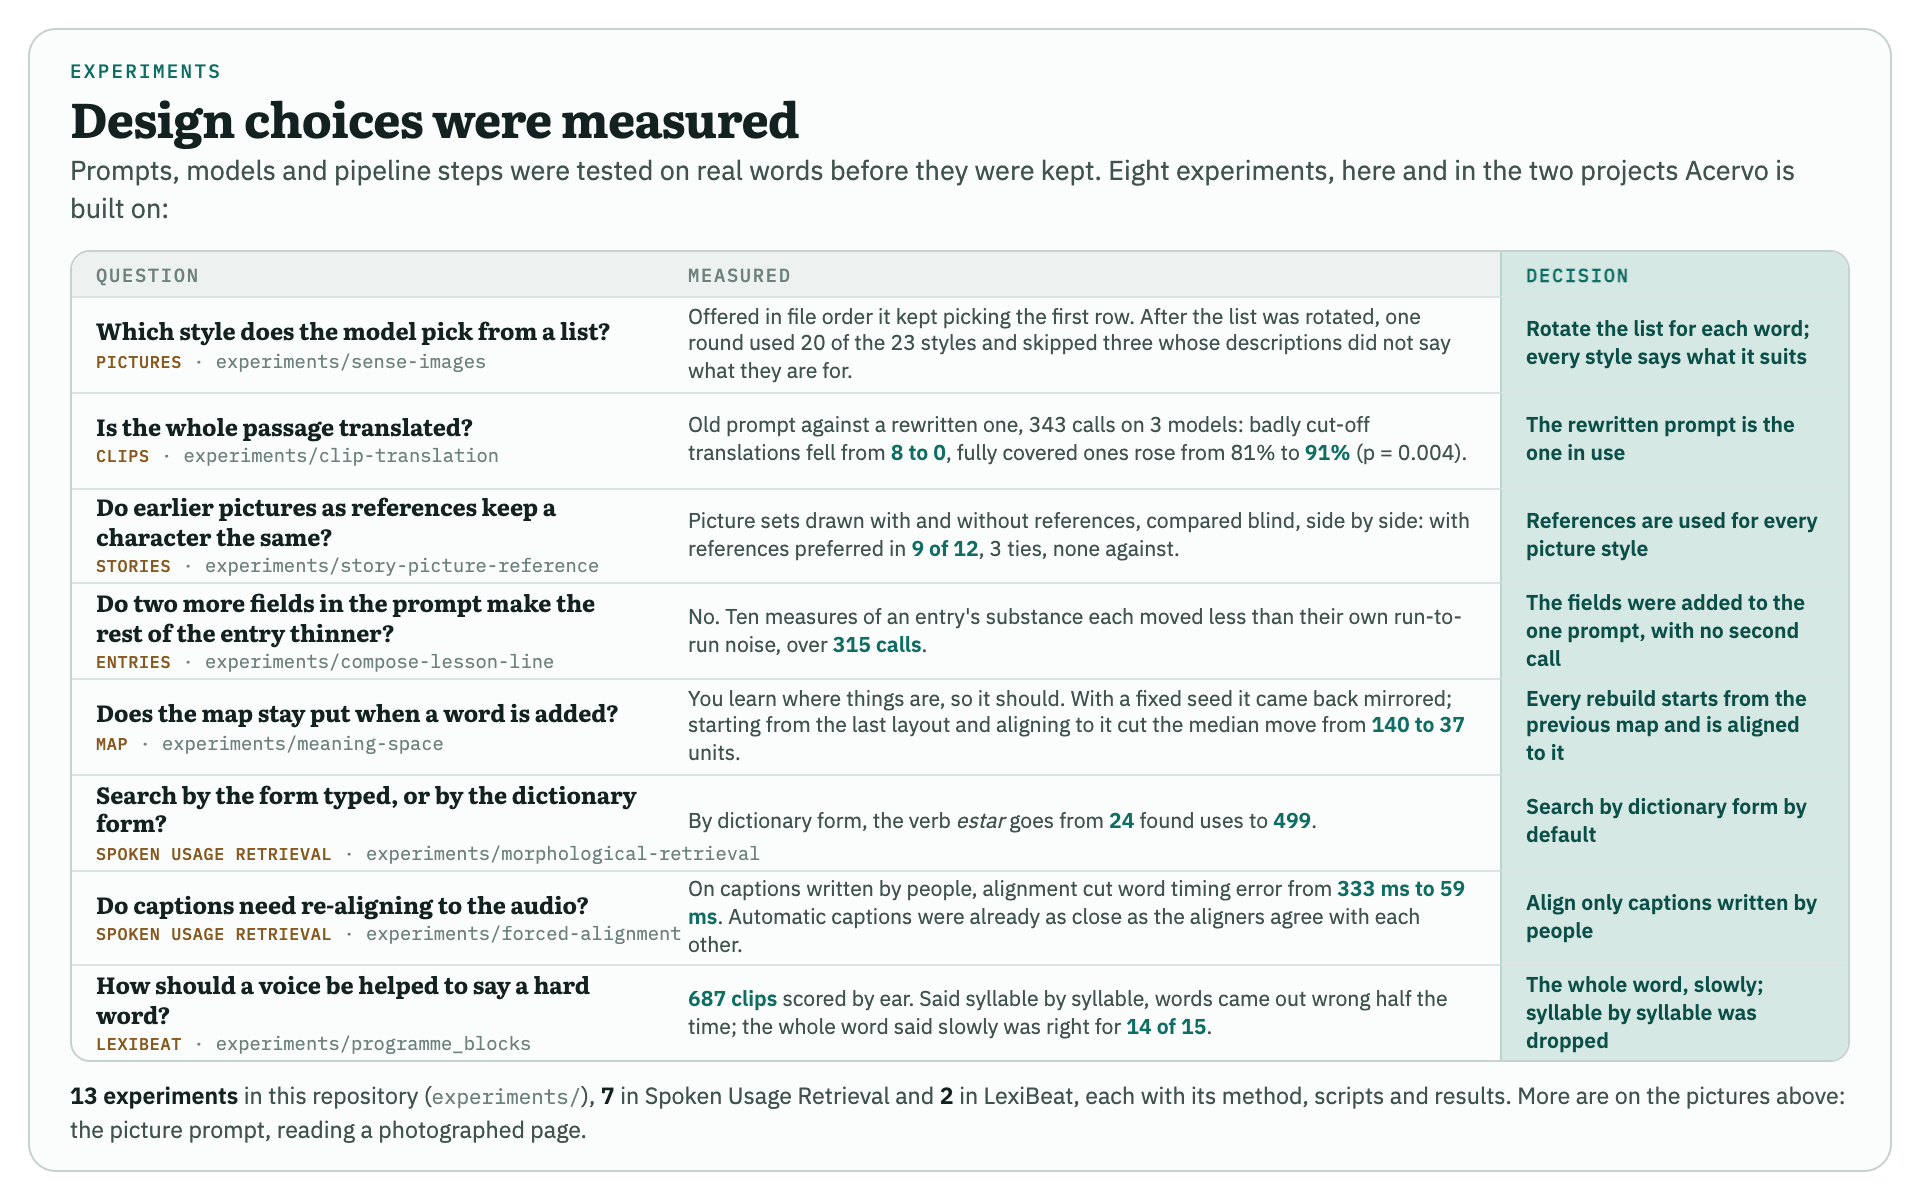
Eight experiments behind the design, each with what was measured and what was decided.
  • llm
  • language learning
  • dictionary
  • multimodal
  • llm evaluation
  • text to speech
  • image generation
  • offline first
  • self hosted

LexiBeat

active

Makes audio programmes that help you learn new words. Given a handful of words, a language model writes the programme: a radio-style lesson, a story, or a plain drill of each word and its translation. The programme is then spoken over calm generated music. Its design was settled by experiments: blind A/B listening to build the sound library, how to compose a programme, and which speech models to use.

Radio format, news-style retrieval practice with shorter segments. Turn the sound on.
Story format, a narrative with longer connected phrases.
Spanish to English, 12 words and phrases over a generated rhythmic backing track.
  • language learning
  • audio
  • text to speech
  • procedural music
  • dsp
  • python
Implemented from scratch

2 projects

Foundation models experiments
Six blocks of implementations trained end to end: representation learning, neural search, transformers and vision transformers, multimodal captioning, audio models with efficient fine-tuning, and RLHF with PPO and preference optimisation. Begun in workshops at the Machine Learning Institute and extended independently.
  • pytorch
  • deep learning
  • transformers
  • vision transformer
  • information retrieval
  • multimodal
  • rlhf
  • from scratch

Deep RL notebooks

active

The hands-on units of the Hugging Face Deep RL course, reworked instead of copied: current library versions, the workarounds removed, and the common code moved into a small tested library. So far PPO on CartPole and Lunar Lander, and Q-learning on Frozen Lake.

  • reinforcement learning
  • deep reinforcement learning
  • pytorch
  • jupyter notebook

Tools and apps

8 projects

Lectern

active

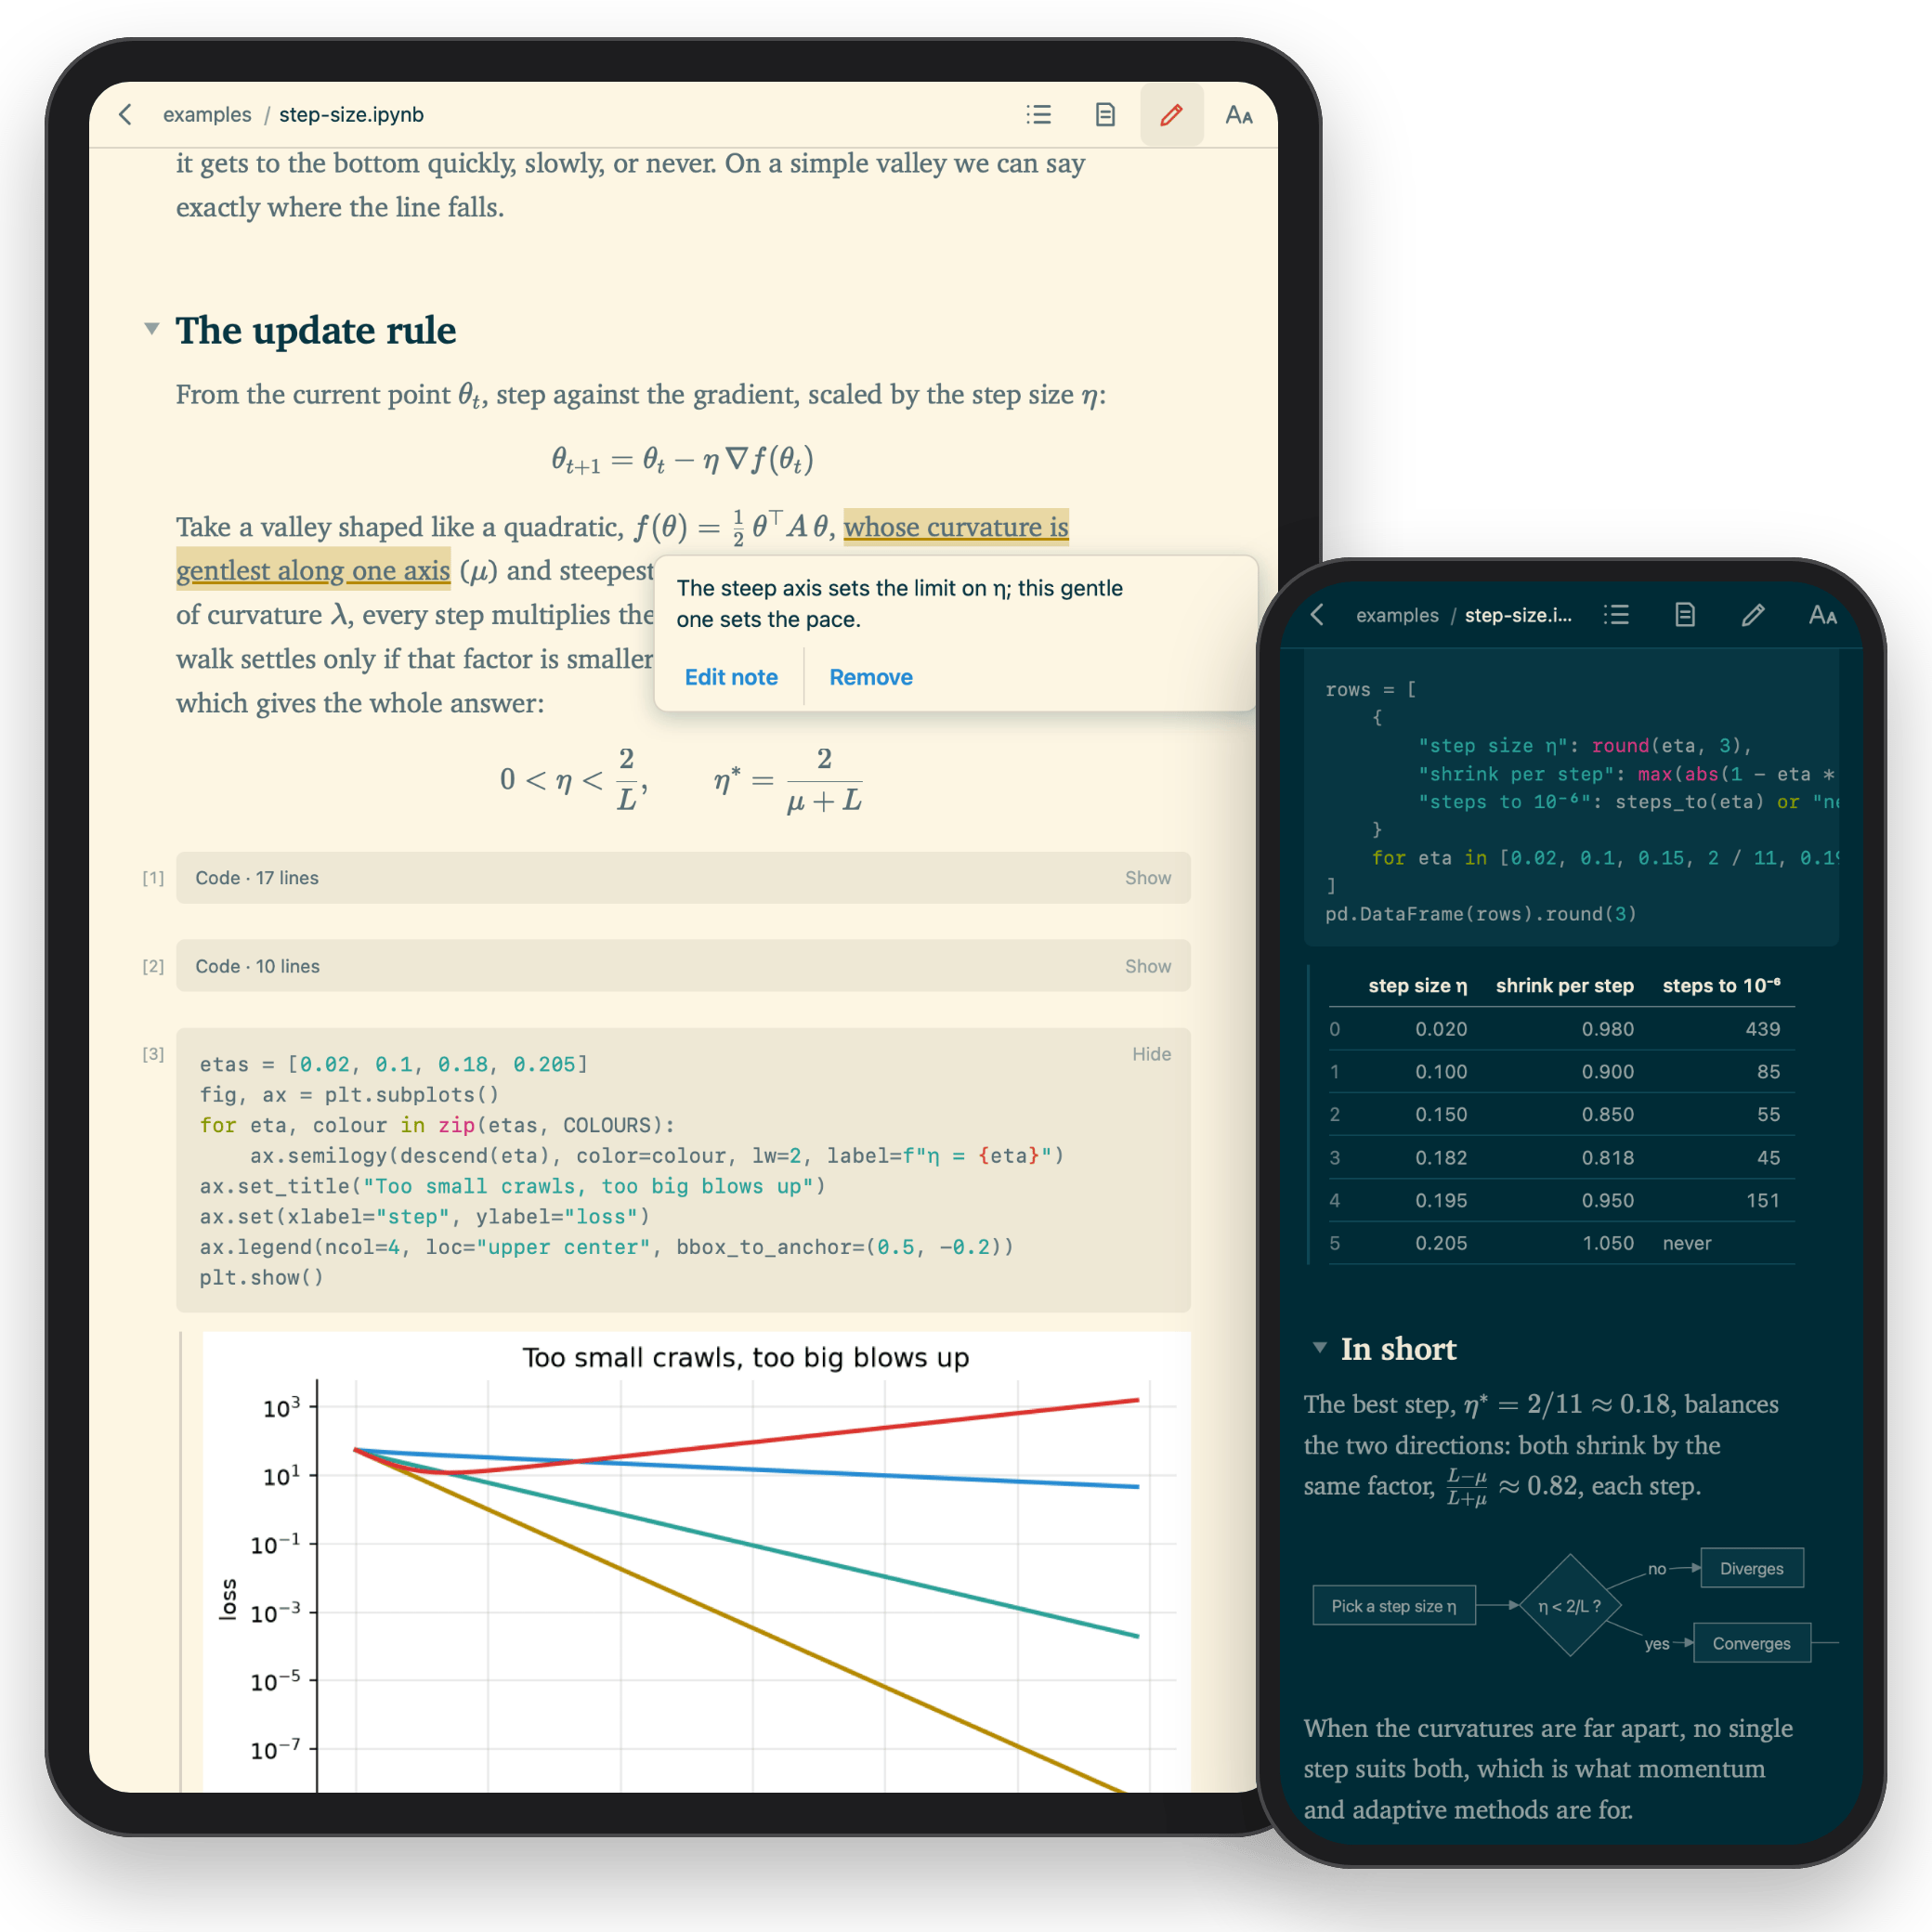
Read Jupyter notebooks and markdown on a tablet, a phone or an e-ink reader, and publish them as a website.

A notebook on an iPad in light colours and on a phone in dark, with typeset formulas, folded code, a plot and a note.

The Vim Wilds

active

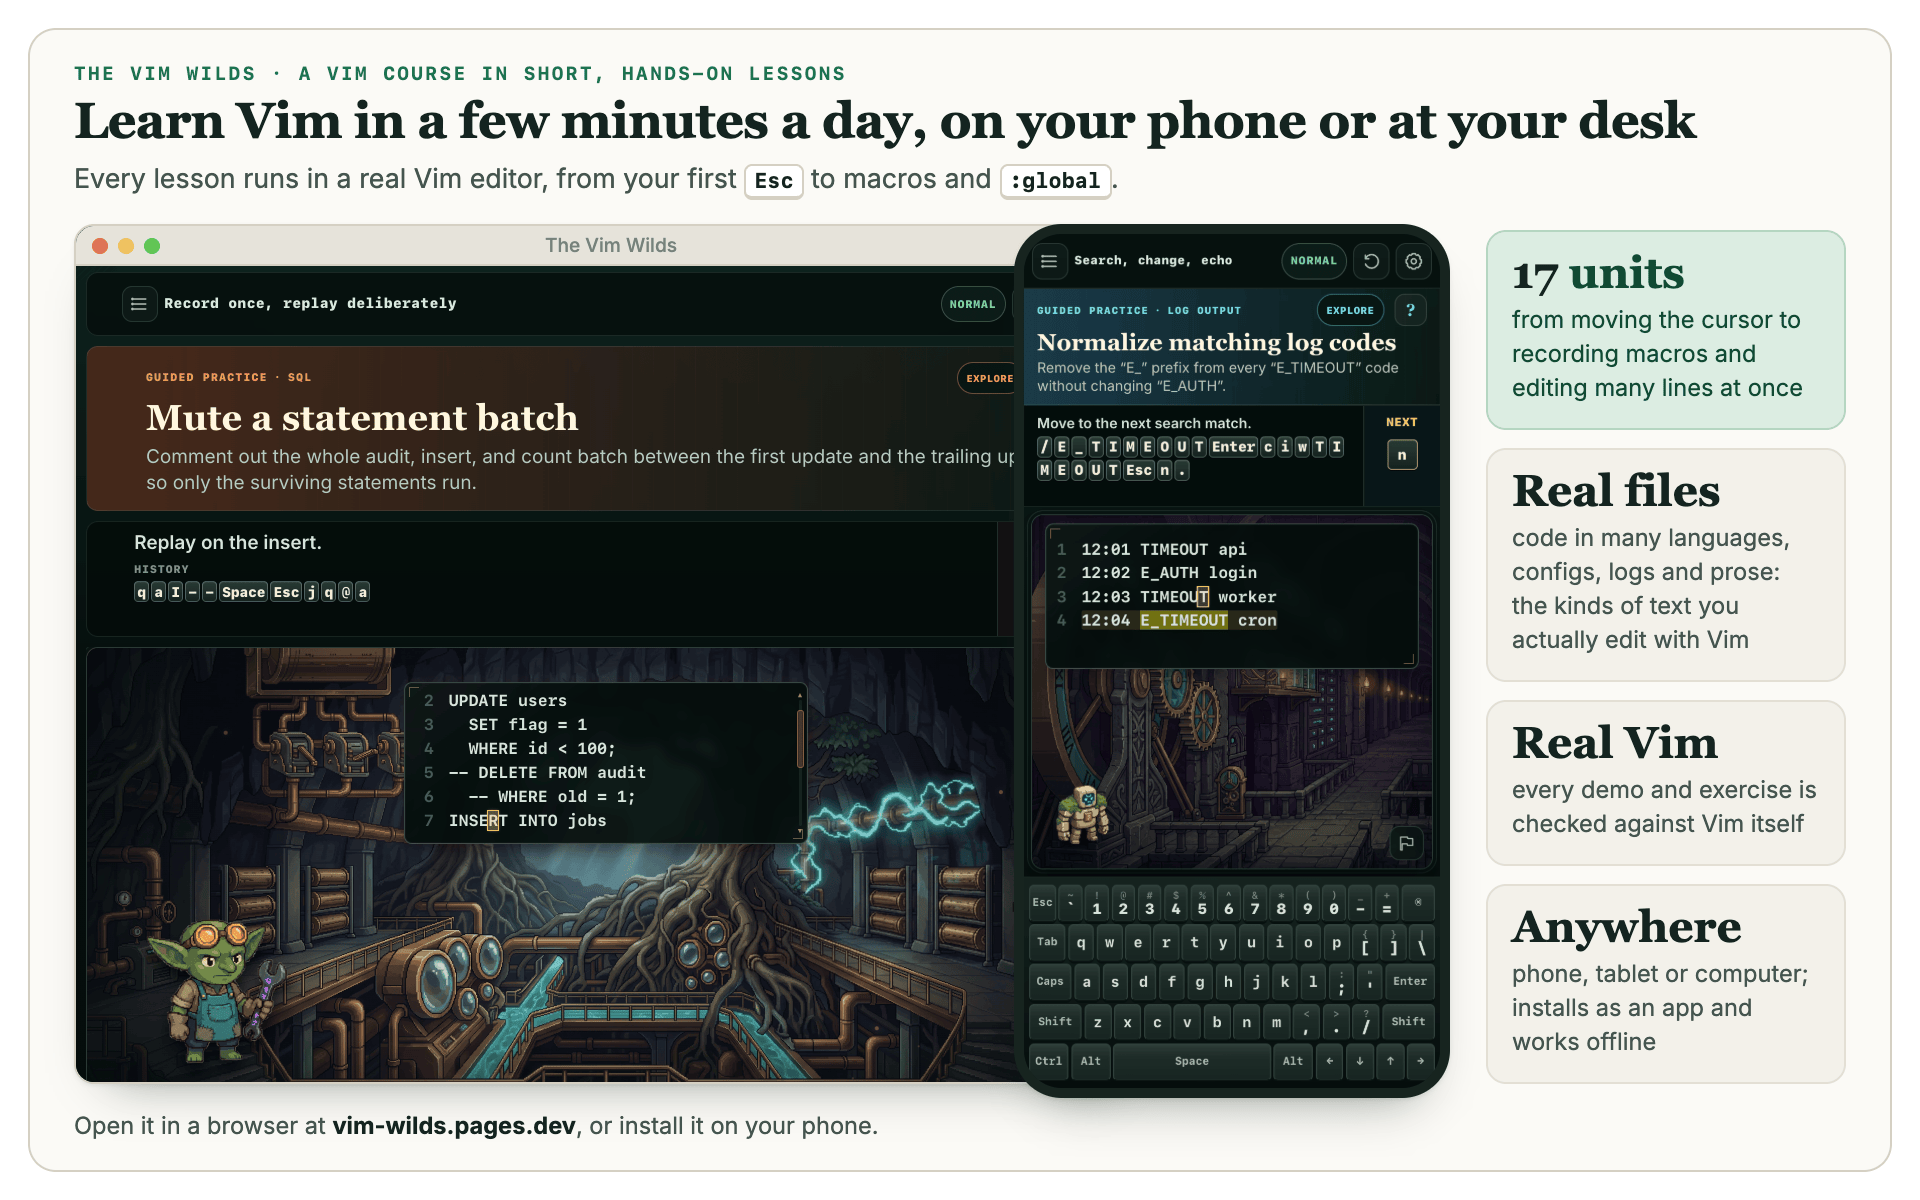
A Vim course in bite-sized lessons for your phone or your desk, from the first Esc to macros and :global, in a real Vim editor.

An exercise on a laptop and another on a phone, both in a real Vim editor.
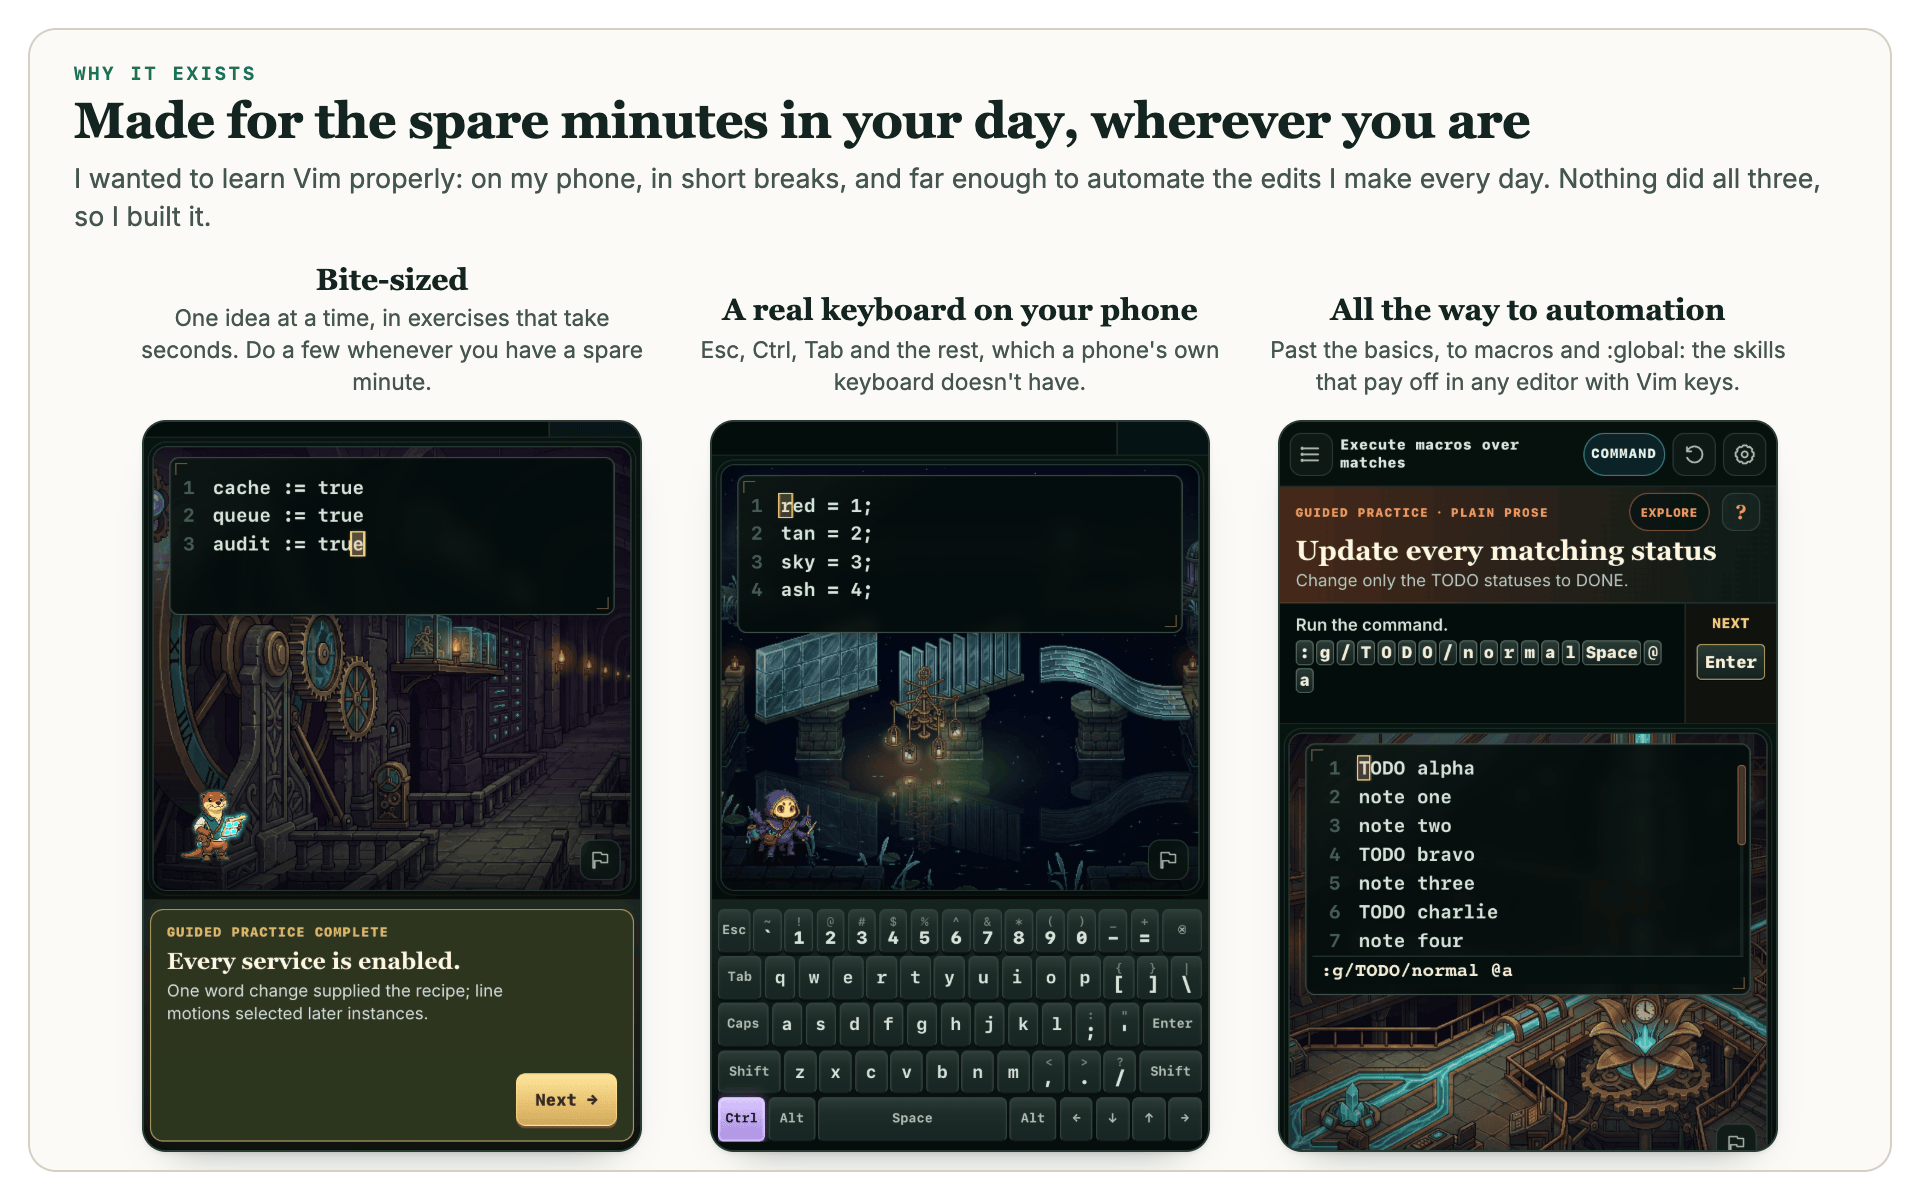
Short exercises, a real keyboard on the phone, and lessons that go all the way to automation.
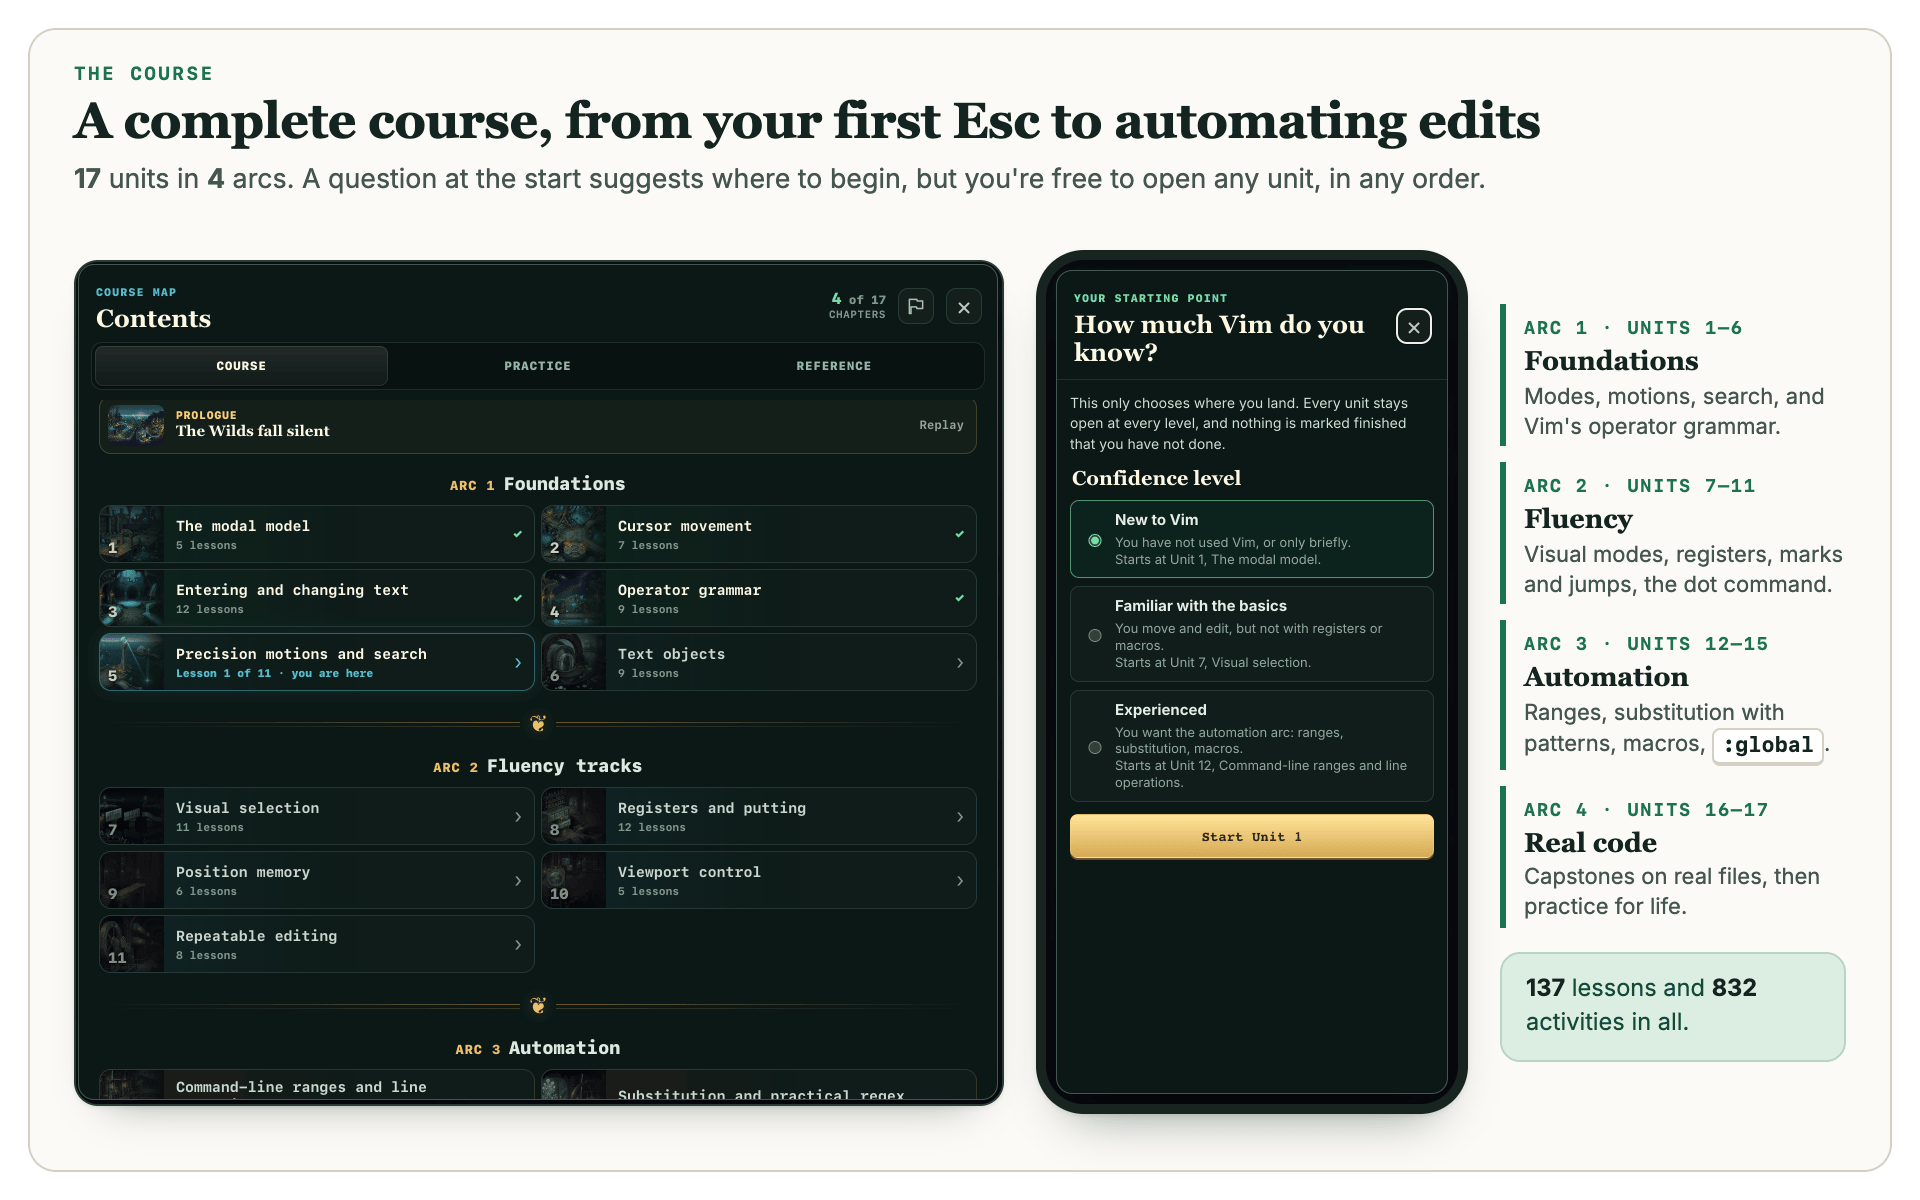
The course map, seventeen units in four arcs, and the one question that places you.
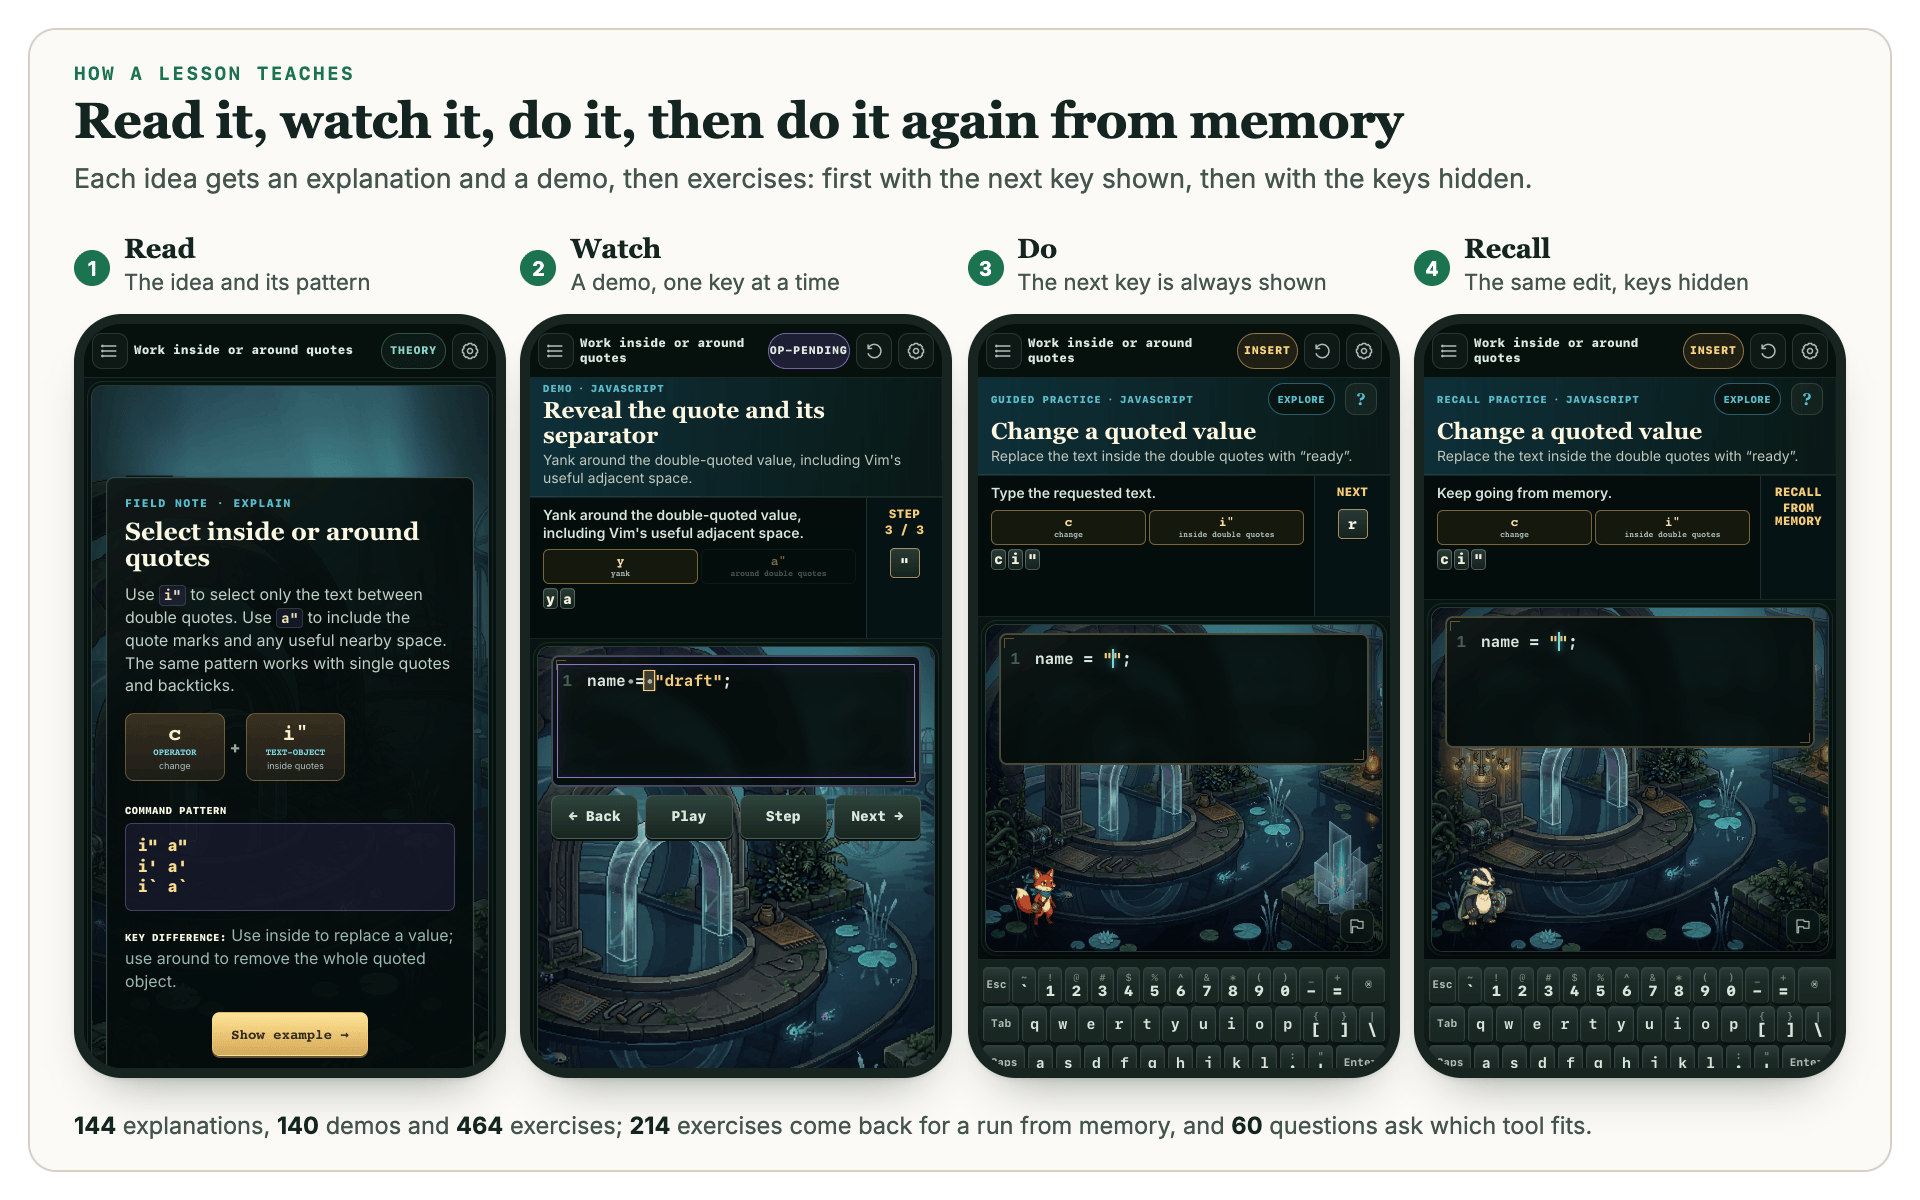
Each idea comes as an explanation and a demo, then the exercise with the next key shown, then the same from memory.
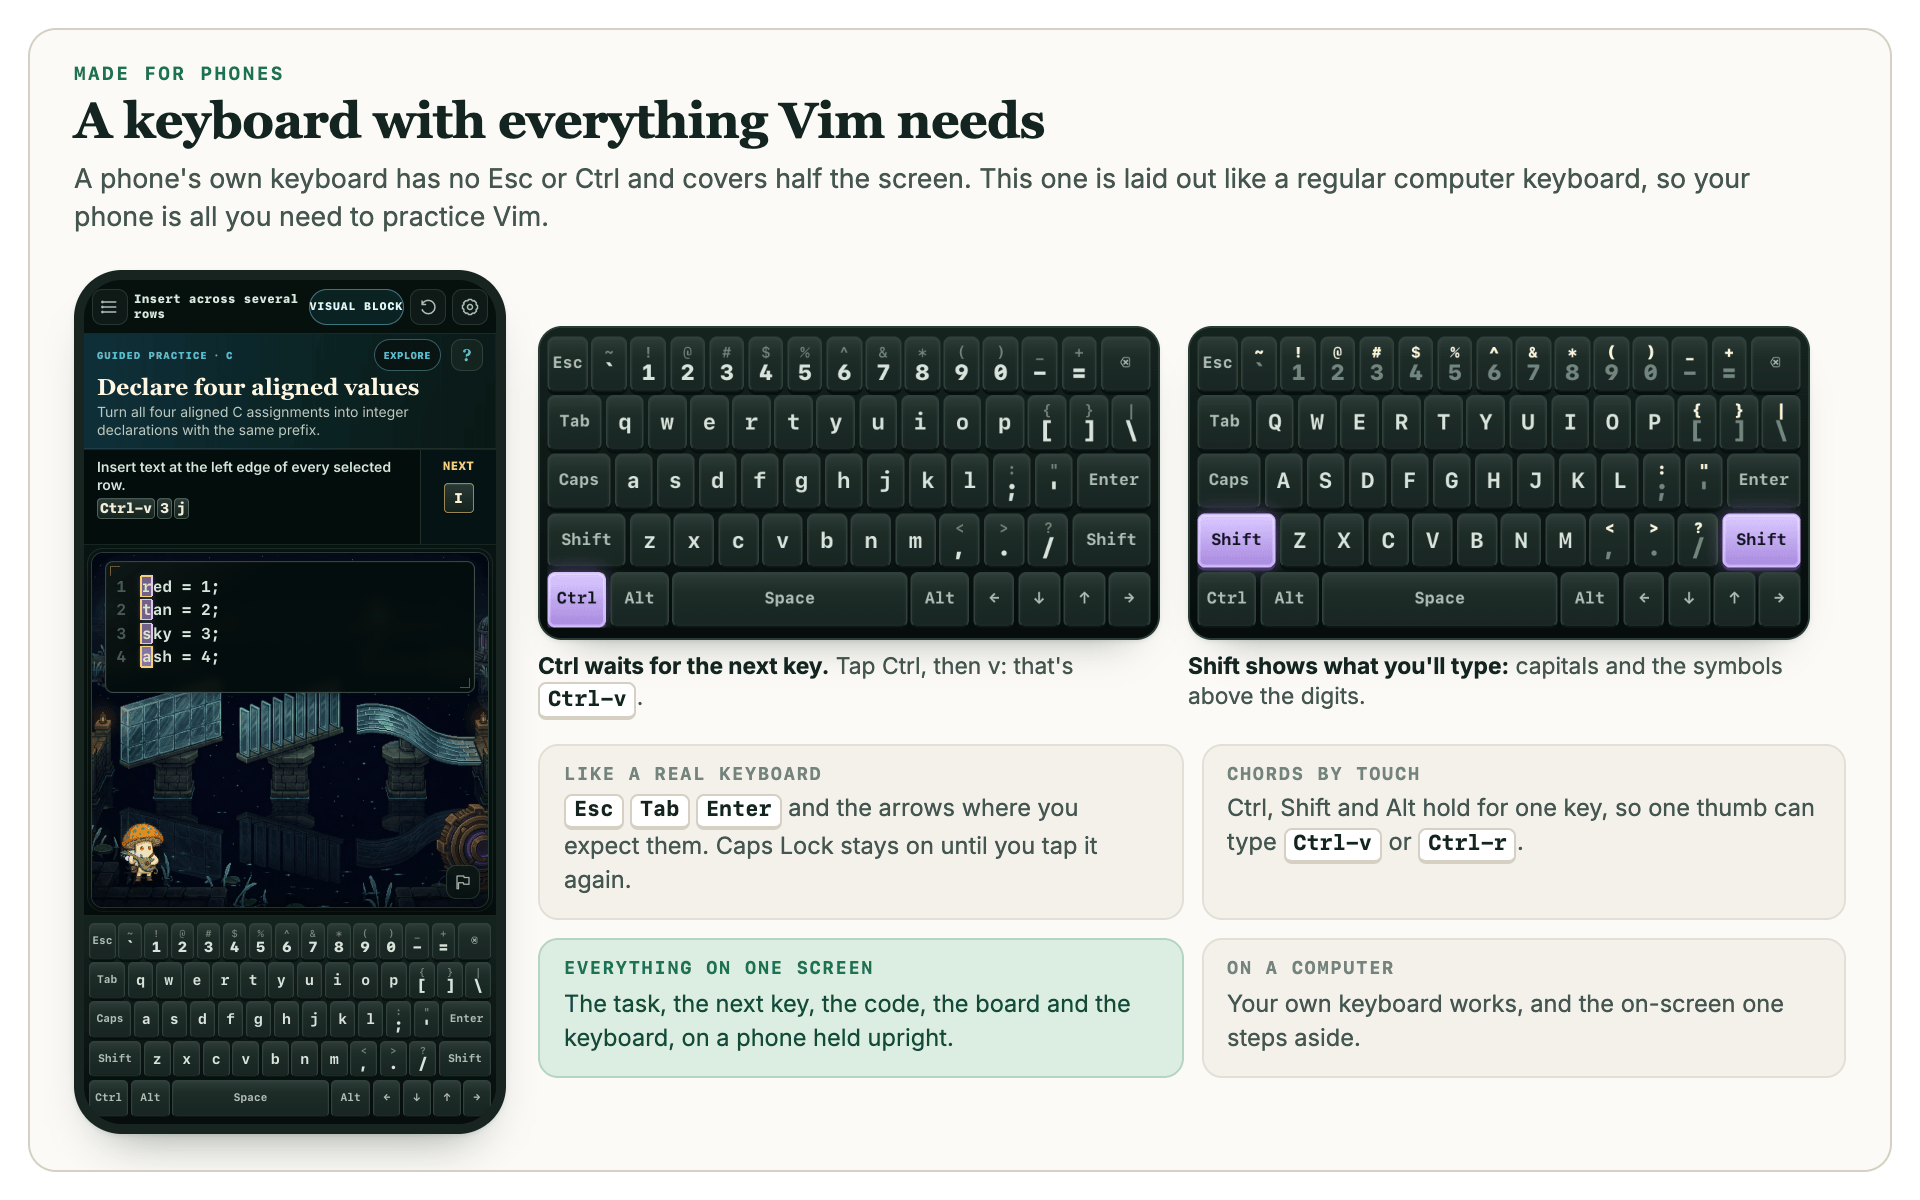
The on-screen keyboard, with Esc, Ctrl and modifiers that wait for the next key.
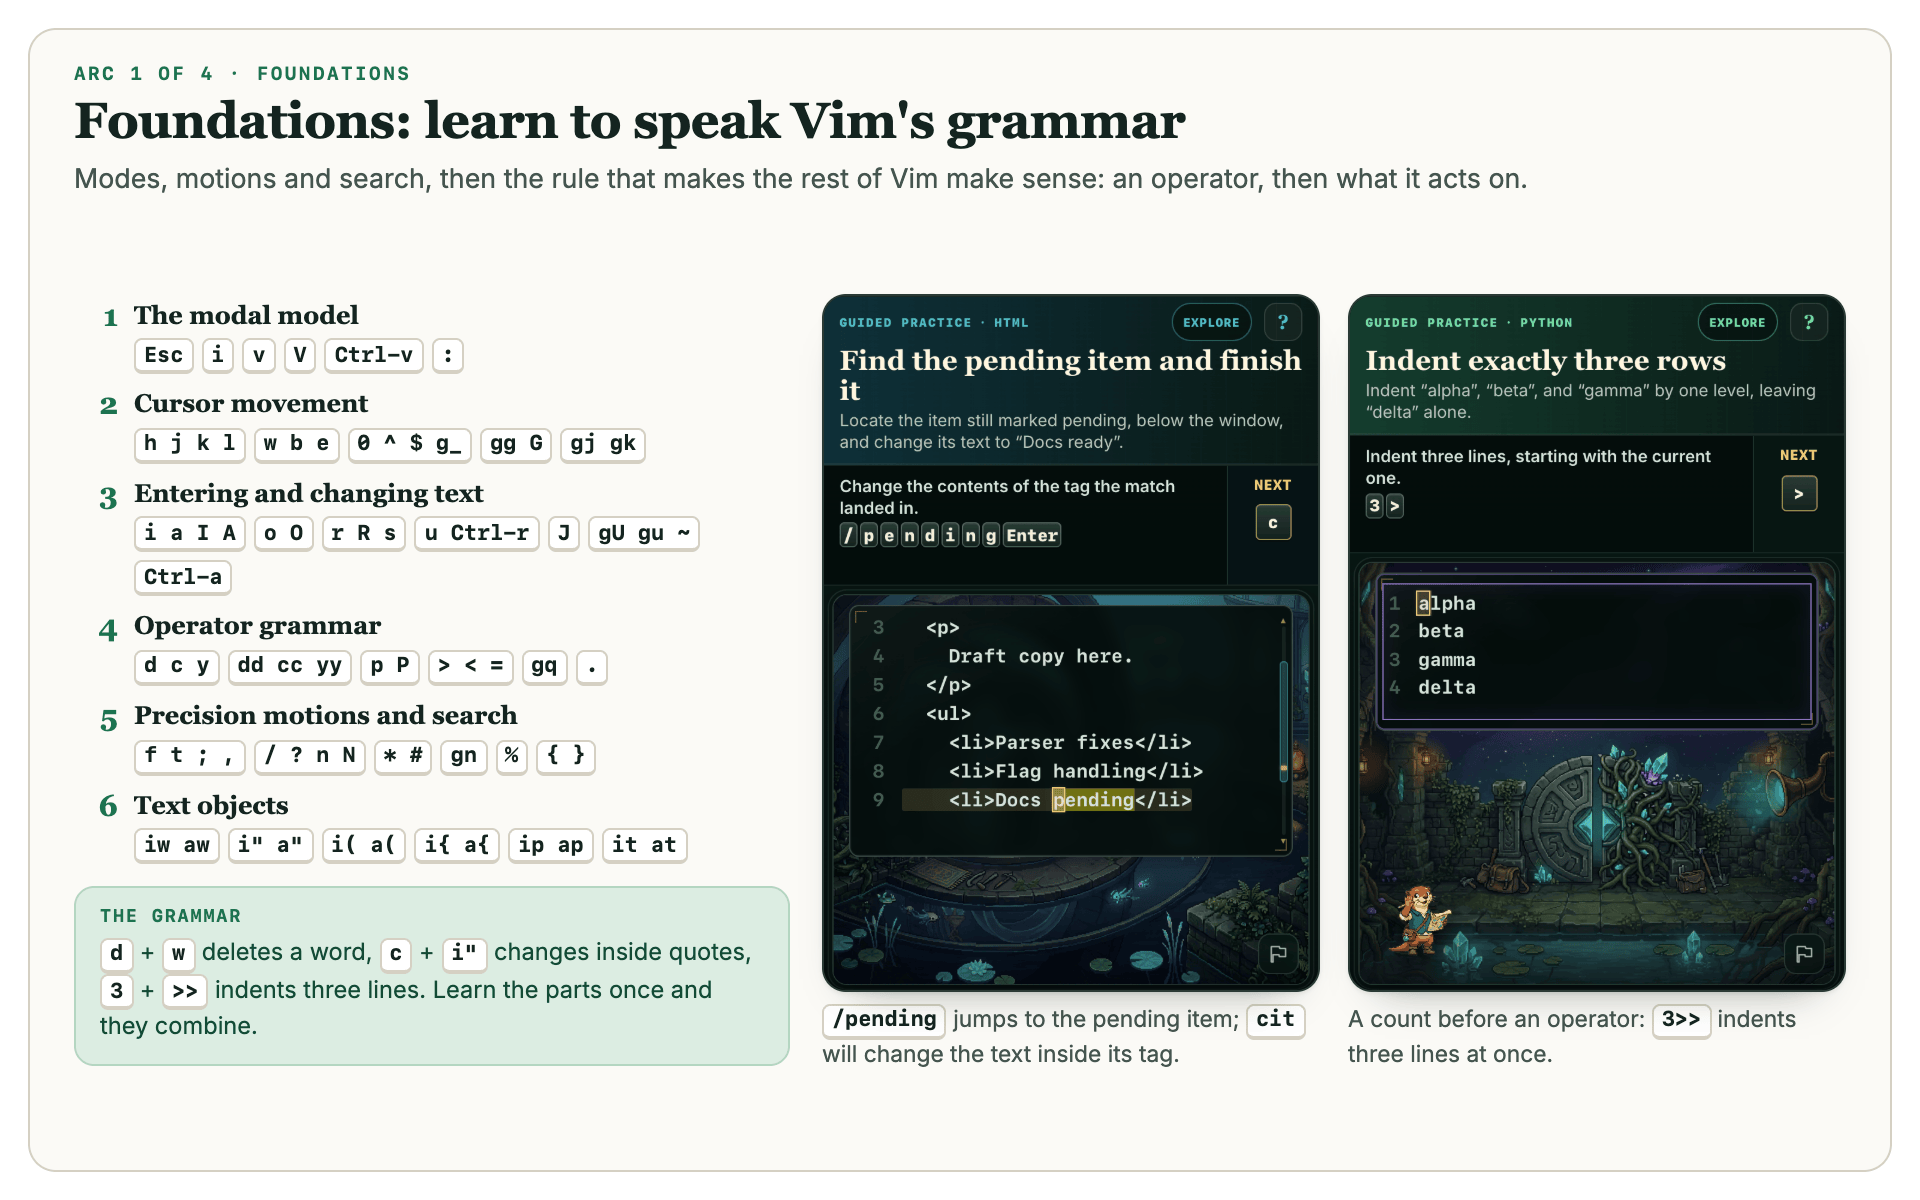
Foundations, the first arc, covers modes, motions, search, operators and text objects.
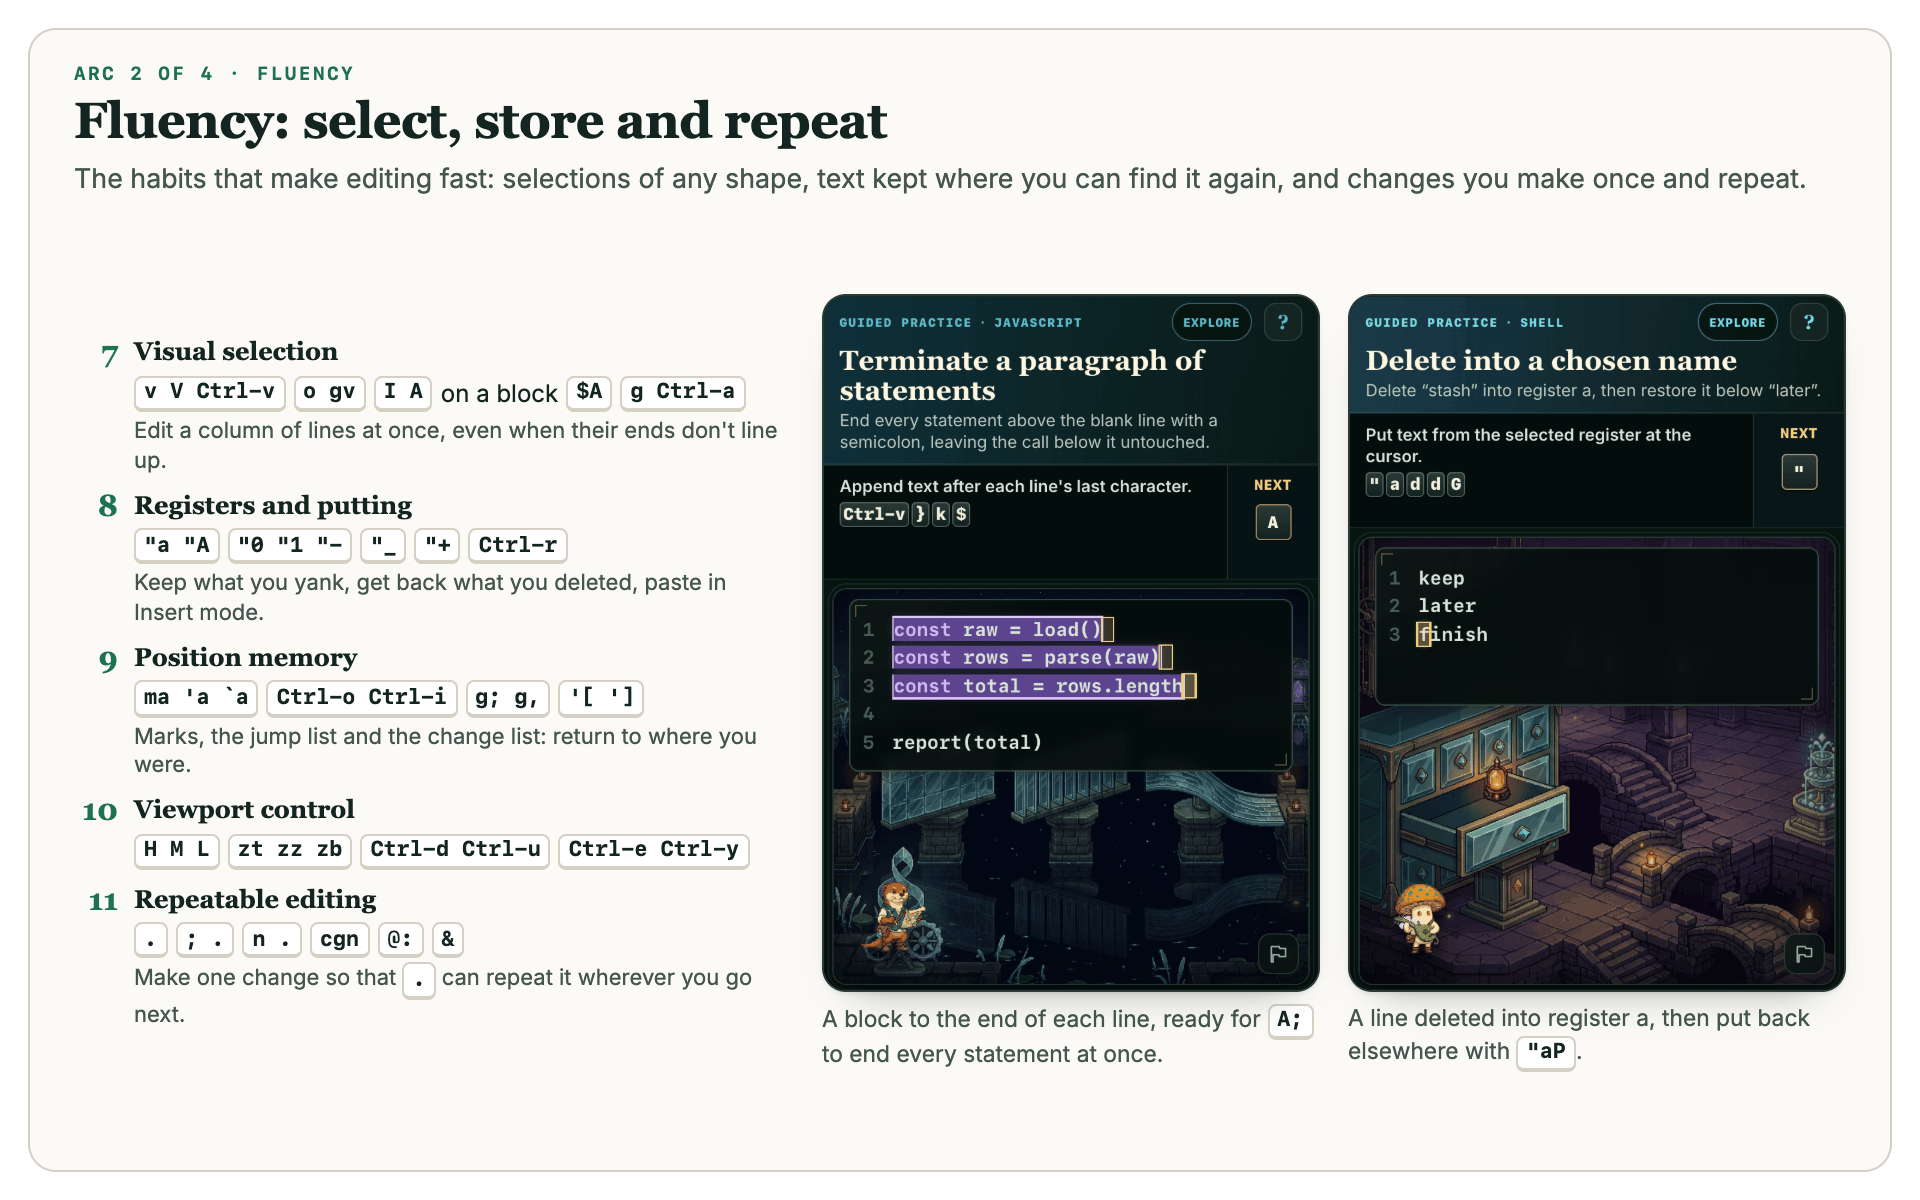
Fluency covers selections of any shape, registers, marks and the dot command.
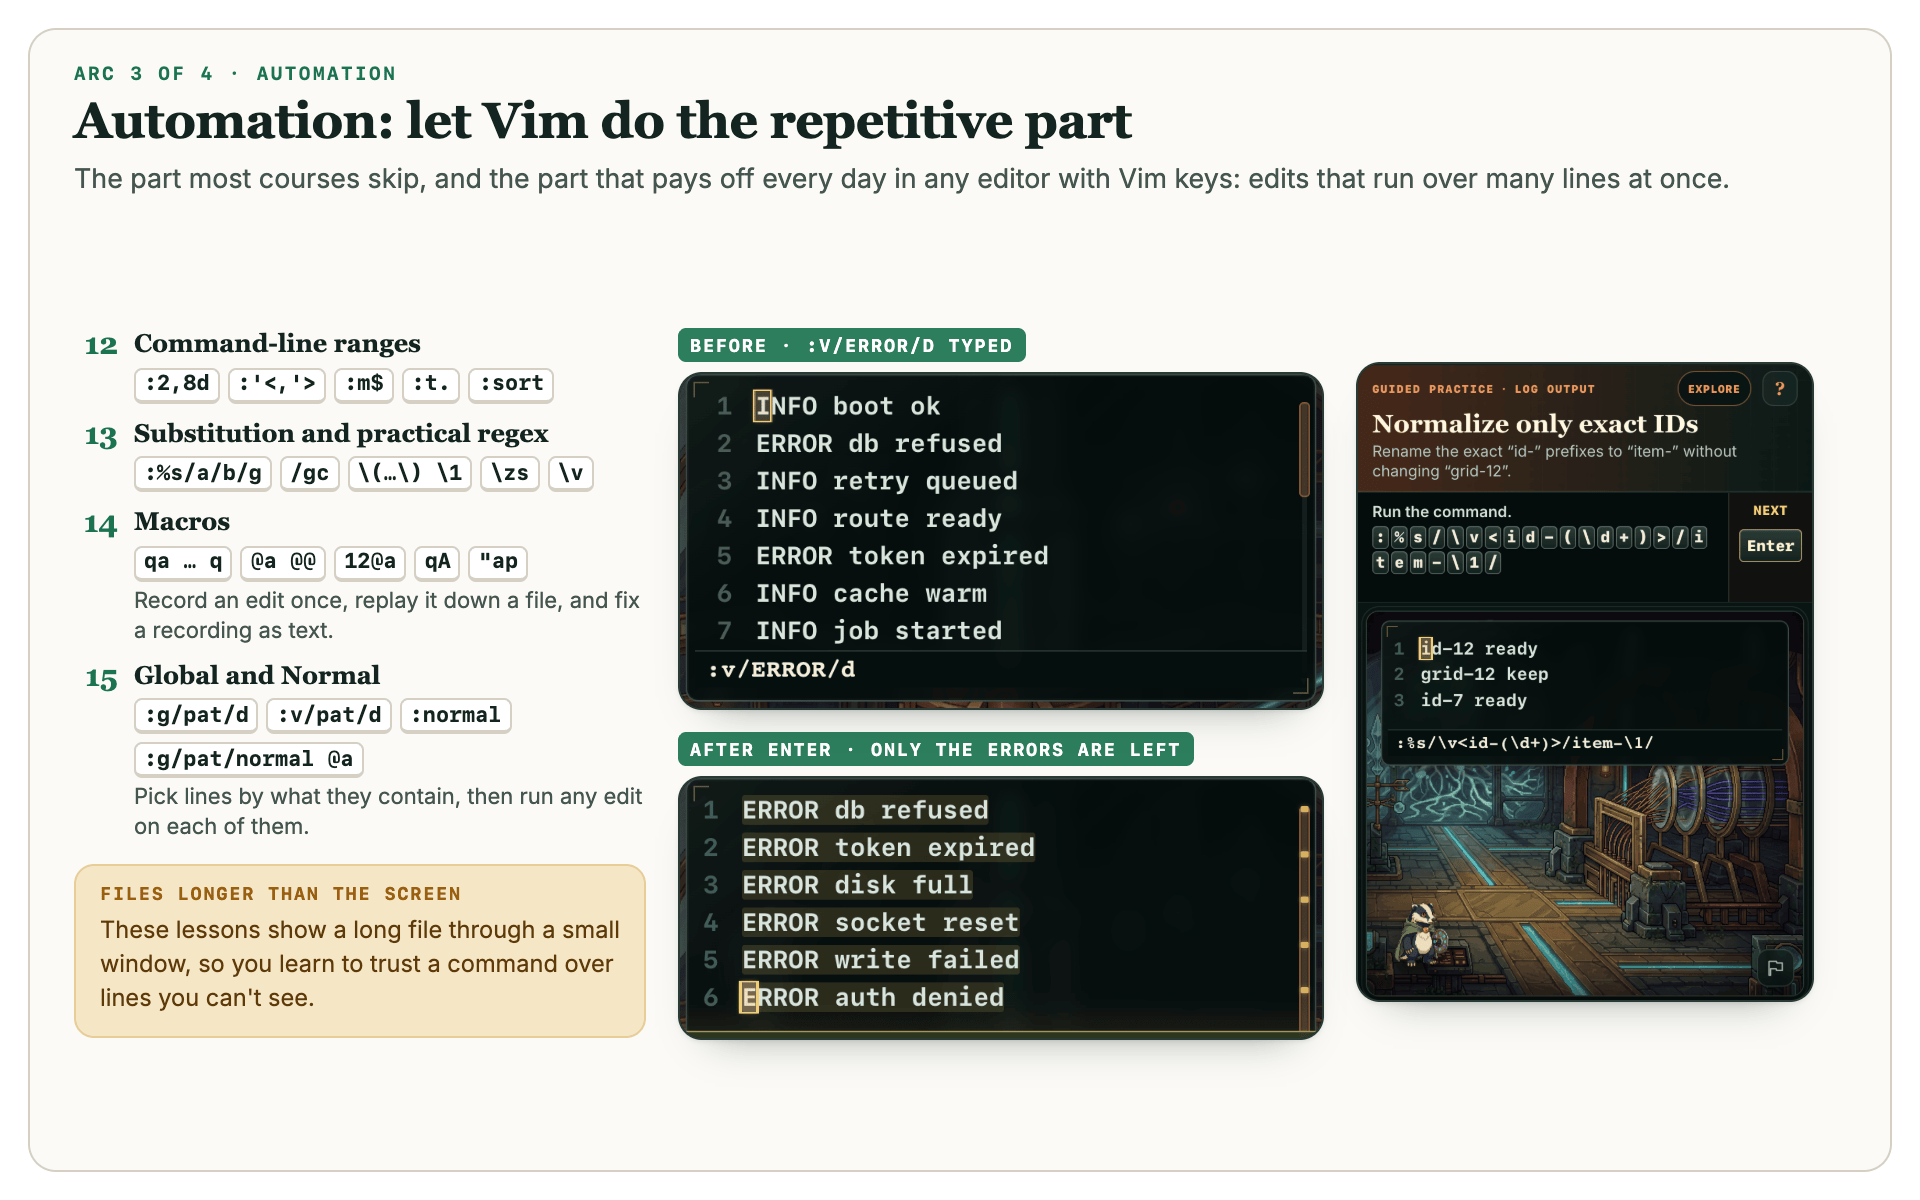
Automation covers ranges, substitution, macros and :global, on files longer than the screen.
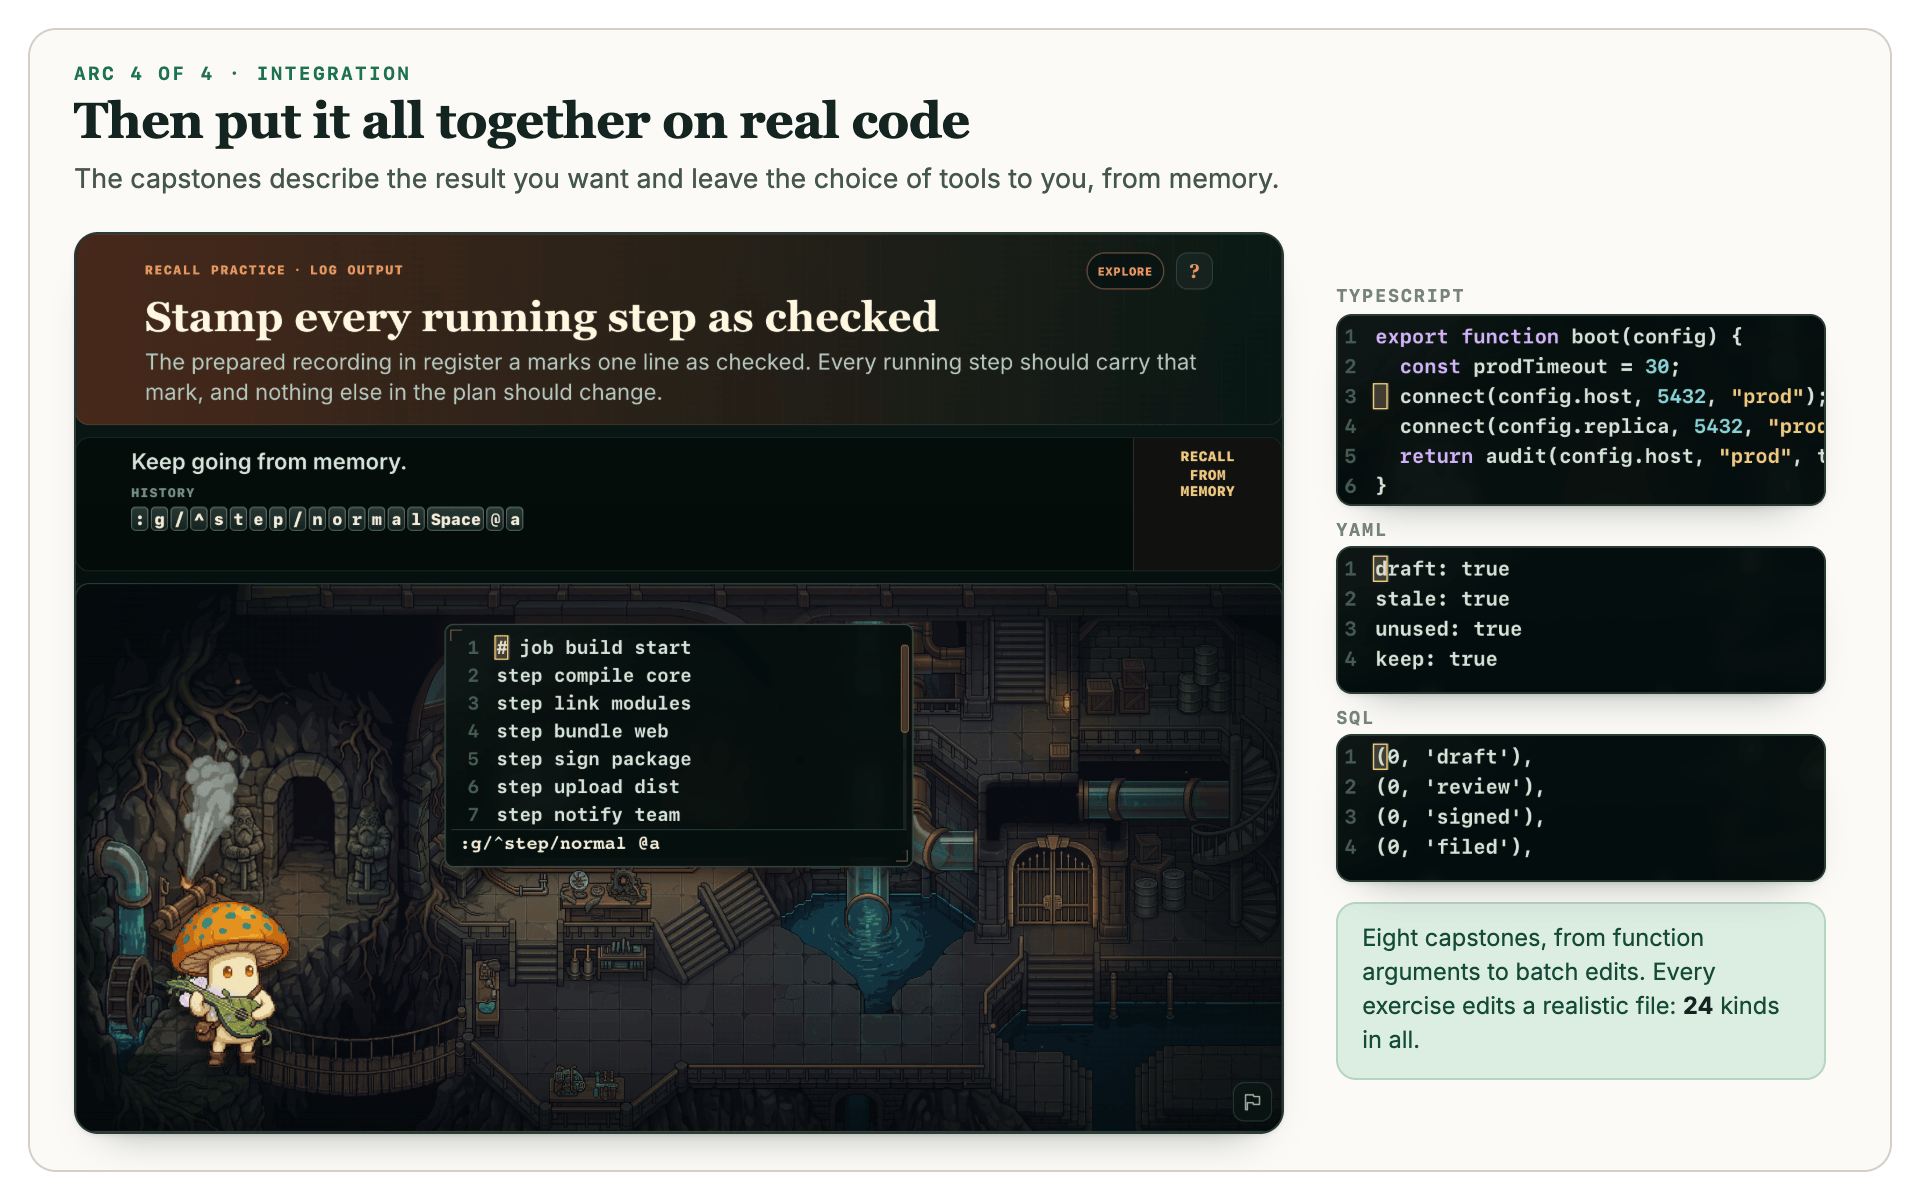
Capstones on realistic files, done from memory.
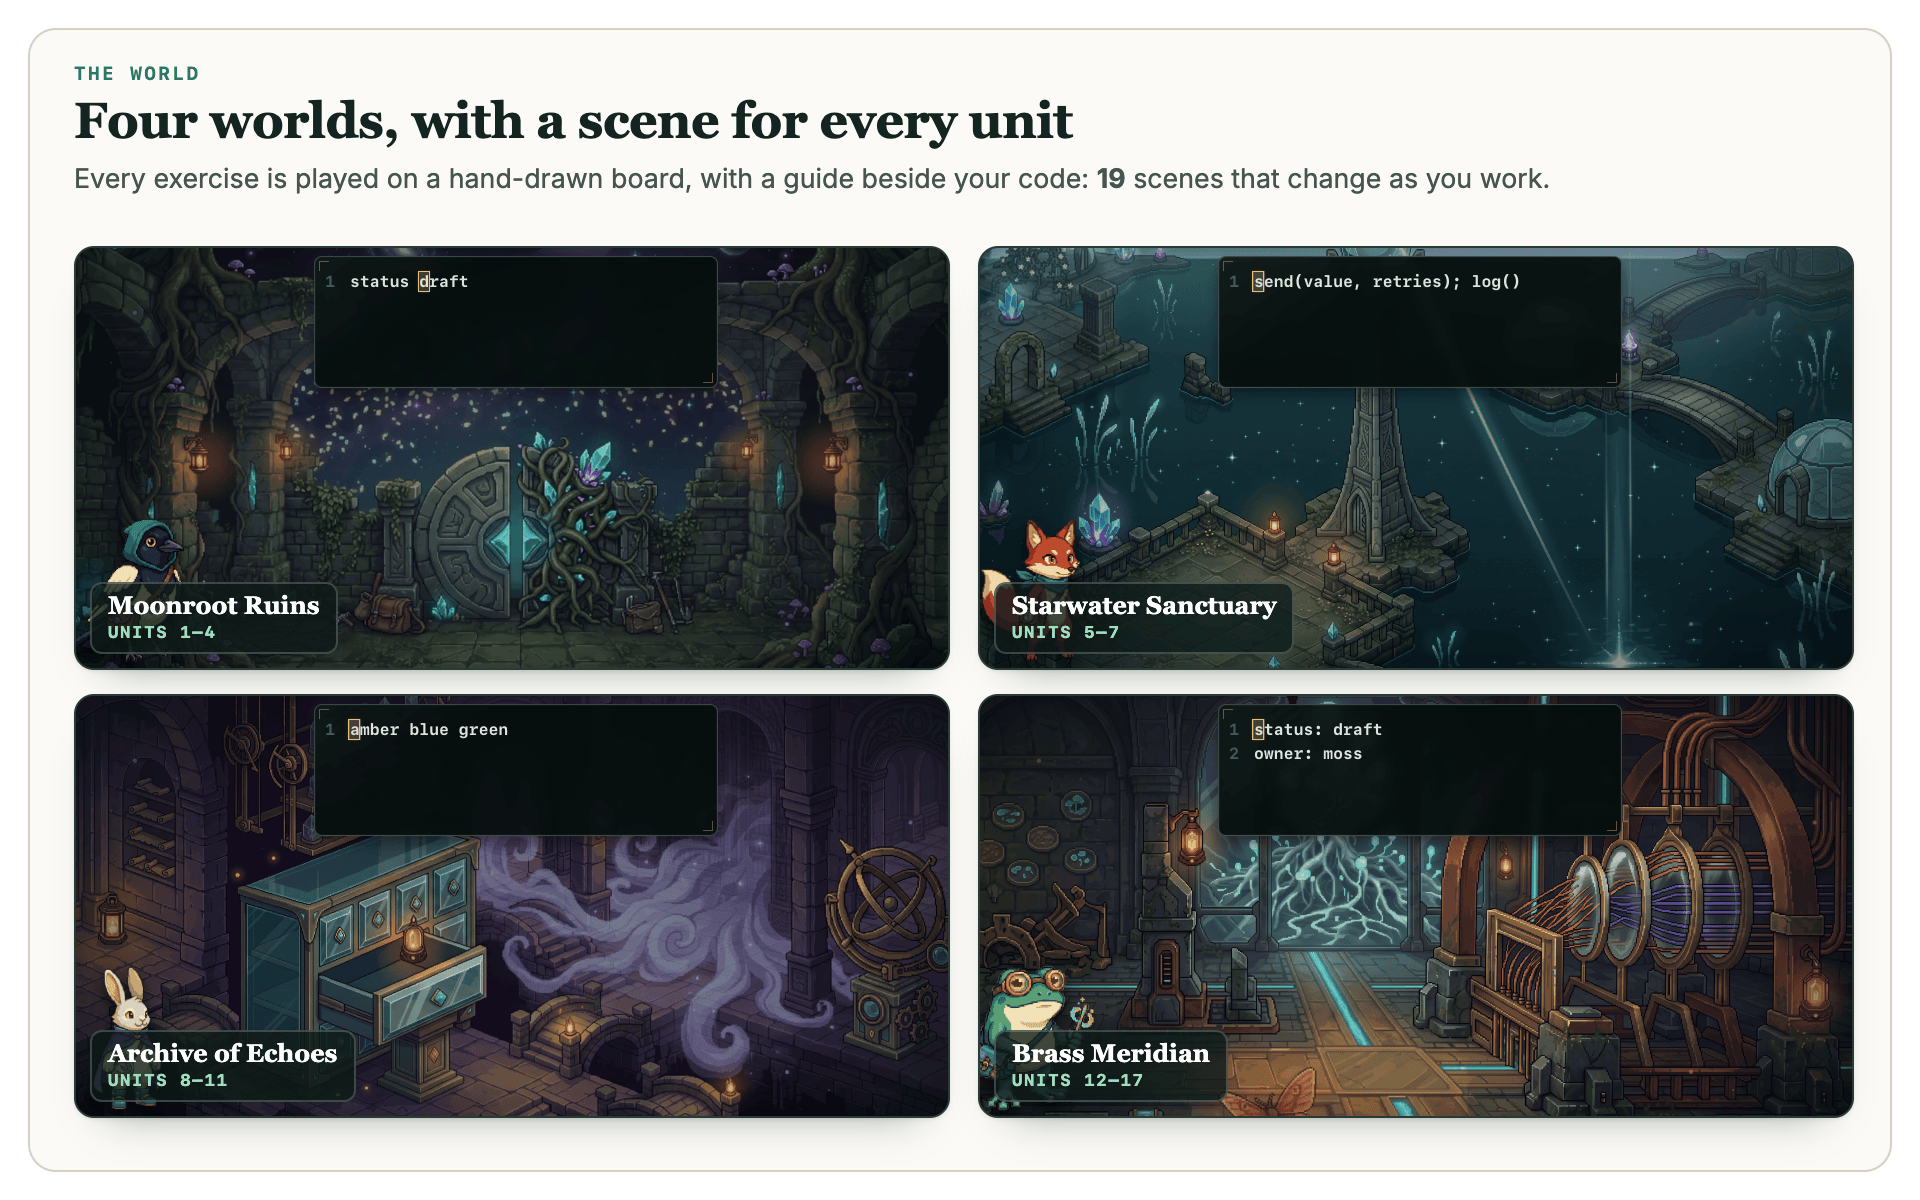
Four hand-drawn worlds, with a scene and a guide for every unit.
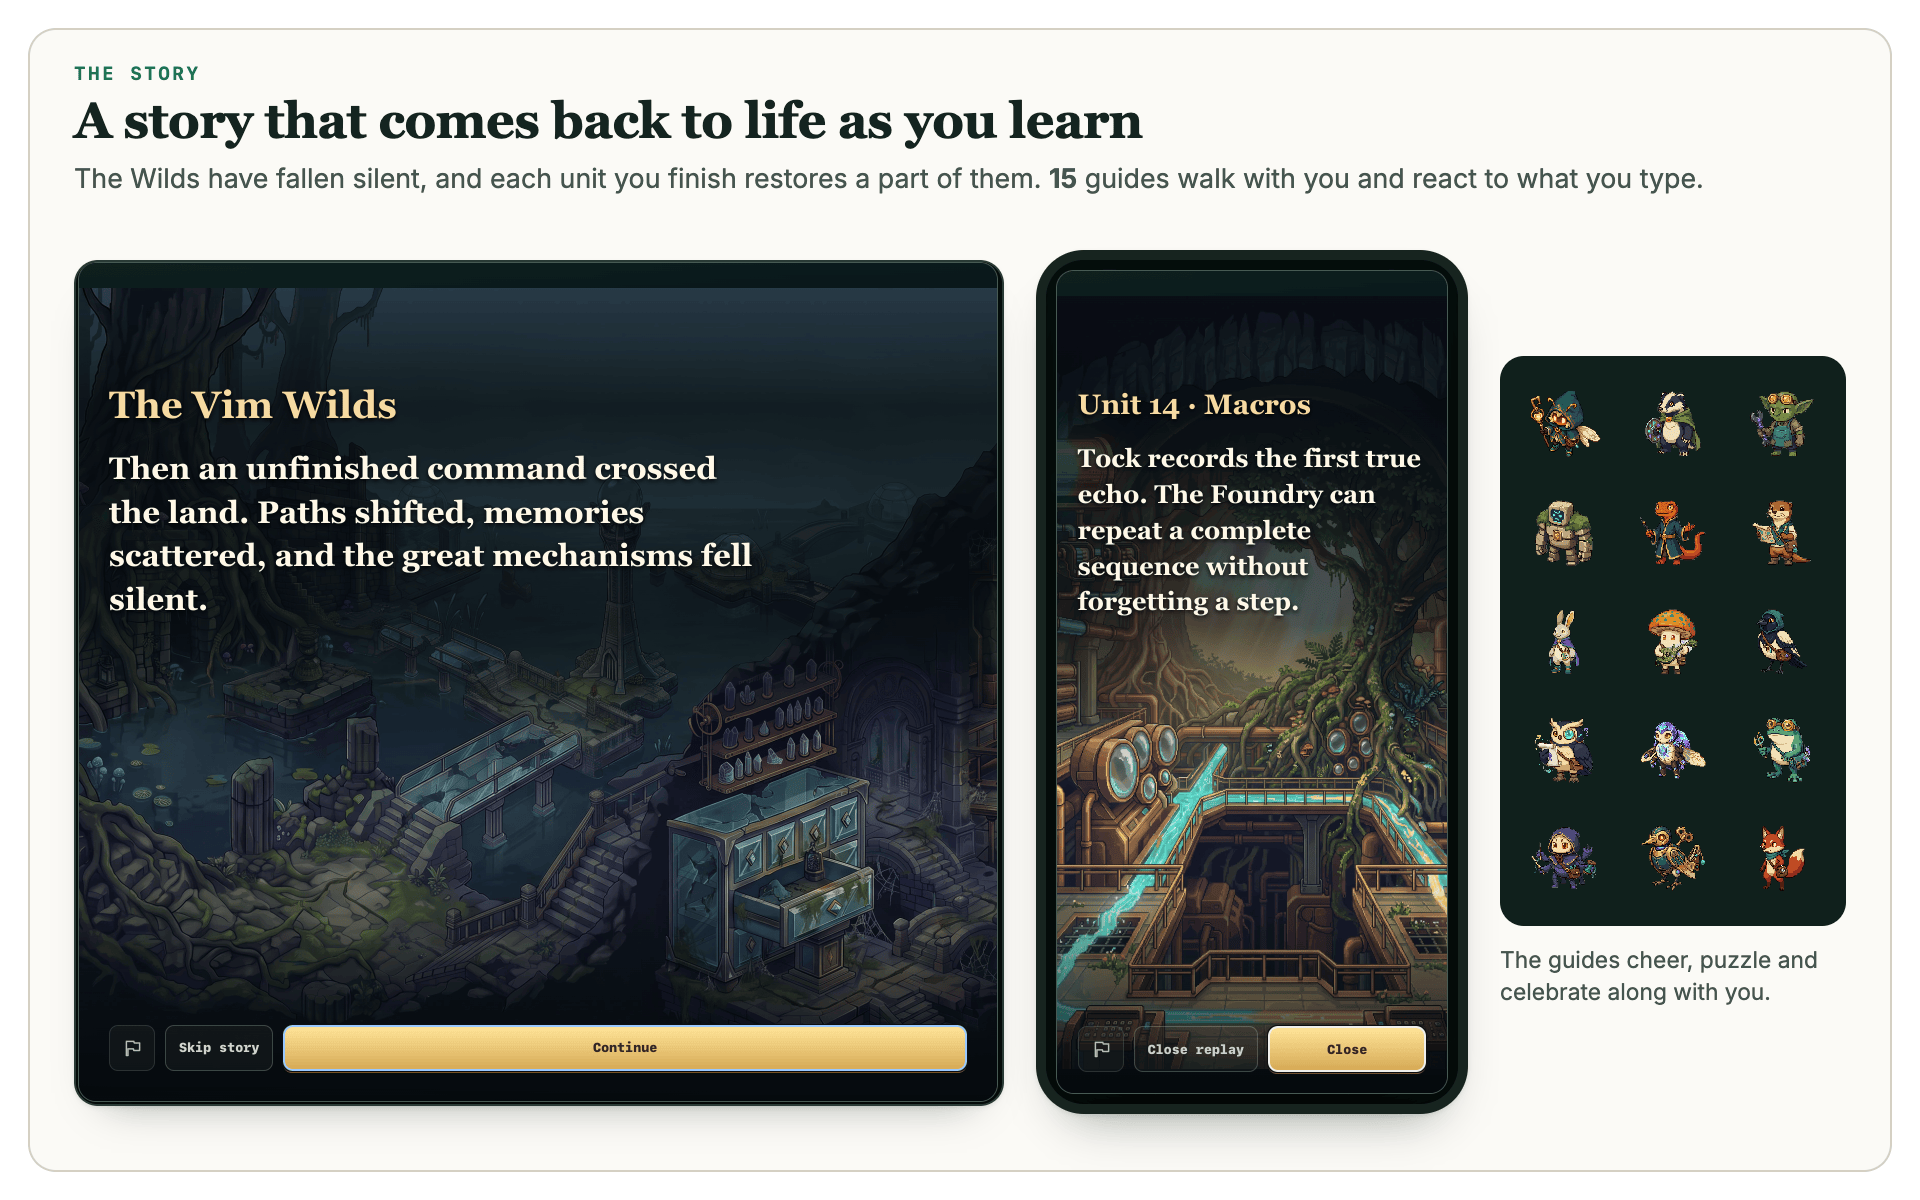
The story that unfolds as you finish units, and the fifteen guides.
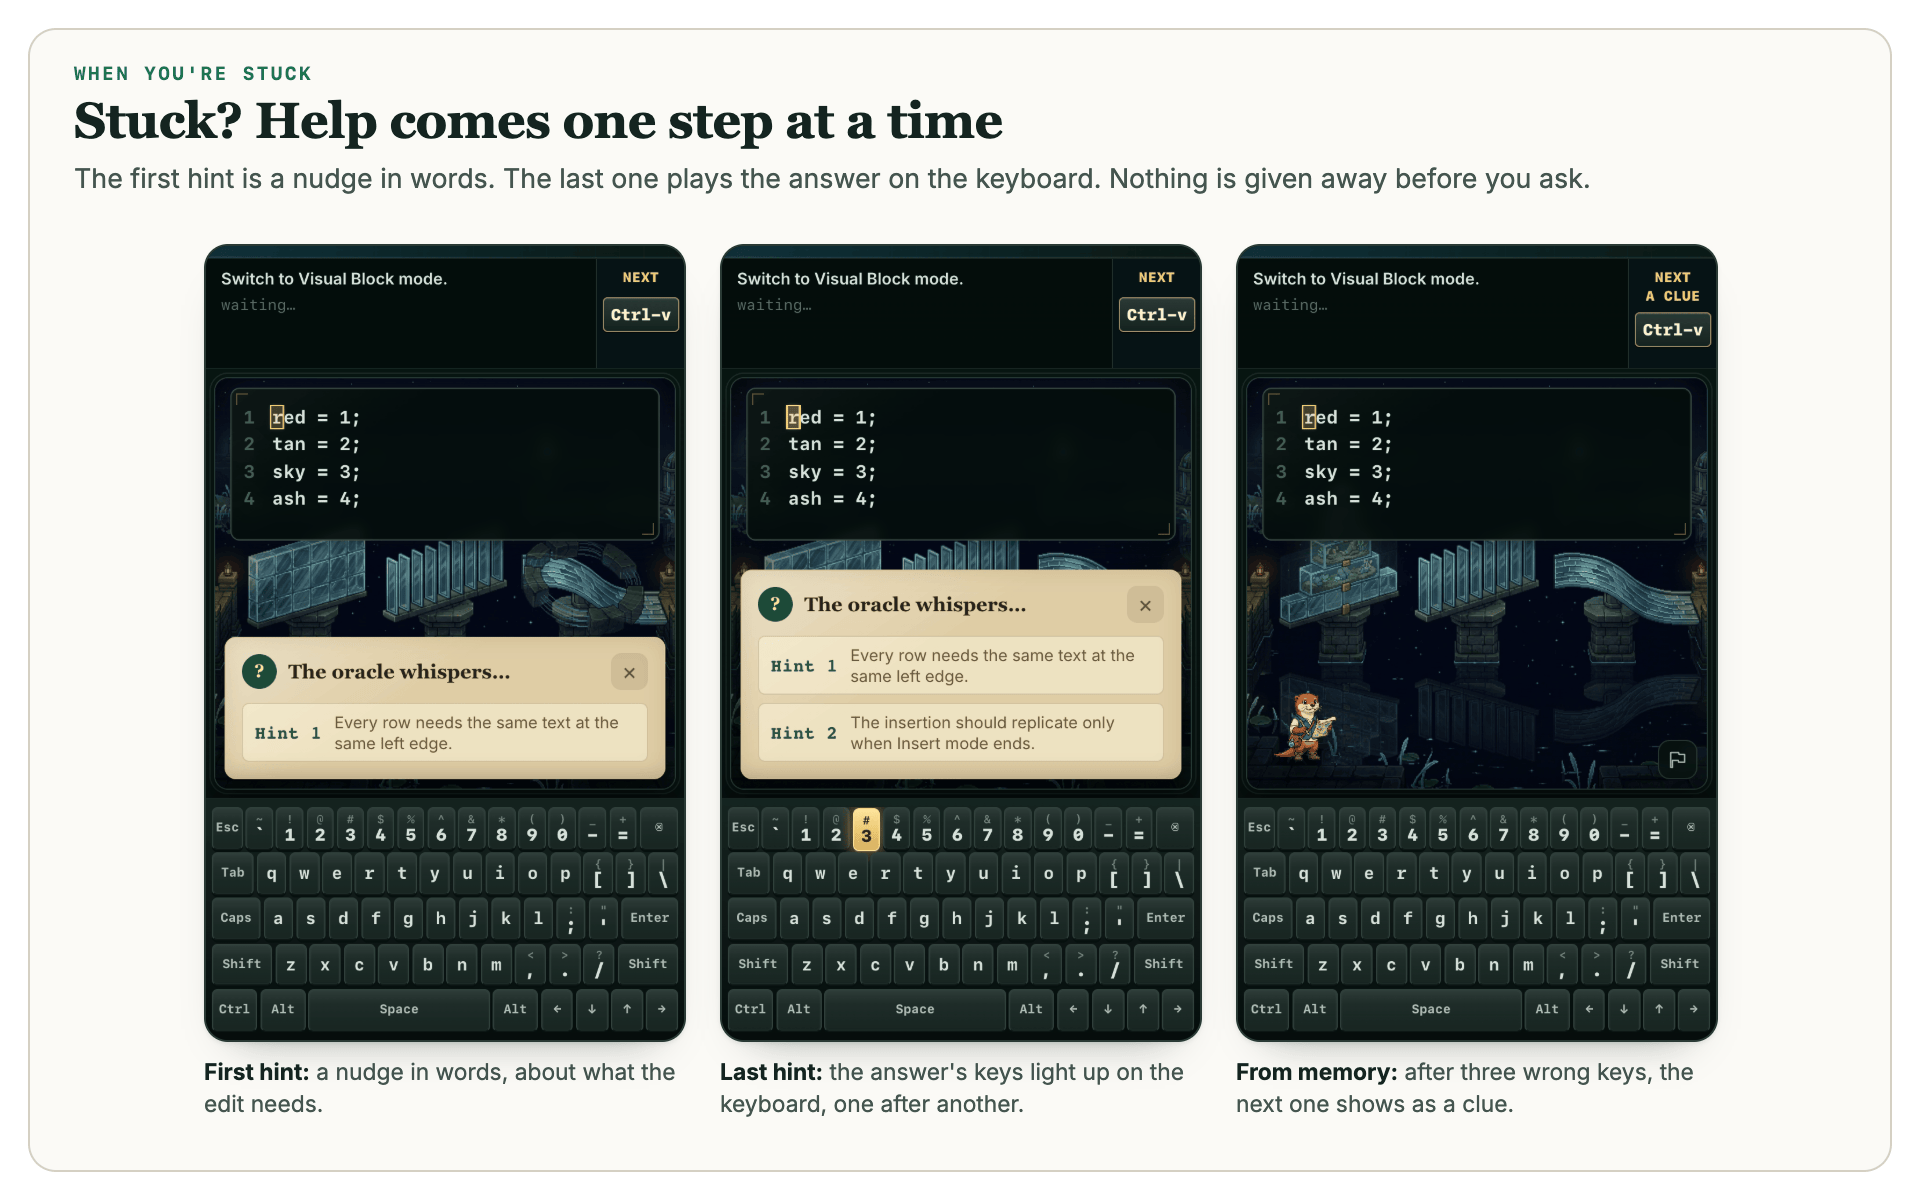
Hints that give away a little more each time, up to playing the answer on the keyboard.
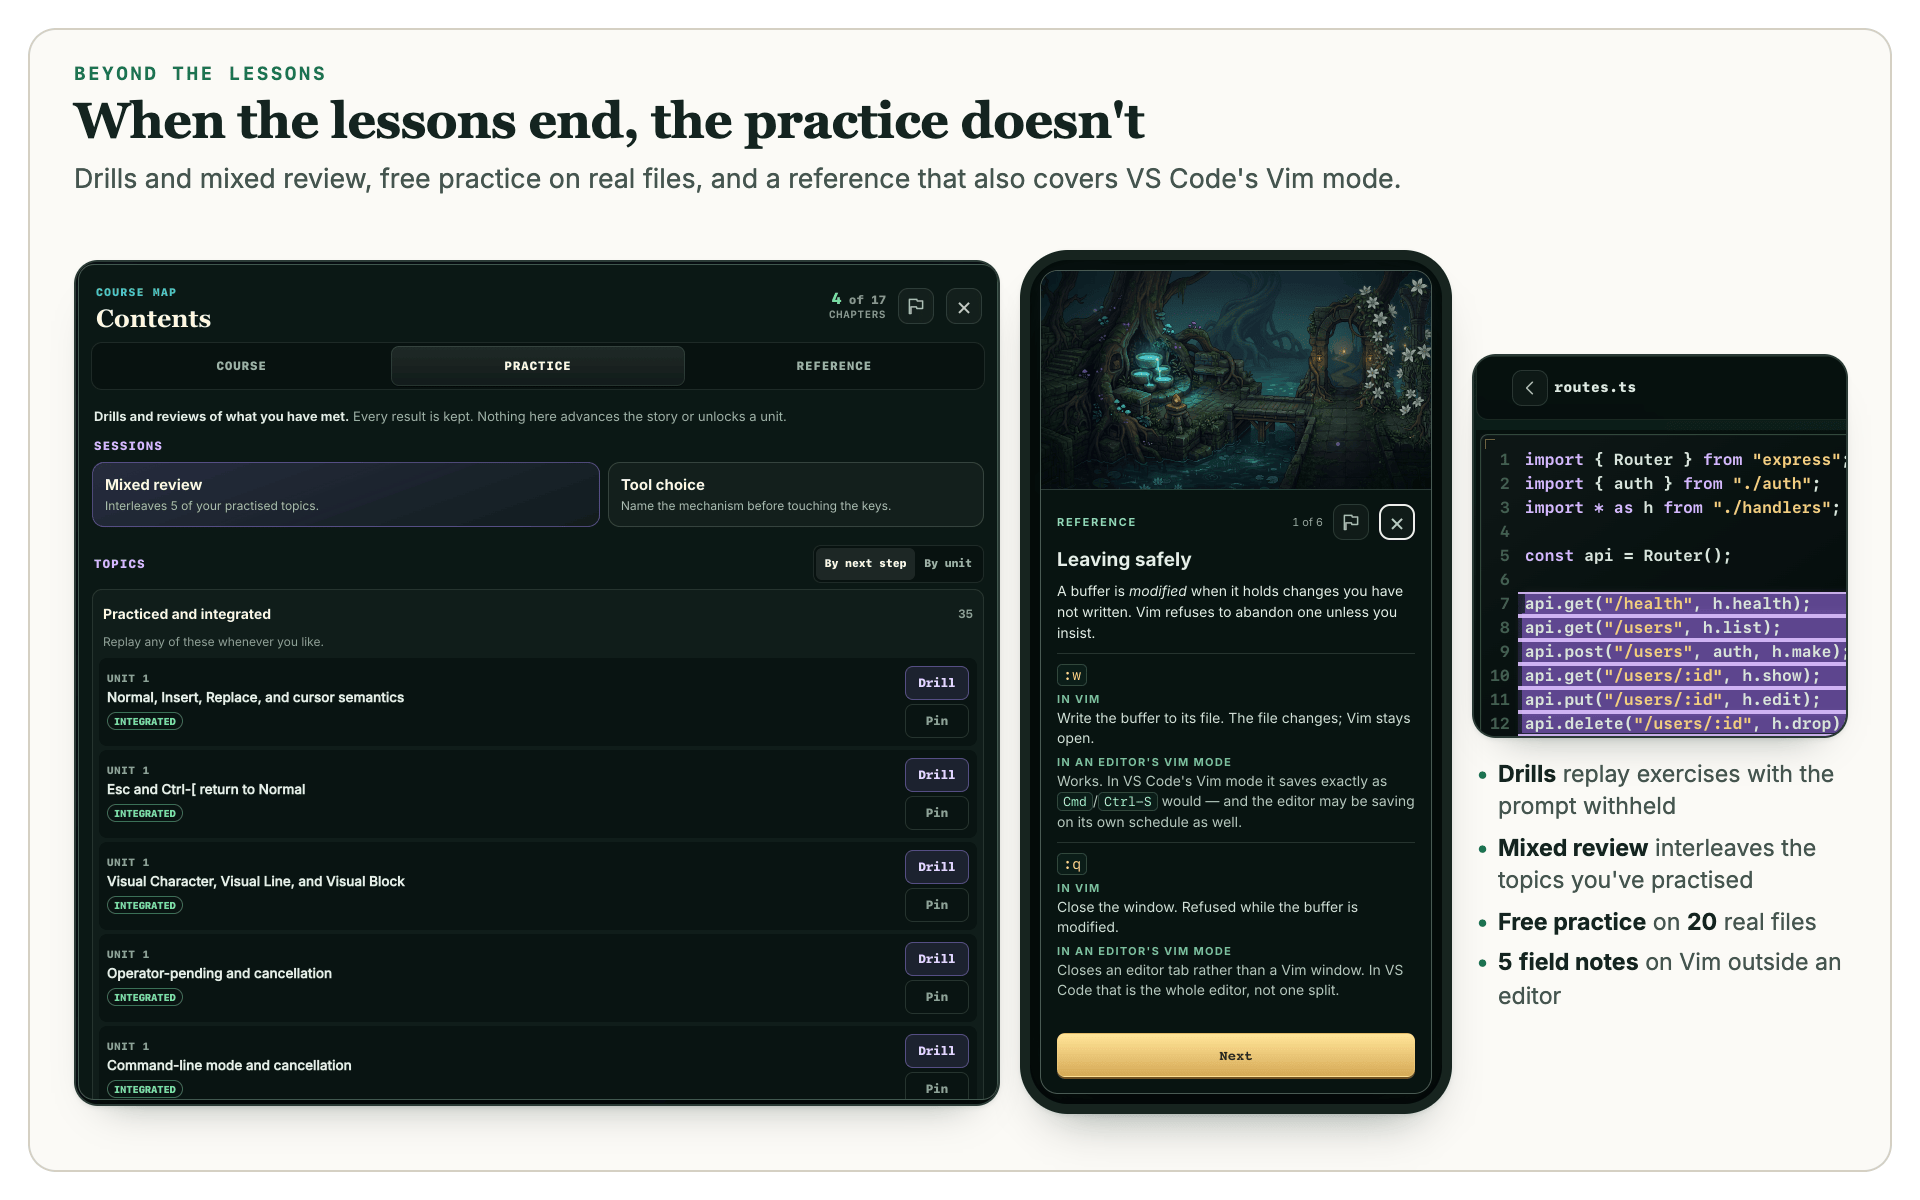
Drills, mixed review, free practice on real files, and a reference with notes for VS Code's Vim mode.
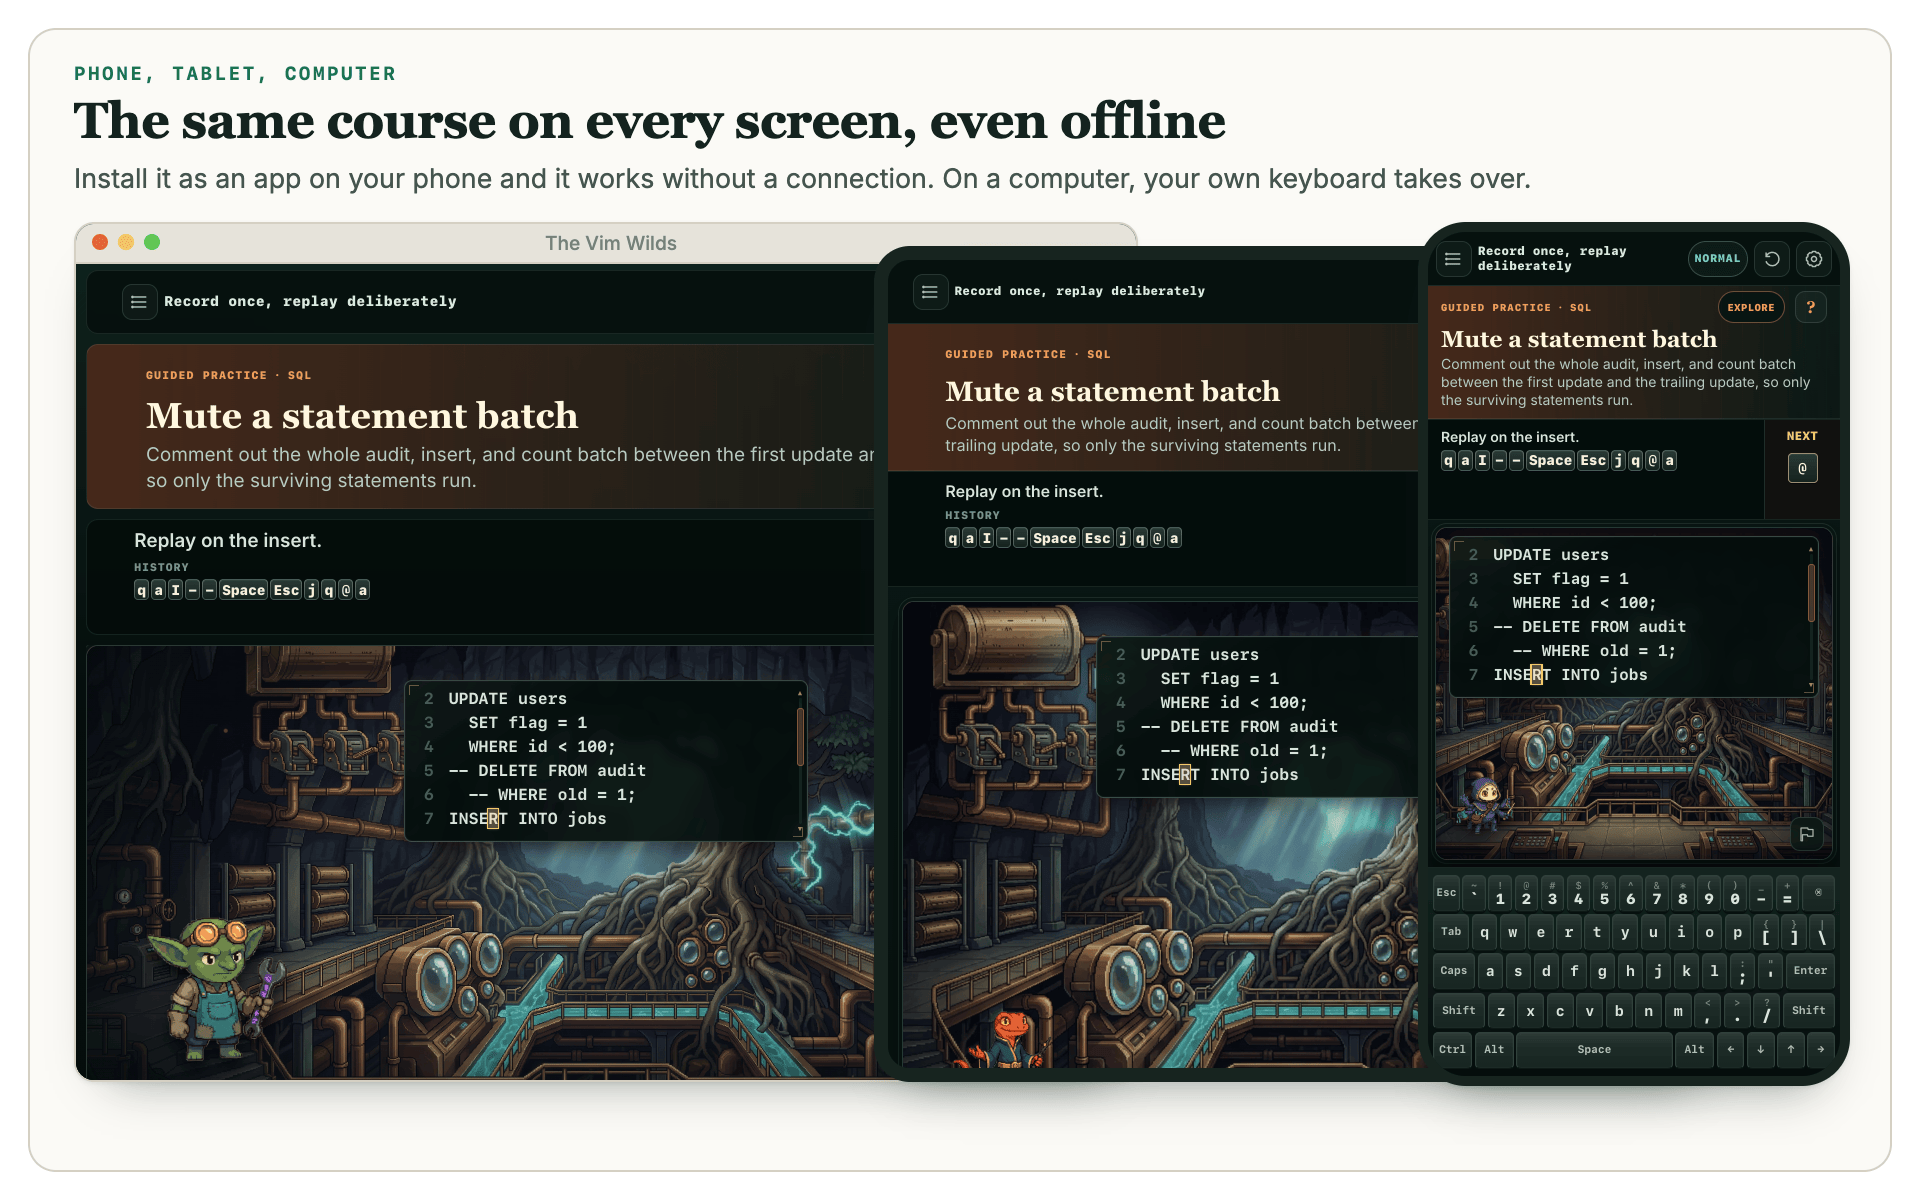
The same exercise on a laptop, a tablet and a phone.
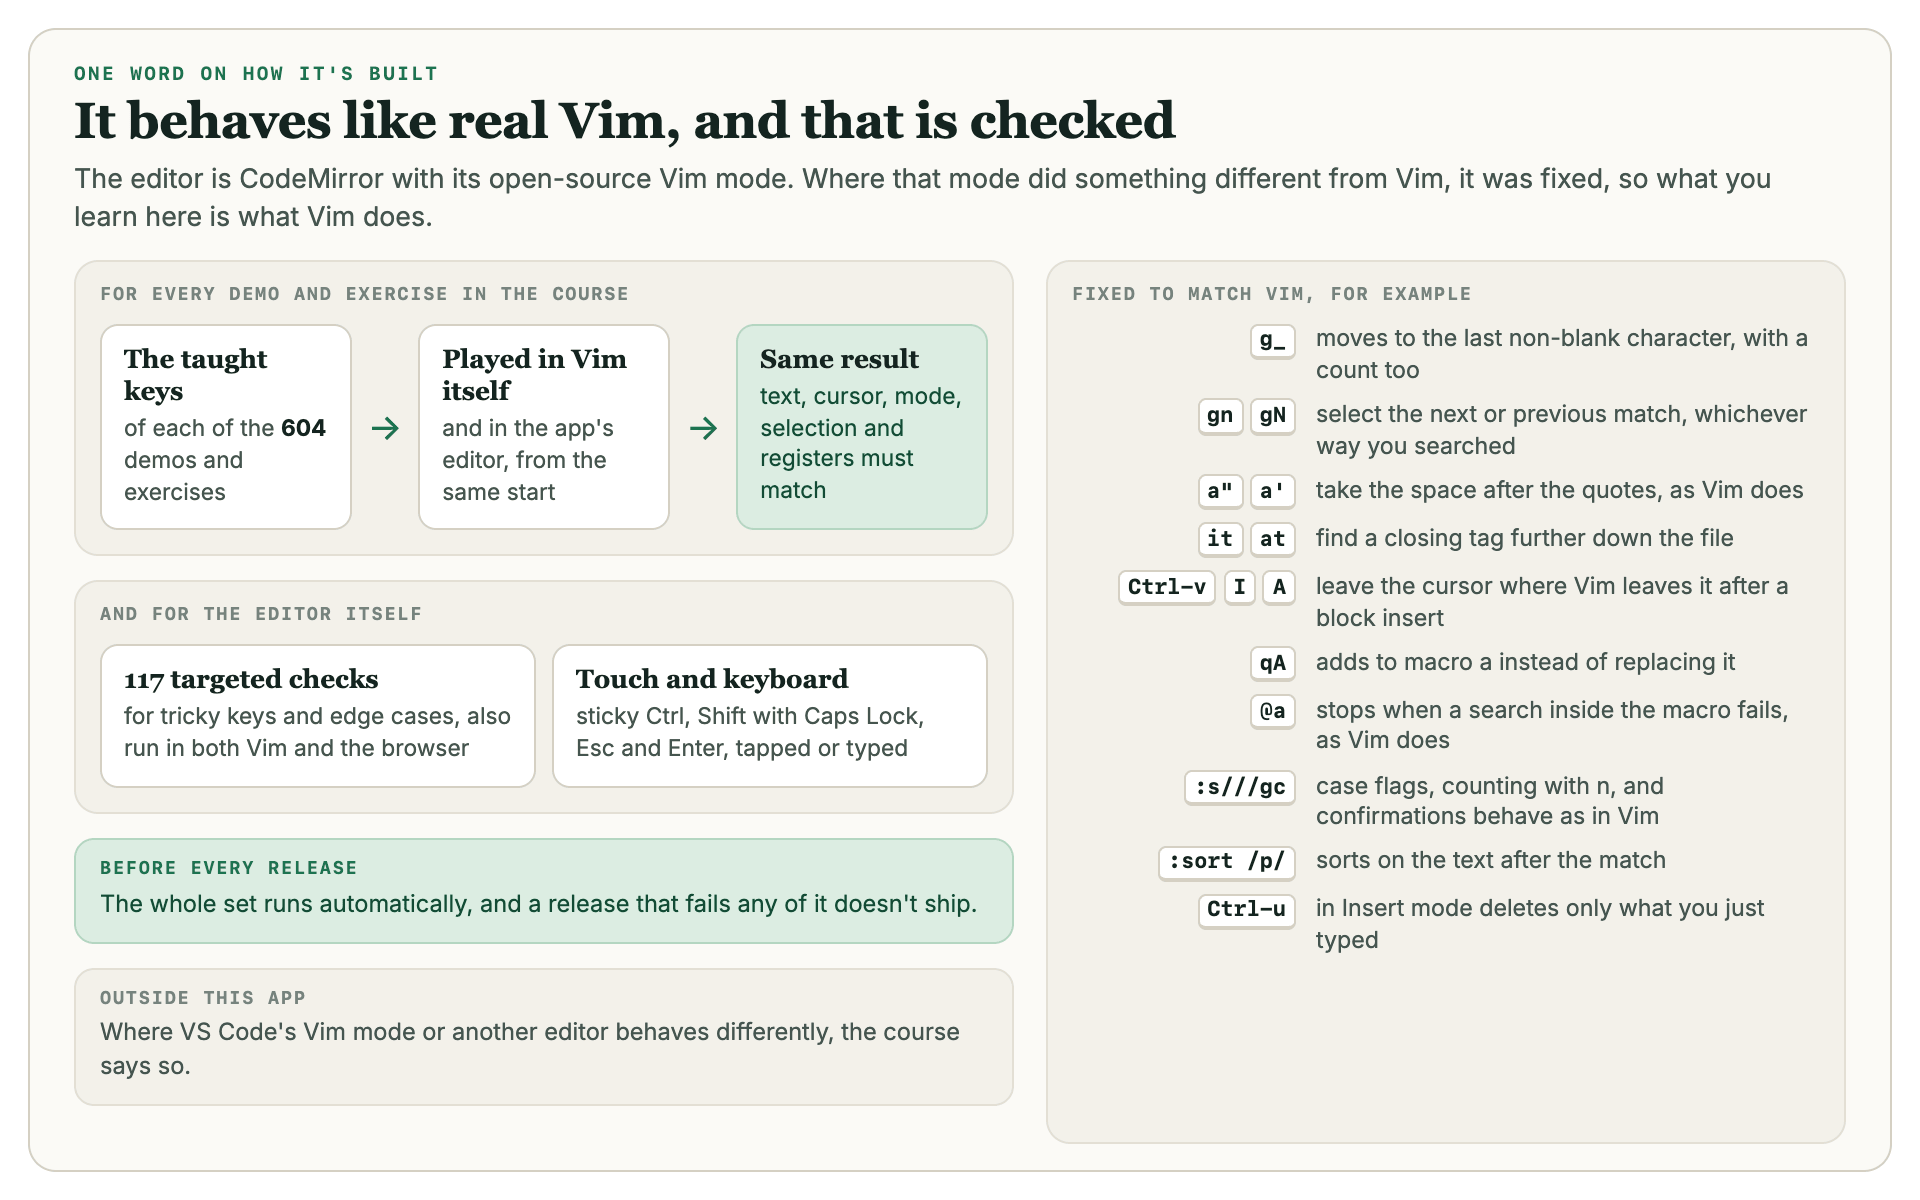
How every demo and exercise is checked against Vim, and what was fixed to match it.

Harmonic

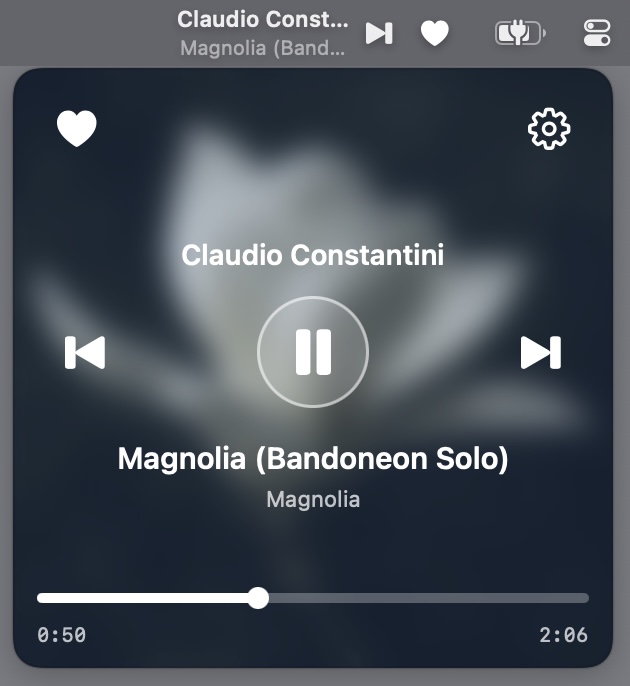
A minimal distraction-free Spotify playback controller for macOS. Control your music from the menu bar — skip tracks, toggle likes, and view track info at a glance.

The menu bar item and the player window.